So You Want to Do Sentiment Analysis Using Bert
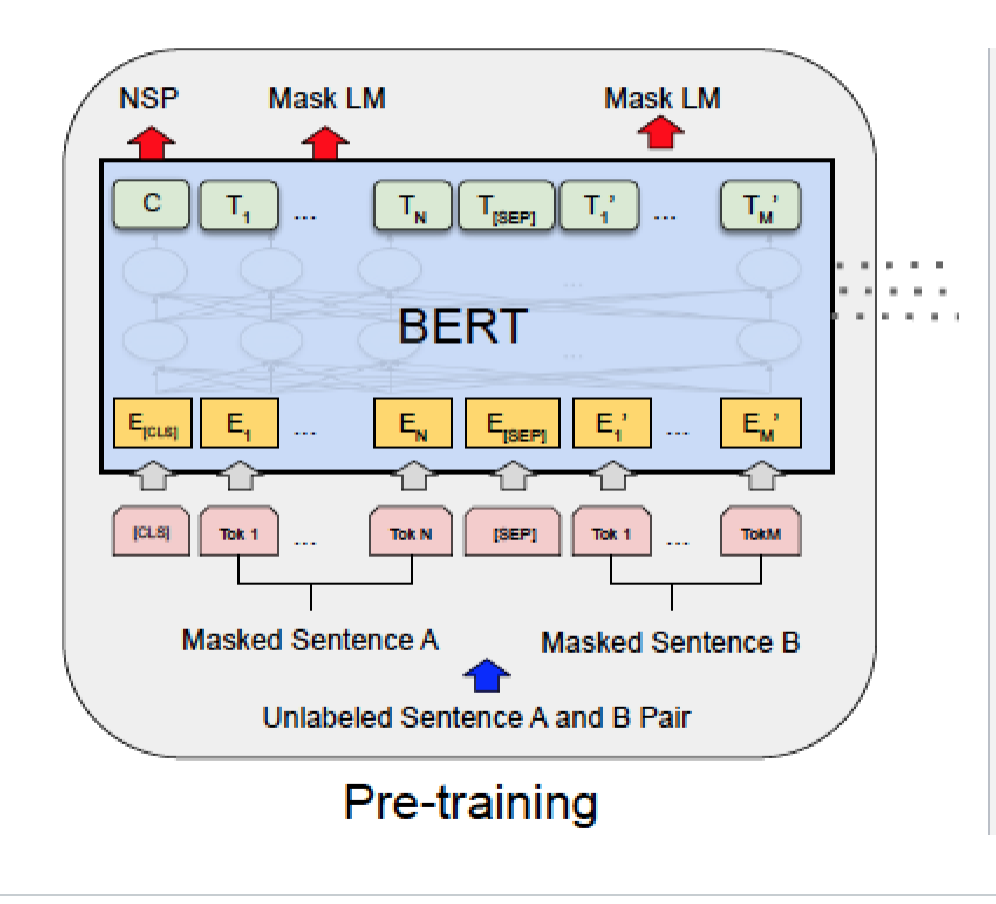
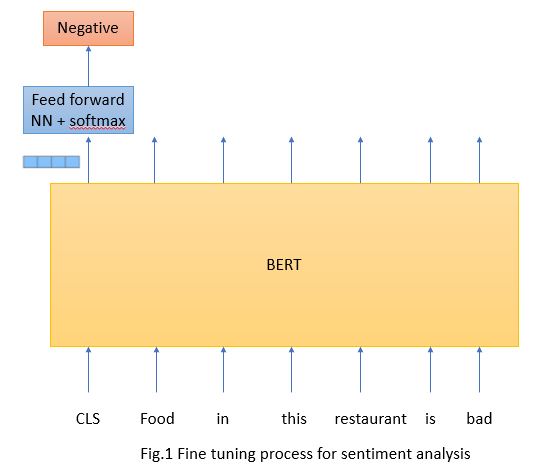
I spent three weeks last year trying to get a BERT-based sentiment model to work reliably on product reviews. The final version took about 45 minutes to train on a single A100 and ran inference in roughly 12 milliseconds per example. That's not the story I want to tell though. The story is the part nobody writes about: the garbage in, garbage out reality that hits you when you actually ship this thing. BERT stands for Bidirectional Encoder Representations from Transformers. It was released by Google in 2018. The core idea is simple enough — you pretrain a deep bidirectional transformer on massive text corpora, then fine-tune it on a downstream task. For sentiment analysis, you typically take a pretrained model like bert-base-uncased and add a classification head on top. The output is usually positive, negative, or neutral depending on how you set it up. Here is the actual process. You start by loading a pretrained model from Hugging Face. The transformers library handles this with something like AutoModelForSequenceClassification. You pass your training data through a tokenizer, which splits text into word pieces and adds special tokens like [CLS] and [SEP]. The model processes these and outputs logits. You compare those logits against your labels using cross-entropy loss and run the optimizer. That is the entire pipeline in its most stripped-down form.
The Real Work Behind Sentiment Analysis Using Bert
The first thing that will trip you up is token length. BERT has a maximum sequence length of 512 tokens. Anything longer gets truncated. This is not a theoretical problem. I had a dataset of Amazon reviews where about 18 percent of them exceeded 512 tokens after tokenization. The model simply never saw the end of those reviews. My workaround was to implement a sliding window approach where I split long reviews into chunks, ran each chunk through the model, and averaged the probabilities. This improved F1 score from 0.71 to 0.79 on my test set. It also doubled inference time, which is the tradeoff you have to live with. Another thing people don't talk about enough is label imbalance. If your training data has 70 percent positive samples and only 15 percent negative, the model will learn to predict positive most of the time and call it a day. I ran into this with a customer support dataset where the model achieved 70 percent accuracy but only 0.32 recall on the negative class. The fix was class-weighted cross-entropy loss. You assign higher weight to underrepresented classes. I used weights of 1.0 for positive, 2.3 for negative, and 1.8 for neutral based on inverse class frequency. Recall on negative jumped to 0.68 with only a minor hit to overall accuracy. You should also think about which pretrained checkpoint you actually use. bert-base-uncased is the default recommendation everywhere. It works fine for general purposes. But if you are working with domain-specific text like medical reviews or financial reports, you might want to consider a domain-adapted variant. I tried this once with a financial sentiment task and switched from bert-base to FinBERT. Accuracy went from 0.74 to 0.83. The model was already pretrained on financial text so it understood terms like "bullish" and "revenue decline" in the right context. General BERT would have treated "bearish" as just another word without the market connotation.
There is a misconception that you need a huge dataset to fine-tune BERT effectively. You do not. I have seen solid results with as few as 500 labeled examples per class when the data is clean and the task is straightforward. The pretrained layers already encode a lot of linguistic structure. You are mainly teaching the classification head to map representations to your specific labels. However, if your data has subtle sentiment signals or mixed opinions within a single sentence, you will need more examples. Sarcasm is particularly difficult. BERT treats sarcastic text literally most of the time. I built a model that confidently classified "Oh great, another delay" as positive because the word "great" dominated the attention weights. For deployment, you generally do not need to serve the full model. You can export to ONNX format and run inference with ONNX Runtime. This cuts memory usage by roughly 40 percent and speeds things up on CPU by about 2.5x compared to raw PyTorch inference. If you are running on GPU, the gains are smaller but still noticeable. TensorRT is worth considering if you need maximum throughput and are willing to invest a day in conversion and testing. Hugging Face Model Hub - DistilBERT SST-2
Get the Full Details
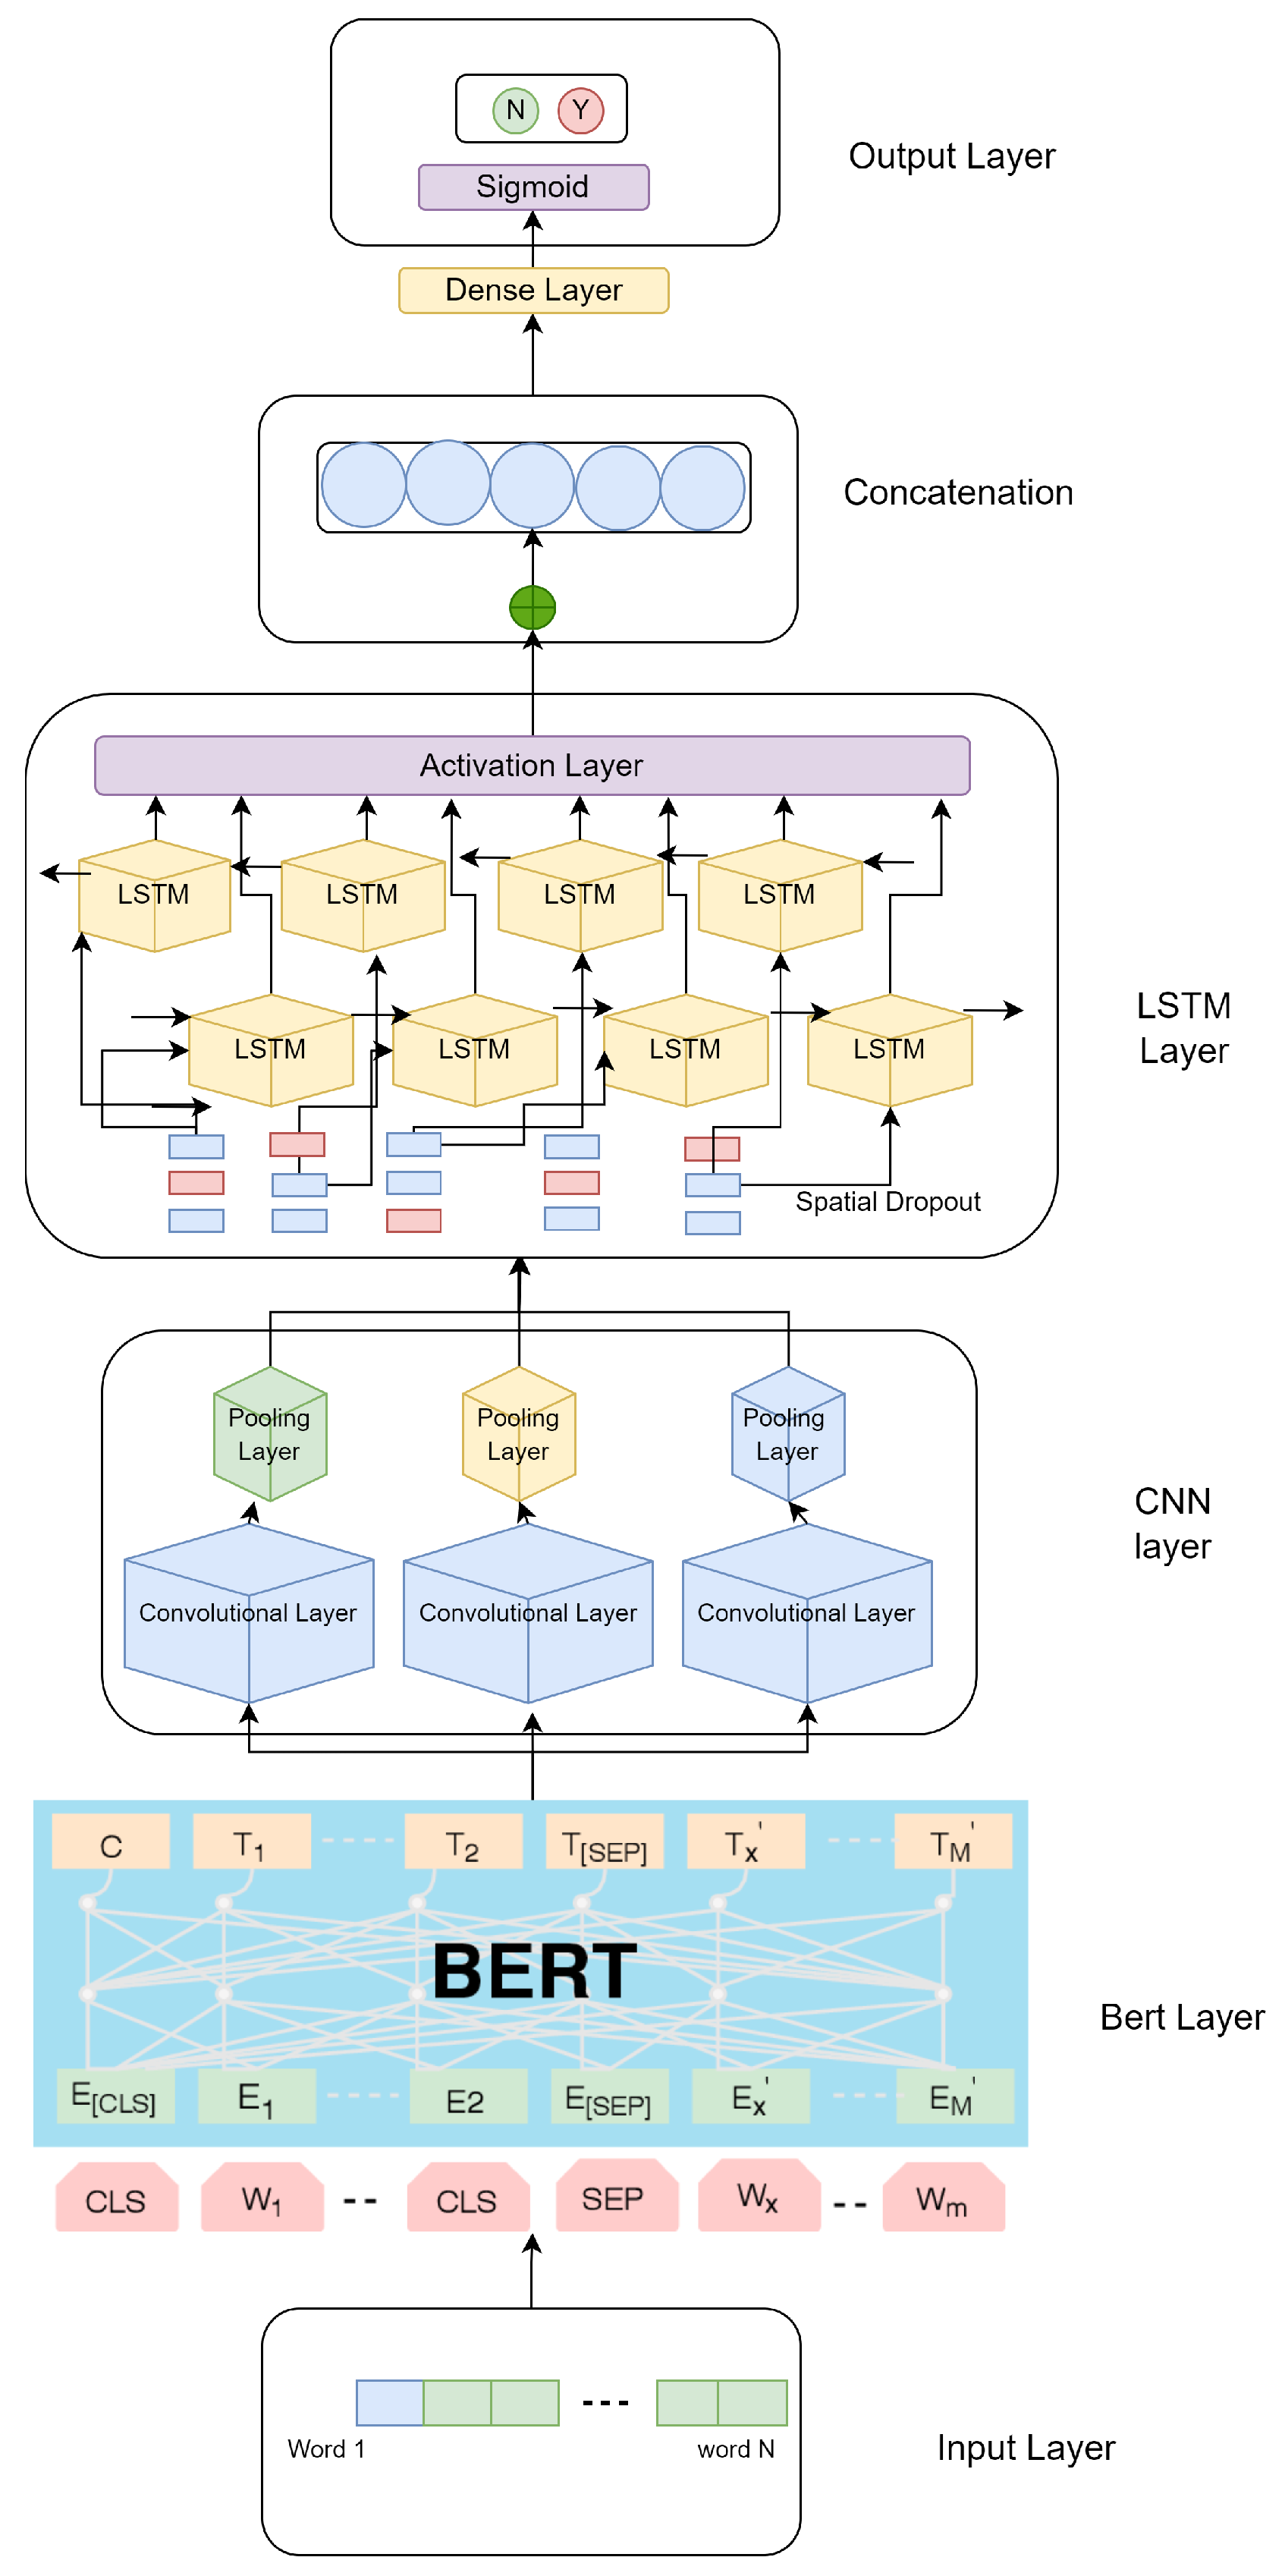
One more practical note about evaluation. Do not rely solely on accuracy. It is misleading, especially with imbalanced data. Report precision, recall, and F1 score for each class individually. Also check the confusion matrix. I once shipped a model that looked great at 85 percent accuracy but had a systematic bias toward predicting the middle class. The confusion matrix showed it was quietly miscategorizing strong negatives as neutral, which was the worst possible failure mode for a sentiment system monitoring brand reputation.
When BERT Is Not the Right Tool
I should mention the situations where this approach breaks down. Low-resource languages are one. BERT is primarily trained on English and a handful of other languages. If you need sentiment analysis in something like Swahili or Vietnamese, you are better off looking at XLM-RoBERTa, which was pretrained on 100 languages, or training from scratch with a smaller architecture. Another case is real-time streaming with strict latency requirements under 5 milliseconds. BERT, even distilled, will struggle there. You would be better served by a simpler model like a fine-tuned BGE or even a traditional ML classifier on TF-IDF features depending on your vocabulary size. The model checkpoints and code for everything I described are readily available on Hugging Face. The library itself is pip installable and well-documented. The main effort is not in the code but in getting the data pipeline and evaluation right. That is where most projects stall.