Three Structures That Actually Run Your Code
Understanding Sequencing Selection And Iteration
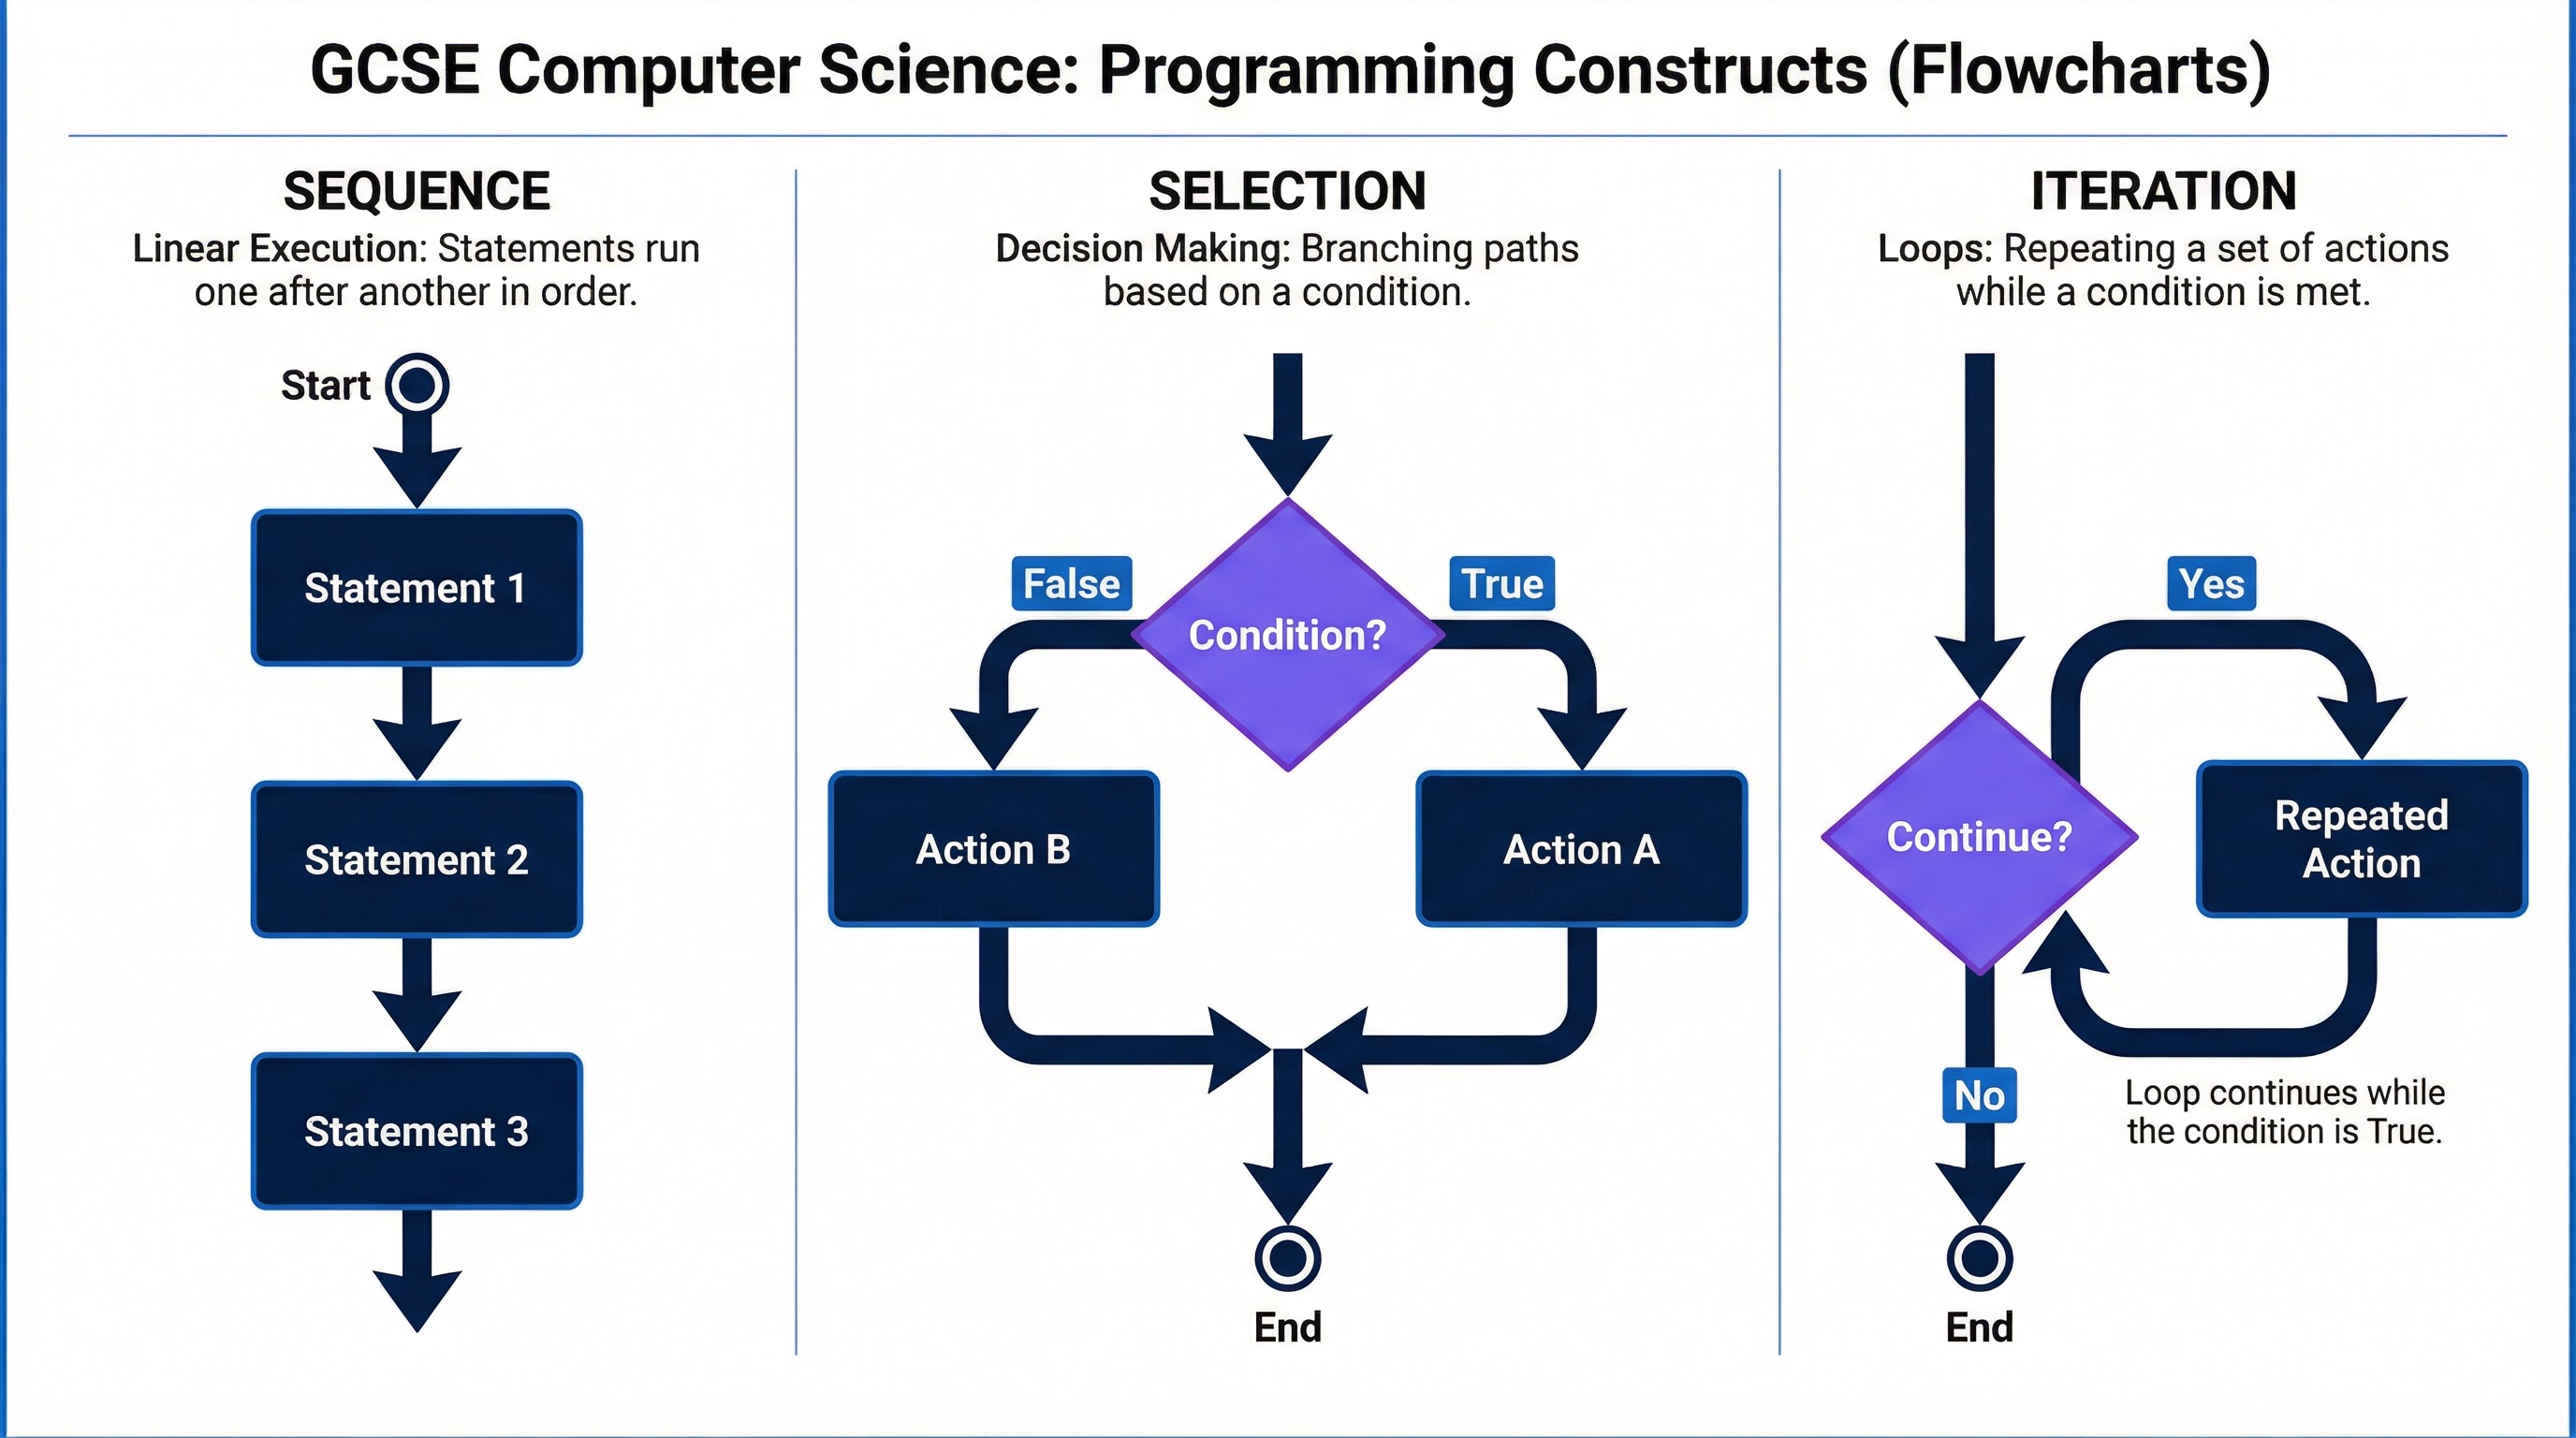
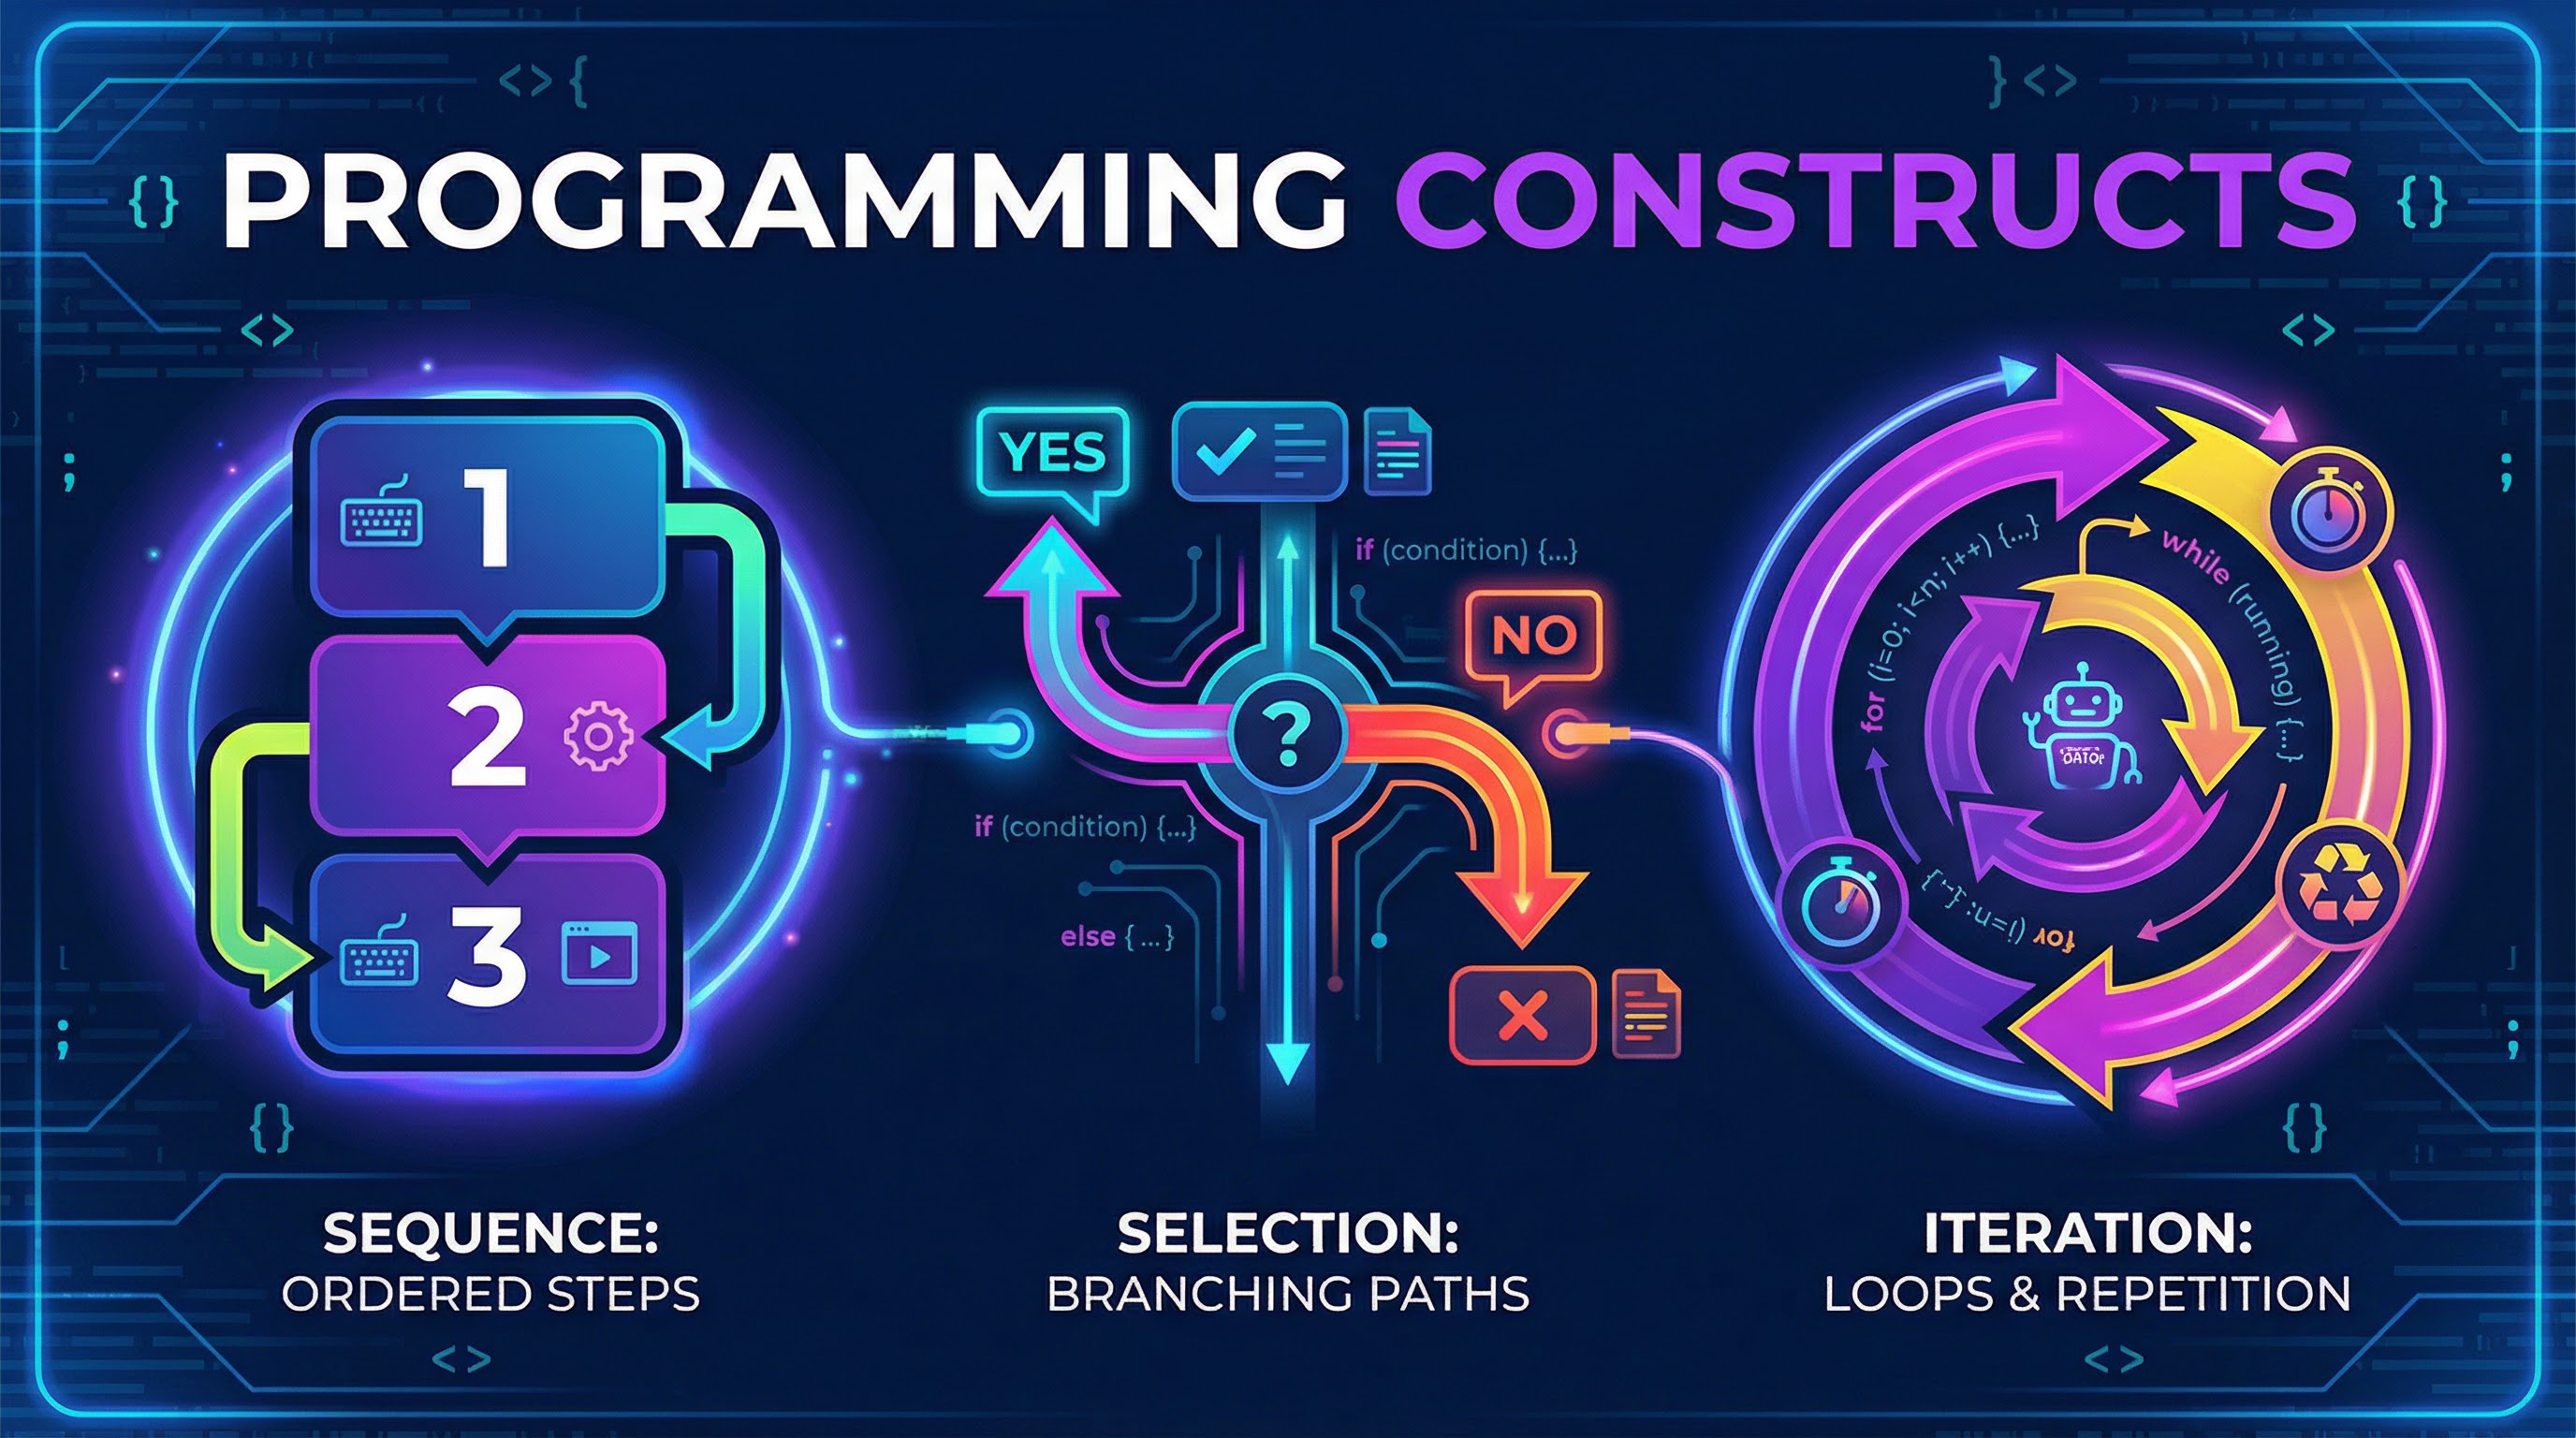
Everything you write in code boils down to three things: lines running one after another, choices between paths, and loops repeating work. Most tutorials treat these as separate topics. They're not really separate - they're just different ways of handling the same problem space. I learned this the hard way debugging a batch processing script that ran for three days before I realized the selection logic inside my loop was re-evaluating the same condition thousands of times per second when it only needed to be checked once. Sequencing is the default state. Code executes top to bottom unless something explicitly interrupts that flow. The problem most people have isn't understanding sequencing itself. It's recognizing when they've accidentally broken it through poorly placed control structures. In a Python ETL pipeline I maintained, a single incorrect indentation level in a nested conditional caused the data transformation step to silently skip roughly forty percent of incoming records. The logs showed success. The output was wrong. Took me a week to trace because the sequencing looked fine at every obvious level. Selection is branching logic. If this, then that, else something else. The common trap here is overcomplicating what should be a straightforward check. If/elif/else chains are fine for maybe five to seven branches. Beyond that, you're usually looking at a dispatch table or a strategy pattern. I worked with a colleague who had a forty-five branch if statement handling payment gateway responses. One branch was dead code. Nobody knew which one until we ported the system and forgot to port that specific branch.
Iteration, or looping, is where most performance issues hide. A for loop and a while loop do fundamentally different things despite looking similar. For loops iterate over a collection or a known range. While loops repeat until a condition changes. The distinction matters more than most developers account for. I replaced a while True loop that was polling a database connection every two seconds with an event-driven callback. The server load dropped from eight percent idle consumption to under one percent. The old code wasn't wrong logically. It was just wrong practically.
How These Structures Interact In Practice
Selection and iteration combine in ways that create some genuinely tricky edge cases. Consider a selection inside an iteration, or an iteration inside a selection. These nested structures are standard in any non-trivial program. They're also where the bugs accumulate. A nested loop with a conditional break can look perfectly clean in thirty lines and then silently drop data under production conditions because the break condition triggers one iteration too early or too late. I hit this exact scenario in a C++ application processing sensor data from industrial equipment. The outer loop read new batches. The inner loop filtered outliers based on a threshold stored in a selection structure. The threshold value was cached incorrectly, so after the first batch, every subsequent batch used the wrong filter. Twenty minutes of runtime produced garbage output that looked statistically plausible. I caught it because the variance in the final calculations didn't match the known input distribution, not because of any error message. The fix was moving the threshold evaluation outside the inner loop and storing it per-batch instead of globally. Another thing nobody tells you about iteration: generators exist for a reason. Loading an entire dataset into a list before iterating is fine for small files. It breaks completely at scale. A generator expression that yields items one at a time uses roughly constant memory regardless of input size. A list comprehension of the same logic will consume all available RAM on anything over a few million records. I saw this crash a production system that processed log files averaging four gigabytes each. The original code used a list comprehension for a filtering operation. Switching to a generator cut peak memory usage from nearly sixteen gigabytes to under two hundred megabytes. The processing time increased by about twelve percent due to the overhead of yielding, but the system stayed stable instead of swapping to disk.
Get the Full Details

Pitfalls That Come Up Again And Again
One issue with selection structures is the implicit assumption that conditions are mutually exclusive. In many languages, an if/elif/else chain stops at the first true condition. If your conditions overlap and the order matters, you need to be explicit about it. A temperature regulation system I reviewed had an elif chain checking sensor ranges. Two adjacent ranges had a one-degree gap where neither condition matched. The system defaulted to off during that gap, causing the heated chamber to fluctuate by plus or minus three degrees around the setpoint. The fix was adjusting the boundary values to eliminate the gap entirely. Iterative structures also have an underrated problem with mutation. When you modify the collection you're iterating over, the behavior becomes unpredictable in most languages. Remove an element from a list while a for loop walks it, and you'll skip the next element. Add elements, and you might enter an infinite loop. The workaround is straightforward: iterate over a copy, or build a new collection, or use an iterator that supports safe removal. I prefer the approach of collecting removals in a separate list and applying them after the loop completes. It's slightly more verbose but makes the intent clear and the behavior deterministic. The real pain point with sequencing is async code. When you introduce asynchronous operations, sequential flow breaks down visually even though it still executes sequentially under the hood. Event loops, callbacks, and promises create an illusion of parallelism that confuses debugging. I spent two days tracking down a timing bug in a Node.js service where a database query appeared to return before the connection pool was ready. The sequencing in the source code looked correct. The event loop's execution order did not match the visual layout. Wrapping the setup in an initialization function that returned a promise and awaiting it at the top level resolved the issue, but the lesson was that readable sequential structure doesn't guarantee sequential execution in async contexts.
When These Patterns Stop Working
There are cases where basic sequencing selection and iteration simply aren't the right tool. State machines with complex transitions are better modeled as tables or graphs than as deeply nested conditionals. Recursive problems like tree traversals or directory listings become stack overflow risks with iterative approaches at sufficient depth. Parallel processing requirements often make flat iteration impossible because the order of operations becomes irrelevant or harmful. For heavy numerical computation, iterative Python loops are orders of magnitude slower than vectorized operations in libraries like NumPy. A loop processing one million floating point values in pure Python can take fifteen to twenty seconds. The equivalent vectorized operation takes roughly eighty milliseconds. The sequential logic is identical. The execution model is what differs. If you're doing this kind of work in Python, you need to understand when to stay in the interpreter and when to push the operation down to C-level code through a library. Another limitation worth noting: these structures don't handle non-deterministic inputs gracefully. If your selection depends on external state that changes between checks, you'll get race conditions in any multi-threaded environment. The standard workaround is locking or moving to an actor model, but both add complexity that makes the original sequencing harder to follow. For systems where this is a primary concern, consider whether a reactive architecture with observable streams would reduce the surface area of these issues rather than layering synchronization primitives on top of imperative code.
Practical Steps For Applying Sequencing Selection And Iteration Correctly
Start each function by writing out the intended sequence in plain English. Three to five sentences maximum. If you can't describe the flow without using the word "then" more than twice, you probably have nested logic that needs restructuring. Then identify which parts require selection and which require iteration. Selection means different outcomes based on input. Iteration means repeating the same outcome across multiple inputs. Mixing these up is more common than you'd think. Test boundary conditions separately. The middle case usually works. The edges are where sequencing breaks, selection misses branches, and iteration runs one time too many or one time too few. A loop that processes ten items should be tested with zero, one, ten, and eleven items. Each boundary reveals different failure modes. The selection inside that loop might handle zero correctly by returning early, fail at one by processing the first item twice, succeed at ten, and then either include the extra item or miss the last one depending on whether you used a less-than or less-than-or-equal comparison. Keep the structure flat whenever possible. Nested depth beyond three or four levels is a signal that your logic needs to be decomposed into smaller functions. Each function should handle one sequence, one selection, or one iteration. If a function does all three, split it. The resulting code is longer but significantly easier to debug, and you'll find that most of the bugs in complex systems come from functions that tried to handle too many control flows at once.