Deploying without a checklist is how you miss things
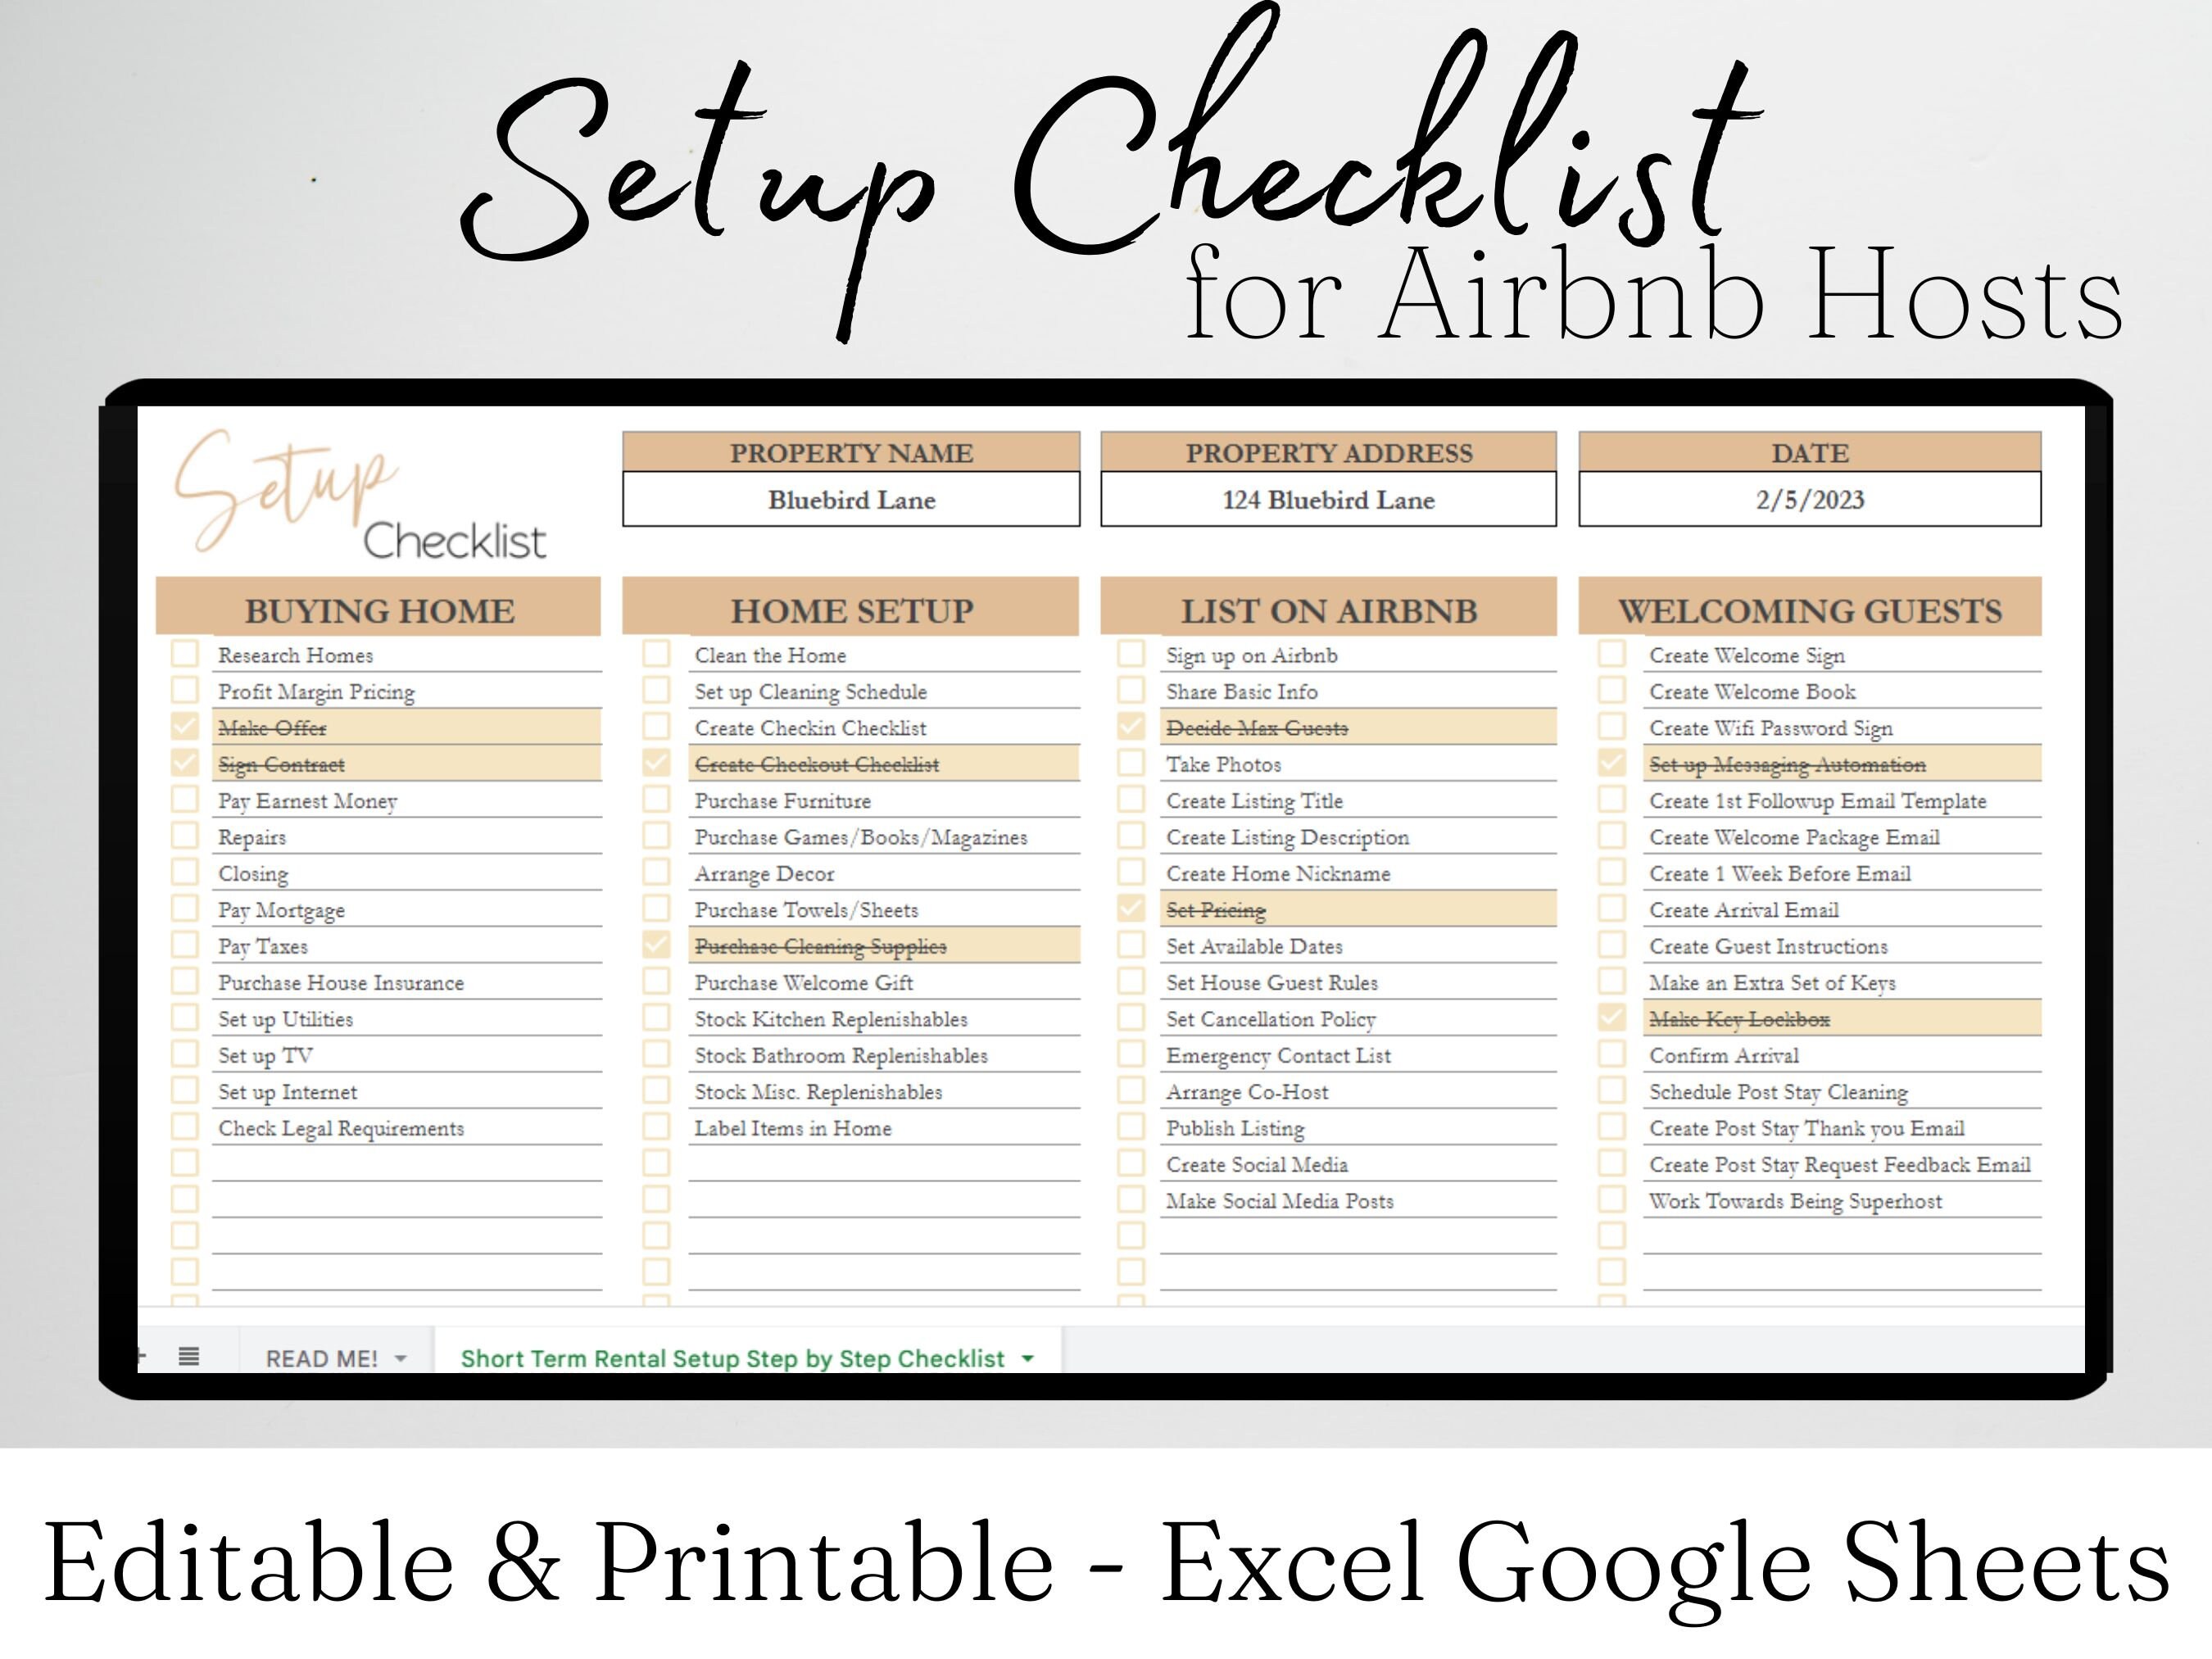
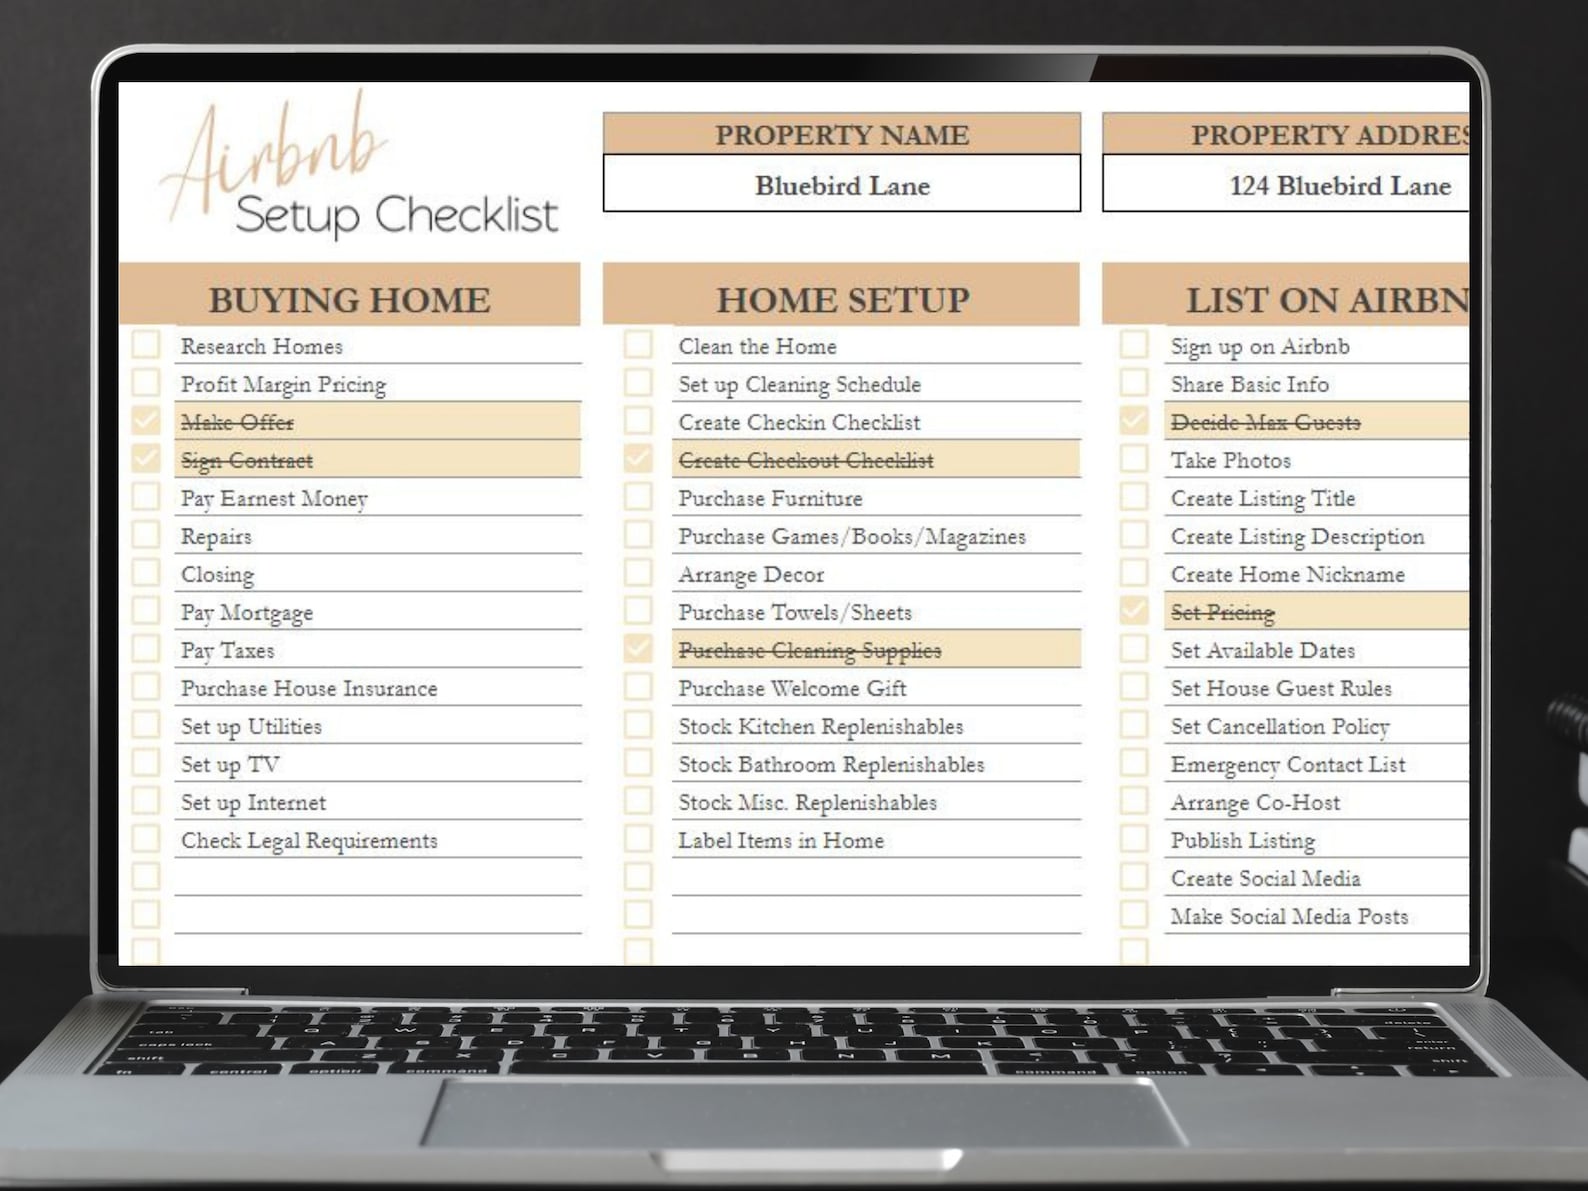
I've been through enough production rollouts to know that the difference between a clean deploy and a 3 AM war room call is usually a piece of paper. Not a fancy diagram, not a project management ticket, just a plain list of steps you go through and check off as you actually do them. A Setup Guide Checklist isn't some theoretical concept — it's the thing that keeps you from forgetting that one environment variable you always seem to skip, or the database migration step that has to run before the app starts. It's a sequential, version-controlled document that maps the exact order of operations for provisioning a system, service, or application in a given environment. It covers everything from prerequisites and dependency installation through configuration, validation, and handoff. The key word is sequential. Most people don't realize that the order of steps matters more than the steps themselves. Running a migration after the app starts is a classic failure mode that no amount of automation can catch if the checklist doesn't enforce it. I once spent two days debugging a service that kept crashing on startup because a Redis connection pool was being initialized before the cache node was fully accepting connections. The fix wasn't complex — it was adding a readyz health check with a retry loop to the setup sequence. But we only found it because someone on the team actually wrote down the startup order in a checklist and worked through it line by line instead of winging it. That experience is why I don't skip them anymore, even for small services.
How to build one that actually works
Start by running through the setup manually in a clean environment first. Don't write anything down until you've done it at least once and know where the rough edges are. When you do write it up, be brutally specific about what success looks like for each step. "Verify connectivity" means nothing. "Run pg_isready -h $DB_HOST -p 5432 and confirm it returns 'server is ready'" means something. Structure it in phases rather than a flat list. Group things into sections like prerequisites, infrastructure provisioning, application configuration, data migration, validation, and cleanup. People tend to skip steps when they're buried in a long unstructured list. Clear section breaks keep you from going back and forth between unrelated tasks. Version it alongside your code. I keep mine in the repo under docs/setup/ with the same branch/tag system as everything else. If you update the deployment script but forget to update the checklist, they diverge and neither one is trustworthy. The checklist should reference specific commit hashes or tags for dependencies when it matters. "Use Kafka 3.6" is fine for a blog post. In a real setup guide, "use kafka_2.13-3.6.1.tgz from the internal artifact registry" is what prevents the person following it from accidentally pulling 3.7 and hitting a schema incompatibility.
Common things people miss
Rollback procedures. Nobody writes rollback steps until something breaks and then they're scrambling. Include a section that documents the exact sequence to undo each change — which migrations to reverse, what config keys to remove, how to point the DNS back. This takes about ten minutes to write when you're not in an incident. Environment parity checks. If you have dev, staging, and prod, the checklist should call out which steps differ between them. I've seen setups where the staging environment had a different max_connections setting that caused a working application to fail in production because nobody documented the difference in the setup instructions. Dry-run validation. Before declaring the setup complete, build in a verification step that actually exercises the system, not just a port check. A server responding on port 8080 doesn't mean your app is functional. Run the health endpoint, hit a write path, verify the queue consumer is draining. This usually adds about five minutes to the process but catches the kind of issues where everything looks green until a real request comes in.
Get the Full Details
There are limits to what a checklist can do. It can't replace testing, and it can't account for unexpected vendor API changes or hardware failures. If your setup depends on a SaaS provider and their SLA doesn't cover degraded performance, no amount of checklist writing will save you from that scenario. In those cases, having fallback configuration options documented is the closest you get to coverage. I recommend keeping a separate contingency section for known failure points rather than trying to hardcode every possible edge case into the main flow.
Download the Template
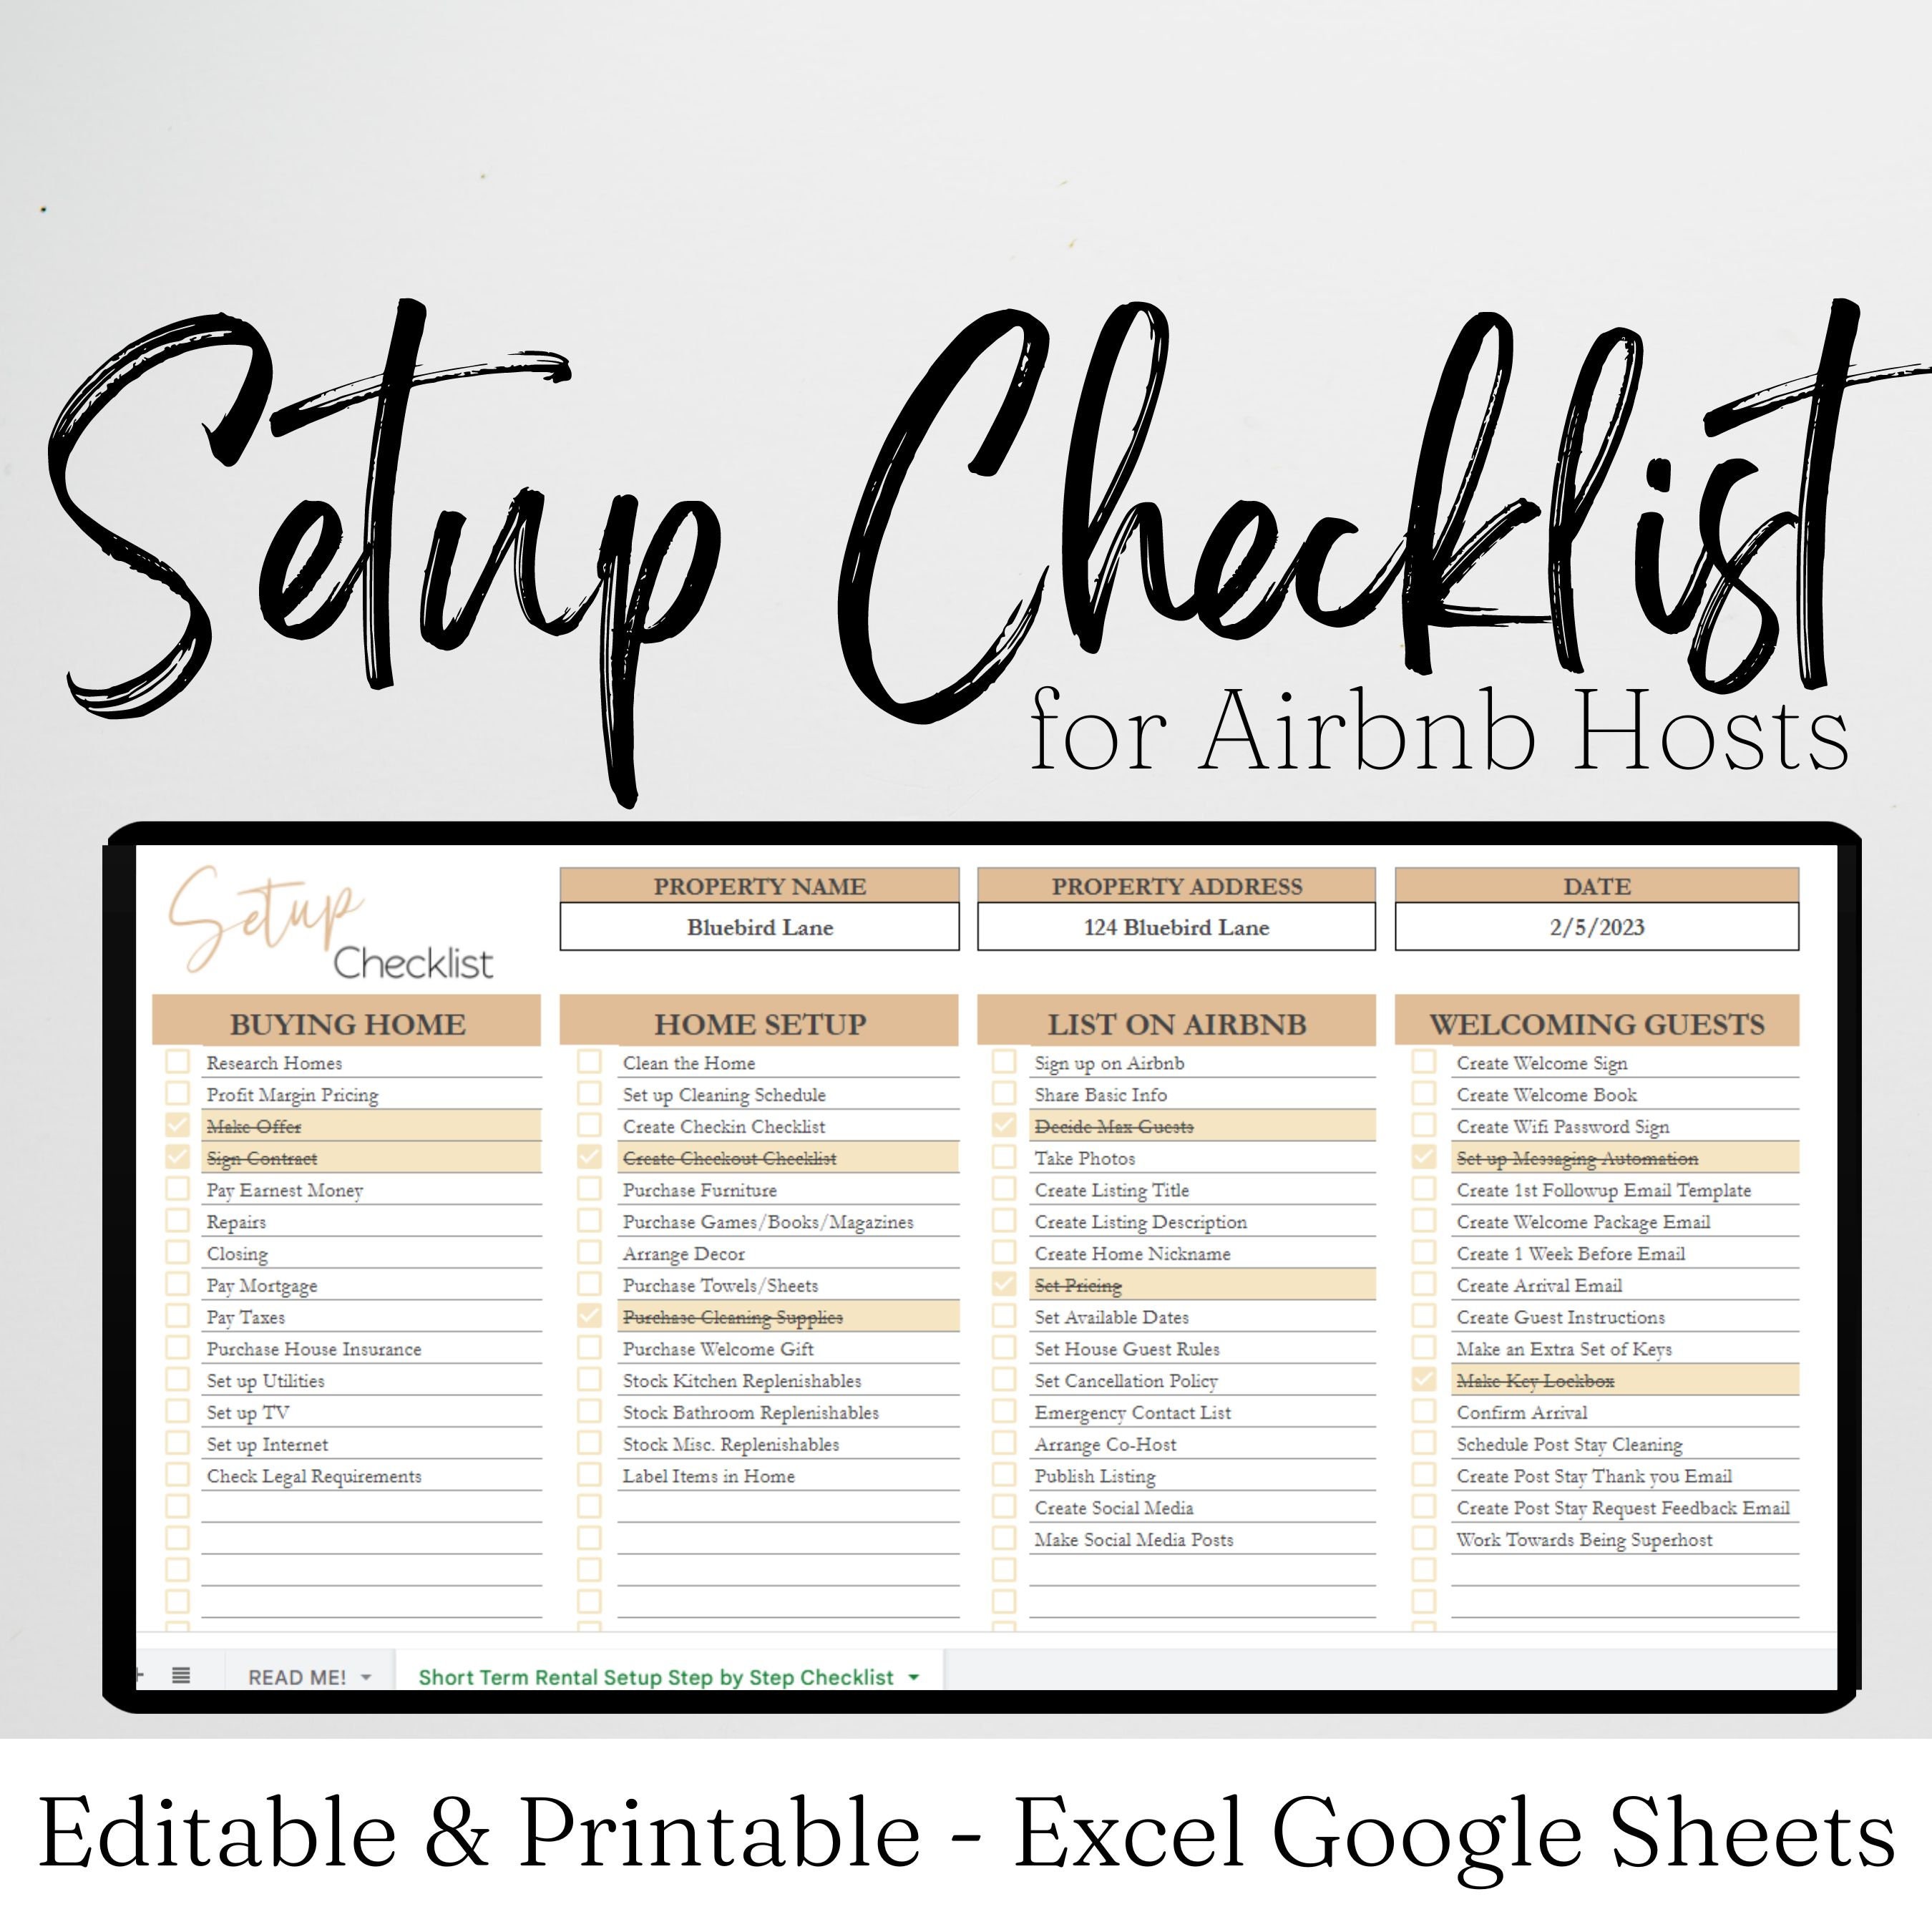
A basic Setup Guide Checklist template is available in the repository. It's structured around the phases I mentioned — prerequisites, provisioning, configuration, migration, validation, and rollback — with placeholders for environment-specific notes and the kind of concrete verification commands that actually work. Nothing fancy. It's meant to be copied into your project and filled in, not treated as a final document. The value is in the gaps you fill, not the blanks you start with. The thing most people get wrong is treating the checklist as a one-time document. It should be updated every time you encounter a step that isn't clear, every time someone on the team gets stuck, and every time you add a new service to the stack. A checklist that hasn't been touched in six months is probably wrong. Trust that. Then go find out where it's wrong and fix it.