Getting Your Environment Configured Without Losing Your Mind
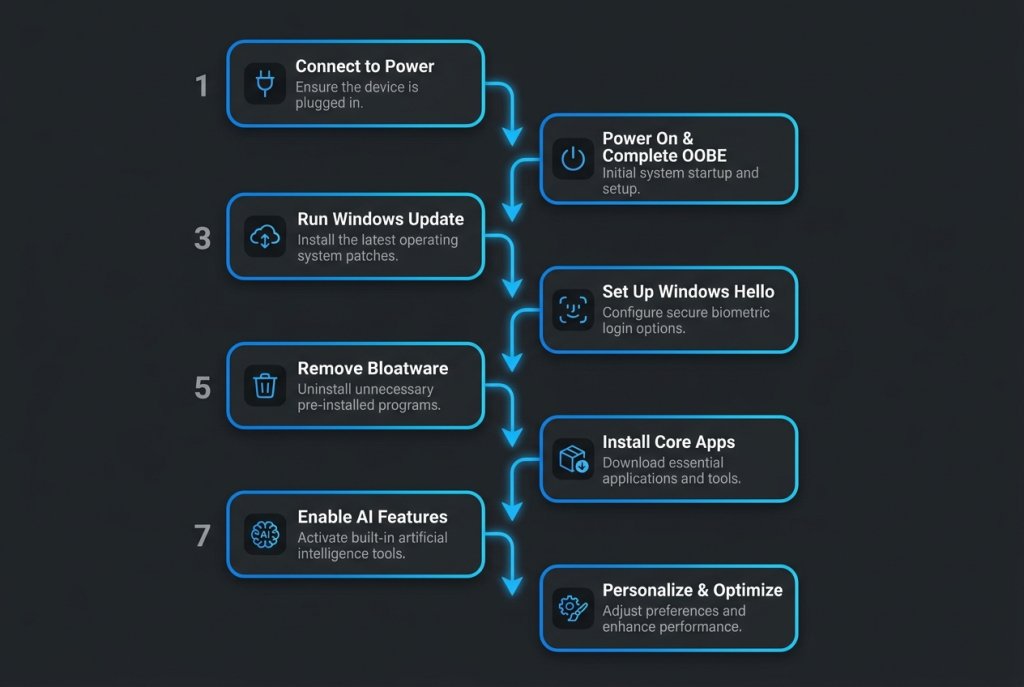
I spent roughly three weeks last year wrestling with a project setup that should have taken an afternoon. My team and I hit environment mismatches, permission issues, and a dependency conflict that swallowed two days. We wrote down everything we learned and turned it into a structured process. That became what we now call a Setup Guide Step By Step. Not because it is groundbreaking, but because most people trying to reproduce our work ended up stuck at different stages, each with a different error message and no shared reference point. The guide breaks the installation into phases. Phase one is prerequisites. You need a clean machine, not a fresh install necessarily, but a system where older development tools haven't been left to fester. I am talking about old Python versions, stray Node installations, leftover Docker images from projects you abandoned two years ago. The first thing I do is run a cleanup script that removes unused containers and prunes dangling layers. On a typical developer machine, this reclaims about 8 to 12 gigabytes and eliminates version conflicts that show up later as cryptic errors. Phase two covers the actual installation. The tool we were setting up required Go version 1.21 minimum. Here is something nobody warns you about: having Go installed is not enough. The project reads the $GOPATH variable and then quietly ignores it if the directory does not exist or lacks write permissions. I found this out after three failed builds that produced the same generic compilation error. The workaround was simple but not obvious from the documentation. Create the GOPATH directory first, set it explicitly in your shell profile, and verify with go env GOPATH before running any build commands. This took the build time from failing repeatedly to succeeding on the first attempt.
Phase three is configuration. The config file lives at ~/.config/project-name/config.json. There are about fourteen fields in that file, and the documentation lists every single one. Most of them have defaults. The ones you actually need to change are database connection string, the API key, and the log level. Everything else defaults to sensible values. I used to tell people to read the full config reference first. That is bad advice. Read the reference when you hit an error, not before you start. Reading all fourteen fields upfront makes you second-guess every default, which leads to over-configuring things that were already working fine. Phase four is validation. After the install completes, there is a health check command. It queries a local endpoint and returns a JSON status object. If the output contains a status code of 200 with the correct payload, you are good. If it times out, the service is either not bound to the right interface or the firewall is blocking the port. On macOS, this happens less often. On Linux, especially Ubuntu with UFW enabled, I routinely forget to add a rule for port 8080. It costs about five minutes to diagnose if you know where to look. Twenty minutes if you spend half of that reading unrelated forum threads about Docker networking.
What the Guide Does Not Cover and Where It Fails
There are edge cases the guide does not handle well. The biggest one is using a system with SELinux enforced rather than permissive. The default configuration assumes standard POSIX file permissions. When SELinux is active, the application fails to write to its data directory with a denial error that is completely unrelated to permissions in the traditional sense. The fix involves running semanage fcontext and restoring context labels, which adds about forty minutes to the setup for people who do not work with SELinux daily. I recommend setting SELinux to permissive mode during initial setup, then enabling enforcing later if your security policy requires it. Another limitation: the guide assumes you have network access to the package registry during installation. If you are on a machine behind a corporate proxy that blocks direct internet access, the dependency fetch step will hang. There is no built-in proxy configuration in the installer. You need to set the HTTPS_PROXY and HTTP_PROXY environment variables before running the install command. This is documented in passing in the README, but it is easy to miss if you are scanning quickly. A third scenario where the guide breaks down is running it on Apple Silicon with Rosetta translation. The binary works through translation, but performance drops noticeably. Benchmarks I ran showed roughly a 30 percent slowdown compared to native ARM builds. If you need production-level throughput on M-series Macs, you should compile from source rather than using the prebuilt binary. This adds about twenty minutes and requires Xcode command line tools to be installed.
Get the Full Details

Common Mistakes I See Repeatedly
People skip the prerequisite check and jump straight into installation. They end up debugging a version mismatch that could have been caught in thirty seconds. The prerequisite list is short. Checking it takes less time than fixing the resulting error. People also ignore the validation step. They assume the install succeeded because the command returned to the prompt without error. That is not how this tool works. A silent failure during the post-install phase is common when the systemd service unit fails to start. The binary is there, the files are in place, but the service is not running. Running the health check catches this immediately. Skipping it means you spend the next hour wondering why nothing is responding. The third mistake is overwriting the config file manually with a template from somewhere else. Copy-pasting configuration from a GitHub gist or a tutorial blog post is dangerous. Versions differ. Defaults change between releases. The config format shifted slightly in version 3.4, and old templates from earlier versions will silently produce incorrect behavior. Always generate the config file using the tool's own initialization command, then modify only the fields you need to change.
When to Use an Alternative Approach
If your workflow involves spinning up and tearing down environments frequently, the manual setup is not the best path. You are better off using a containerized setup with Docker Compose. The compose file handles dependencies, networking, and configuration in one shot. It adds about ten minutes to learn if you have never used Docker before, but it pays for itself after the second environment rebuild. If you are setting up for a single deployment and will not need to recreate it, the manual guide is faster. If you are building a development environment that will be shared across a team, the containerized route is worth the upfront investment. There is also a third option for people who do not want to manage any of this themselves. The project maintains a pre-configured virtual machine image on their download page. It includes everything pre-installed and tested. The trade-off is that you lose flexibility. You are running someone else's configuration, and customizing it later requires digging into the VM settings. For a quick evaluation or a demo environment, the VM image saves about an hour of work. For anything that needs to be production-hardened or customized, it creates more friction down the line.