How to actually work out molecular geometry when you are doing it for real
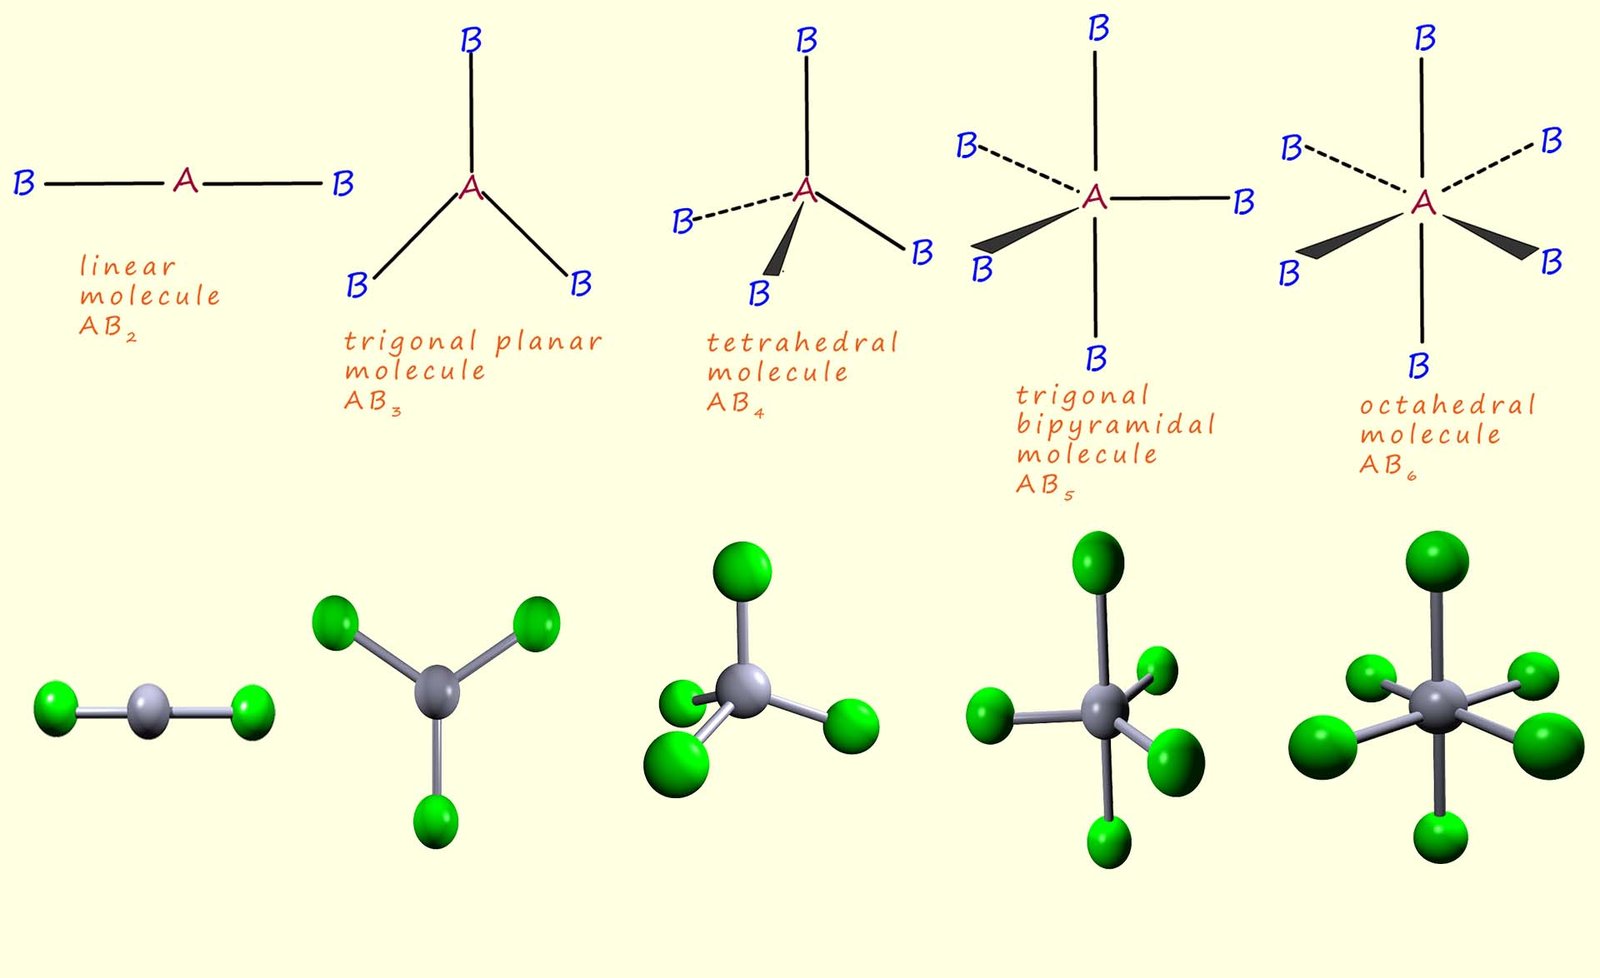
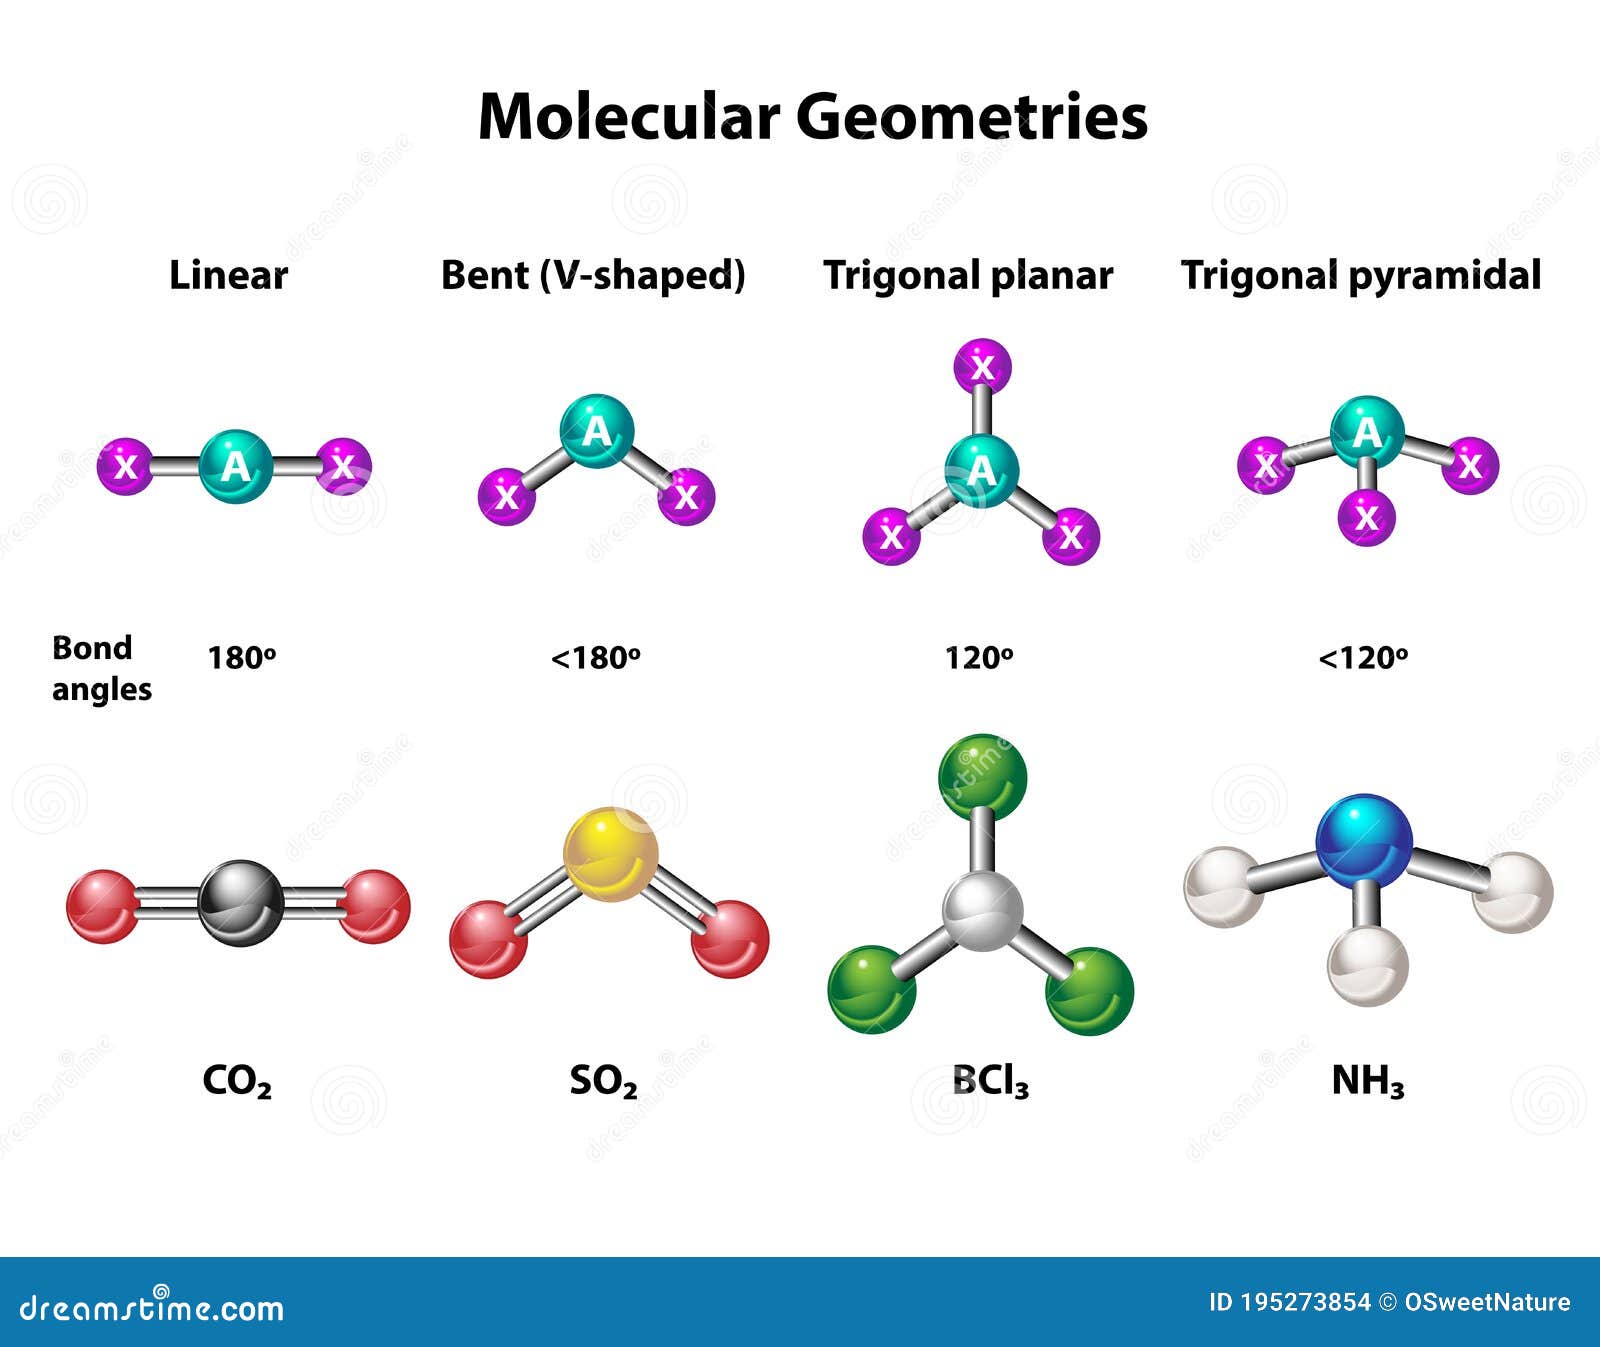
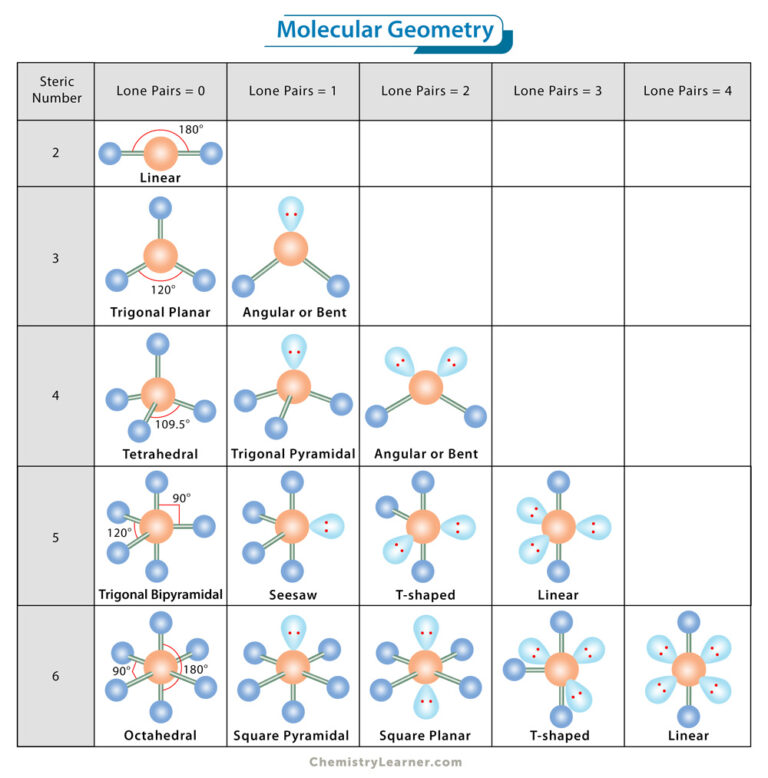
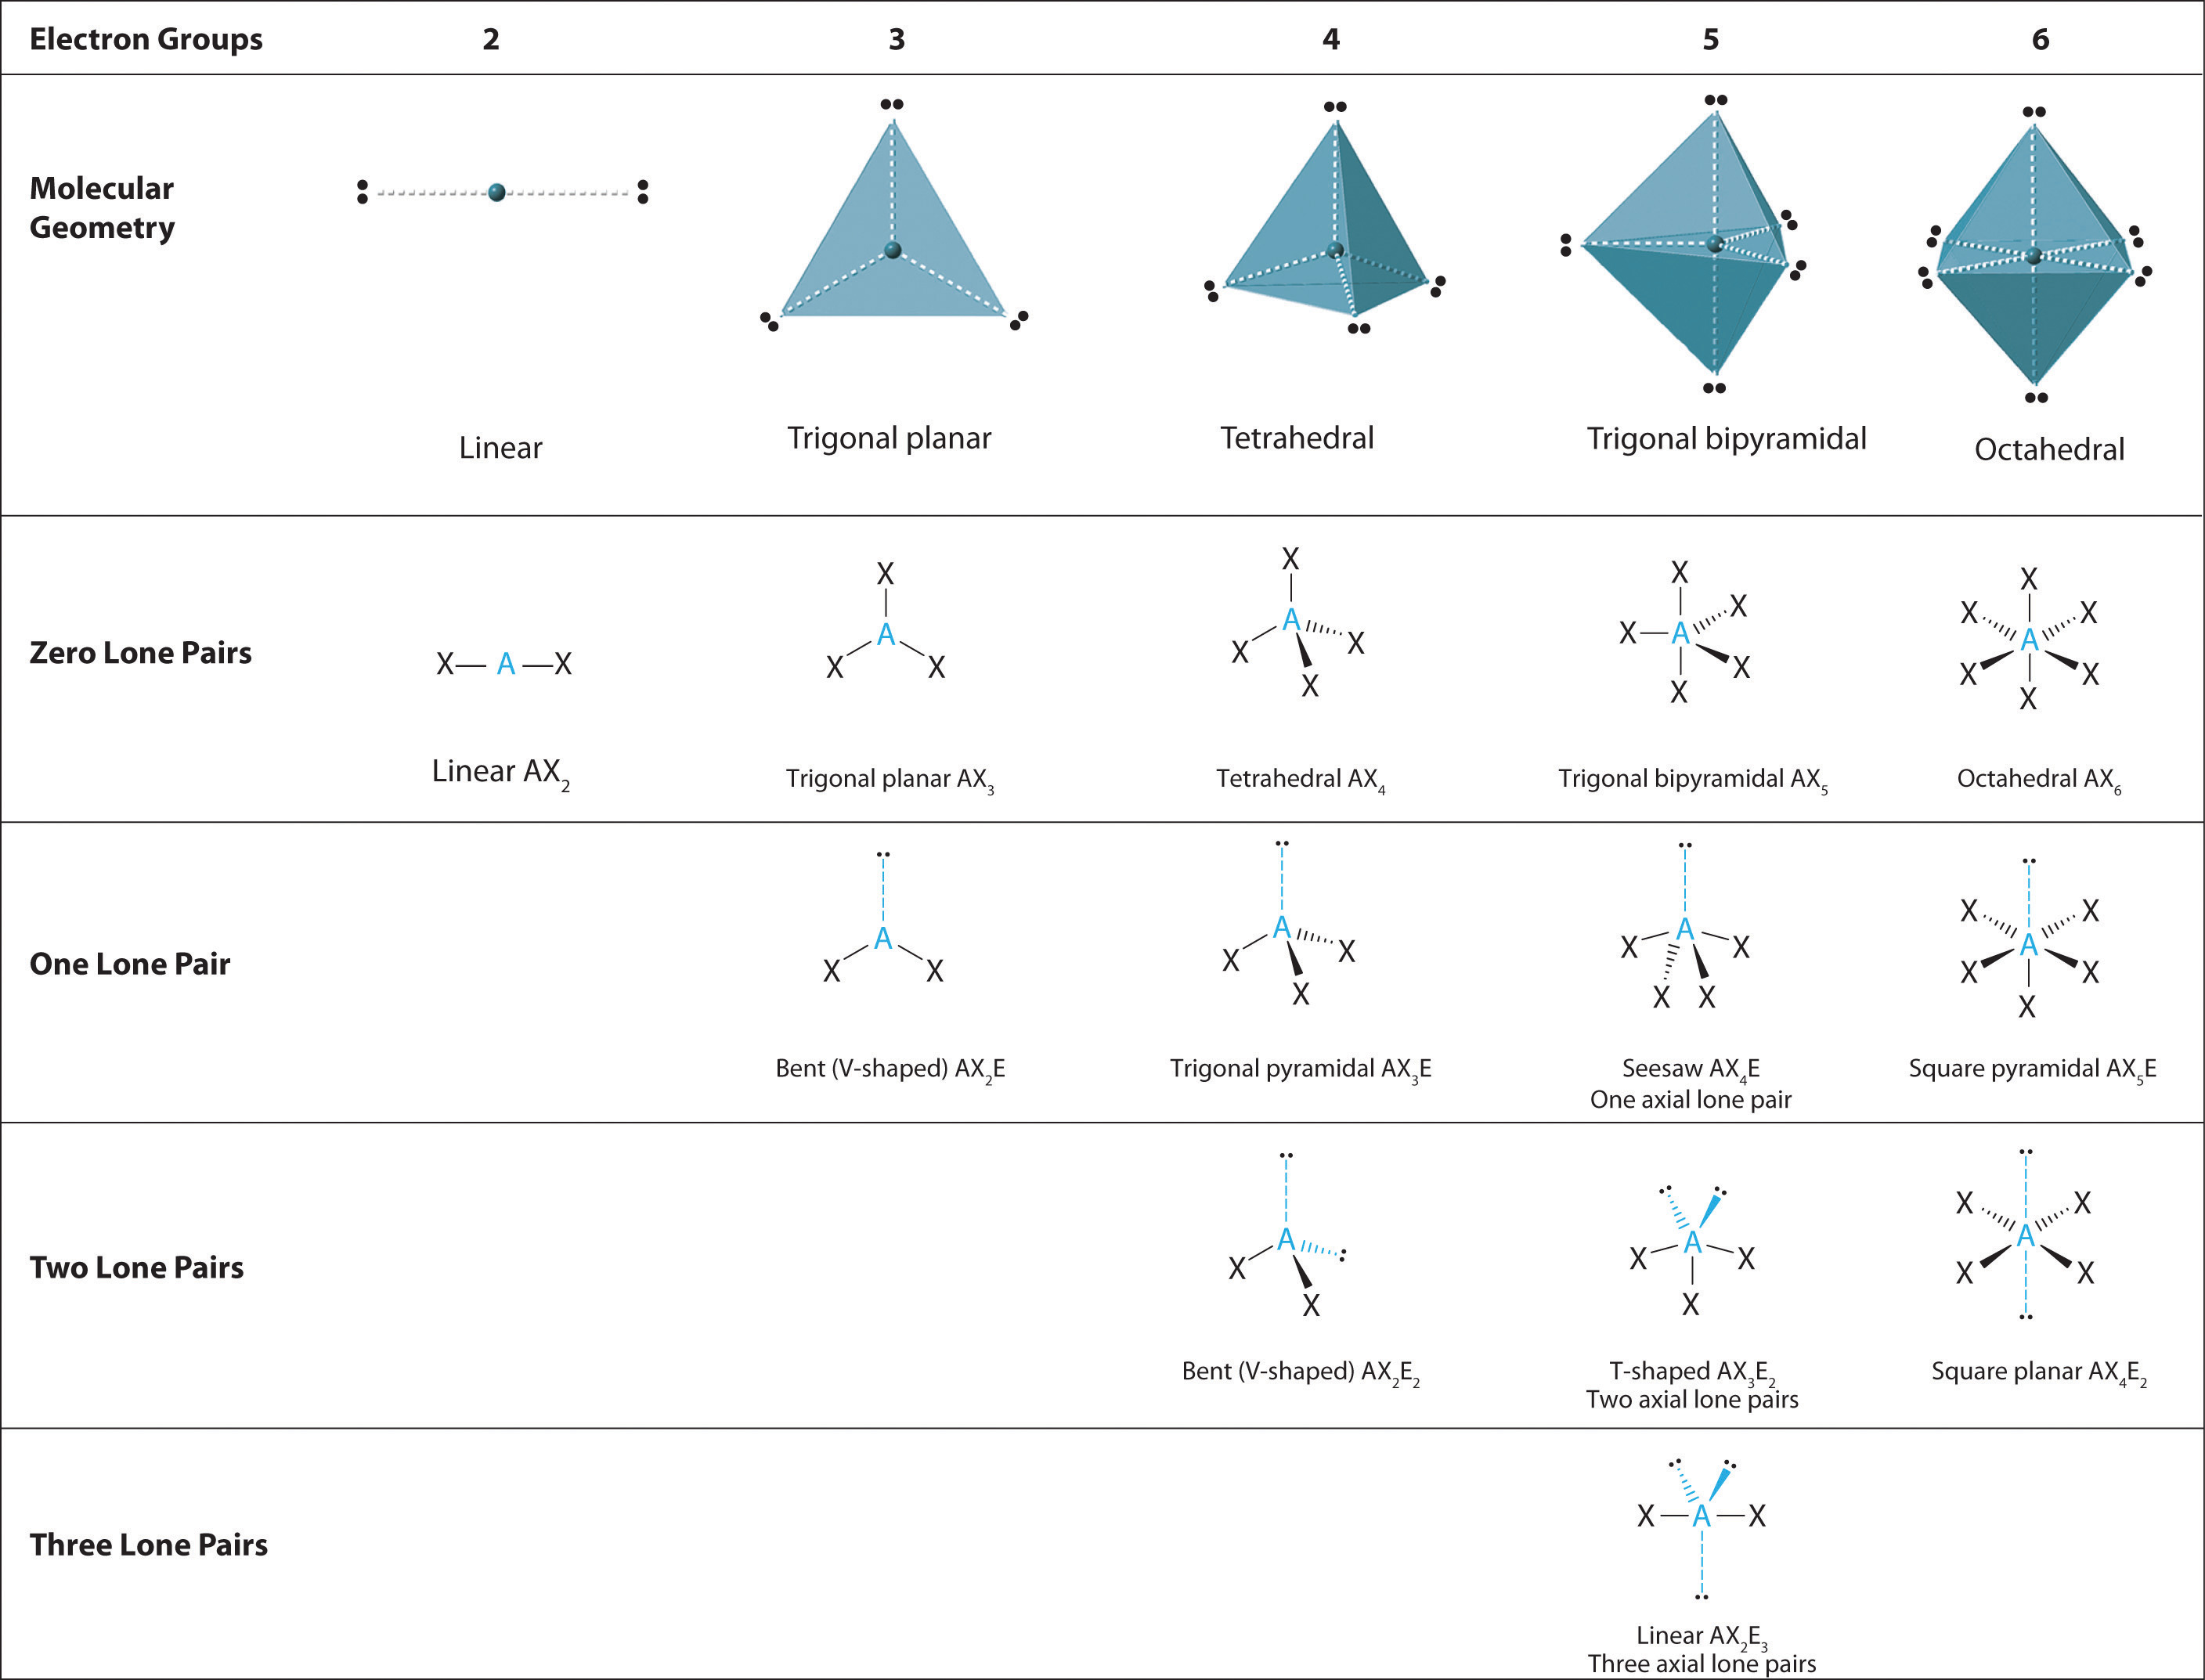
Most people learn VSEPR theory in a single lecture and then immediately forget how to apply it once they hit anything beyond simple cases. I have spent years modeling molecular structures for a living, and the gap between textbook diagrams and what molecules actually do is enormous. The process of determining Shape And Geometry Of Molecules requires more than counting electron pairs and drawing dots on a whiteboard. The first step is always building the Lewis structure correctly. Get that wrong and everything downstream collapses. I cannot count how many times students and junior researchers hand me a molecule with the wrong formal charges and expect me to debug the geometry. Formal charge matters. It determines which atom carries the lone pairs, and lone pairs are what distort the geometry away from the ideal arrangement. Here is where beginners consistently mess up. They count regions of electron density around the central atom and stop there. The number of bonding pairs versus lone pairs is what actually defines the shape, not just the total steric number. A steric number of four gives a tetrahedral electron geometry regardless, but the molecular shape depends entirely on how many of those four regions are bonds. Three bonds and one lone pair produces a trigonal pyramidal shape, not a tetrahedron. The bond angles drop from 109.5 degrees to roughly 107 degrees because the lone pair occupies more space. This is not subtle. It is the single most common mistake I see.
I once had a project where we were modeling nitryl fluoride, NO2F. The Lewis structure looks straightforward. Five valence electrons from nitrogen, six each from the two oxygens, seven from fluorine. You draw it with nitrogen in the center, double-bonded to one oxygen, single-bonded to the other oxygen and to fluorine. Steric number of three. Trigonal planar electron geometry. But the actual molecular geometry is bent at the oxygen-nitrogen-oxygen angle, and the F-N-O angles are noticeably wider than the O-N-O angle. Why? Because the double-bonded oxygen exerts more repulsion than the single-bonded ones. The Cramer rule of thumb here is that double bonds occupy more angular space than single bonds, and lone pairs occupy even more. You need to account for that when predicting real bond angles. For NO2F specifically, the O-N-O angle comes out around 125 degrees, while the F-N-O angles sit closer to 117 degrees. The experimental data from electron diffraction confirmed this. Textbook VSEPR would tell you all angles are roughly equal in a trigonal planar arrangement. They are not. The deviation is significant enough that if you were building a computational model based on equal angles, your energy calculations would be off by several kilocalories per mole, which is a meaningful error in anything involving reaction pathways.
Tools and techniques used in practice
When I am working on actual molecules rather than homework problems, I rely on a combination of computational chemistry software and spectroscopic data. Gaussian, ORCA, and Psi4 are the standards. You input the atomic coordinates and the program iteratively minimizes the energy until it finds the most stable geometry. The output gives you bond lengths, bond angles, and sometimes dihedral angles for larger molecules. One thing that is worth understanding is that different computational methods give different results, and the method you choose depends on the molecule. Hartree-Fock is fast but often inaccurate for geometries involving heavy atoms or transition metals. Density functional theory, particularly B3LYP or M06-2X, tends to be more reliable for organic molecules and gives reasonable geometries at a fraction of the cost of post-Hartree-Fock methods like CCSD(T). The problem is that DFT functionals vary, and some perform better for bond lengths while others are better for angles. You need to know which functional your system responds to well. Spectroscopy validates what the software predicts. Microwave spectroscopy gives rotational constants that translate directly into moments of inertia, which constrain the possible geometries. Infrared spectroscopy shows vibrational modes that are sensitive to bond angles. If your calculated geometry predicts a vibrational frequency that does not match the experimental spectrum, the geometry is wrong and you need to rethink your model. I have seen people trust their computational output without checking against experimental data, and then wonder why their predicted reactivity patterns made no sense.
Get the Full Details
Common pitfalls when working with complex systems
Treating every molecule as if it follows simple VSEPR rules is a trap. Take xenon tetrafluoride, XeF4. The steric number is six with two lone pairs, giving an octahedral electron geometry. The molecular geometry is square planar because the two lone pairs occupy opposite positions. This is textbook material. But now consider a transition metal complex like cisplatin, Pt(NH3)2Cl2. The geometry is square planar, which seems similar on the surface, but the driving force is completely different. It is not lone pair repulsion around a central atom. It is d-orbital splitting and crystal field effects that stabilize the square planar arrangement over tetrahedral. If you try to explain this using VSEPR alone, you will get confused because the theory was never designed for transition metal complexes. Another frequent issue involves hypervalent molecules. Phosphorus pentachloride, PCl5, has five bonding pairs and zero lone pairs, giving a trigonal bipyramidal geometry. But the axial and equatorial bonds are not equivalent. The axial bonds are longer and weaker than the equatorial bonds. When you put PCl5 in solution, the axial chlorines are far more reactive than the equatorial ones. The standard VSEPR treatment does not explain this difference. Molecular orbital theory does, through the concept of three-center four-electron bonds in the axial positions. If you ignore this distinction in your models, your predictions about reactivity will be wrong. I ran into a case recently where I was modeling the geometry of a sulfur-containing heterocycle with an unusual substitution pattern. The computational output showed bond angles that did not match any simple hybridization scheme. The ring was puckered in a way that pure VSEPR could not account for. What was actually happening was a combination of steric strain from bulky substituents and hyperconjugation effects that stabilized one conformation over another. The fix was to run a conformational search using a force field like MMFF94 to generate starting geometries, then refine with DFT at the B3LYP/6-311+G(d,p) level. The initial geometry from the force field was off by about 8 degrees in the critical angle, which would have led to incorrect conclusions about the molecule's dipole moment if I had used it without optimization.
Why this matters beyond the classroom
Understanding molecular geometry is not an abstract exercise. It determines how molecules interact with each other. Protein-ligand binding depends on the three-dimensional shape of both the binding pocket and the drug molecule. If the geometry is wrong, the binding affinity prediction is meaningless. Enzyme catalysis relies on precise geometric alignment of reactive groups. Material science uses molecular geometry to predict how polymers pack and how crystal structures form. Even something as routine as predicting solubility depends on molecular shape because shape affects how molecules stack and interact with solvent. The limitations are real though. Computational geometry optimization can get stuck in local minima rather than finding the global minimum structure. For molecules with flexible chains or multiple rotatable bonds, the conformational space can be enormous. A molecule with ten rotatable bonds has potentially millions of conformers, and sampling them all is computationally expensive. The workaround is usually a combination of systematic search and Monte Carlo sampling, but this adds time and complexity to the workflow. Another limitation is that gas-phase calculations do not always translate to solution behavior. Solvent effects can shift bond angles and favor conformations that are not stable in vacuum. Implicit solvation models like PCM or SMD help, but they are approximations. If you need high accuracy, you should use explicit solvent molecules in your model, which increases the computational cost significantly. For a medium-sized organic molecule, going from gas-phase optimization to solvated geometry optimization can increase calculation time from a few hours to several days on the same hardware.
The bottom line is that Shape And Geometry Of Molecules is a foundational concept that is deceptively simple to understand and genuinely difficult to master in practice. The basic rules work for simple molecules. Once you move into transition metals, hypervalent systems, or molecules with significant steric strain, you need more sophisticated tools and a deeper theoretical background. Knowing when the simple approach breaks down is more important than memorizing the rules.