Compressing PDFs Without Losing Your Mind
PDFs get bloated. Images embedded at full resolution, fonts that shouldn't be there, metadata from every editor that touched the file. You end up with a 50MB document when you need something that fits under 5MB for upload. I spent years going through every online compressor before finding a workflow that actually sticks. The direct approach is using Ghostscript's command line tool. It's built into most Linux distributions and available for macOS and Windows. Here's what the actual command looks like when I run it: ghostscript -sDEVICE=pdfwrite -dCompatibilityLevel=1.4 -dPDFSETTINGS=/screen -dNOPAUSE -dQUIET -dBATCH -sOutputFile=output.pdf input.pdf
The /screen flag gives you the lightest compression. /ebook is the sweet spot for most cases — 150 DPI for images, reasonable font subsetting, metadata stripped. If you're dealing with scanned documents, you might want to start with /prepress and then downsample, because /screen will make text blurry on some scans. One thing people miss: Ghostscript will rewrite your PDF structure entirely. That means any interactive elements like form fields, bookmarks, or attached files can disappear. I learned this the hard way when a client sent me a PDF form that they needed back filled out, and I compressed it without realizing the form fields were gone. Took twenty minutes to rebuild them. For files where interactivity matters, try setting -dPreserveEPSInfo=true and -dRenderModes=/Slow. It slows the process down but preserves more of the original structure. Output time goes from about 30 seconds to maybe 2-3 minutes for a 40-page document on a decent machine. Still faster than doing it by hand.
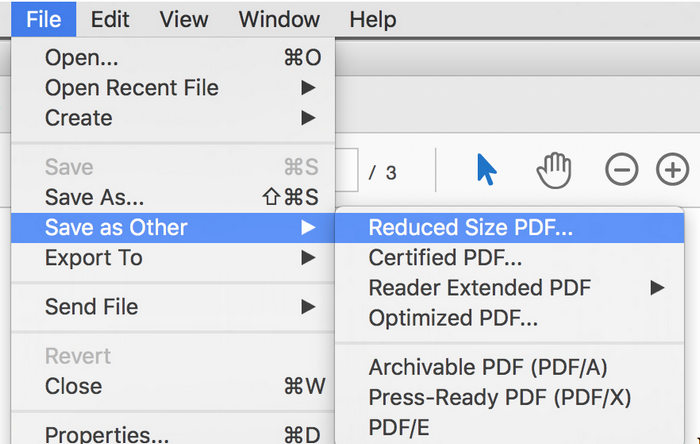
If you don't have Ghostscript installed or need something more visual, Adobe Acrobat Pro's "Save As Other > Reduced Size PDF" does the same heavy lifting under the hood, just wrapped in a GUI. The settings dialog lets you pick a compatibility level and whether to discard bookmarks and attachments. Discard attachments if you don't need them — that alone can cut 30-40% off a file that has embedded images or supplementary documents. For Python users, the pikepdf library with PyMuPDF as a backend handles this cleanly. A basic reduction script runs in about 10 seconds for a typical 20-page document. The tradeoff is you need to manage dependencies, which is why I stopped recommending it unless someone is already comfortable with pip. Online tools exist, obviously. iLovePDF, Smallpdf, PDF24 — they all do compression. But they have a hard limit on file size (usually 50-100MB), they upload your data to someone else's server, and they often compress more aggressively than you'd want. The aggressive setting on these tools tends to apply uniform compression across the entire document, which means text-heavy pages get needlessly degraded just to compensate for one high-res image. Ghostscript lets you target specific objects. That's the difference between a usable output and one that looks like a watermark.
Get the Full Details

Here's a practical edge case: documents that contain vector graphics exported from Illustrator or Inkscape. These often come with embedded preview images at full resolution inside the SVG, even though the vector data is what matters. Ghostscript sees that embedded raster image and can't tell the difference. My workaround was to open the source SVG first, remove the embedded preview, save it, then re-insert it into the PDF before running compression. Saves maybe 200MB in a single pass on files that have multiple heavy illustrations. Another gotcha: color profiles. If your PDF has an embedded ICC profile and you're compressing for screen viewing, stripping the profile can actually cause colors to shift worse than if you'd left it alone. Use -dColorImageResolution=72 and keep the profile if color accuracy matters. For purely text-based documents, strip everything. The realistic expectation: you'll get 60-80% reduction on a typical image-heavy PDF with Ghostscript's /ebook setting. Scanned documents without OCR might only see 40-50% because the compression can't deduplicate what's essentially random pixel data. If you need further reduction after Ghostscript, the next step is OCR with tesseract on the scanned pages, which converts raster to text and usually drops file size dramatically. That's a separate pipeline entirely, but it's worth knowing about if your PDFs are all scans.
Keep the original uncompressed file around. I know it feels wasteful, but compressed PDFs are destructive — you can't recover the original images or embedded content once Ghostscript has processed them. One client lost a 300DPI photograph embedded in a report because they only kept the compressed version and needed to reprint it at full quality. Saved me about an hour of explaining why it was gone.