Getting a Skills Improvement System Assessment Right
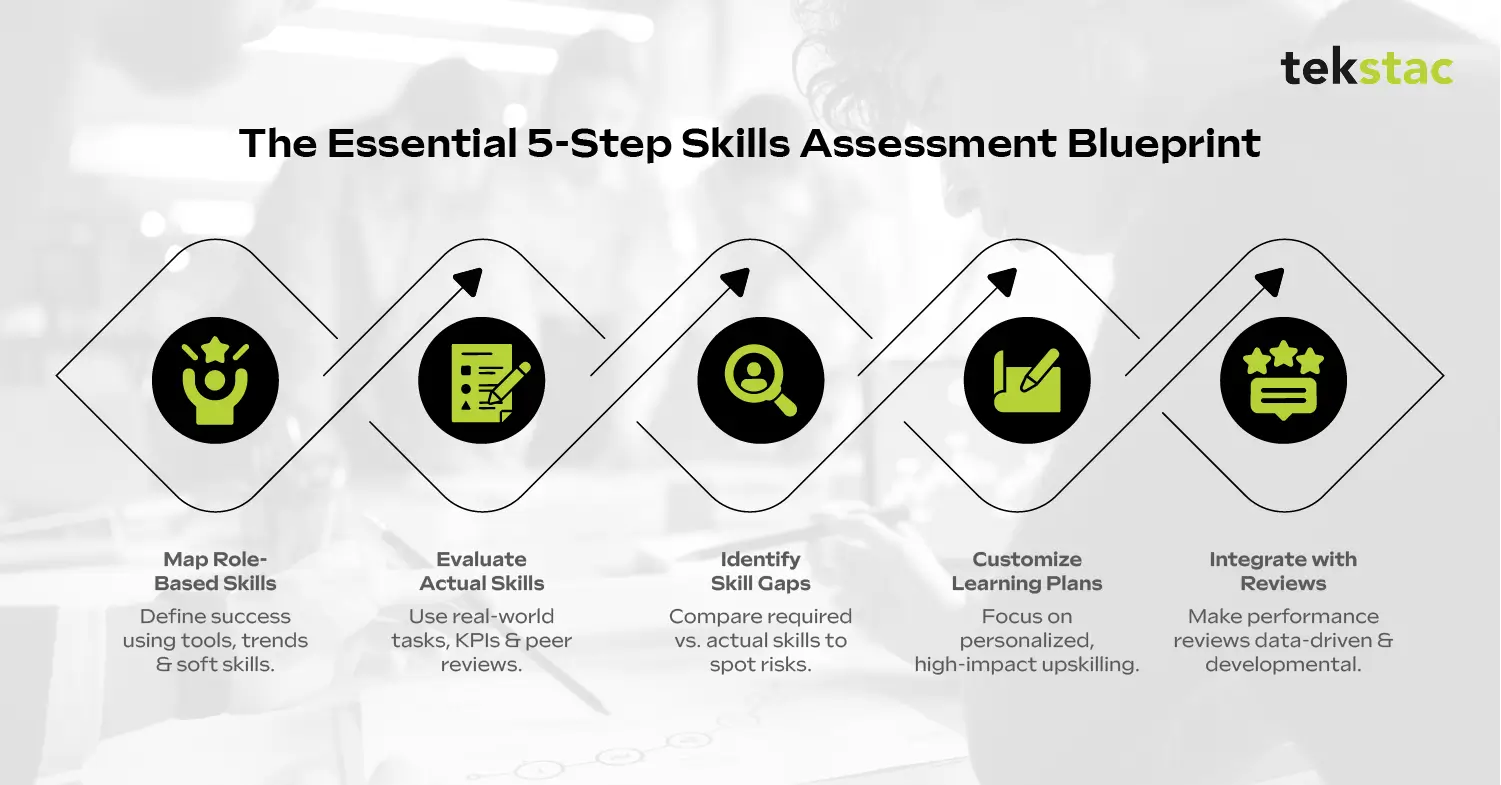
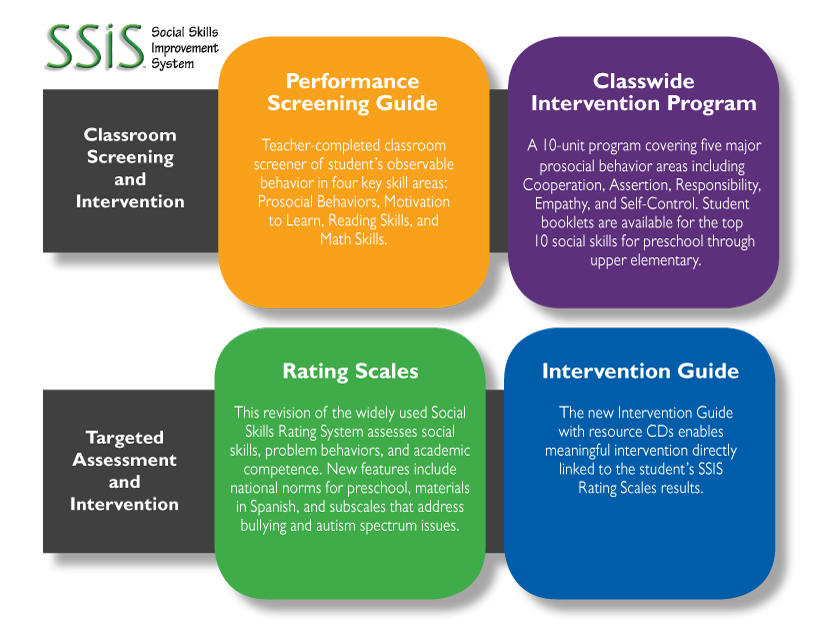
Most people treat skills tracking like it is a spreadsheet with a progress bar. They log hours, mark boxes, and call it improvement. That is not how it works. I spent three years running this for a mid-size engineering team and learned the hard way that the gap between what you think you can do and what you actually can do is where things break.A Skills Improvement System Assessment is fundamentally a structured audit of current capability against a desired benchmark, combined with a tracked pathway to close the gap. The tricky part is that most organizations define the benchmark too vaguely. "Good at Python" does not exist in practice. You need specific, observable behaviors. Can they build a REST API from scratch? Can they write and run integration tests? Can they debug a memory leak in C++? I built ours out of nothing but Google Sheets and honest conversations. Then I realized that approach collapsed after about 40 people in the department. The data became untrustworthy because everyone calibrated differently. One manager thought "proficient" meant they could complete a task with help. Another thought it meant they could teach it to someone else. Same label, completely different reality. The system has four working parts: the skill dictionary, the assessment method, the gap analysis, and the improvement tracker. Everyone focuses on the tracker. That is the wrong emphasis. The skill dictionary is the foundation. If your dictionary is sloppy, the rest of the system produces garbage output. We ended up with about 200 discrete skills across the org. Not abstract competencies like "leadership" but concrete abilities like "can refactor a monolithic service into three bounded contexts without breaking existing contracts."
The assessment method matters more than people realize. Self-assessment alone is dangerous. People systematically overrate themselves by about 15 to 20 percent when left to their own devices. Manager assessment introduces bias. The solution I found was a combination of demonstrated work plus calibrated peer review. Give people a real task. Not a quiz. A task they would actually do on the job. Then have two other people who know the domain evaluate the output against a rubric. The correlation between self-rating and peer-rated actual performance was roughly 0.43. That is not good enough to build a system on.
The Calibration Problem Nobody Talks About
When I first rolled this out, I hit a wall at month four. The data showed 87 percent of staff were progressing toward their goals. It was statistically impossible. What actually happened was that managers were inflating ratings to avoid uncomfortable conversations. I caught it because the improvement trajectories made no sense. Someone claimed to go from novice to expert in a framework in six weeks. That does not happen unless the person already knew it and was just not crediting themselves earlier. The workaround was a blind calibration round. I took 20 random assessment records from different managers, stripped the names, and had three senior leads re-rate them independently. The inter-rater reliability came back at 0.61. That is mediocre at best. We spent three weeks going through the discrepancies and aligning definitions. After that, reliability jumped to about 0.82. The system became usable. That calibration step is non-negotiable if you want the data to mean anything. Skip it and you are building on sand. Here is what most people miss: the improvement tracker is the least interesting part of the system. The most valuable output is the skill dictionary itself. It forces the organization to explicitly define what excellence looks like for each role. That conversation is where the actual cultural shift happens. People arguing about whether "debugging" should be a standalone skill or part of "problem solving" ends up clarifying more than any training program ever could.
Get the Full Details
Building the Skill Dictionary
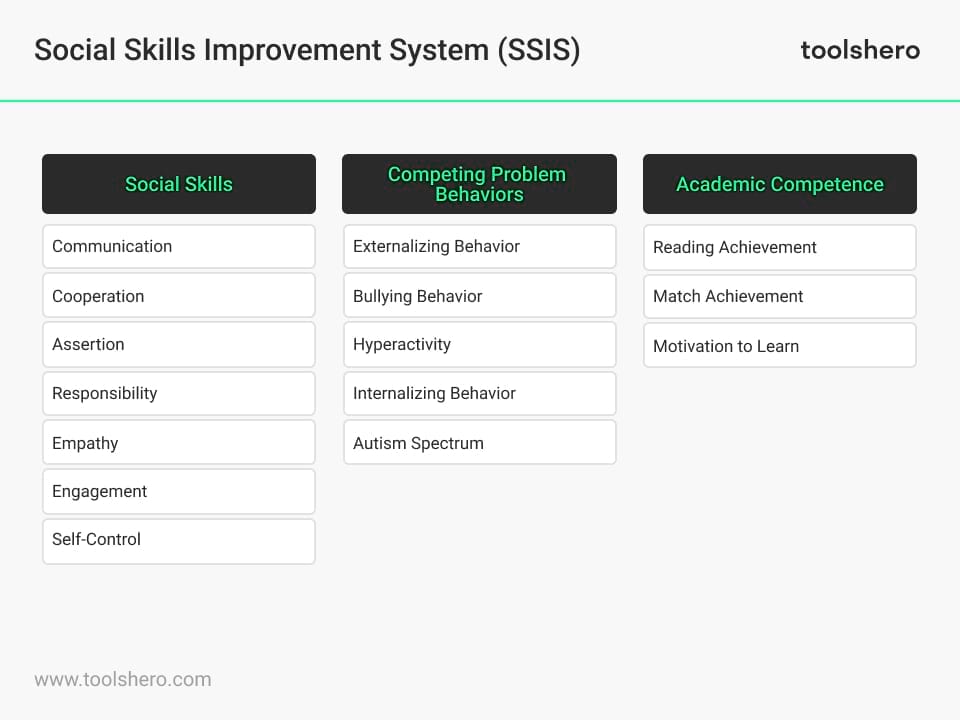
Start with role-based clusters. Don't try to assess every human at the company against the same framework. A developer, a project manager, and a salesperson do not share enough common ground for a unified skill list to work well. Create separate dictionaries per functional area, then identify cross-cutting skills like communication or tools that appear across multiple dictionaries. Each skill entry needs a clear description, observable indicators at four levels, and a typical experience range. The four levels should be something like: foundational, developing, proficient, and expert. But define what each level means in behavior, not in time. "Three years experience" is not a skill level definition. "Can independently architect and implement a solution for a moderately complex problem with minimal guidance" is. The latter tells you something actionable. We used a modified Delphi method for building the dictionary. Six subject matter experts per cluster reviewed the draft independently, marked disagreements, then met for a structured session to resolve them. The first two clusters took about 40 hours each. After that, we got faster, down to roughly 20 hours per cluster. Rushing this step is the single biggest mistake I see. A poorly defined skill dictionary leads to assessments that measure the assessor's mood rather than actual capability.
The Assessment Cycle That Actually Works
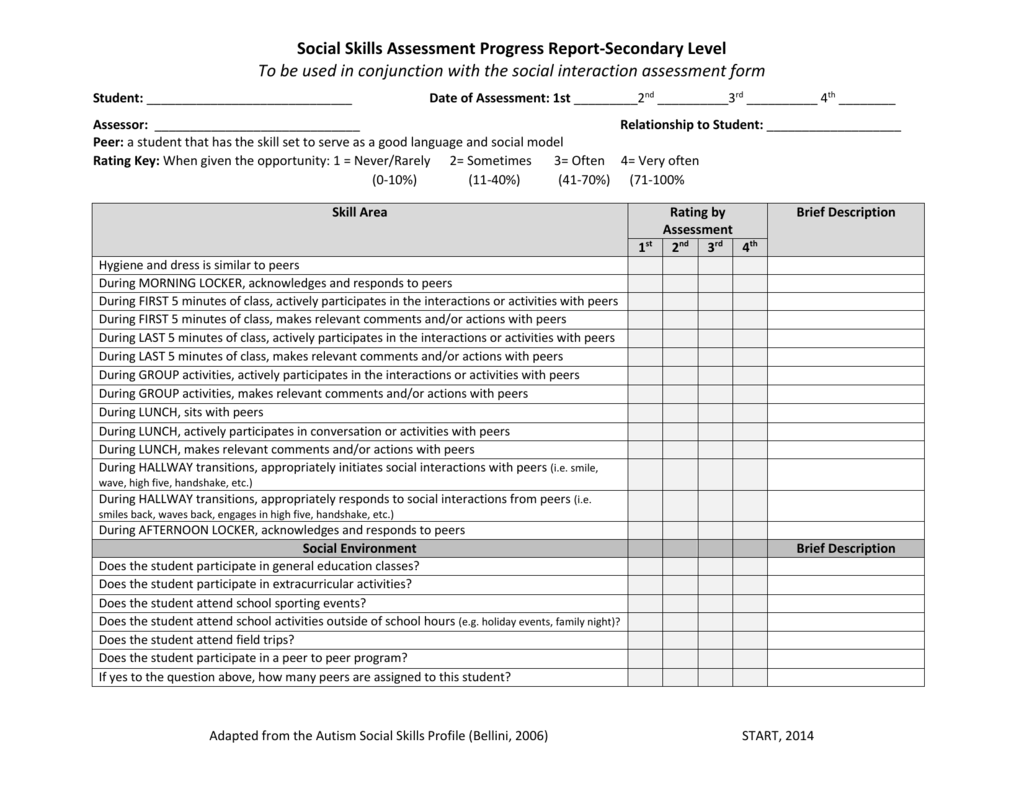
Annual assessments are too infrequent. Quarterly is the minimum cadence that captures meaningful change. Monthly is ideal but creates administrative overhead that most teams cannot sustain. We landed on a hybrid: quarterly formal reassessment with monthly lightweight check-ins where people log completed learning activities and self-reported confidence shifts. The formal assessment takes about 45 minutes per skill cluster. That includes the demonstrated work task, peer review, and the calibration discussion with the manager. For a typical engineer with 12 skills in their cluster, that is roughly nine hours of focused assessment work per quarter. Budget for it or it will get cut when things get busy. And they always get busy. I ran into a specific edge case around month eighteen that almost broke the whole system. We had a contractor whose contract was being evaluated for renewal, and the assessment data showed a significant gap between their self-reported level and their peer-assessed level on two critical skills. The contractor pushed back hard, claiming the peer reviewers were biased and the task was unfairly difficult. Standard procedure would have been to dismiss the complaint and proceed, but the data was actually messy. The peer reviewers had only worked with this person on two projects and both were high-pressure situations where communication was poor. The task itself had an ambiguous requirement that tested judgment more than technical ability.
The fix was to bring in a third reviewer who had never worked with this person, giving them full context about the role and the evaluation criteria, and repeating the task with clarified requirements. The new assessment moved the rating from "developing" to "proficient" on both skills. The original peer ratings were not wrong per se, but they were based on incomplete information. This taught me that assessment quality depends heavily on the reviewers' familiarity with the person's work context, not just their technical expertise. A senior engineer who has never collaborated with the person being assessed is often a worse rater than a mid-level colleague who has.

Turning Assessment Data Into Actual Improvement
This is where most systems fail. You collect the data, produce the reports, and then nothing changes. The assessment becomes a compliance exercise. To prevent that, every assessed gap must have a corresponding improvement action with a deadline and a success metric. Not "take a course" but "complete project X using skill Y by date Z, demonstrated through a code review or deliverable accepted by at least one peer." The improvement path needs to be specific enough to execute and flexible enough to adapt. People abandon plans that are too rigid. We allowed a 20 percent adjustment window between assessment cycles. If someone's project priorities shifted or a planned learning opportunity fell through, they could revise the improvement plan without restarting the whole process. That flexibility kept adoption rates above 70 percent instead of the typical 30 to 40 percent I see in other organizations. Linking assessment results to compensation or promotion decisions is controversial and usually counterproductive if done too directly. It incentivizes gaming the system. We kept assessment data separate from compensation decisions, using it only for development planning. Promotion decisions used a different criteria set that referenced the skill dictionary but was not mechanically derived from it. This reduced the incentive to inflate ratings and improved data honesty significantly.
Common Pitfalls
Overassessing is real. When we first launched, we tried to assess 60 skills per person across five clusters. It took two weeks per cycle and people hated it. The effective number was probably closer to 25. The extra 35 skills were either too granular to measure meaningfully or redundant with existing ones. Cutting the list improved both data quality and participation rates. Assessment fatigue sets in around month six of any continuous program. People start treating it as paperwork. We combated this by rotating the depth of assessment each cycle. One quarter you do a full deep assessment on half your skills and a quick pulse check on the other half. The next quarter you flip. This keeps the cognitive load manageable and surfaces different information each cycle. Another issue is the recency bias in peer reviews. Reviewers tend to rate based on the last three months of interaction rather than the full assessment period. We solved this by requiring reviewers to cite specific examples from different time periods. If they could not produce examples from at least two separate quarters, the review was flagged for reconsideration. This did not eliminate the bias but reduced its impact considerably.
What This System Cannot Do
A Skills Improvement System Assessment does not predict performance. It describes current capability relative to a defined standard. There is a difference. Someone can score high on paper skills and underperform in practice due to motivation, team dynamics, or unclear priorities. The system measures ability, not output. Do not conflate the two. It also does not replace good management. A skilled manager with strong interpersonal relationships will often know their team's capabilities better than any assessment tool. The system is most valuable in organizations where managers lack the bandwidth or expertise to evaluate all skills across all team members. In small teams of fewer than ten people where everyone works closely together, the overhead may outweigh the benefit. The data is only as good as the calibration. If you skip the calibration rounds or treat them as a formality, the system produces noise dressed up as insight. Budget time for calibration. It is not optional infrastructure. It is the load-bearing wall.
Skills Improvement System Assessment is not a silver bullet. It is a structured way to make capability visible, track change over time, and create accountability for development. It works when the organization is willing to invest in proper calibration and honest conversations. It fails when treated as another HR metric to box-tick. The tools and templates are straightforward. The discipline required to use them well is not.