What the slope coefficient actually tells you in a regression model
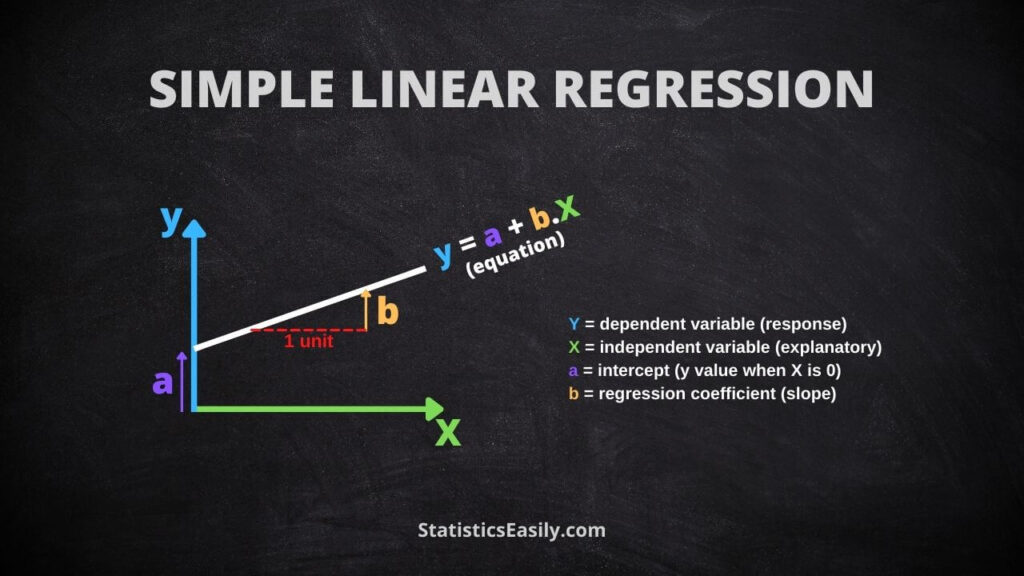
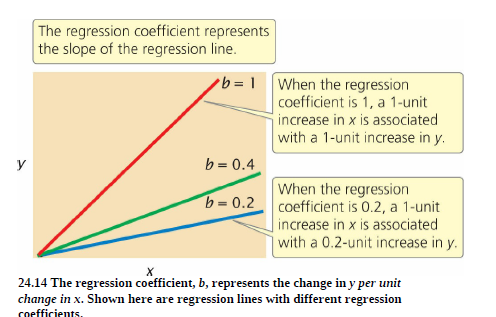
When I first started running regressions back in 2008, I treated the slope coefficient like it was this magical number that captured some kind of fundamental truth about the relationship between variables. That lasted about three months before I learned otherwise. The slope coefficient is literally just the amount the dependent variable changes, on average, when the independent variable goes up by one unit. That's it. Nothing more, nothing less. The thing that people don't tell you in the textbook is that this number is completely meaningless without context. A slope of 2.5 could be incredibly significant or completely noise depending on the standard error, the sample size, and whether you've actually controlled for the right confounding variables. I spent an entire quarter working on a housing price model where the square footage coefficient looked impressive at first glance, then turned out to be picking up neighborhood-level effects because I hadn't included location fixed effects. The coefficient was technically "correct" for the model I specified, but it was telling a lie about what was actually driving prices.
Understanding the Slope Coefficient In Regression Meaning
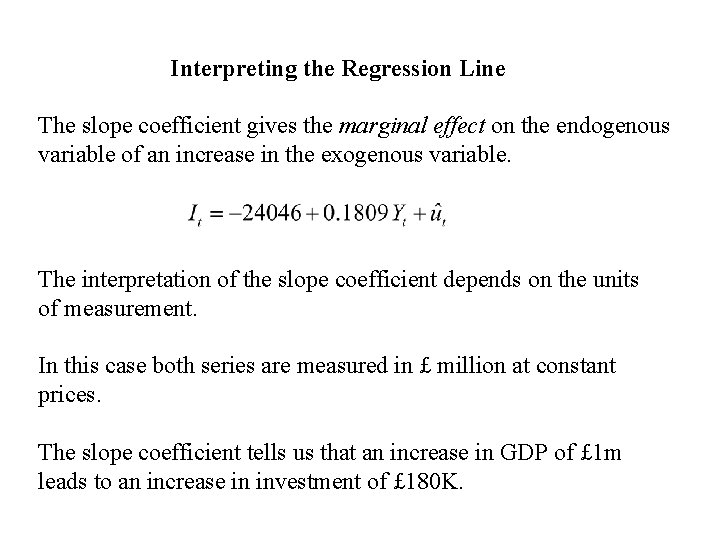
Let me walk through this the way someone would actually encounter it in practice rather than the idealized version from the textbook. You run a regression, you get output that looks something like this: your coefficient estimate, a standard error, a t-statistic, and a p-value. The coefficient itself is the slope. If your independent variable is measured in dollars and your dependent variable is in years, the slope tells you how many years change per additional dollar spent. If both are in the same units, it's a unitless ratio. Simple enough on paper. But here's where it gets tricky. The slope coefficient assumes a linear relationship. This is almost never true in the real world, and nobody who actually works with data keeps this straight in their head every day. I remember building a model for a logistics company where delivery time had a nonlinear relationship with distance because of how drivers scheduled their routes. The slope coefficient for distance was positive and statistically significant, which meant longer distances took longer. But the coefficient was masking the fact that trips over 200 miles were disproportionately expensive because they required overnight stops. A single linear slope can't capture that structure. You need piecewise linear terms or a transformation, or you accept that your coefficient is just an approximation over the range of data you actually observed. Another thing that catches people off guard is multicollinearity. When two independent variables move together, the slope coefficients become unstable. I had a model with income and education level as predictors, and flipping between different specifications produced wildly different coefficient estimates for each variable even though the overall model fit stayed essentially the same. The individual slopes were not identifiable with the data I had. This doesn't mean the model is useless, but it means you should not make strong claims about what any single coefficient represents when your predictors are correlated. A one standard deviation change in one variable while holding the other constant is often a scenario that doesn't exist in your data.
The interpretation also depends heavily on how you've measured your variables. If you log-transform the dependent variable, the slope becomes approximately a percentage change rather than an absolute change. If you log-transform both sides, it's an elasticity. If you use a dummy variable on the right side, the coefficient is a level shift for that category. These distinctions matter more than people realize, and they affect how you communicate results to anyone who isn't going to look at the raw output. There's also the issue of omitted variable bias, which is really just the slope coefficient absorbing effects from variables you didn't include. This is the fundamental problem with causal inference using observational data, and it has nothing to do with statistical significance. A coefficient can be precisely estimated and still be wrong as a causal effect. I worked on a project evaluating the impact of a training program on wages, and the raw coefficient suggested a thirty percent premium. After controlling for prior work experience and industry choice, the effect dropped to eight percent. The coefficient wasn't wrong in the sense that it was miscalculated, but it was wrong as an interpretation of what the program actually did. If you want to check whether your slope coefficient is reasonable, run some basic diagnostics. Plot the residuals against the fitted values. Look for patterns that suggest nonlinearity or heteroscedasticity. Check the leverage and influence of individual observations using Cook's distance. A single outlier can pull your slope in a direction that doesn't reflect the rest of the data. I've seen cases where removing five observations changed a coefficient from positive to negative, which means the relationship was driven by a handful of points rather than being a general feature of the data.
Get the Full Details

Regularization methods like ridge and lasso also affect how you interpret slope coefficients, and not in a way that people always expect. These techniques shrink coefficients toward zero, which reduces variance at the cost of introducing bias. The resulting coefficients are not directly interpretable in the same way as OLS coefficients. You should not report them as if they represent the same quantity. They are useful for prediction, but they don't have the clean ceteris paribus interpretation that ordinary least squares provides. One practical tip that saves time: standardize your continuous variables before running the regression if you want to compare the relative importance of different predictors. A one standard deviation change in each variable puts everything on the same scale. The coefficients become comparable, and you can see which predictors have the largest effects in standardized units. Don't do this if you need to report results in original units for stakeholders, but it's very useful for model building and variable selection. The bottom line is that the slope coefficient is a descriptive summary of the relationship in your data, conditional on the other variables in the model. It is not a causal parameter unless you have made strong assumptions that are hard to verify. It is not stable across different samples if your data generating process changes. And it is almost never the complete story about how the world works. Treat it as a starting point for further investigation rather than a final answer.