Why Your Qualitative Data Analysis Keeps Stalling Out
I spent six months cleaning up a research project where the coding structure collapsed under its own weight. Twenty-six semi-structured interviews, over 400 pages of transcript, and I ended up with a mess of 147 codes that barely overlapped. The project was salvageable but it took another three weeks to fix. That experience taught me more about qualitative analysis than any textbook did. Most people approaching Sociology Hacks Essential dive straight into coding without a structural plan. They open their first transcript, start highlighting interesting passages, and let the codebook grow organically. This works fine for small projects with five or six interviews. Beyond that threshold, the system breaks down. Codes that seemed distinct at the start become conflated. Themes that looked clean in your head don't map onto the data the way you expected. By the time you realize something is wrong, you are deep enough into the dataset that going back and restructuring is costly.
Sociology Hacks Essential: What Actually Helps
Let me walk through the workflow that works, starting from the part everyone skips. Step one is writing a codebook before you touch a single line of transcript. This sounds backwards. You do not have enough data to know what codes you need yet. But you do need a preliminary framework to guide your initial pass. I write a two-page document with five to eight broad parent codes and two to three subcodes under each. These are descriptive, not interpretive. They describe what kind of content belongs under each code, not what it means. For example, instead of a code called "institutional distrust," I write "critiques of institutional effectiveness" with a definition that includes statements about bureaucratic friction, perceived incompetence, and failed service delivery. The interpretive layer comes later, after I have seen how the codes interact across the full dataset.
Step two is the structural read. Read through your entire dataset without coding. Just read. This takes longer than you think but it is where you identify the actual themes rather than the ones you brought into the project expecting to find. My rule of thumb: allow roughly forty-five minutes per hour of interview audio for this pass. You will not remember everything, but you will get a sense of the territory. Step three is the first coding pass with your codebook in hand. Use whatever tool you prefer. NVivo, Atlas.ti, Dedoose, or even a well-structured spreadsheet. The tool matters less than the discipline of applying codes consistently. When you encounter a passage that does not fit any existing code, create a new one but log it in a separate column labeled "pending." Do not integrate it into your main codebook yet. After the first full pass, review all pending codes. You will find that three or four of them collapse into existing categories and one or two warrant new parent codes. Step four is the second pass focused on relationships between codes. This is where most people stop, and it is also where most projects fail to produce publishable analysis. Coding is not the hard part. Understanding why certain codes co-occur, why some never appear together, and what those patterns mean is where the actual work lives. In my stalled project, I had coded everything correctly but had no framework for explaining the distribution of codes across demographic groups. That gap is why the analysis collapsed.
Get the Full Details
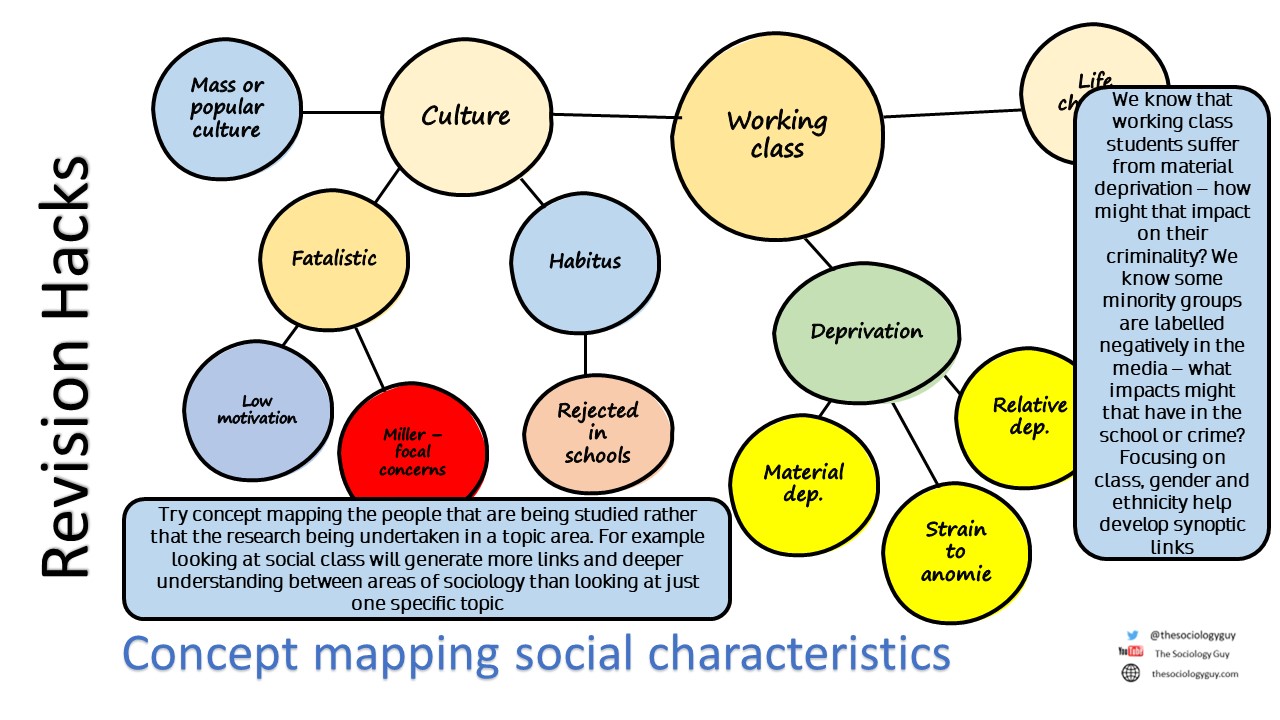
One practical technique for this stage: create a co-occurrence matrix. Most qualitative software can generate this automatically. Look for pairs of codes that appear together significantly more often than chance would predict, and equally importantly, pairs that never appear together. The absences are sometimes more revealing than the presences.
What People Get Wrong
The biggest mistake is treating coding as a finite task rather than an iterative process. You will recode sections of transcript at least twice. The first pass identifies content. The second pass identifies pattern. A third pass is often necessary if your dataset exceeds ten interviews. Accept this upfront. Budget time accordingly. A second mistake is over-coding. Beginners tend to code everything that seems remotely relevant. This creates noise that drowns out signal. If a single paragraph requires three codes to describe it, at least one of those codes is probably redundant or too narrow. Aim for the smallest codebook that still captures the meaningful variation in your data. My heuristic after years of this work: if your codebook exceeds sixty codes for a project under twenty interviews, you are probably being too granular. Counter-intuitive insight: Inter-coder reliability is often overrated for single-researcher projects. Running a second coder through your data and calculating Kappa scores sounds rigorous but it rarely improves your analysis if you are the only person who will interpret the results. What matters more is auditability. Keep a decision log documenting every time you merged, split, or revised a code and why. When you revisit your coding after six weeks and cannot remember your reasoning, that log becomes the single most valuable document in the project.
When This Approach Fails
Sociology Hacks Essential does not work well for projects with highly specialized populations where you lack domain vocabulary. If you are studying a community or subculture you have no familiarity with, your preliminary codebook will be off-base and the structural read alone will not fix that. In those cases, you need preliminary ethnographic engagement or at minimum a thorough literature review before you can build a functional coding framework. No workflow shortcut replaces genuine subject matter engagement. The approach also breaks down with extremely large datasets. Once you cross roughly fifty interviews or two hundred pages of transcript, the manual iterative process becomes impractical and you should consider computational assistance. Tools like qualitative text analysis packages with automated code suggestion can help, but they introduce their own problems around false positives and the loss of contextual nuance. There is no clean solution at that scale, only tradeoffs. Another limitation: this method assumes your data is textual or transcript-based. If your primary material is visual, spatial, or interactional, the coding framework needs substantial modification. Phenomenological photography analysis, for instance, requires a different structural approach than interview transcript analysis. The principles of iterative refinement still apply, but the mechanics differ enough that you cannot simply copy-paste the workflow.

Practical Timeline Estimates
For a standard project with ten to fifteen interviews and roughly two hundred pages of transcript, here is what I typically see: structural read takes four to six hours spread across multiple sessions. First coding pass with codebook takes eight to twelve hours. Second pass focused on relationships takes another six to ten hours. Writing the analysis from the coded data takes the longest, usually twelve to twenty hours depending on your comfort with academic writing. Total effort lands somewhere between thirty and forty-eight hours of concentrated work, plus additional time for revision and reorganization. If you are working under a tighter deadline, the structural read and first coding pass can be condensed but you should not combine them. Reading without coding and coding while reading are different cognitive tasks and doing both simultaneously produces shallower analysis. The minimum viable approach is: quick read through, codebook creation, then code. Do not skip the codebook step even if you are pressed for time. The downloadable resources available online for Sociology Hacks Essential mostly offer template codebooks and checklist PDFs. I have found the templates useful as starting points but they are not substitutes for the actual work of building your own framework from your data. Use them to save time on formatting, not on thinking.