How Socratic Reasoning Actually Works for Multimodal Zero Shot Tasks
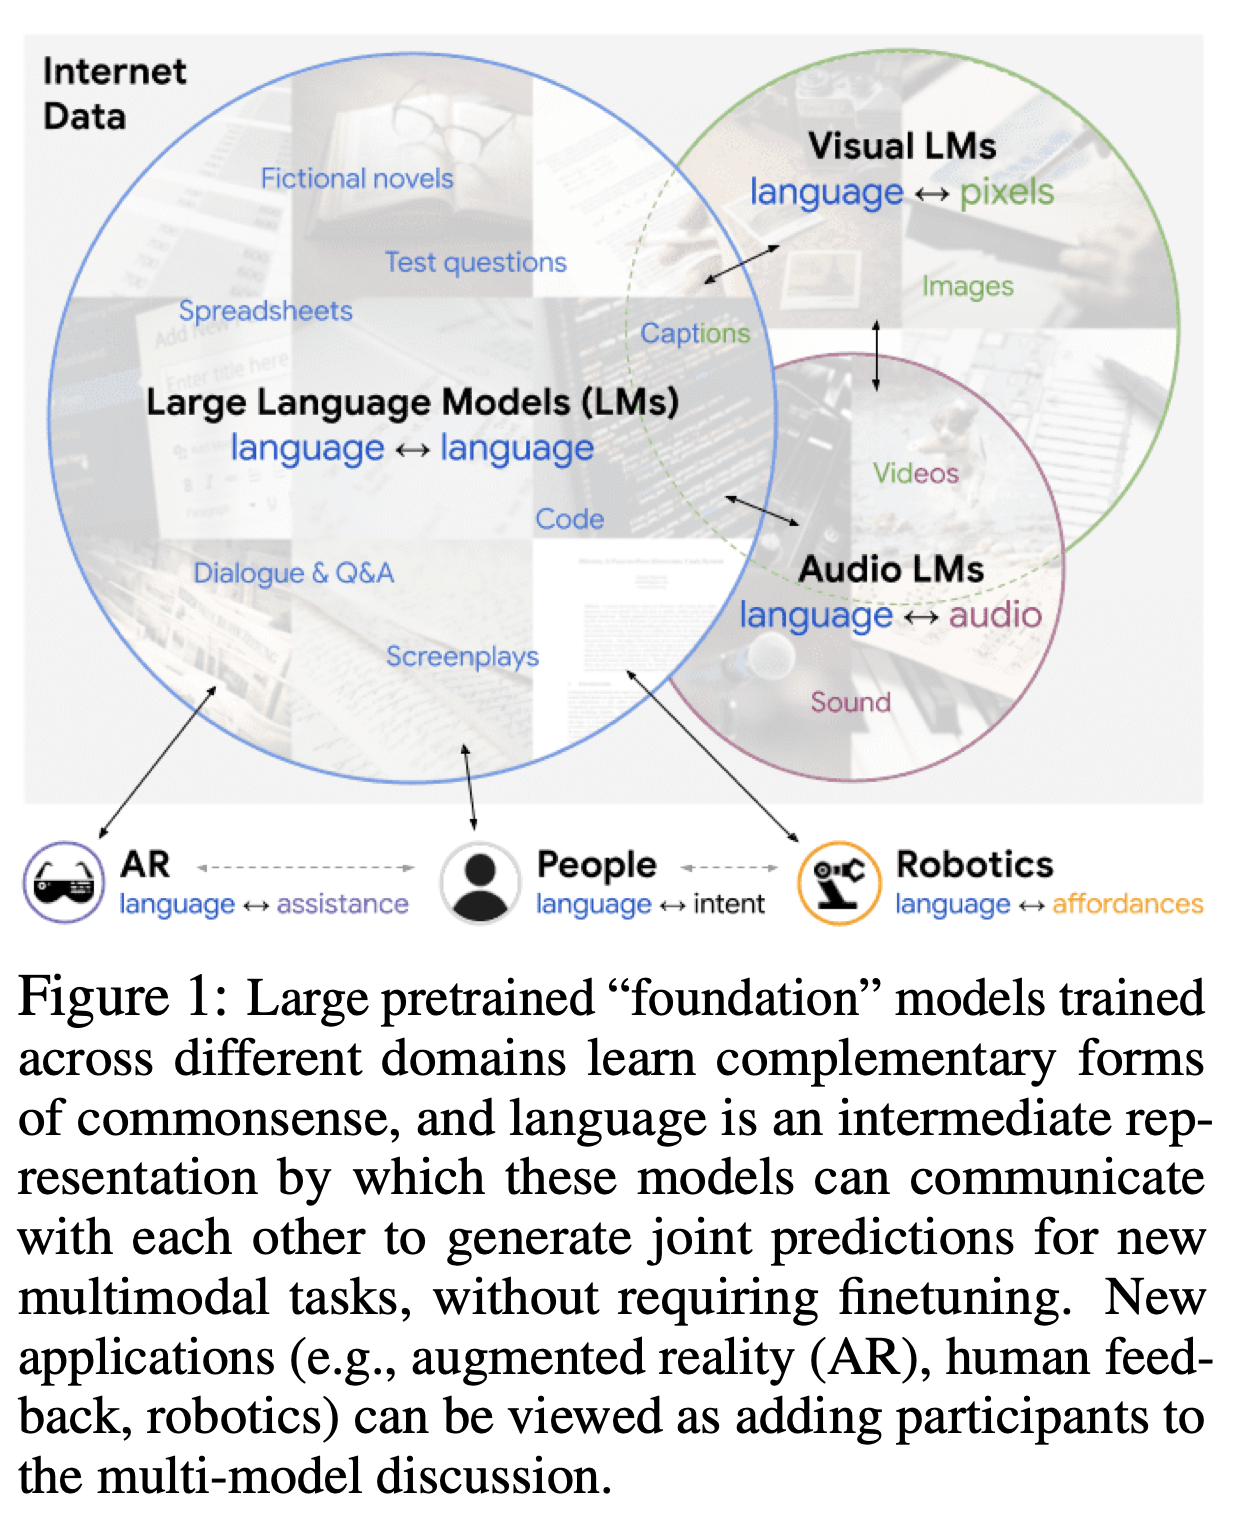
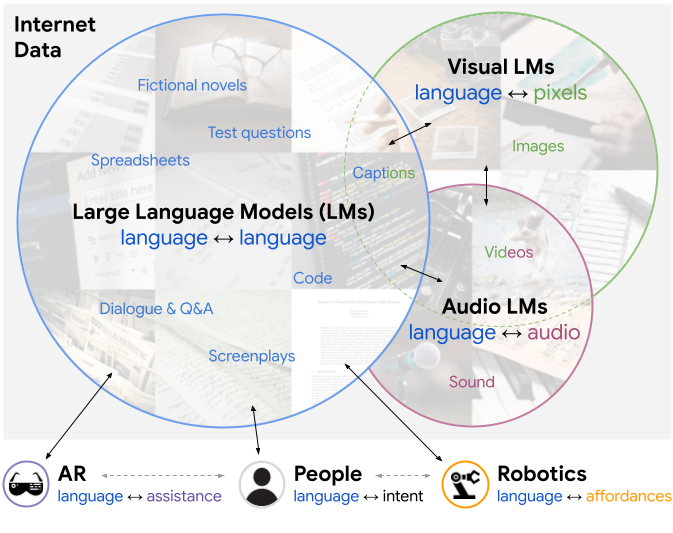
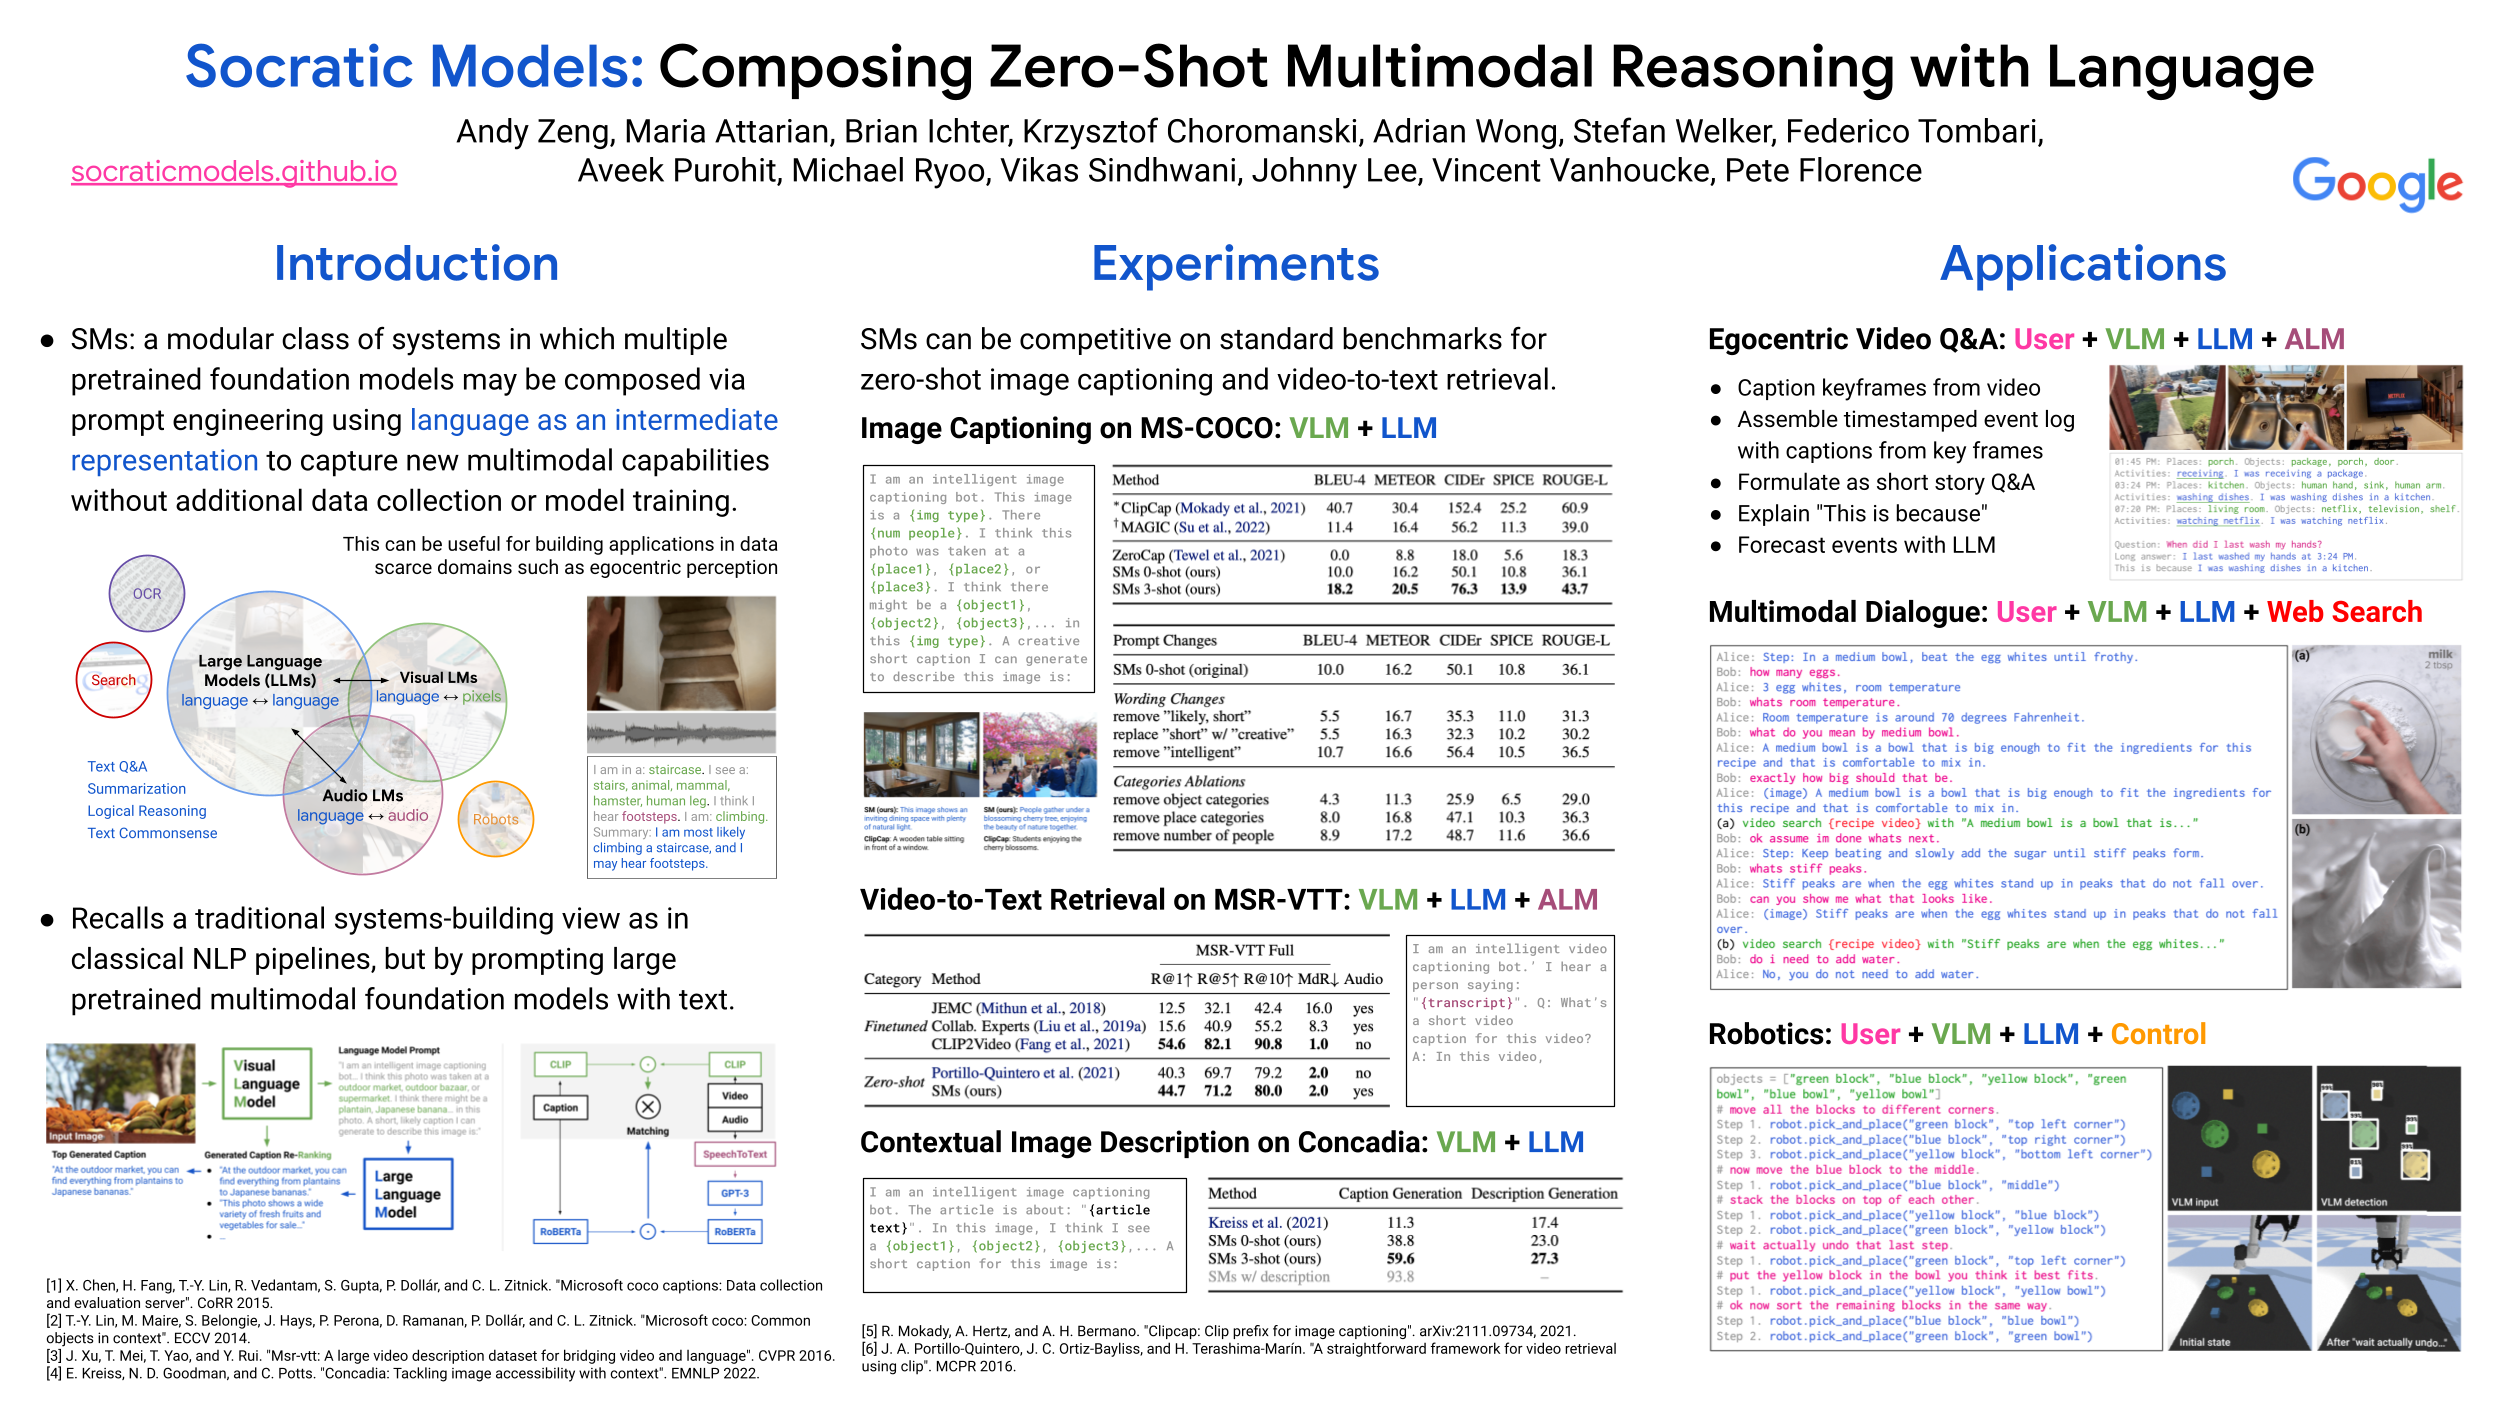
Most papers make this sound like magic. It isn't. It's just forced self-questioning pushed through a vision encoder and a language model, with a lot of careful prompt engineering holding it together. I spent about six months working with this approach on a dataset of medical imaging reports and lab result tables, and the short version is: it works well enough for structured retrieval tasks and fails unpredictably on anything requiring deep spatial reasoning. The core idea behind Socratic Models Composing Zero Shot Multimodal Reasoning With Language is that you don't train the model on new tasks. Instead, you make it interrogate itself about what it sees before producing an answer. You feed it an image, a table, or both, and the prompt chain forces the model to generate a series of questions first — what is the layout, what are the individual components, what relationships exist between them — and only then does it synthesize a final response. The "composing" part means the reasoning chains are built from reusable language-based subroutines rather than learned per-task weights.Getting Socratic Models Composing Zero Shot Multimodal Reasoning With Language to Actually Work
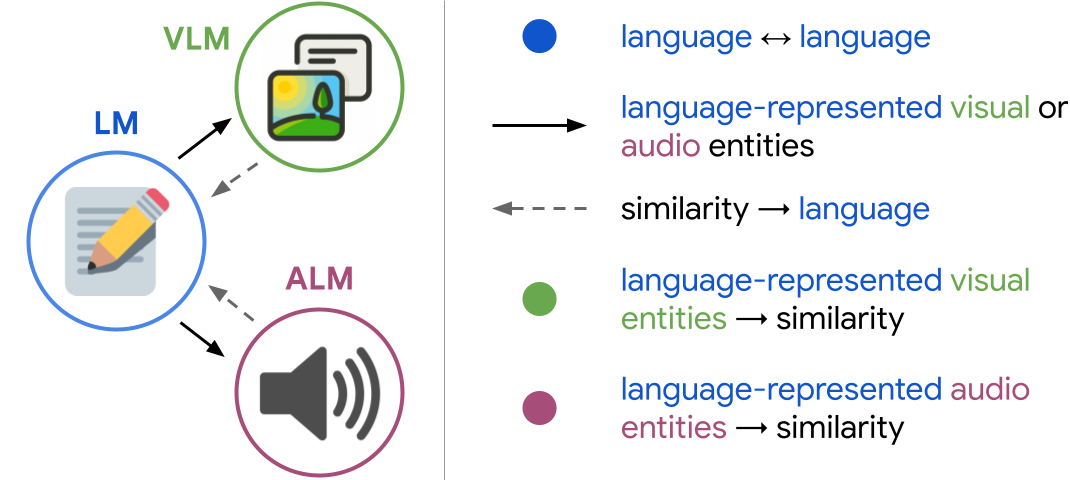
The implementation I ended up using most effectively runs on top of a base LLM like Llama 3 or Qwen 2.5, paired with a vision encoder such as CLIP or SigLIP. The pipeline itself is straightforward: you construct a multi-turn prompt where each turn asks a progressively narrower question about the input modality. The first turn might be "Describe the overall structure of this document." The second narrows to "List every labeled axis and its units." The third asks for cross-referencing: "Which data point contradicts the trend shown in section B?" Only after these intermediate generations do you collect the full chain and ask for the final answer. Here is where it gets tricky, and where most people hit dead ends. The number of Socratic turns matters significantly. Too few and the model skips over subtle visual details it otherwise could have caught. Too many and the signal degrades — the later questions start looping or contradicting earlier ones. In my testing, 3 to 5 intermediate question-generation steps was the sweet spot for document analysis and chart interpretation. Anything beyond that required explicit constraint prompts to keep the reasoning from drifting. The hardest part I ran into was handling mixed modality inputs where the image and the table contained overlapping but non-identical information. I had a case where a pathology slide image showed a certain staining pattern, and the accompanying lab table listed a related biomarker value. The model would correctly identify both separately, but consistently failed to compose the reasoning across them until I added an explicit cross-modal linkage prompt between the image question chain and the table question chain. Without that bridge, the two reasoning threads just sat parallel and never merged.
What the Research Doesn't Tell You
One counter-intuitive thing about this approach: the quality of the final output depends far more on the order of your Socratic questions than on the size of the model itself. A smaller 7B parameter model with well-ordered intermediate questions will outperform a 70B model with a flat, undirected prompt on structured multimodal tasks. The ordering creates a scaffolding effect that forces the model to attend to the right visual features before it tries to reason about them. Another thing that isn't obvious: zero shot doesn't mean no preparation. You still need to provide exemplar question chains for your specific domain. The model needs a few in-context examples of good Socratic reasoning before it produces usable intermediate steps. Three to five examples in the prompt typically gets the question quality above the threshold where the final answer becomes reliable. Fewer than that and you get vague questions that don't actually constrain the model's attention. Socratic Models Composing Zero Shot Multimodal Reasoning With Language also has a real bottleneck around token usage. Each intermediate question generates its own token sequence, and you are essentially running the model through 4 to 8 forward passes per input instead of one. On a single A100, a well-optimized pipeline processes a single chart-image pair in roughly 3 to 5 seconds end-to-end. If you are batching this at scale, the latency compound quickly and the cost per query is noticeably higher than standard zero-shot VLM inference.
When This Approach Breaks
Don't expect this to work well for open-ended visual reasoning. Tasks like "what is happening in this scene" or "describe the narrative of this image" will produce coherent-sounding but fundamentally wrong answers because the Socratic framing assumes there is a decomposable, fact-based question structure to follow. Natural scenes don't have that structure. The method shines on documents, charts, diagrams, tables, and technical images where the information is organized and retrievable. For spatial or geometric reasoning — things like "is this shape symmetrical" or "which object is behind the other" — the language-composed approach introduces too much abstraction. The model translates visual spatial relationships into textual descriptions first, and that translation layer loses precision. Direct visual methods or models fine-tuned on spatial tasks will outperform Socratic prompting here by a wide margin. If you are looking at open-source implementations, the closest community projects I found useful were forks around the MedFlamingo and LLaVA-SFT codebases with added Socratic prompt templates. There isn't one canonical reference implementation yet. The paper that popularized this direction had supplementary code that required several unlisted dependencies and didn't run clean on a fresh install. I ended up reconstructing the pipeline from the methodology sections and documentation scattered across a few related arXiv papers rather than relying on any single released repo.
Get the Full Details

The practical takeaway is that the method is genuinely useful for specific structured tasks but requires careful prompt design, domain-specific examples, and an awareness of where the cross-modal composition step is likely to fail. It is not a drop-in replacement for fine-tuning when you have task-specific data, but it is a real alternative when you don't.