The Two Tools Nobody Tells You Are Different Until Your Pipeline Breaks
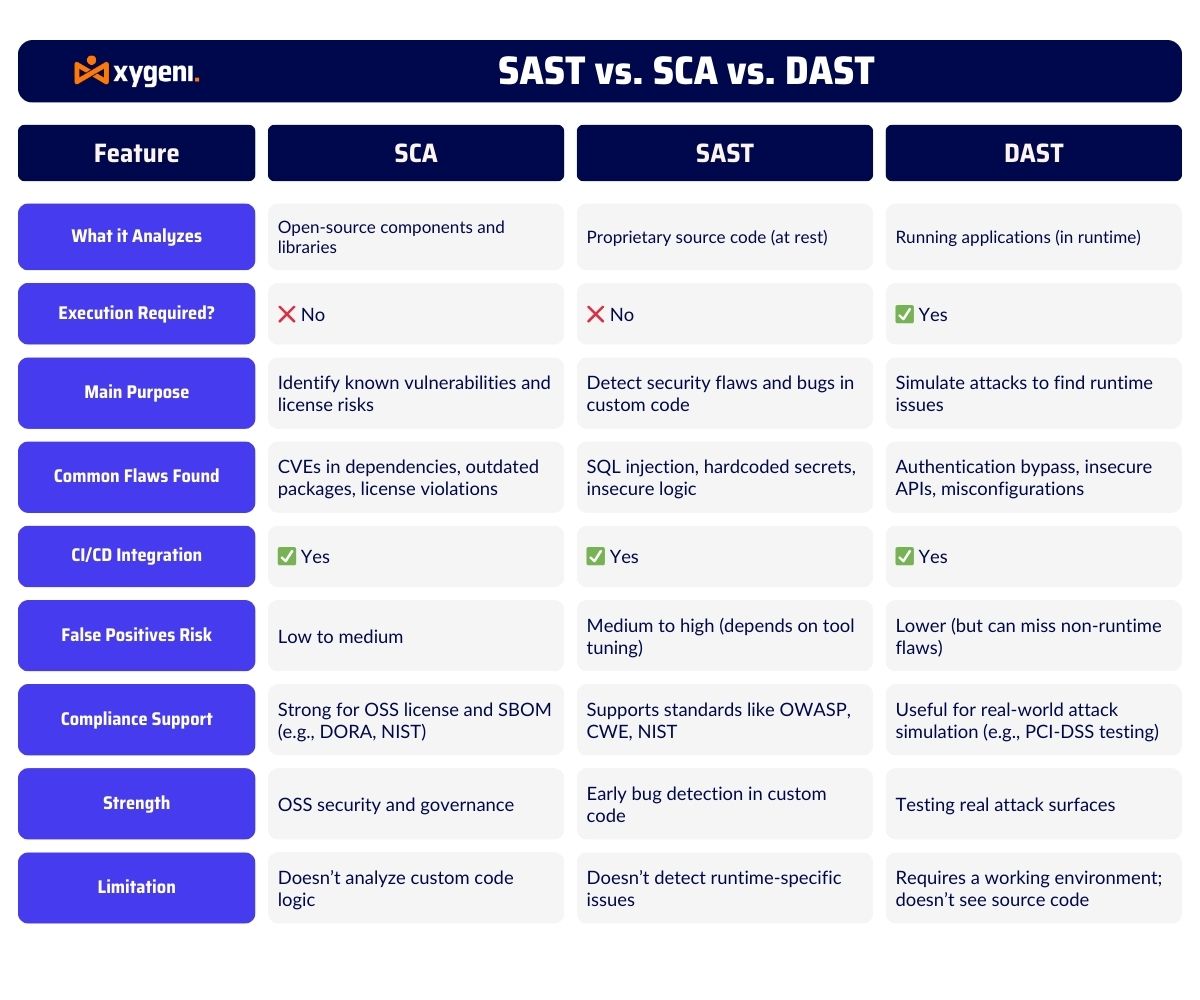
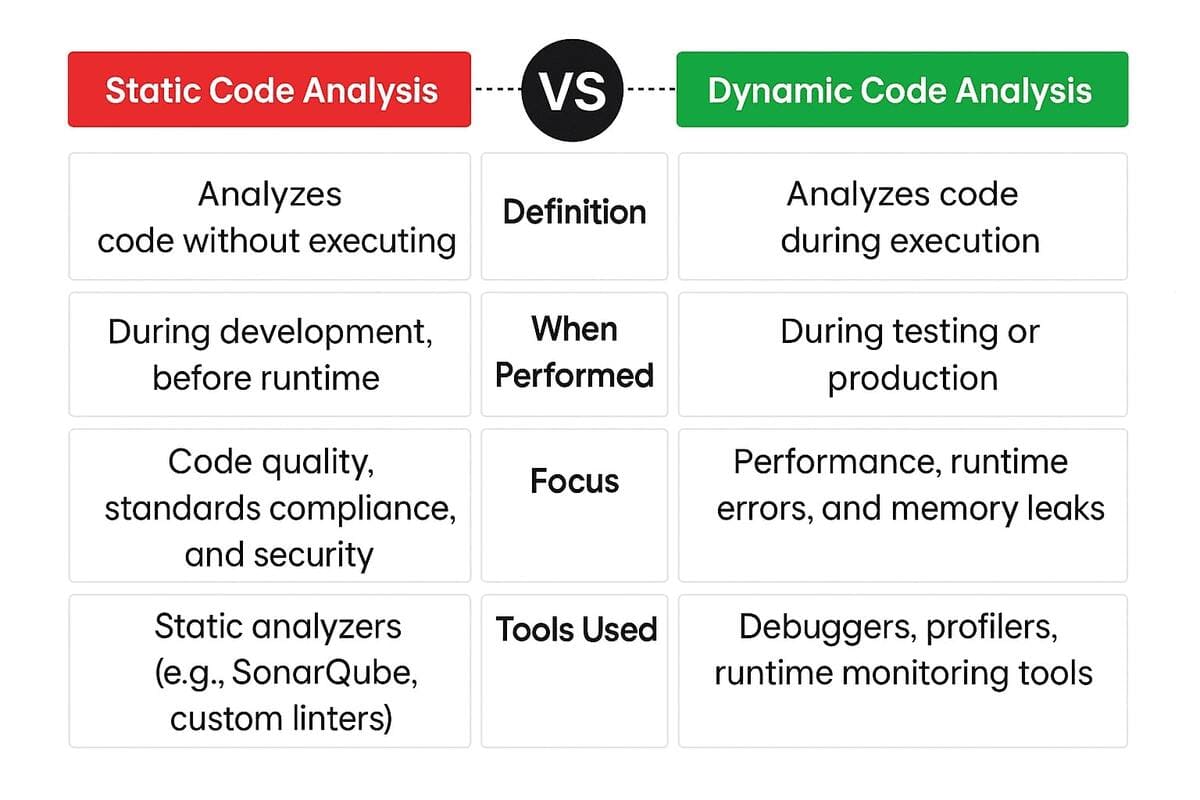
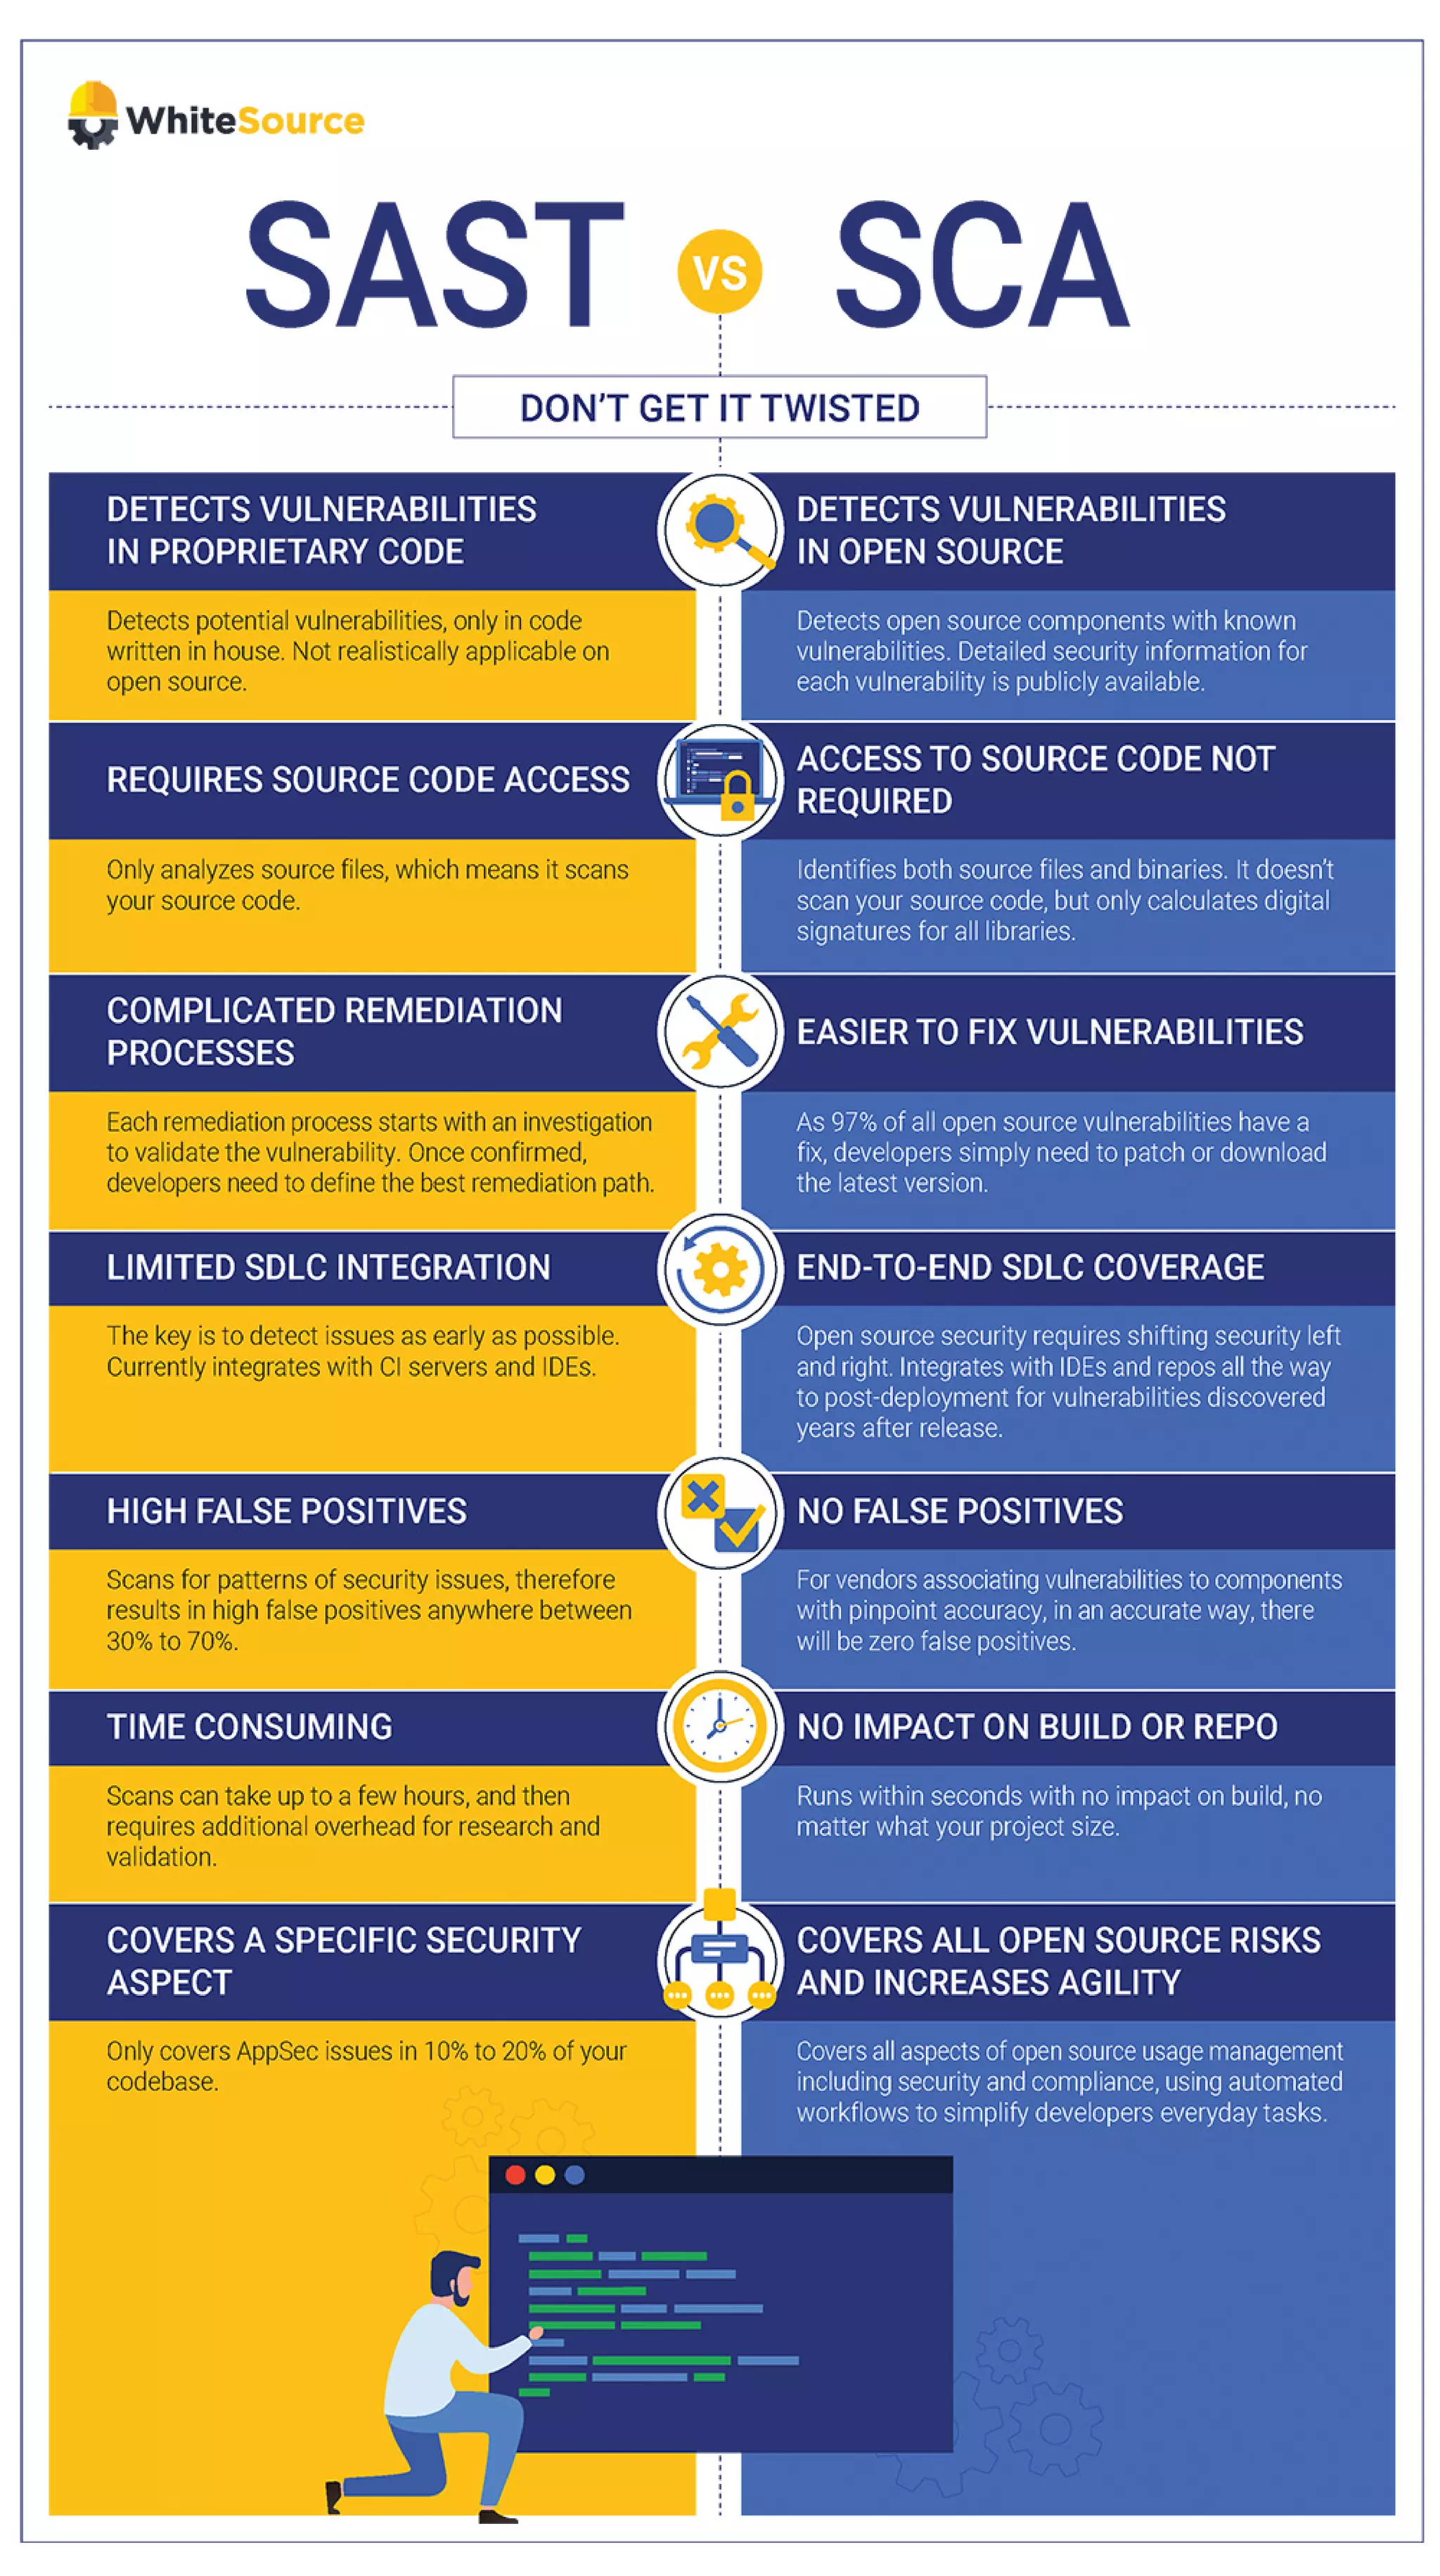
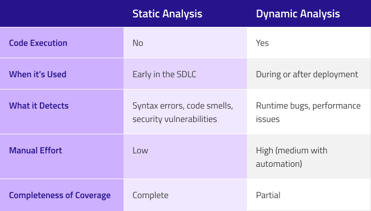
I spent three years watching developers confuse SCA with SAST until a production outage forced me to write down exactly what each tool actually does. The confusion isn't theoretical. It shows up as false confidence, missed vulnerabilities, and teams picking the wrong tool for the problem at hand. Static Code Analysis is what it sounds like. You point a scanner at your source code, the tool parses the syntax tree, and it looks for patterns that match known vulnerability signatures in your own written code. It catches things like unvalidated input, hardcoded credentials, buffer overflows, and incorrect error handling. The tool reads your code the way a compiler would — it doesn't execute it, but it understands the structure well enough to trace data flow across functions. Software Composition Analysis works differently. Instead of scanning your code, it scans your dependency graph. You pull packages from npm, PyPI, Maven, or whatever registry your project uses, and SCA maps every single transitive dependency back to its original open source component. Then it cross-references those components against databases like the National Vulnerability Database, GitHub Advisory Database, and various vendor security bulletins. If lodash has a prototype pollution issue, SCA tells you your project is affected regardless of whether you directly imported lodash or pulled it in through a transitive dependency three levels deep.
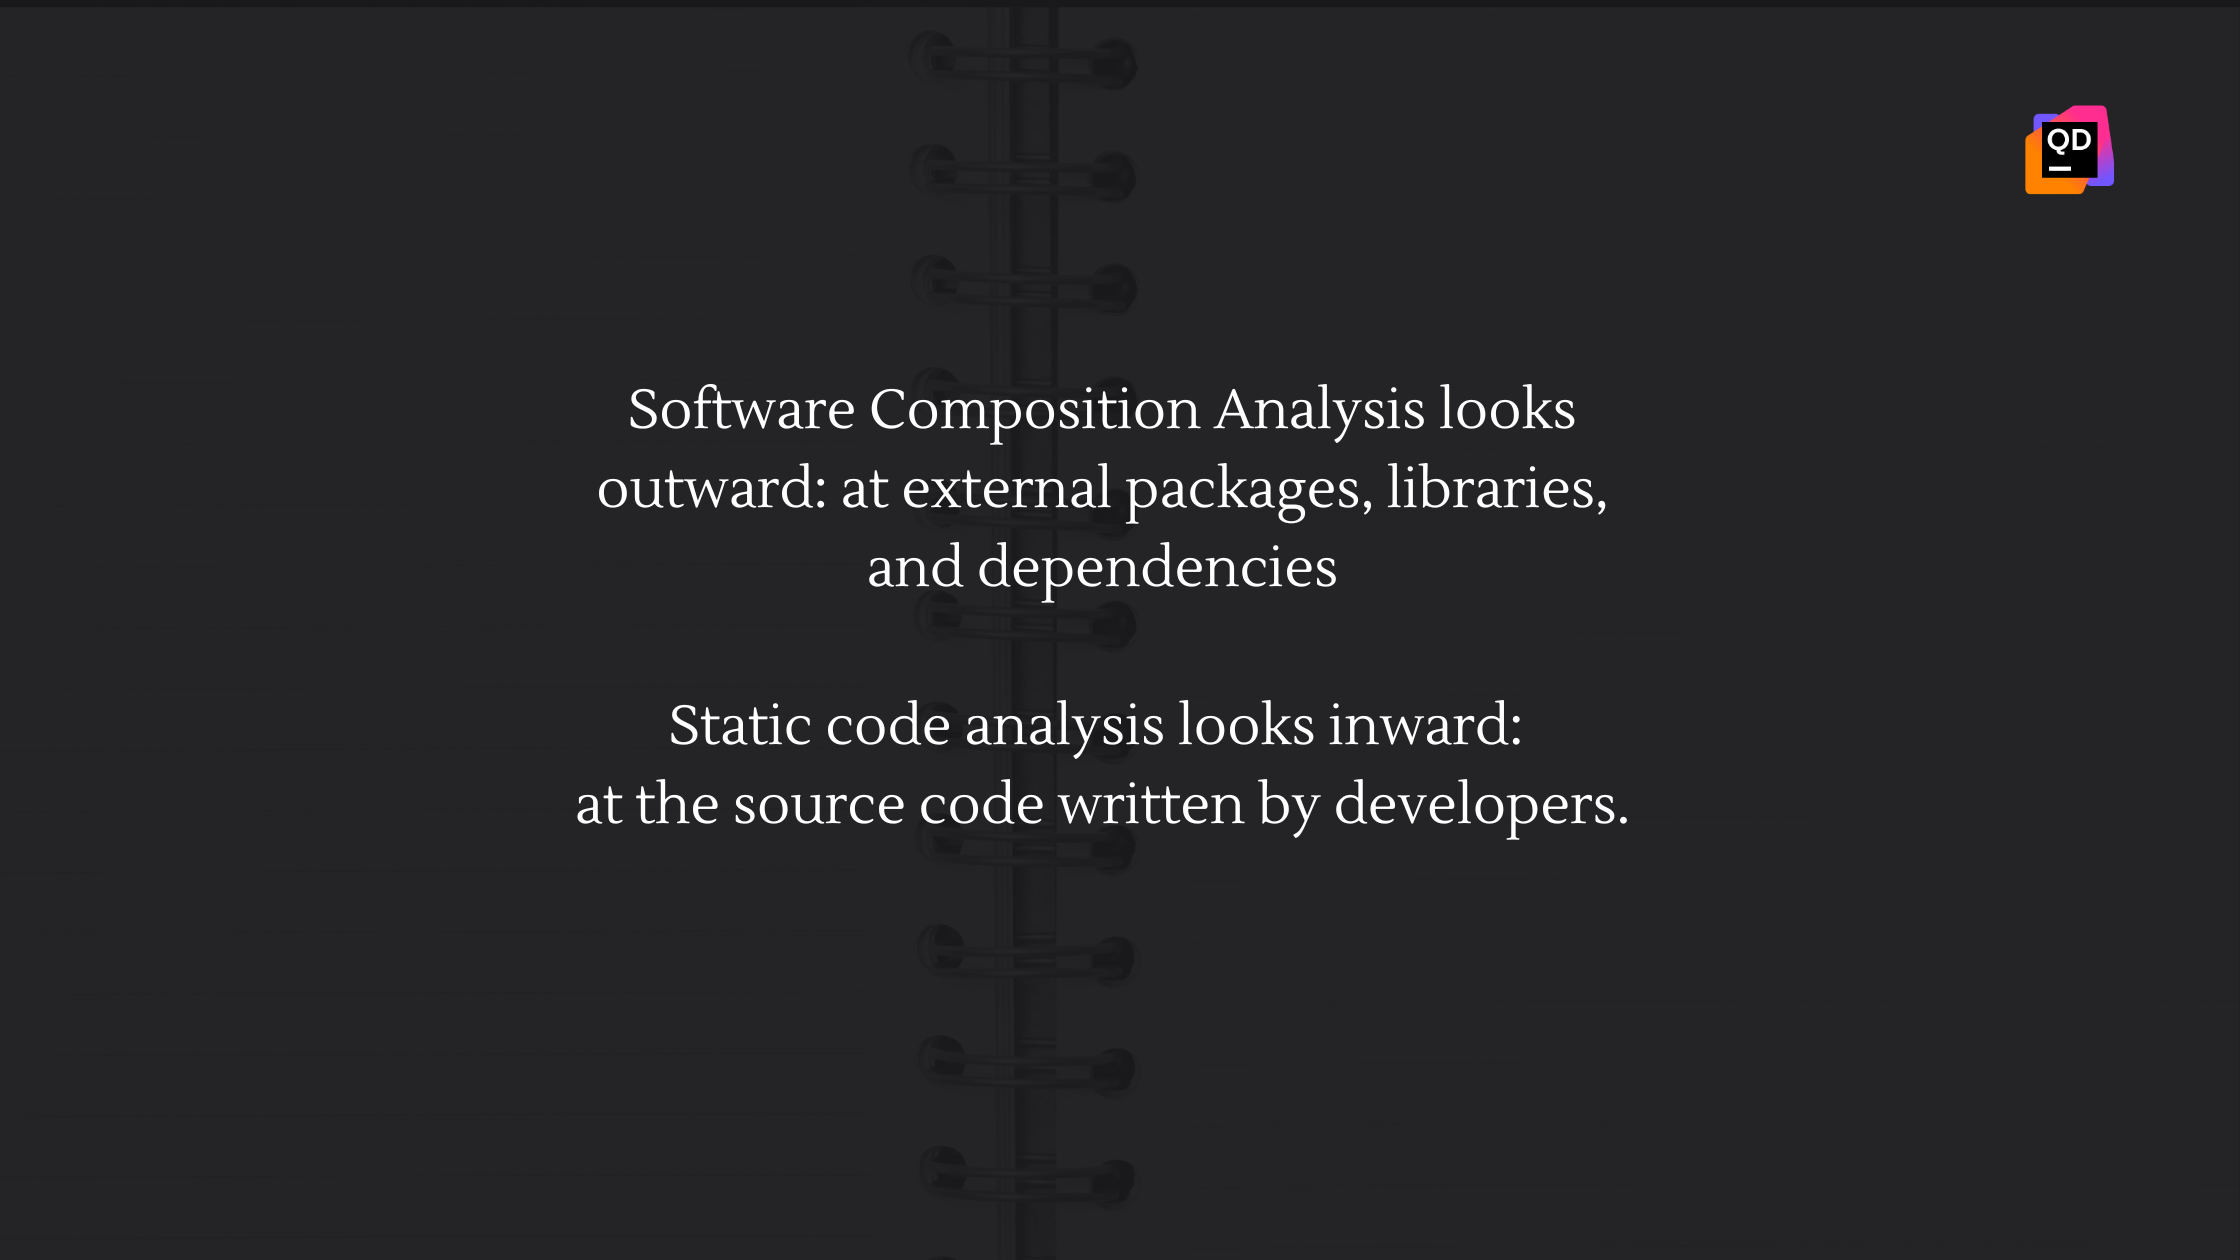
The core difference comes down to scope. SCA looks outward at what you brought in. Static analysis looks inward at what you wrote. They answer completely different questions, which is why running just one creates blind spots. I learned this the hard way in 2022. Our team relied heavily on SAST and we felt secure. Then we discovered a vulnerable version of log4j sitting in a nested dependency that nobody had directly referenced. Our static analyzer never looked for it because the vulnerable code wasn't in our repository. It was in the compiled artifact we'd pulled from a Maven repo. SCA caught it immediately once we actually ran it, but by then the exposure window had been weeks long. That incident changed how I think about these tools entirely.
How Static Code Analysis Actually Works Under the Hood
Modern SAST tools build abstract syntax trees from your source files. They apply taint analysis to track how data moves from entry points like HTTP parameters through your application logic to sensitive operations like database queries or system commands. The tool marks where untrusted input enters the system, follows it through variable assignments and function calls, and flags any path where tainted data reaches a sink without proper sanitization. There are different analysis strategies you'll encounter. Rule-based scanning uses predefined patterns from CWE lists and MITRE attacks. Every finding maps to a specific weakness category with a confidence score. Flow-sensitive analysis goes deeper by understanding control flow and data dependencies across the entire codebase. This approach reduces false positives but takes significantly longer to complete. For a medium-sized Java project, flow-sensitive analysis might run for forty-five minutes to two hours depending on complexity. Rule-based scanning finishes in under ten minutes but misses context-dependent issues. Precision matters more than recall in most enterprise settings. I've seen teams treat every SAST finding as a critical bug and burn developer time chasing false alarms. The smarter approach is configuring your tool to suppress low-confidence findings in boilerplate code, test files, and generated sources. A typical tuning pass takes about three days of rule configuration and yields a twenty to forty percent reduction in noise without missing real vulnerabilities.
Get the Full Details
One thing beginners consistently miss is that SAST cannot verify whether a third-party library function actually exists or behaves the way the documentation claims. It analyzes the call site, not the implementation. If you're calling a method on a dependency and that method has a buffer overflow vulnerability, SAST sees the call but doesn't know the underlying risk. That's the SCA gap.
How Software Composition Analysis Actually Works Under the Hood
SCA tools generate a bill of materials from your project's lock files or dependency manifests. They parse package.json, requirements.txt, pom.xml, Cargo.toml, and similar files to extract every component with its exact version number. The resulting SBOM becomes the input for vulnerability matching against curated advisory databases. The real complexity comes from transitive dependencies. A direct dependency might declare another package as optional, and that optional package might pull in five more levels of nested dependencies. Modern SCA tools handle this recursively, but the accuracy depends on how well they resolve the dependency tree in your specific environment. Projects with custom build scripts or monorepo structures sometimes produce incomplete SBOMs unless you configure the tool properly. Version resolution is where SCA gets tricky. If your pom.xml declares spring-boot-starter-web version 2.7.3 and that artifact transitively depends on Jackson 2.13.4, the SCA tool needs to know that exact transitive version to match it against vulnerability databases. Most tools do this correctly now, but older or poorly configured scanners sometimes match against the direct dependency version instead of the resolved runtime version. This mismatch can either miss real vulnerabilities or flag ones that don't actually affect your deployment.
I encountered a specific edge case that still frustrates me. We had a Go project using go.mod with replace directives that pointed local module paths instead of remote versions. The SCA tool parsed go.mod correctly but couldn't resolve the local replace targets to their actual version numbers. The result was a completely empty vulnerability report. The workaround was exporting the dependency tree with go list -m all after running go mod download, then feeding that output into the SCA tool's import feature. This added about five minutes to the pipeline but produced an accurate report.
When to Use Each Tool and Why Both Matter
Static analysis is essential when you're writing new code or modifying existing logic. It catches insecure coding patterns before they ship. The typical scan time for a modern codebase ranges from fifteen minutes for small projects to three hours for large monoliths with multiple language files. CI pipeline integration usually adds four to eight minutes per build depending on your tooling choice. Software composition analysis is essential whenever your project includes external dependencies, which is basically every project except the smallest hobby scripts. Dependency vulnerabilities represent a larger share of real-world breaches than custom code vulnerabilities. The OWASP Top Ten lists broken access control and injection flaws consistently, but industry breach data shows supply chain compromises accounting for a significant percentage of incidents. The recent MOVEit transfer vulnerability affected thousands of organizations through a single commercial dependency with zero custom code changes required. Running both tools together gives you coverage across the full attack surface. SCA catches what you didn't write but inherited. Static analysis catches what you wrote and potentially made insecure. Gaps appear when you rely on only one approach because each tool's blind spot is the other's strength.
Here's a practical limitation most teams don't anticipate. SCA vulnerability databases have a lag between the day a CVE is published and the day your SCA tool flags it in your dependencies. That window varies from hours for popular open source packages to days or weeks for niche components. During that gap, your CI pipeline reports clean even though a known vulnerability exists in your stack. This is why some teams supplement automated scanning with manual dependency reviews for critical infrastructure components.
Common Mistakes That Waste Time and Money
The biggest mistake I see is treating SAST findings as equal priority. A critical severity XSS vulnerability in a utility function deserves immediate attention. A low severity information disclosure in a logging library that runs inside a container with no network access deserves a quarterly review at most. Teams that triage everything as critical end up with alert fatigue and miss the actual high-risk findings hiding in the noise. Another mistake is running SCA scans only on direct dependencies. If your tool doesn't recursively resolve the full transitive dependency tree, you're missing vulnerabilities in packages you don't even know you're using. Check your SCA tool's documentation to confirm it generates a complete SBOM including indirect dependencies. Most commercial tools do this by default, but free or open source scanners sometimes require explicit configuration flags. False negatives are the silent killer. Both tools produce them. SAST tools miss vulnerabilities in dynamically typed languages or runtime-generated code. SCA tools miss vulnerabilities in custom built dependencies that don't appear in public advisory databases. The mitigation strategy is simple: understand what your tools cannot see and supplement with manual code review for critical paths and penetration testing for production-like environments.
I also recommend against running SCA and SAST scans sequentially in the same CI job without parallel execution. The combined scan time for a medium project can easily exceed twenty minutes, and sequential execution adds that time linearly. Running both jobs in parallel through your CI platform's matrix feature cuts total pipeline time roughly in half while preserving full coverage.
Practical Setup Recommendations
For static analysis, Semgrep is a solid free option that supports Python, JavaScript, Java, Go, and several other languages. It runs in about three minutes on a typical project and integrates cleanly into GitHub Actions or GitLab CI. For enterprises needing deeper flow-sensitive analysis, tools like Checkmarx or Fortify provide more thorough scanning at higher cost and longer scan times, typically fifteen to forty-five minutes per language. For software composition analysis, Snyk is widely used and offers a free tier that covers small projects. It scans in about two to five minutes depending on dependency count. For organizations needing SBOM generation and licensing compliance in addition to vulnerability scanning, tools like Black Duck or Dependabot provide broader coverage. Dependabot is free with GitHub and runs automatically on every pull request, though its vulnerability detection depth is shallower than dedicated SCA tools. A practical pipeline configuration I've used successfully runs SCA first because it completes faster and identifies blocking issues early. Then SAST runs in parallel with SCA to save time. If either tool reports critical vulnerabilities in production-bound code, the pipeline fails immediately. Blocking only critical and high findings rather than all severity levels prevents pipeline fatigue from low-risk issues that don't warrant urgent action.
Both tools improve over time through feedback loops. When your security team reviews a finding and marks it as a false positive, feeding that feedback back into the tool's configuration reduces repeated noise. I've seen teams reduce SAST false positive rates by thirty to fifty percent over six months through disciplined tuning. SCA false positives are less common but still occur when advisory databases contain outdated version mappings or when your project uses patched versions that haven't been propagated to the database yet. The bottom line is straightforward. SCA and static analysis address different vulnerability categories. Using both covers more of your attack surface than using either alone. The tools have limitations and will occasionally miss real issues or flag benign ones, but configured properly and run consistently, they catch the vast majority of known vulnerability vectors before code reaches production.