Why most competency matrices end up collecting digital dust
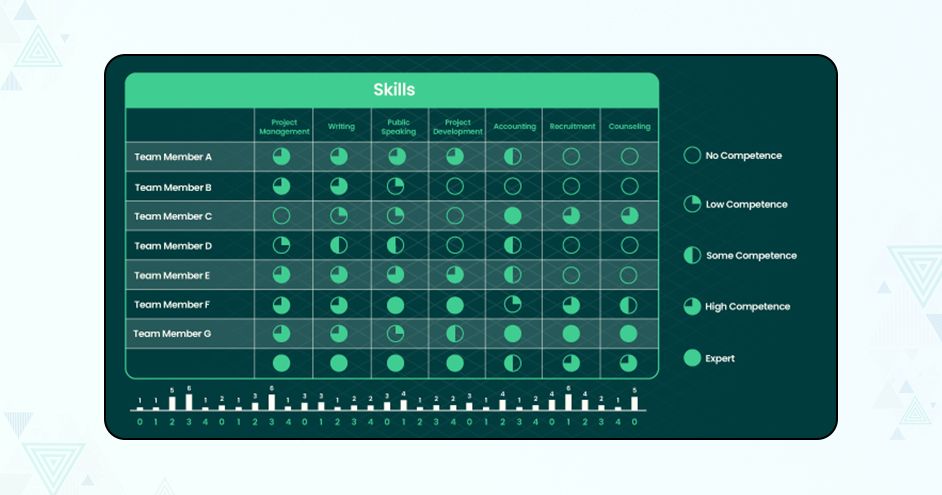
I built three different Software Engineering Competency Matrix frameworks across two companies and watched them all fail in similar ways. The first one was a simple Excel spreadsheet with levels from Junior to Principal. People filled it out once a year, nobody read it, and then we tried to use it for promotion decisions and everyone got angry. The second was a proper tool with self-assessment, manager assessment, and calibration rounds. Still failed, but for a different reason — the language was so vague that two senior engineers could rate themselves at completely different levels on the same criterion. The third one actually stuck. Not because it was perfect, but because we stopped trying to measure everything and started measuring only the things that created actual friction in daily work.
Building a Software Engineering Competency Matrix that people actually use
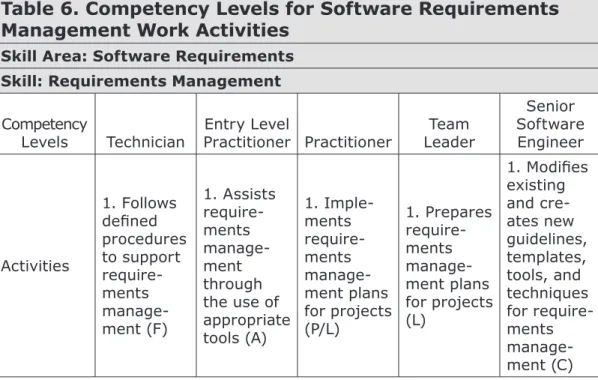
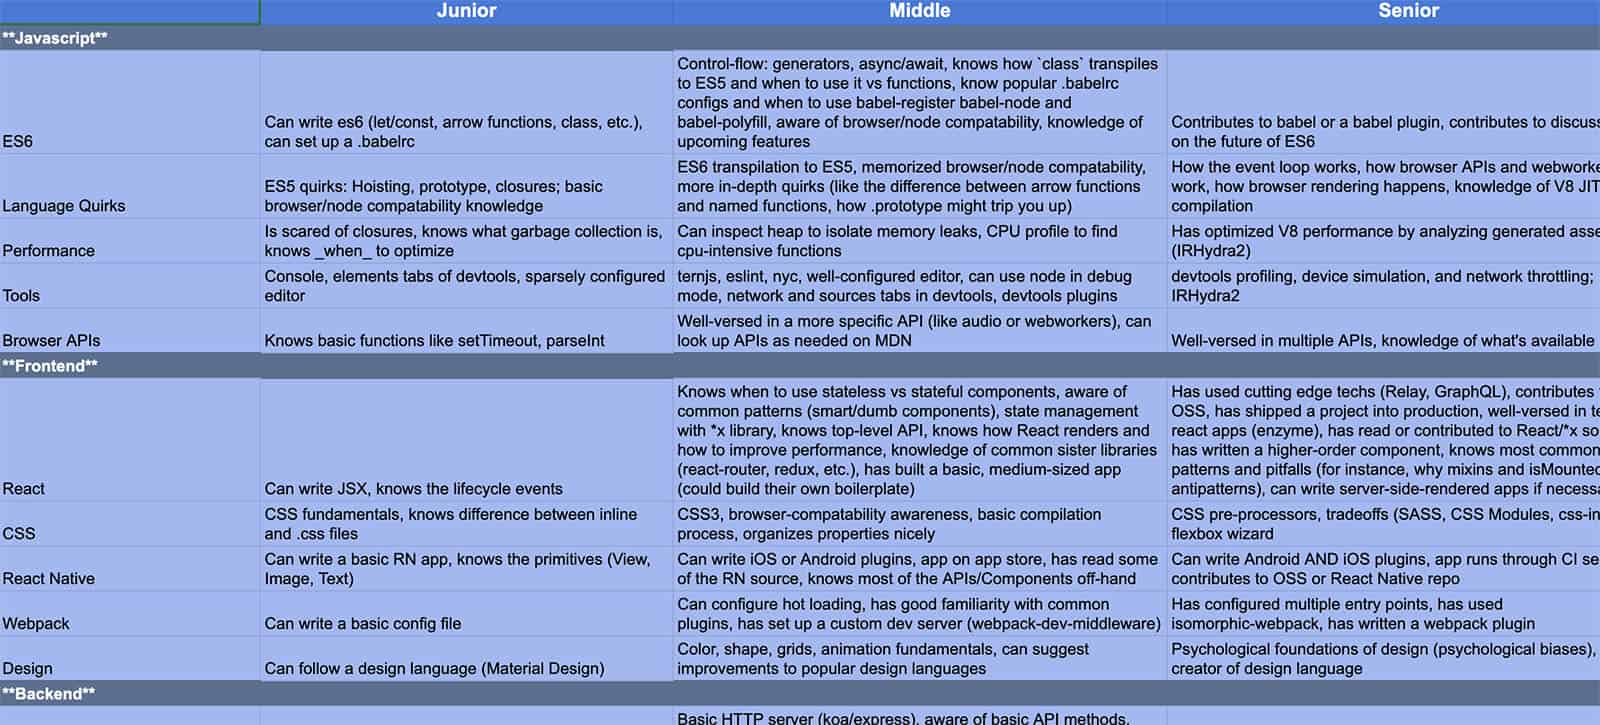
Start by mapping out the roles you have. Not idealized roles from a textbook. The roles you actually pay for. If your company has Staff engineers who do completely different work than your Senior engineers, that's two separate tracks. Don't merge them into one ladder because it's easier to administer. It's not easier, it's just less accurate. I learned this the hard way when we had a track where Staff and Senior were lumped together. A principal-level engineer named Derek applied for an internal transfer to a team that needed a Staff engineer. He checked the competency box on "technical leadership" and marked himself competent. The hiring manager looked at his code reviews and realized Derek's idea of technical leadership was writing a design doc and then disappearing for three weeks. Derek was technically senior for the time he spent coding, but completely junior for the time he spent influencing. The merged track couldn't see that distinction. We rebuilt the matrix with separate behavioral anchors for individual contribution versus team leadership, and suddenly the promotion process stopped producing arguments. Write behavioral anchors, not adjectives. "Good communicator" means nothing. "Writes design docs that get reviewed by at least two engineers before implementation begins" means something. Every level of every competency needs concrete, observable behaviors. If you can't describe what someone actually does differently at level 3 versus level 4, you don't have a competency — you have a feeling.
Here's the part most people skip: timebox the calibration session. I've seen these processes drag on for six weeks because managers kept arguing over whether someone was a "strong three" or a "solid four." Set a hard limit. Thirty minutes per person. If you can't decide after thirty minutes, the calibration criteria aren't written well enough. Go back to the drawing board, not the argument. The matrix should have five competencies at most for the initial rollout. Five. I see teams build matrices with twelve or fifteen competencies and then wonder why engineers spend four hours filling them out instead of working. Pick the competencies that actually matter for the decisions you're making. If you're using this for promotions, you need engineering depth, shipping velocity, and cross-team influence. You don't need a separate competency for "good attitude" because that's not a professional skill you can measure. That's a management judgment call. Weight matters more than breadth. I'd rather see a matrix with five weighted competencies where each one has a clear percentage of the total evaluation than a long list of equally weighted items. A well-written matrix should take the average engineer about twenty minutes to complete if they understand their own work. If it takes an hour, you've added complexity without adding clarity.
Get the Full Details
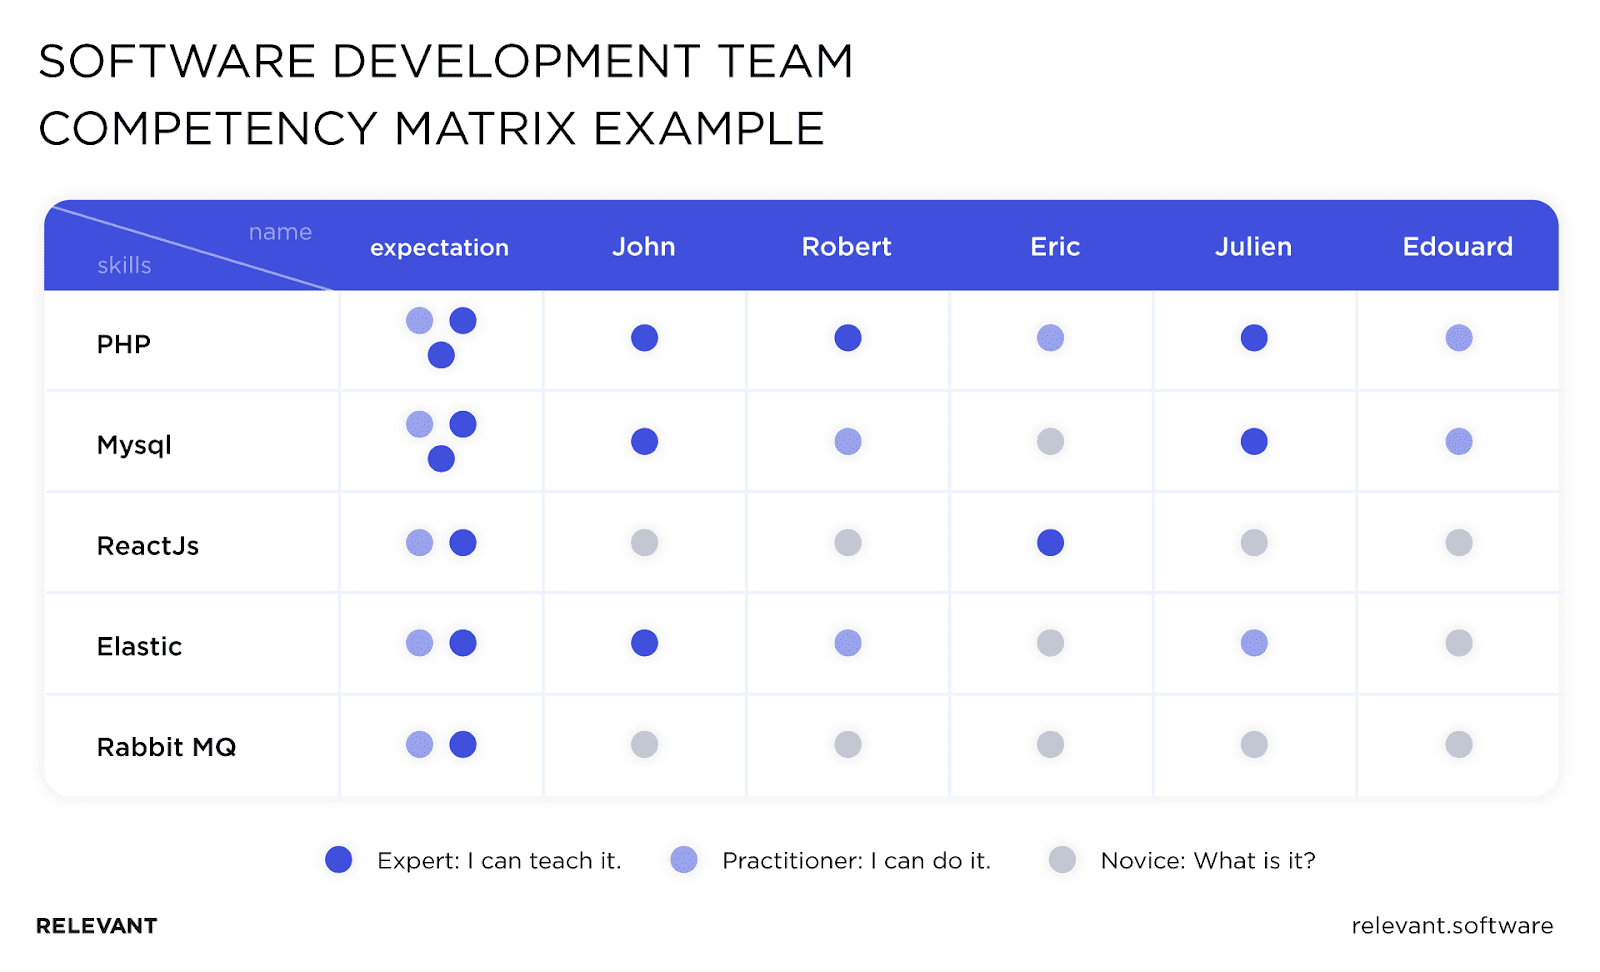
The biggest failure mode I encountered involved calibration bias. During our second annual review cycle, three managers on the data platform team rated everyone at level 3 or above across all competencies. Meanwhile, the infrastructure team had people rating at level 2 and below. When we compared the two teams, the data platform engineers weren't actually better. Their managers just had a habit of inflating ratings. We solved this by requiring all calibration sessions to include at least one manager from a different org group who had no direct knowledge of the person being reviewed. That person would ask uncomfortable questions like "show me an example of this person demonstrating this competency" and suddenly the inflation disappeared. It felt awkward for everyone, but it worked. Another thing nobody talks about: the recency effect. Engineers tend to get rated based on what they did in the last quarter, not what they consistently do. A person who shipped a big project three months ago gets rated higher than someone who has been quietly keeping the platform stable for eighteen months. I started including a requirement that every competency rating must reference at least one example from the current quarter AND one from the prior quarter. This forced managers to actually think about sustained behavior rather than recent events. It took more effort upfront but produced more defensible outcomes. The one scenario where this approach breaks down completely is with new hires or people in transition. If someone joined three months ago, they haven't had the opportunity to demonstrate many competencies yet. Forcing a rating produces noise, not signal. The workaround is simple: create a separate track for people under six months tenure where the matrix only captures demonstrated competencies and leaves the rest blank with a note. Review again at the six-month mark. It's not ideal, but it's honest about what the data actually says.
If your organization is smaller than about fifty engineers, I'd recommend skipping the formal matrix entirely and using a lighter version. The overhead of maintaining behavioral anchors, running calibration sessions, and documenting everything usually exceeds the benefit at small scale. A simple conversation between a manager and an engineer with a shared document of growth areas does the job. The matrix pays for itself only when you have enough people and enough ambiguity that the manual approach starts producing inconsistent results across teams.