Orion NPM: A practical walkthrough
The Solarwinds Orion Network Performance Monitor is one of those tools that most IT teams either love or tolerate. It does its job well enough, but the setup process has quirks that trip people up regularly. I have been running Orion for about eight years across several environments, and even now I find myself checking documentation for things that should be intuitive. That is just how it is. Before you download anything, understand that Orion is not a single application. It is a platform with multiple modules. Network Performance Monitor (NPM) is just one of them. The installer pulls down the core engine, SQL database requirements, and the web console. If you are installing this in a production environment, plan for at least 4-6 hours for initial setup on a mid-sized network. Smaller shops under 50 nodes will be faster, but larger deployments with custom polling intervals and alerting can take an entire day. The download comes from the SolarWinds portal. You need a valid trial or license key to activate it. The free 30-day trial gives you full functionality, which is useful if you want to evaluate before committing. Just be aware that the installer requires Microsoft .NET Framework 4.8 and a supported version of Microsoft SQL Server. SQL Express works for small deployments, but once you exceed a few hundred nodes, you will want a full SQL Server instance. This is a common bottleneck that people overlook during planning.
How the polling architecture actually works
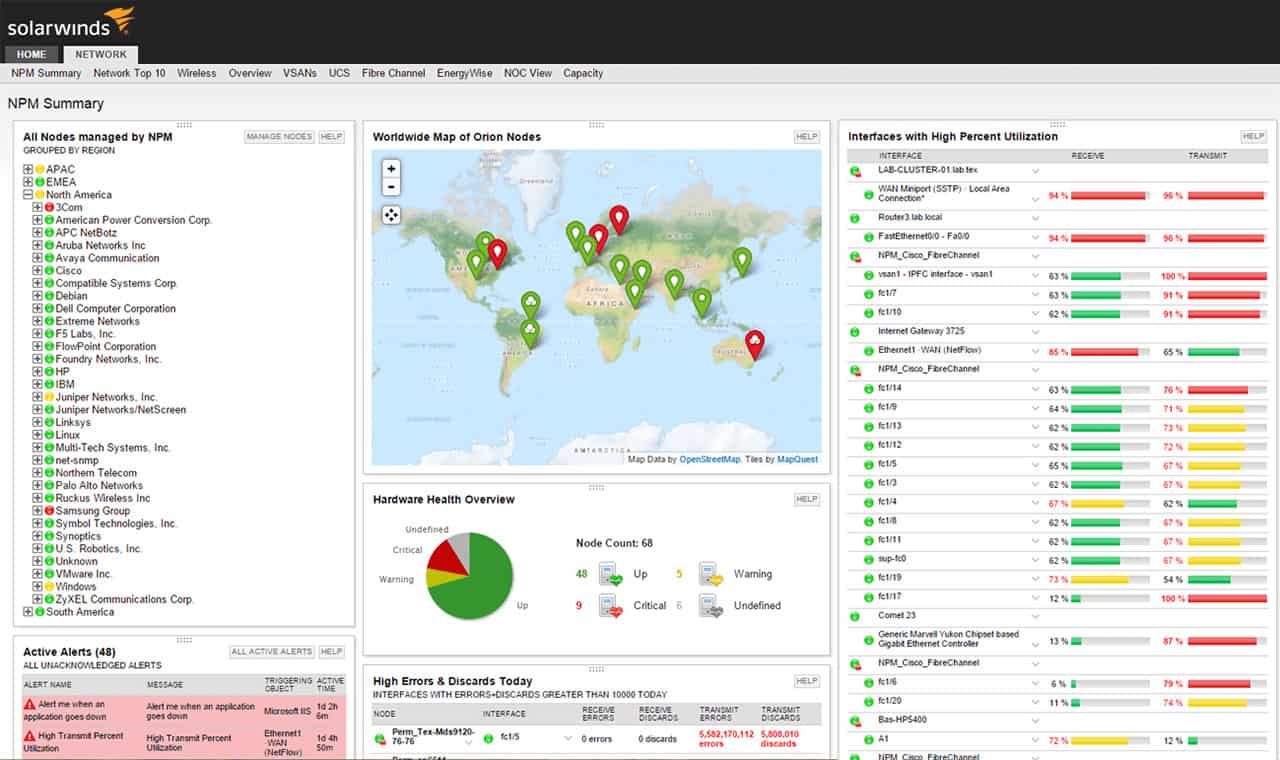
Orion does not pull data in real time. It uses a polled architecture with configurable intervals. By default, NPM polls SNMP every 60 seconds for bandwidth and interface statistics, and ICMP every 60 seconds for availability. You can change these intervals per node or globally, but there is a catch. Shorter intervals multiply quickly. Dropping your poll interval from 60 seconds to 15 seconds quadruples the database write load. Your SQL Server will thank you if you keep intervals reasonable. The primary polling engine communicates with child polling engines if you distribute the load. Each child engine can handle roughly 2,000 to 3,000 nodes depending on your configuration and hardware specs. If you are managing 5,000 nodes, do not put them all on a single engine. Split them across at least two children. I learned this the hard way when my original engine started timing out during peak polling windows. The web console would show purple dots everywhere, and the database log grew to over 50 gigabytes in a single night because of transaction backup bloat.
Installation steps that actually matter
Run the installer on a server that meets the published minimum specs. Those minimums are generous, meaning a server with barely enough resources will install fine but perform poorly once you add components. Aim for at least 16 GB of RAM and a dedicated SSD for the SQL database files. Network throughput during installation is modest, but the database operations during initial cataloging can spike CPU if you scan a large subnet range at once. During the setup wizard, you will be asked to configure the database connection string, the admin password, and whether to enable HTTPS. Generate a self-signed certificate if you do not have an internal PKI ready, but do this properly. I have seen too many environments where the self-signed cert expired after six months and then nobody could access the console because they never bothered to rotate it. Set a calendar reminder before installation finishes. After the core components are installed, you add nodes. The most efficient method is batch discovery using a IP range or AD integration. Manual node addition works for critical infrastructure items, but if you are adding more than twenty devices one by one, you are wasting time. The discovery wizard can find entire subnets, import SNMP community strings, and assign node templates in one pass. Use it.
Get the Full Details

A real problem I ran into and how I fixed it
One specific issue that cost me half a day involved interface name mapping after an OS patch on a cluster of HP ProCurve switches. Orion had been polling by interface index correctly for two years, then after a firmware update on those switches, the interface names started resolving to generic labels like "Ethernet1/1" instead of the human-readable descriptions that had been populated before. The data was still polling, but the dashboards became useless for quick identification. The workaround was to clear the ARP and cDP/LLDP cache in Orion, then force a resync. Specifically, I went into the Nodes list, selected all affected devices, ran a Discover Network Page, and then manually triggered a refresh on the Interface Map settings. This took about twelve minutes across forty switches. SolarWinds does not document this exact sequence well. The interface descriptions come from LLDP and cDP tables, and when the switch firmware changed how it reports those tables, Orion cached stale data until you forced the refresh. There is also a PowerShell cmdlet called Sync-SwisEntity that can help in scripted environments, but I prefer the manual re-discovery because it is harder to mess up accidentally across a large fleet.
Alerts and thresholds: what to watch for
Alerting in Orion is flexible, and that flexibility is also its weakness. The default alert templates are decent but noisy. You will get threshold breach notifications for nearly everything out of the box, and most of them are low-value. Critical alerts for node reachability loss are useful. Alerts for minor bandwidth fluctuations on internal links are not. I recommend starting with a strict threshold policy. Set node down alerts to trigger only after three consecutive failed polls, not one. This prevents a single ICMP timeout from waking you up at 2 AM due to a transient blip. Set bandwidth alerts at 80 percent utilization with a sustained duration of ten minutes minimum. One spike does not indicate a problem that needs immediate attention. The alert notification engine supports email, SNMP traps, and integration with tools like ServiceNow and PagerDuty. If you are sending alerts to Slack or Teams, you will need a webhook or an intermediate middleware. Orion does not support those natively without a connector or a custom script.
Limitations and when to look elsewhere
Orion NPM has real limitations. The web console can feel sluggish with more than 10,000 nodes loaded, even on well-provisioned servers. The search function is slow and sometimes returns incomplete results. Custom reporting requires SQL knowledge or reliance on the built-in report builder, which has limited export options compared to dedicated BI tools. If you need pixel-perfect network topology maps with custom branding, you will be disappointed. The built-in topology views are functional but visually dated. Another significant limitation is licensing cost. Per-node pricing adds up fast, especially if you count sensors. A single switch with forty-eight interfaces might count as one node but fifty sensors, and sensor licenses are not always cheap. Make sure you understand your billing model before committing. Some organizations have found better value in tools like PRTG for smaller deployments or Zabbix for environments where open source licensing matters. Cloud and hybrid environments are also a weaker point. Orion was designed for on-premises networks. If you are managing significant cloud infrastructure alongside physical devices, you will need additional modules or a complementary tool to get complete visibility.

What I wish I knew before my first deployment
Plan your SNMP community strings carefully. Use read-only strings and rotate them periodically. I have seen environments where the default public community string was never changed, and while SNMP enumeration alone is not a critical vulnerability, it gives attackers useful information about your network structure. Change the default. Everyone forgets this step during the rush to get the tool running. Back up your Orion configuration database regularly. The built-in backup feature runs daily by default, but verify that it is actually succeeding. I found one environment where the backup job had been failing silently for three weeks due to a permissions issue on the backup share. When a critical configuration change went wrong, there was nothing to roll back to. Check your backup logs weekly. It takes five minutes and prevents major headaches. Use SWIS PowerShell cmdlets for bulk operations. If you need to modify settings across hundreds of nodes, the web interface will frustrate you. The SWIS cmdlets are not the most intuitive to learn, but once you have a working script for bulk changes, you save significant time. A simple PowerShell loop can update polling intervals, adjust alert thresholds, or reassign nodes to different groups in minutes instead of hours.
The tool works. It is not elegant, and it is not free, but it covers a broad range of monitoring needs out of the box. Just give yourself enough time for proper sizing, configuration, and ongoing maintenance, and it will serve you well for years.