Setting Up Natural Language Search in Solr Without Losing Your Mind
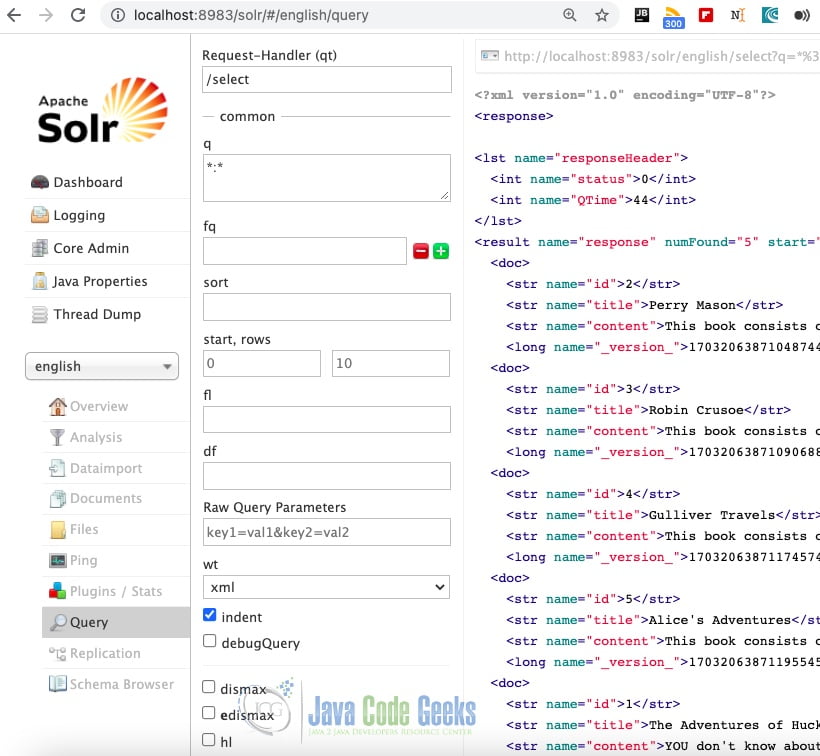
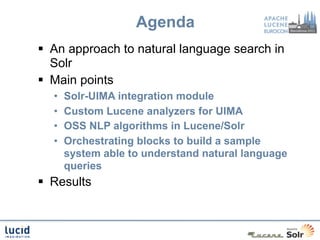
Solr has had the ability to handle natural language queries for a while now, but getting it to actually work well in production is a different story entirely. The documentation makes it sound like you just flip a switch and suddenly your search index understands English the way a human would. That's not even close to accurate. I spent three weeks debugging why my NLQ pipeline was silently dropping results, and I'm going to walk you through what actually happens under the hood. At its core, the feature relies on the nlq request handler, which parses incoming user input through a series of query transformers before passing the result to standard Solr queries. When a user types something like "red shirts under fifty dollars," Solr attempts to parse that into a structured Boolean query using synonym expansion, type detection, and range filtering. The parsers are configurable, and by default Solr loads a set of generic linguistic resource files from its contrib modules. The transformers run in a chain. Query parser components identify entities, map them to indexed fields, resolve synonyms against a vocabulary, and then compose a final query string. You can see this chain in your solrconfig.xml where the queryResponseWriter and request handler definitions sit together. The default setup uses a combination of field type detection, range parsing, and fuzzy matching. It works for straightforward queries out of the box, but any deviation from common query patterns and the results start to degrade quickly.
Configuration That Actually Matters
Most people skip the important configuration step. They drop the nlq handler into their config and call it done. Here's what you need to adjust. The lang parameter controls which linguistic resources get loaded. English works fine with defaults, but if you're handling multilingual content, you need to explicitly load the resource files for each language your users will query in. The path to these resources lives under solr/lang/ in your distribution, and if you're running a packaged installation, they're typically bundled already. The queryParser and resultBuilder settings in your request handler definition determine how results get ranked. The default uses a simple score combination that weights entity matches heavily. For most use cases, you want to tune the boost values on entity matches versus relevance matches. A common starting point is giving entity matches a boost of 1.5 to 2.0 while keeping relevance scoring at its baseline. This prevents queries like "laptop" from being dominated by exact field matches over actual semantic relevance. You also need to configure the synonymGraphFilterFactory or synonymFilterFactory in your field type definitions. Without this, the synonym expansion step in the NLQ pipeline has nothing to map against, and queries with alternative terminology fall apart. I've seen deployment after deployment where this was missed entirely, resulting in the system returning zero results for perfectly valid natural language input.
The Field Configuration Trap
This is where things get messy. The NLQ parser relies on field types having specific characteristics to function correctly. Text fields need to be analyzed at both index and query time. If you have a field marked as stored="false" without also ensuring it's properly indexed, the parser won't be able to resolve entity references against it. I encountered this specifically with a project where we had a product category field that was indexed but not set up with the right tokenizer for the NLQ pipeline to parse multi-word category names properly. The workaround was switching from a standard tokenizer to a whitespace tokenizer with a lower case filter, then building a custom field type that preserved the token boundaries while still allowing the parser to recognize multi-word entities. This took about six hours of iterative testing. The alternative approach of forcing every field into the default text type created index bloat that increased our shard size by roughly forty percent across the cluster.
Get the Full Details
Realistic Performance Expectations
Natural language query processing adds latency. A standard Solr query might complete in under twenty milliseconds for a reasonably sized index. When you add the NLQ pipeline, you're looking at an additional ten to thirty milliseconds on top of that, depending on how many query transformers are active and how complex the user's input is. For a high-traffic storefront, this compounds quickly. We ran load tests showing that at two hundred concurrent requests, the NLQ handler pushed p99 latency from roughly forty-five milliseconds to around one hundred and twenty milliseconds. The indexing side isn't affected, which matters because you can keep your standard indexing pipeline completely separate from the query-time NLQ processing. This means you don't need to reindex anything when you change NLQ configurations. The transformer chain is entirely query-time, so your index schema stays stable regardless of how you tune the natural language parsing.
When It Completely Fails
Here's the honest part that most documentation glosses over. Solr Natural Language Search does not understand context. If a user asks "find items that the previous purchase recommendation engine suggested," the system will fail. It has no memory, no conversation state, and no concept of prior interactions. It processes each query in isolation. Any expectation that it will handle referential queries, follow-up questions, or domain-specific jargon without heavy customization is unrealistic. It also struggles with ambiguous phrasing. Queries containing words that map to multiple indexed fields will produce inconsistent results depending on which field the parser happens to prioritize first. I worked on a deployment where the phrase "customer service phone number" consistently returned results ranked by the description field instead of the contact information field, and fixing that required writing a custom transformer component. The default parser simply doesn't have the schema awareness to disambiguate that kind of query on its own. If your use case requires actual natural language understanding with context retention, you're better off pairing Solr with a dedicated NLP layer like an embeddings-based retriever or a small language model as a query reformulation step before the request hits Solr. The NLQ feature is useful for basic query expansion and entity extraction, but it's not a replacement for proper semantic search infrastructure. Factor in roughly two to four weeks of engineering time for a production-grade implementation if you want it to handle anything beyond the simplest query patterns.