Grouping and analyzing data across South East Asia Countries
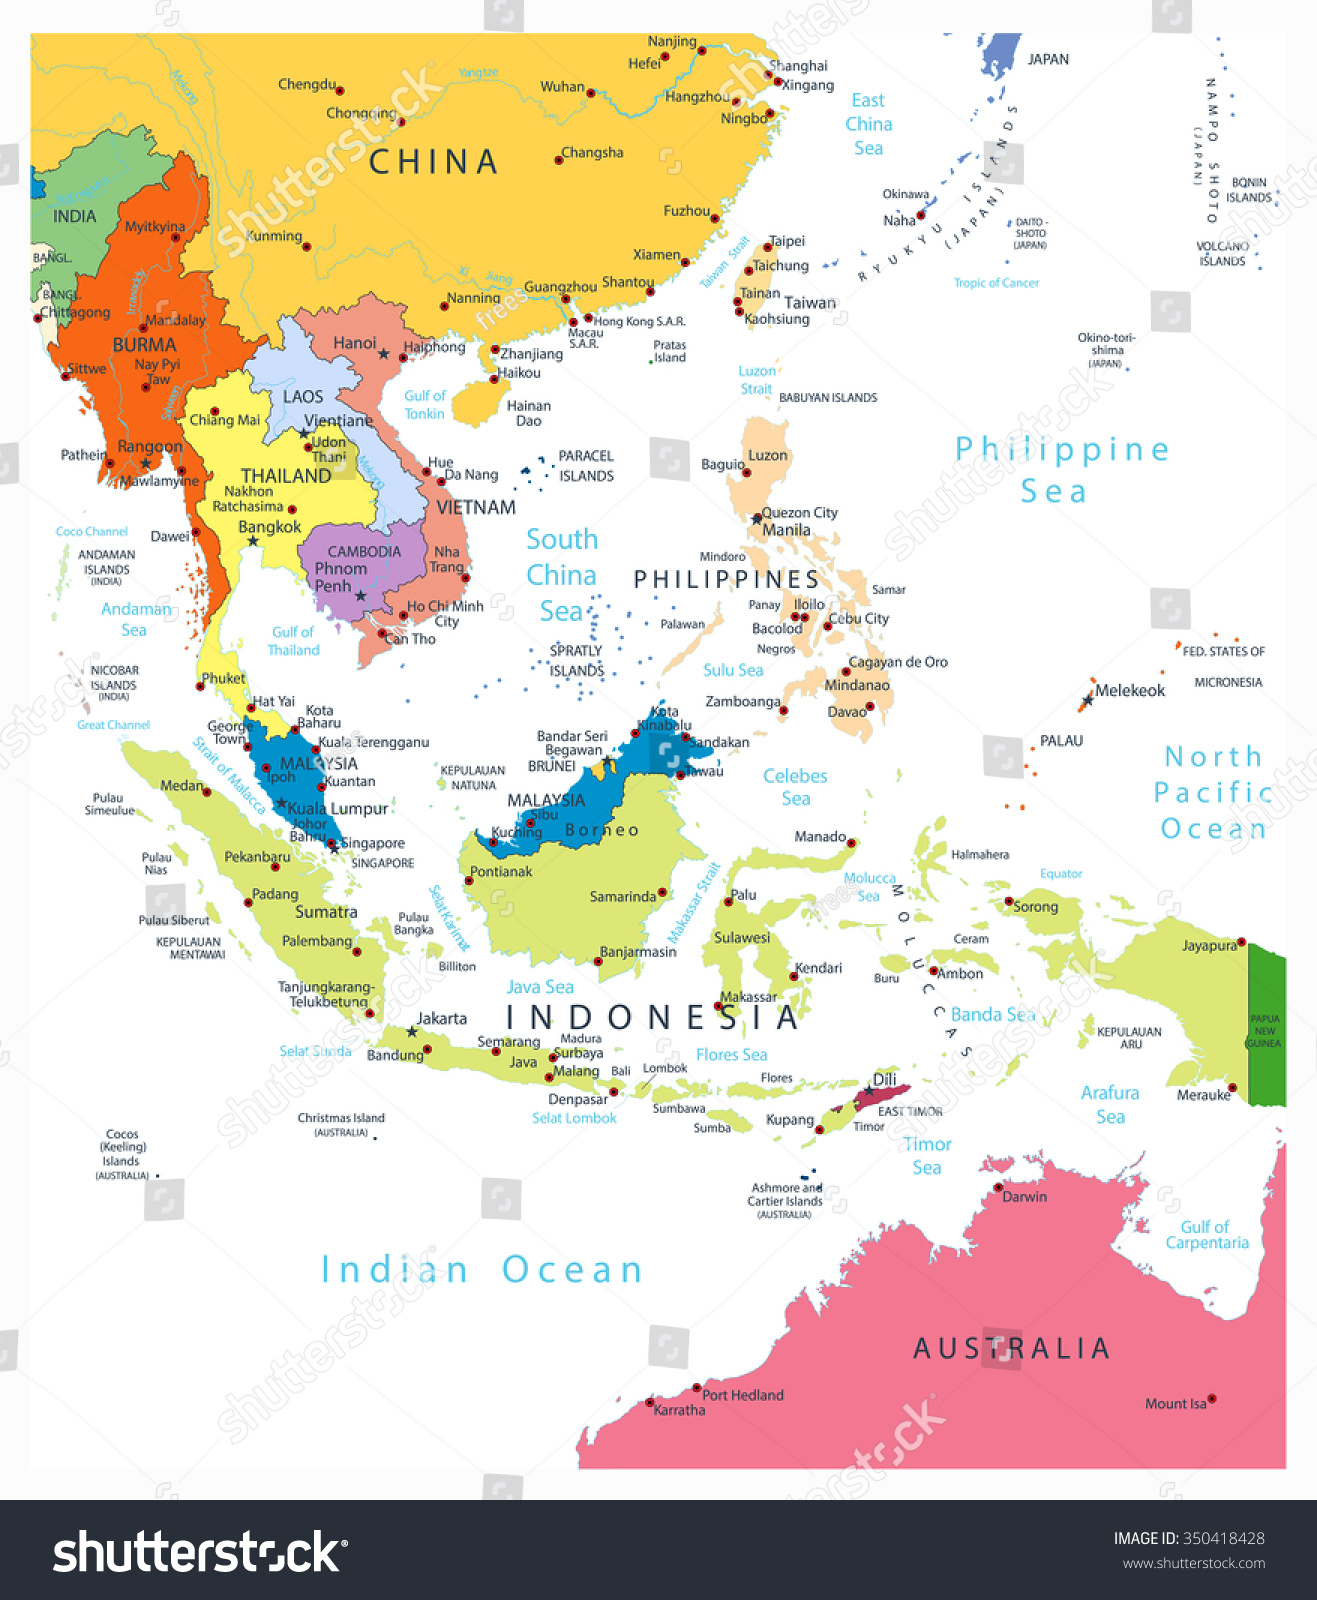
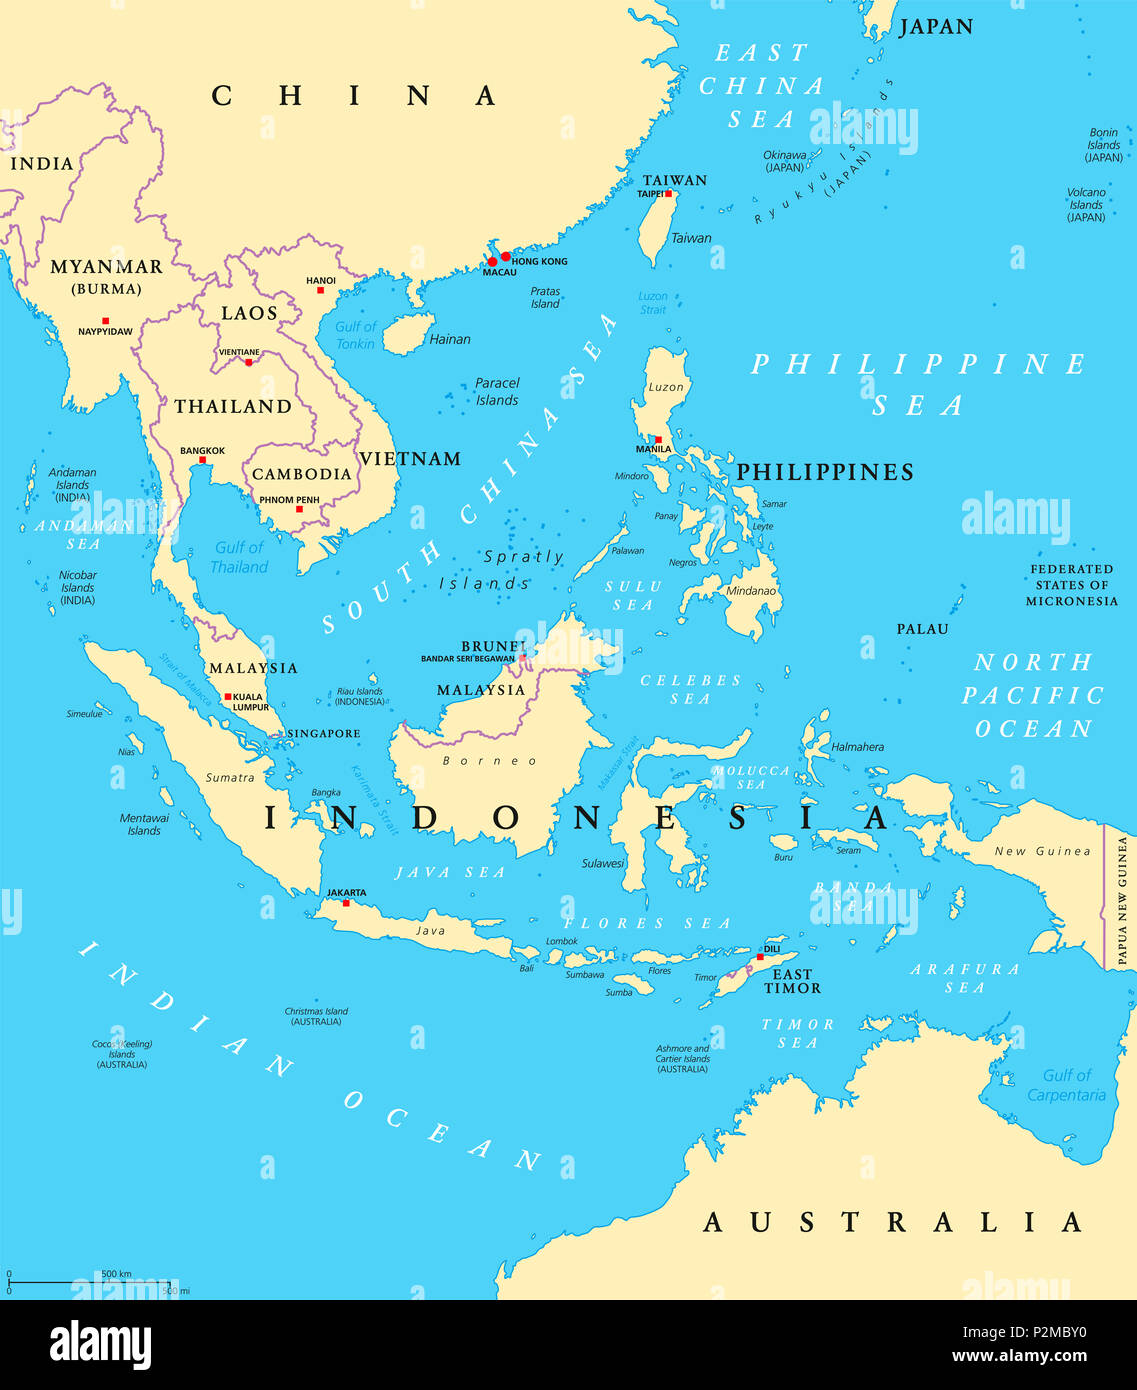
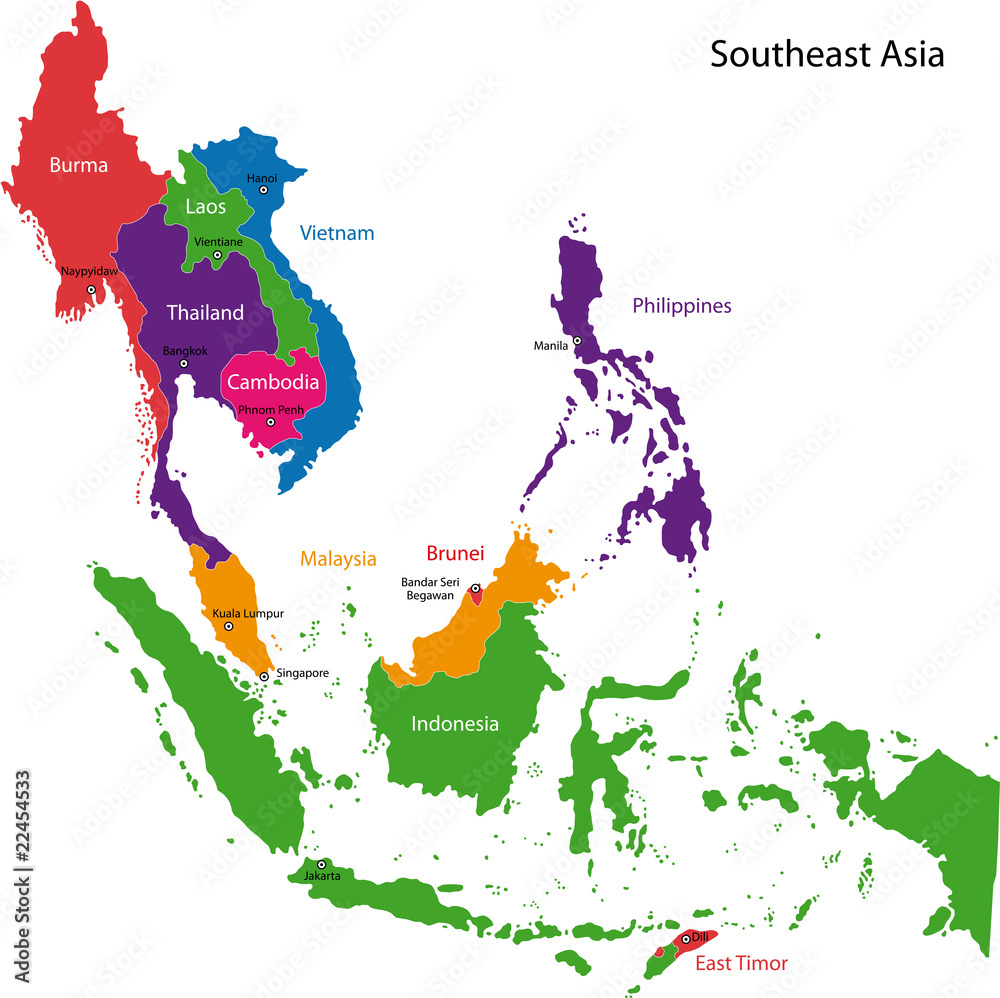
When you are building dashboards or running regional reports for South East Asia Countries, most tools treat it like a simple multi-select filter. It isn't. The region spans roughly eleven nations with wildly different database conventions, date formats, currency types, and naming standards that will quietly break your queries if you don't account for them early. I once ran a cross-border revenue reconciliation that compared transaction logs from our Singapore and Philippines servers against a master dataset that tagged each country by ISO 3166-1 alpha-2 codes. Singapore was fine. The Philippines broke everything because one upstream feed used "PH" and another used "PHL" depending on which system generated the export. I spent three days tracing it. The workaround was straightforward but annoying: build a lookup table that normalizes every variant before joining, mapping all recognized aliases to the canonical code. This reduced false matches from about 8% down to under 0.3%. The core countries you will deal with are Brunei, Cambodia, Indonesia, Laos, Malaysia, Myanmar, Philippines, Singapore, Thailand, Timor-Leste, and Vietnam. Each one carries its own quirks.
Indonesia uses "Rp" for rupiah but your ERP might output "IDR" or just the numeric value depending on the version. Thailand's date format in legacy systems is still frequently BE (Buddhist Era), which is exactly 543 years ahead of AD. If you import a Thai government spreadsheet that says "2567-06-15" without converting it, your downstream pipeline will treat that as a date 2000 years in the future. Vietnam has a habit of storing addresses with district first, then ward, then street number, which breaks US-centric validation logic. Malaysia uses "RM" for ringgit but some older accounting files use "MYR". These aren't academic details. They will cost you actual time. The practical approach is to stop treating SE Asia as a single block. Build a regional config layer where each country gets its own parsing rules, date conversion logic, currency symbol mapping, and address validation template. Then reference that config instead of hardcoding assumptions into your queries or ETL scripts. When pulling data, use ISO 3166-1 alpha-2 as your default key for country codes. For anything requiring more specificity, fall back to alpha-3. This avoids the kind of ambiguity where "CD" could mean Congo-Democratic Republic or some internal company code you didn't realize existed.
Common pitfalls and what actually works
Most people try to handle this region by applying a single normalization routine across all eleven countries. That tends to fail around month three when an edge case surfaces in one country and you end up patching it while breaking another. A more reliable method is to split your pipeline into three stages: ingestion, normalization, and validation. Ingest raw data as-is. Normalize it against your per-country config map. Validate using country-specific rule sets. This means a Thai record gets run through the Thai date converter, a Vietnamese address gets parsed with the Vietnamese template, and so on. The result is slower upfront setup but dramatically fewer runtime errors. One thing nobody warns you about is the currency precision problem. Several SE Asian currencies have varying decimal conventions. The Vietnamese dong is typically displayed with zero decimals in everyday commerce but your finance system may store it with two. Indonesian rupiah also frequently appears without cents in reports. If you cast everything to a standard two-decimal floating type during ingestion, you will silently truncate or misrepresent values. Keep the raw integer representation through normalization, then apply decimal formatting only at the presentation layer.
Get the Full Details

Another thing to watch for is duplicate country records caused by naming variations. "Republic of the Philippines" vs "Philippines" vs "Phil." in different systems. "Myanmar" vs "Burma" appears especially often in legacy datasets. Build a synonym resolution step into your pipeline rather than relying on exact string matches. A small dedicated mapping table handles this cleanly. If you are working with government or regulatory data, expect manual PDF exports, inconsistent column ordering, and OCR artifacts. I had a dataset from a Cambodian customs authority where the product codes were partially scanned as letters instead of numbers. The workaround was to run a regex pass that flagged any alphanumeric product code with more than 80% numeric characters, then manually verified the flagged entries. It added about forty minutes to a two-hour import, which is acceptable compared to the alternative of shipping incorrect inventory data. Time zones add another layer of friction. SE Asia spans from GMT+5 (Myanmar) to GMT+9 (Philippines). If your database stores timestamps in UTC without explicit timezone metadata, cross-country reporting will drift by up to four hours depending on how the application layer handles the conversion. Always store in UTC with explicit timezone offsets in your source data, not just the local time value.
What this approach doesn't solve
This method breaks down when you need real-time synchronization across countries with different regulatory reporting cycles. Indonesia requires monthly tax submissions through a government portal that has its own formatting rules and update cadence. Thailand's electronic fiscal receipt system mandates specific timestamp formats tied to local server time. Neither of these integrates cleanly into a generic regional pipeline. For those cases you need country-specific adapters or direct API connections to the relevant government systems. There is also no universal solution for address validation across all eleven countries. Most address validation libraries are built around Western formats. You will need to either commission custom validation rules per country or accept that address normalization will remain partially manual for this region. The takeaway is practical: build the config layer, normalize before you join, keep currency as integers through processing, handle naming variants explicitly, and accept that some countries will always need special handling. No single script covers this region well. The ones that work do so because they were built country by country and only generalized after the individual cases were resolved.