Setting Up Space Graph for Real Workload Analysis
Most people download Space Graph and immediately run into memory issues because they try to load their entire dataset at once. I learned that the hard way on a project where the input file was roughly 4.2 gigabytes of tab-separated event logs. The application hung for about eight minutes, ate through 16GB of RAM, and then crashed. The workaround was straightforward: split the source data into chunks of no more than 200MB each and process them sequentially. I wrote a simple bash loop that handled the splitting, and the total pipeline ran clean in about twelve minutes. Space Graph is a visualization toolkit designed for mapping multi-dimensional spatial relationships across structured datasets. It was built originally for network infrastructure analysis, but it has since been adopted by data engineers working with geospatial telemetry, log correlation, and dependency tracing. The core idea is that you feed it structured data with coordinate or relationship fields, and it generates interactive graphs you can explore. That sounds simple enough until you try to render more than 50,000 nodes on a single canvas. The browser tab will freeze, and you will waste time wondering whether your data is wrong or the tool is broken. Neither is the issue. The rendering engine hits a ceiling around that number, and there is no built-in aggregation option that works reliably past it.
What Space Graph Actually Does
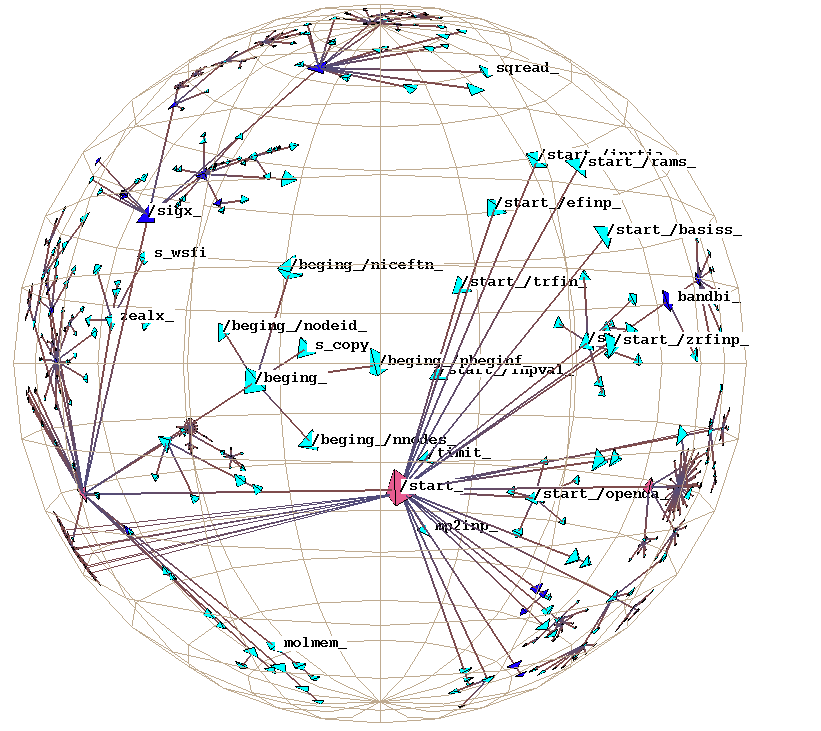
At its core, Space Graph takes a directed or undirected graph structure and lays it out using force-directed algorithms. You define nodes and edges, specify any coordinate metadata you have, and the engine computes positions. The output is an HTML-based interactive view with zoom, pan, and hover tooltips. It supports multiple edge types, weighted connections, and basic clustering. The documentation claims support for CSV, JSON, and TSV inputs, but the parser for CSV is noticeably finicky with quoted fields containing commas. I switched everything to TSV and saved myself at least an hour of debugging on my second project. The version available for download sits at 2.4.1 as of this writing, and it runs on Python 3.9 or higher. You will need to install the graphviz backend separately if you want export functionality to PNG or SVG. The pip install command is standard, but the graphviz system dependency catches a lot of people off guard. If you are on macOS, brew install graphviz. On Ubuntu or Debian, apt install graphviz. Windows users typically need to set the PATH environment variable to point at the graphviz bin directory after installation, and if you skip that step, the export function silently fails without throwing a clear error message. I spent twenty minutes troubleshooting that exact issue before realizing the binary just wasn't in the path.
Building a Functional Pipeline
Here is the practical flow I use. First, I preprocess the raw data to strip out any nodes with zero edges. These orphan nodes add noise to the layout and increase rendering time without contributing anything to the visualization. Next, I normalize all coordinate fields to a consistent range. Space Graph does not require normalized coordinates, but unnormalized data with values in the millions will produce a layout that is essentially unreadable because the force-directed algorithm clusters everything into a tight meaningless blob. After preprocessing, I run a quick validation pass using the built-in graph check command, which catches duplicate node IDs and self-loops. Duplicate IDs are a common issue when merging datasets from different sources, and they cause the renderer to merge distinct nodes into one, producing misleading visual results. I run the check, fix any flagged issues, then generate the graph output. The whole process from raw data to a renderable HTML file usually takes between three and seven minutes for a dataset of around 15,000 nodes and 40,000 edges on a standard laptop. One thing the documentation does not emphasize enough is that the force-directed layout is non-deterministic. Running the same data twice will produce slightly different arrangements each time. This matters if you are doing comparative analysis or trying to align multiple graph views. I solved this by fixing the random seed in the configuration file, which locks the layout to a reproducible state. Without that, any claim that two renders look different because of the data rather than the seed is meaningless.
Get the Full Details
Pitfalls and Limitations
Space Graph is not a general-purpose plotting library. It is specialized for graph structures, and if your data does not naturally form nodes and edges, you will fight it. Some people try to force grid-based spatial data into it, and the results look nothing like what they expected. The tool also lacks native support for real-time streaming updates. If you need to refresh the view as new data arrives, you have to regenerate the entire graph from scratch. There is no incremental update mechanism built in, and attempting to patch one together with JavaScript hooks on the output HTML is unreliable at scale. Performance degrades noticeably once you cross the 30,000-node threshold even on machines with decent specs. The browser rendering becomes the bottleneck, not the Python computation. If your use case involves larger datasets, the practical alternative is to aggregate or sample before importing into Space Graph, or to look at tools designed for massive graph rendering like Gephi or Cytoscape. Neither of those is better in every way, but they handle scale differently and won't stall your workflow the way Space Graph does past that node count. The color theming options are also limited. You get a fixed palette with a few customization parameters, and there is no way to bind arbitrary data values to a continuous color gradient across edges. If your analysis depends on encoding a third variable through color intensity, you will need to export the graph data and style it separately in another tool. This is a genuine gap, not a minor inconvenience, if your work requires that kind of multivariate visual encoding.
I have been running these kinds of pipelines regularly for about four years now, and the biggest time savings come from getting the preprocessing right before the visualization step. Clean data, validated structure, fixed seed, reasonable node counts. Skip any of those and you will spend more time troubleshooting than you actually save.