Most people run into the actual problems only when they try to use vector spaces for something beyond homework. The abstract definition is clean on paper. Real code and real data don't care about clean paper.
What this is, before anything else: a vector space is a set where you can add elements and scale them by numbers, following a fixed list of axioms. That's it. Anything that satisfies those axioms is a vector space. Polynomials, matrices, function spaces, coordinate tuples — they're all the same thing structurally. The confusion comes when someone treats them as different topics instead of recognizing the pattern.
The practical starting point is picking your basis. Every basis gives you coordinates, and every coordinate system introduces distortion somewhere. If you're working in R^n, fine, use the standard basis. If you're dealing with signal processing or differential equations, the standard basis is usually the wrong choice and you'll pay for it later.
I spent two weeks debugging a machine learning pipeline where the feature space was implicitly treated as Euclidean when it absolutely wasn't. The data lived in a high-dimensional polynomial space. Distances computed with the standard dot product made no sense. Switching to a kernel-aware representation solved it in a day, but the initial symptom was just "the model scores look wrong." No error, no crash. Just bad results.
Understanding Spaces Linear Algebra Foundations
You need to understand span, independence, and dimension before anything else. Those three concepts show up in every application. If you can't tell whether a set of vectors spans your space, you're guessing.
A basis is a minimal spanning set. That's all the formal definition adds. In practice, finding one is where things get interesting. Gaussian elimination works for finite-dimensional cases. For function spaces, you're usually constructing a basis by inspection or through an orthogonalization process like Gram-Schmidt.
Gram-Schmidt is a common reference point, but it's numerically unstable. If you need an orthogonal basis for anything computationally serious, modified Gram-Schmidt or Householder reflections are the standard replacements. The difference matters when your vectors are nearly linearly dependent. I've seen precision drop from double to single effectively because someone ran classical Gram-Schmidt on a nearly singular matrix.
Projection is the workhorse operation. Once you have an orthogonal basis, projecting a vector onto a subspace is straightforward: sum the individual projections onto each basis vector. That's the math. The implementation detail most people skip is that you need to normalize your basis vectors or divide by their squared norms, otherwise the formula breaks.
Common Operations That Actually Matter
Matrix representations only exist once you fix a basis. Change the basis and the matrix changes. The underlying linear transformation does not. That distinction gets blurred constantly and causes real mistakes.
If you compute eigenvectors and eigenvalues, you're looking at a special basis where the transformation becomes diagonal. Not every operator has a full eigenbasis. Over the reals, rotations in R^2 are the textbook example. They have no real eigenvectors. You need to move to complex numbers or accept that the matrix isn't diagonalizable.
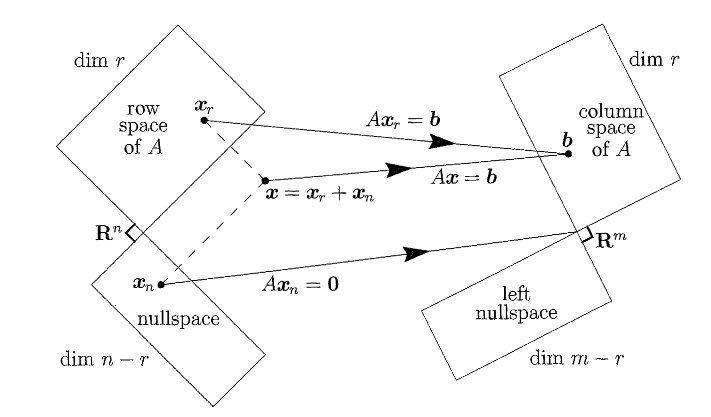
Rank, nullity, and the rank-nullity theorem connect the dimensions of the column space and the null space. This is not optional knowledge. When you're solving Ax = b and the solution doesn't exist or isn't unique, rank tells you why immediately. A rank-deficient matrix means either no solution or infinitely many. The singular value decomposition resolves both cases cleanly.
SVD deserves more attention than it gets. Every matrix A decomposes into UV^T. The singular values in tell you the effective dimensionality of the transformation. Zero or near-zero singular values mean the matrix is close to rank-deficient. This is how you handle ill-conditioned systems without resorting to regularization heuristics.
I worked on a computer vision project where the geometry estimation step produced a nearly singular matrix. The naive inverse gave wildly oscillating answers. Pseudoinverse via SVD with a threshold on the singular values stabilized everything. We just discarded components below a practical noise floor. It's not theoretical. It's what separates working code from crashing code.
Subspaces and Their Relationships
Intersection and sum of subspaces come up more often than textbooks suggest. The intersection is what both spaces share. The sum is everything you can reach by combining vectors from each. Dimension formulas connect them:
dim(U + V) = dim(U) + dim(V) - dim(U V)
This looks trivial until you need to compute it. Finding the intersection explicitly requires solving a system. Setting up the right equations depends on how your subspaces are represented. If they're given as spans, you stack the basis vectors and row reduce. If they're given as null spaces, you work with the defining matrices directly. Mixing representations without converting first is a reliable way to waste time.
Orthogonal complements are useful because they give you a clean decomposition: any vector splits uniquely into a component in the subspace and a component in the orthogonal complement. That's what least squares optimization is built on. The residual is orthogonal to the column space of your design matrix.
When Vector Spaces Break Down
Not every useful structure is a vector space. Cones, manifolds, and quotient spaces appear in applications and they don't follow the same rules. Convex optimization lives on convex sets that aren't vector spaces. General relativity uses manifolds where local coordinates replace global linear structure. Quotient spaces arise when you identify vectors that differ by something in a subspace, which is essential for understanding projective geometry and error-correcting codes.
Finite fields change the arithmetic entirely. Linear algebra over GF(2) is fundamental to coding theory and cryptography. The same algorithms apply, but subtraction is addition and scaling is restricted. Expect different behavior from Gaussian elimination and pivoting strategies.
Infinite-dimensional spaces require topology. Pointwise convergence isn't enough. You need norms or inner products to define distance, and then you need completeness to guarantee limits exist. Hilbert spaces are the standard framework for quantum mechanics and signal processing. Banach spaces generalize further by dropping the inner product requirement.
Practical Recommendations
Learn to move fluently between coordinate-free and coordinate-dependent reasoning. The coordinate-free view keeps you from making category errors. Coordinates are necessary for computation. Both are needed.
Use SVD before pseudoinverse before any custom solver. It's slower than specialized methods in some cases but it exposes the structure of your problem. That visibility prevents silent failures.
For numerical work, always check condition numbers. A condition number above 10^8 in double precision means you should expect meaningful loss of significance. There's no workaround that doesn't involve restructuring the problem or increasing precision.
Documentation and references that are worth keeping close: Axler's Linear Algebra Done Right for the coordinate-free approach, Trefethen and Bau for numerical linear algebra, and Strang for the applied perspective. Each covers different gaps the others leave.
Gallery Spaces Linear Algebra
Vector Space Examples Linear Algebra Pdf Examples Of Vector Spaces
Introduction to Vector Spaces - Linear Algebra (full course) - lecture 13 (of 23) - YouTube
Linear Algebra | S01E01 Vector Spaces| B.A/M.A Economics Entrance ISI/DSE - YouTube
Vector Space In Linear Algebra Examples Day 30: Mat234 (linear
Linear Algebra for Machine Learning | CS-677