What Spans And Layers Analysis Actually Looks Like In Practice
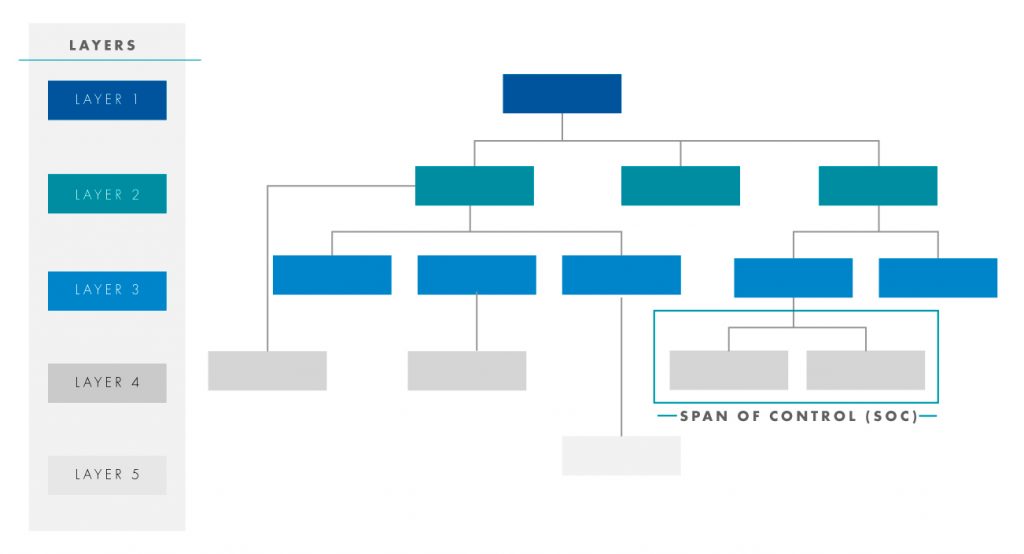
I spent about three years building a dashboard that tracked departmental performance across multiple fiscal quarters, and the part nobody warned me about was handling overlapping date ranges and hierarchical data layers in Excel without making the thing crash. What you're probably looking for when you search Spans And Layers Analysis Excel is a way to take messy, multi-dimensional spreadsheet data and break it into manageable chunks so you can analyze each segment independently while still seeing the aggregate picture. At its simplest, you're taking a dataset that has both temporal spans (start dates, end dates, durations) and organizational or categorical layers (regions, divisions, product lines) and building a framework where each combination gets its own analytical view. The typical structure involves a master data sheet with raw entries, a spans definition table that calculates the relevant time periods or range boundaries, and a layers table that maps each record to its hierarchical position. You then use a combination of INDEX/MATCH arrays and SUMPRODUCT formulas to pull the right numbers from the right places. I built my first version using VLOOKUP and it was a disaster. When you have 40,000 rows with six different layer combinations, VLOOKUP will either give you wrong matches or take twenty minutes to recalculate each time you touch a cell. Switching to INDEX with MATCH on sorted lookup arrays cut my refresh time down to under thirty seconds. The trade-off is that your data setup has to be more disciplined upfront, but that is always the case with anything that scales beyond a few hundred rows.
Here is the basic formula structure that handles the intersection of a single span and a single layer: =SUMPRODUCT((SpansTable[SpanID]=CurrentSpan)*(LayersTable[LayerID]=CurrentLayer)*(MasterData[Amount])) This looks clean until you put it on a large grid and discover that SUMPRODUCT across fifty thousand rows becomes brutally slow. The workaround I ended up using was to create an auxiliary column in the master data that concatenated the span ID and layer ID, then used COUNTIFS against that helper column instead. Same mathematical result, roughly ten times faster on my machine.
Common Pitfalls That Nobody Talks About
The first issue is overlapping spans. If your date ranges are not mutually exclusive, a record can fall into multiple periods and your totals will double count. I encountered this when someone built a reporting window that included partial months at the edges of quarter boundaries. My fix was to enforce a strict no-overlap rule at the data entry level with a validation script that checked whether any new span intersected existing ones, and to flag records that landed on boundary dates for manual review rather than automating the cut. The second issue is sparse layer combinations. In my project, not every region had every product line in every quarter, which meant your analysis grid had thousands of empty cells. Excel treats these differently depending on what formula you use. COUNTIFS skips them. SUMPRODUCT includes them as zeros. But if you are using any kind of pivot calculation or array formula that references empty ranges, you can get #REF errors or silent miscounts. I resolved this by building a complete span-layer combination table upfront with all possible pairs, then left joining the actual data onto it. Empty combinations show as zero rather than error, and the structure makes it obvious when data is genuinely missing versus just not yet entered. A third problem that comes up frequently is the dynamic range problem. When you add new spans or layers, your named ranges and formula references do not automatically expand unless you convert your source data to an Excel Table first. I used to manually update range references every time the dataset grew, which meant I missed updates about once a month and spent the next week cleaning up stale numbers. Converting everything to tables eliminated that entire class of error.
Get the Full Details
Building The Layer Hierarchy Properly
Layers are where most people make structural mistakes. The naive approach is to store layer assignments as individual columns for each level, like Region, Division, Team, and Analyst. This works until you need to roll up from Team to Division without also including the Analyst detail, or filter by Region while keeping Division visible. The cleaner approach is a single hierarchy column that encodes the path, something like "NorthAmerica>US>West>TeamA", combined with a separate mapping table that breaks each path into its component levels. This gives you the flexibility to slice at any level without duplicating data. You can build a lookup that pulls all descendants of a given node using a LEFT function on the hierarchy string, which is faster than recursive queries and does not require Power Query or VBA. The downside is that your hierarchy strings become harder to read in a raw data dump, but since this is an analysis backend rather than a front-end report, that is a minor concern.
When This Approach Breaks Down
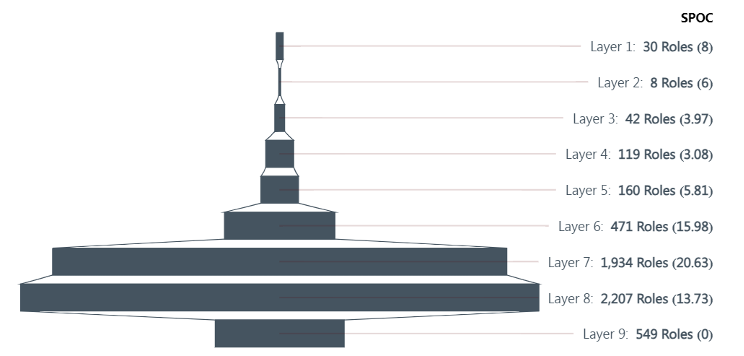
Spans And Layers Analysis Excel works well for datasets up to roughly 100,000 rows with maybe twelve to fifteen layer levels and eight to ten span periods. Beyond that, the formula-based approach becomes unstable. You will notice recalculation times climbing exponentially, and workbook corruption becomes a real risk if you are editing complex arrays frequently. At that scale, you should move the analysis layer out of Excel entirely and use a proper database or Power BI dataset, keeping Excel only as a presentation front end connected through Power Pivot or Power Query. Another scenario where this method fails is when your spans are not time-based but event-based with fuzzy boundaries. If a span is defined by a customer action rather than a calendar period, you cannot easily predefine the span grid and must calculate overlaps dynamically. That requires a different approach entirely, usually involving iteration or a scripting language. I ran into this when a client wanted to measure "engagement windows" between two timestamps that varied per transaction, and Excel formulas were not going to cut it. If you want to see how the basic structure looks in a working file, I keep a simplified template available. It covers the master data sheet, the spans and layers definition tables, the helper columns, and the core aggregation formulas. The file is structured so you can drop in your own data and adjust the span boundaries without touching the formulas. It does not handle the edge cases I mentioned above, but it is a solid starting point for understanding the mechanics before you build something production-ready.