Handling Non-Standard Glyphs in Production Code
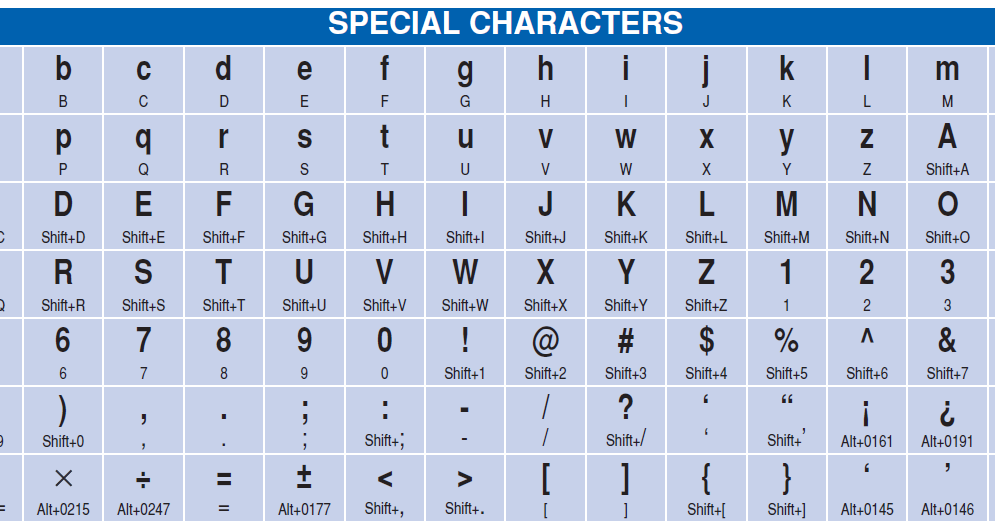
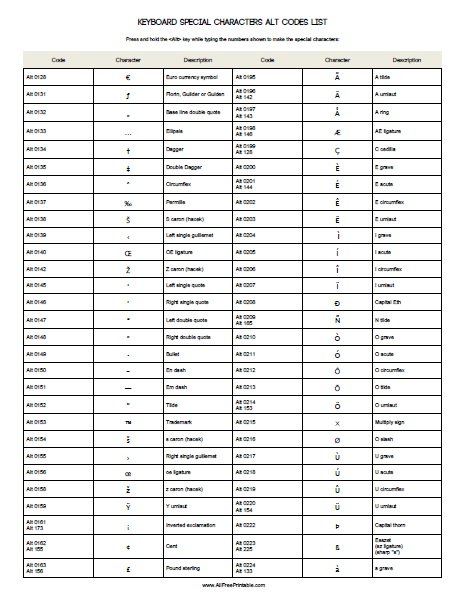
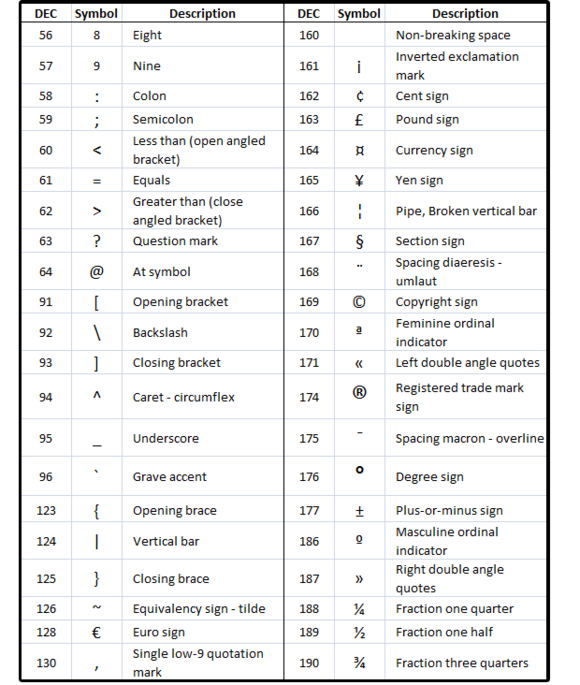
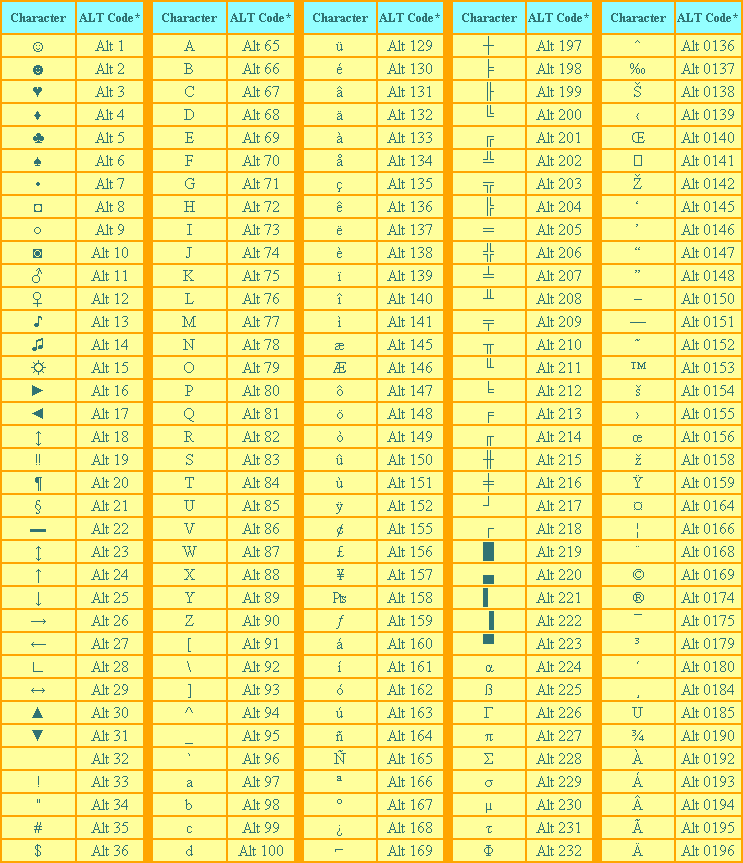
You are building a form, a report generator, or a content management system that needs to accept and display characters outside the standard ASCII set. You might be pulling data from a legacy source, generating invoices with specific currency symbols, or letting users paste content from word processors. The moment you try to insert a symbol that is not a letter, number, or common punctuation mark, you run into encoding issues, font limitations, and broken rendering. A Special Characters Symbols List is your reference point for navigating those failures. I used to think symbol support was solved because every modern browser handles Unicode. That belief broke on a project where I was pulling a PDF export of financial tables and pasting the content into a SQL insertion script. The numbers looked fine until the database rejected rows with hidden zero-width joiners and copy-pasted smart quotes that changed column widths. I had to trace back to the source, strip the invisible characters, and map every visible symbol to its correct Unicode code point before the pipeline worked again. A structured list saved me from guessing which glyph was causing the break. The items you will see in a Special Characters Symbols List are grouped by function and encoding block. You get basic Latin extensions for accented letters, general punctuation marks, currency signs, mathematical operators, box-drawing characters, arrow symbols, dingbats, and a wide range of emoji that behave differently across platforms. Each entry usually includes the visual glyph, the named entity if it exists, the Unicode code point, and sometimes the HTML or CSS escape form. That combination is what lets you pick the right representation for the system you are targeting.
The best references are the official Unicode charts and the HTML character entity lists maintained by web standards bodies. Browser-based reference pages are useful for quick lookups, but they change and sometimes hide rare blocks behind navigation menus. For a Stable source, I use the Unicode character database export and filter it by name or range. If you need something you can open without internet, a local HTML cheat sheet generated from the public Unicode data works better than pinned browser tabs. Search terms like Special Characters Symbols List often return a mix of outdated blogs and SEO pages, so I prefer the raw tables and then I format them myself. I generate a working list by exporting Unicode names and code points, filtering to the blocks my project touches, and converting each entry into a table row with three columns: the rendered glyph, the code point, and the safe HTML entity. I then run a small validation pass that checks which entries fail in my target environment. That validation step is where I catch the difference between a symbol that looks correct in a font preview and one that breaks layout in the actual app. The export process usually takes about twenty minutes for a focused subset, and it cuts future lookup time down to roughly three minutes per issue. When you have a curated list, you stop opening generic symbol pages and start searching your own file instead. That shift alone prevents most of the encoding mistakes I see in early prototypes.
Encoding, Fonts, and Why Symbols Break Across Systems
Unicode solves a lot of naming problems, but it does not guarantee rendering. A glyph may exist in the standard while the system font simply does not include it. In those cases, the browser or application shows a replacement character, a broken box, or nothing at all. HTML entities like © or & are resolved by the parser, but complex symbols often require either a CSS font-face fallback or direct Unicode input. When you paste from a word processor, you frequently pull in formatting metadata and zero-width spaces that make text look normal but behave oddly in selectors and regexes. That is why I sanitize paste input before storing it, and I compare the cleaned result against the expected code points in my list. You insert symbols by copying the glyph from the list, using the code point with a CSS or JavaScript escape, or inserting the named entity directly into markup. CSS content properties accept Unicode escapes, and JavaScript strings accept the same syntax. HTML allows named entities for common punctuation and currency marks, but many rare symbols only have numeric decimal or hexadecimal references. If you are generating output for a system that strips unknown entities, prefer the numeric decimal form because it is less likely to be removed by aggressive sanitizers. I keep the list open in a split pane while I work, and I tag each symbol with the environment it passed validation in. That tag prevents me from reusing a glyph that looked fine on my local machine but failed in the staging build. The routine is slow at first, but it removes the most common debugging loops around missing glyphs, wrong encoding declarations, and unexpected null bytes in input fields.
Get the Full Details
Edge Cases You Will Encounter
One recurring problem is combining marks and ligatures. A single visual symbol may actually be two or more code points stitched together. If your regex or string matcher expects one character, it will miss the sequence. Another issue is emoji variation selectors. Some emoji render as text by default and as color graphics only when a specific selector is present. Without that selector, parsers may treat the symbol as plain text and apply text styling instead of the intended presentation. I handle this by normalizing strings to NFC form before storage and by checking the expected code point length rather than relying on visual count. Another practical edge case involves right-to-left marks and bidirectional text. A symbol that sits next to Arabic or Hebrew text can shift cursor positions and break alignment in UI components. I caught this when a customer support tool displayed ticket numbers incorrectly after users pasted content containing mixed-direction markers. The fix was not to remove the symbol, but to wrap the affected span with explicit direction controls and verify the output with a bidirectional text inspector.
Limitations of Any Static List
A Special Characters Symbols List is only as reliable as the environment that renders it. New emoji releases change approved characters, and some symbols are deliberately deprecated or restricted in certain contexts. Legacy databases that expect ISO-8859-1 or Windows-1252 will reject many entries without explicit conversion. If you store symbols in a column with a collation that treats certain characters as equivalent, search and sort behavior can become unpredictable. These constraints are not failures of the list itself, but they mean you must validate each symbol against your storage schema, your query engine, and your display layer before marking it as usable. I do not recommend relying on someone else's generic download link because those files often contain outdated blocks and unvalidated symbols. Instead, I generate a personal list from the public Unicode data and host it as a simple HTML file with search and filtering. You can build that in under thirty minutes using a script that pulls the Unihan and UnicodeNameAliases data, formats the selected range into a table, and exports it as a single-page reference. The result is a Special Characters Symbols List that matches your actual tech stack, includes only the glyphs you validated, and stays current when you rerun the script after a Unicode update. The file I distribute internally is an offline HTML page with three panels: a searchable glyph grid, a CSV export of code points and names, and a small validation log showing which symbols passed tests in our target browsers and database collations. The page itself is under two megabytes, loads instantly without external requests, and includes a printed view for quick reference. I store it in the project's documentation folder and link to it from the developer onboarding notes. That placement keeps the list visible during implementation and reduces the time spent researching symbols mid-sprint.
Do not assume that all symbols in a generic article are safe for your system. Many web pages list decorative dingbats that look fine in previews but fail in older browsers or in systems that strip unknown markup. Do not rely solely on visual matching; verify the code point, the entity form, and the normalization state. Do not copy from a rendered webpage without inspecting the source, because clipboard content often carries hidden formatting that changes how the character is stored. And do not treat emoji as interchangeable across platforms; the same visual symbol can have different underlying sequences and presentation behaviors depending on the OS. If your project only needs a handful of common symbols, you can avoid most encoding pain by using named HTML entities and CSS pseudo-elements for the frequent cases. For heavy symbol usage, such as icon sets or specialized mathematical notation, a dedicated font library or SVG sprite approach is more stable than raw Unicode pasting. Those alternatives give you controlled rendering and consistent fallback behavior, though they add a build step and a dependency. Choose the method that matches your deployment constraints and your tolerance for maintenance overhead. A well-maintained reference beats guesswork every time. When you know the code point, the safe entity form, and the environment validation status, you stop chasing rendering errors and start shipping forms, reports, and interfaces that handle special characters without surprises.