What a spend analysis report actually looks like in practice
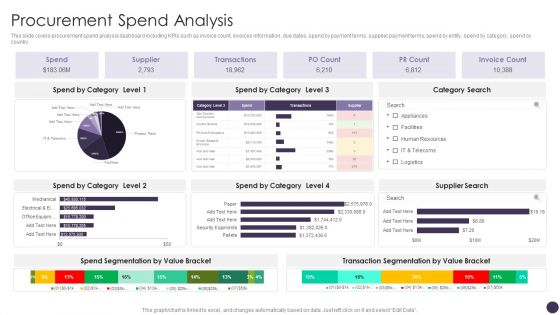
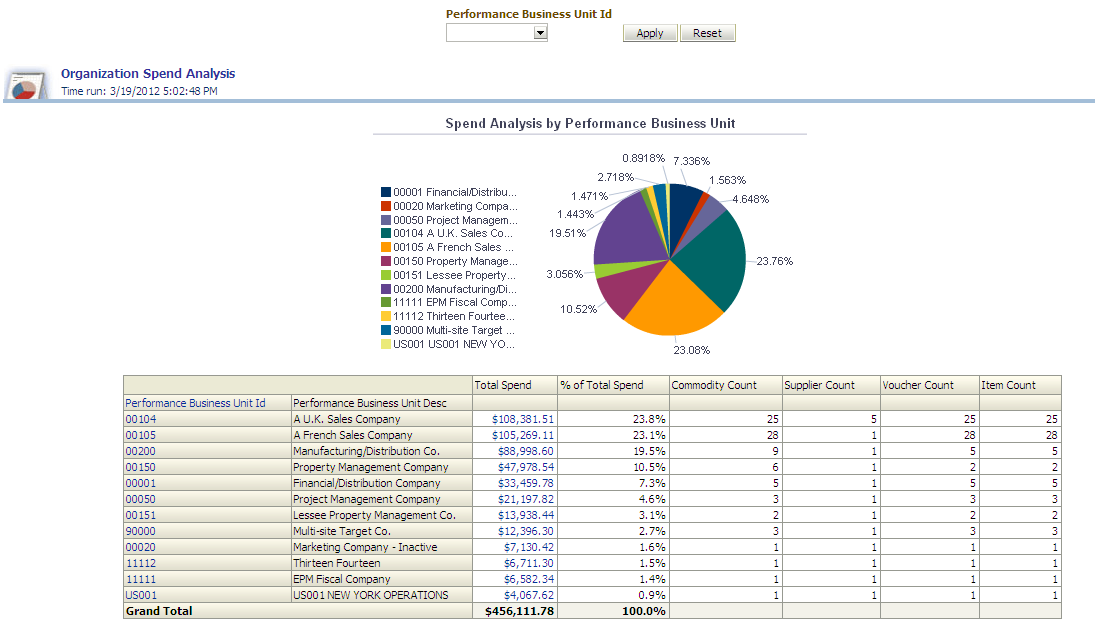
The first thing most people get wrong is thinking spend analysis is about collecting receipts. It isn't. It's about mapping every dollar that left your organization over a defined period and categorizing it in a way that reveals where leverage actually sits. A spend analysis report example that I put together recently for a mid-size manufacturing client looked like this: purchase orders from the last 24 months, cleaned and remapped to GL codes, with supplier consolidation showing we were spending $4.2 million across eleven different vendors on the same category of industrial adhesives. The savings opportunity wasn't in negotiation, it was in noticing the duplication and moving to a single source. Here's the layout I've used consistently across more reports than I can count. The first section is always the data inventory, which sounds boring but is where 70 percent of projects die. You list every source system you're pulling from, the date range, the approximate record count, and the known quality issues. A sample entry might read: SAP ERP, AP module, 14 months of data, approximately 38,000 line items, roughly 12 percent missing commodity codes. Be honest about this section. The people reading your report will find out if you weren't. The second section is the spend characterization framework. This is where you define how you're categorizing data. The standard approach uses the UNSPSC or eCl@ss taxonomy, but most companies I work with just map internally to their chart of accounts plus a custom layer for supplier grouping. For the adhesive example, I created a three-layer hierarchy: Level 1 (MRO), Level 2 (Chemical Adhesives), Level 3 (Industrial Tapes and Epoxies). Each transaction gets tagged at Level 3. This granularity matters because it's what lets you spot that you have eleven suppliers instead of one.
The third section is the analysis output. Pareto charts showing the top ten suppliers by spend, category penetration heatmaps, price variance tables across sites, and supplier risk scoring. The numbers drive the story. I once had a situation where the Pareto chart showed an 80/20 split that looked textbook until I realized the top five suppliers were all subsidiaries of the same holding company. Our real supplier concentration was half of what the initial data suggested. That changed the entire negotiation strategy from supplier-by-supplier deals to a group-level conversation. Fourth section is always recommendations with expected savings ranges. Not exact numbers. Ranges. A realistic range for the adhesive situation was $600K to $900K annually based on volume commitment scenarios. The wide gap exists because procurement didn't yet know whether they could consolidate demand across two European sites that had been operating independently for years. That uncertainty gets flagged explicitly.
The cleanup problem nobody warns you about
Data in these reports is rarely clean. I spent three weeks on a healthcare spend analysis where "Office Depot" appeared under twelve different names: OfficeDepot, Office Depot Inc, Staples Business Division (a miscode that somehow happened), OD Supply Co, and a few others that were clearly test entries from a sandbox system that hadn't been purged. The fix was a fuzzy matching script paired with manual review of anything scoring below 85 percent confidence. But here's the thing most guides skip: don't trust automated deduplication alone. I ran a dedup algorithm on a construction client's data once and merged three separate entities belonging to the same parent company into a single supplier, then built an entire category strategy around that false consolidation. The procurement director nearly signed a contract that would have violated their conflict-of-interest policy. A two-hour manual audit would have caught it. The practical rule I follow now is this: run the automated match, but flag every merge where the legal entity names differ for human review. This adds maybe an hour of work per 5,000 records, which is nothing compared to getting it wrong. Also, check the dates. I once found purchase orders from 2019 still being posted in 2023 in a dormant cost center that nobody had closed out. The spend was inflating headcount categories entirely.
Get the Full Details

Where spend analysis completely fails
It fails when the underlying transactional data is so poor that categorization becomes guesswork. I've seen this in companies that merged recently and have three different ERP systems with incompatible chart of accounts, no master data governance, and purchase order descriptions that are literally single words like "materials" or "services." In those cases, the analysis produces noise dressed as insight, which is worse than no analysis at all because leadership actually believes it. The workaround is to start with a smaller, higher-quality slice, prove the method works, then expand. Don't boil the ocean on day one. It also fails when the goal is really just cost reduction without understanding demand. If you analyze spend and conclude "we spend too much on logistics," you've identified a problem but haven't done the work of figuring out whether the demand itself is rational. Maybe those shipping costs are high because sales agreed to five-day delivery on low-volume accounts that should be on two-week consolidated shipments. That's an operational issue, not a procurement pricing issue. Spend analysis surfaces it but doesn't solve it. You need the operational people in the room for that part.
A note on tools
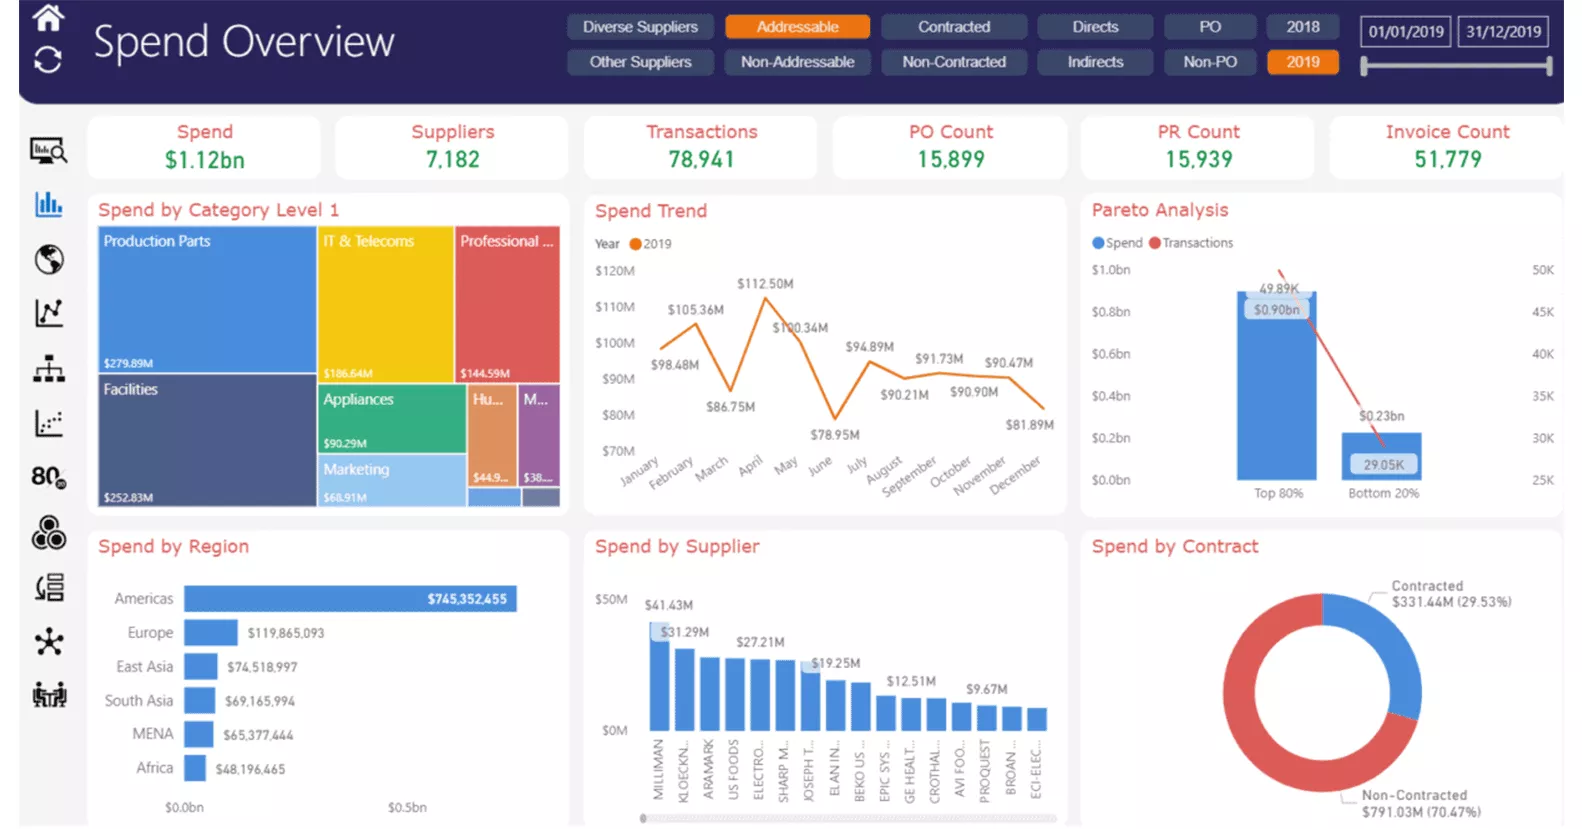
I've used Coupa, SAP Analytics Cloud, Tableau, and straight Excel for these reports. Excel still handles about 60 percent of the cases I see because the dataset is small enough and the stakeholders want to poke at the numbers themselves. For anything over 100,000 line items, Excel becomes a liability. The bottleneck is never the analysis, it's the data prep, and no amount of VLOOKUP will save you from 40,000 rows of inconsistent supplier names. A lightweight Power BI dashboard connected directly to the cleaned dataset tends to be the sweet spot for most mid-market organizations. If you're building your first version, keep it simple. One category at a time, one data source at a time, one stakeholder interview per week. The reports that look impressive to executives are usually the ones that took six months to build properly. The ones that actually change behavior are the ones that answer one specific question clearly and stop there.
A specific case from my recent work
Last quarter I ran a spend analysis for a 2,000-employee tech company that had grown through four acquisitions in five years. Each acquisition brought its own vendor contracts, its own purchasing policies, and its own incomplete chart of accounts. The raw data across all systems totaled about 220,000 transactions over 36 months. The initial Pareto showed $18 million in IT services spend spread across forty-three different vendors, which looked like an obvious consolidation opportunity. The deeper analysis revealed that eighteen of those vendors were actually the same company invoiced through different regional subsidiaries after the acquisitions. Another seven were managed service providers billing through a parent reseller. Once I mapped the true economic relationships, the vendor count dropped to twenty-one and the actionable spend concentration jumped to six suppliers controlling 68 percent of the category. The real recommendation wasn't "negotiate harder with everyone," it was "pick one of the six and renegotiate the group terms, let the rest follow." We saved approximately $1.4 million in year one against a baseline of $18 million in that category. The thing I'd do differently is flag the subsidiary mapping problem earlier. I spent the first three weeks confused by why certain supplier IDs kept reappearing with slightly different names before connecting it to the acquisition timeline. If I'd pulled the org history up front, I could have started with the consolidated view instead of cleaning data I'd have to re-clean later.
Wrapping this into something usable
If you need a starting template, the structure is straightforward enough to build in any spreadsheet tool. Columns for date, supplier name, GL account, commodity code, amount, site, PO number, and a flag column for data quality issues. That's it for the raw layer. From there, pivot tables and a few calculated fields get you the Pareto breakdown and category totals. The value isn't in the template, it's in knowing which columns matter before you start and being willing to stop when the data stops being useful.