
Getting Started With SPSS Without Losing Your Mind
SPSS is a proprietary statistics package made by IBM. The full name is Statistical Package for the Social Sciences, but nobody uses that anymore. It has a point-and-click interface that most people start with, and a syntax window that experienced users live in. Both do the same calculations; the syntax version just saves you from clicking through the same dialogs dozens of times. The interface has three main panes. The Data View shows your spreadsheet. The Variable View lets you define names, types, measures, and value labels. The Syntax Editor is where you write commands. You can generate syntax by running dialogs and clicking Paste, or you can write it from scratch. Learning the syntax isn't optional if you plan to do anything more than one t-test.
Understanding Spss Data Analysis And Interpretation
Data analysis in SPSS means importing a dataset, checking your variables, running a test, and reading the output. Interpretation is the separate step where you decide what the numbers actually mean in context. Most beginners conflate these two steps and draw conclusions from output without verifying their data first. That is where mistakes happen. The most common starting point is your dataset. SPSS handles .sav files natively, but you can import CSV, Excel, and many other formats through File > Import Data. When you import from Excel, check the "Read variable names from the first row of data" option. If you skip it, your first variable becomes named "x1" or whatever Excel generates instead of your actual column header. I have seen this error multiple times in thesis submissions.
Variable Setup Before You Run Anything
Before any analysis, go to Variable View and set three things correctly: the measure type, the value labels for categorical variables, and missing value definitions. The measure type determines what tests SPSS considers appropriate. Nominal, ordinal, and scale are the three categories. If you code gender as 1 and 2 but mark it as Scale instead of Nominal, SPSS will happily calculate a mean for it. A mean gender of 1.47 is technically a number, and it is completely meaningless. Value labels are how SPSS tracks what your codes actually represent. You enter 1 for male and 2 for female in the Values column. The output will show "male" and "female" instead of raw numbers if labels are set correctly. Without them, you are reading output that says "Group 1 had a mean of 3.42" and spending ten minutes cross-referencing your coding sheet. Set the labels once and move on.
Get the Full Details

Running Basic Tests
An independent samples t-test lives under Analyze > Compare Means > Independent-Samples T Test. You select your grouping variable and your test variable. The grouping variable needs exactly two values. SPSS will throw an error if you give it three. Define the group values before clicking OK—enter 1 and 2 if that is how your data is coded. One-way ANOVA is under Analyze > Compare Means > One-Way ANOVA. You put your dependent variable in the Dependent List and your factor in the Factor box. Post-hoc tests require a separate click. The default output does not include them. Tukey's HSD is the standard choice when group sizes are equal. If they are not equal, use Welch's ANOVA option instead, which SPSS provides in the same dialog under Options. The regular F-test assumes equal variances, and violating that assumption inflates Type I error rates. Regression analysis goes under Analyze > Regression > Linear. Put your outcome in the Dependent field and your predictors in the Independent(s) box. The output includes coefficient tables, R-squared values, and diagnostic statistics. The coefficients table is where most people stop reading. The model summary and ANOVA table matter too. The ANOVA table tells you whether the model explains a statistically significant portion of variance at all. The coefficients table tells you the direction and magnitude of each predictor's effect.
Interpreting Output Correctly
The p-value in SPSS output is labeled Sig. A value below .05 means the result is statistically significant at the conventional threshold. This does not mean the finding is important. It means the observed effect is unlikely under the null hypothesis. A large sample size can make trivial effects statistically significant. A small sample size can make meaningful effects non-significant. Your sample is always part of the interpretation. Cohen's d is not calculated by default in SPSS. You have to compute it manually or use a conversion formula. For an independent t-test, Cohen's d equals the mean difference divided by the pooled standard deviation. Effect sizes matter more than p-values for understanding practical significance, and SPSS hiding this calculation is one reason people skip it entirely.
My Experience With Weighted Cases
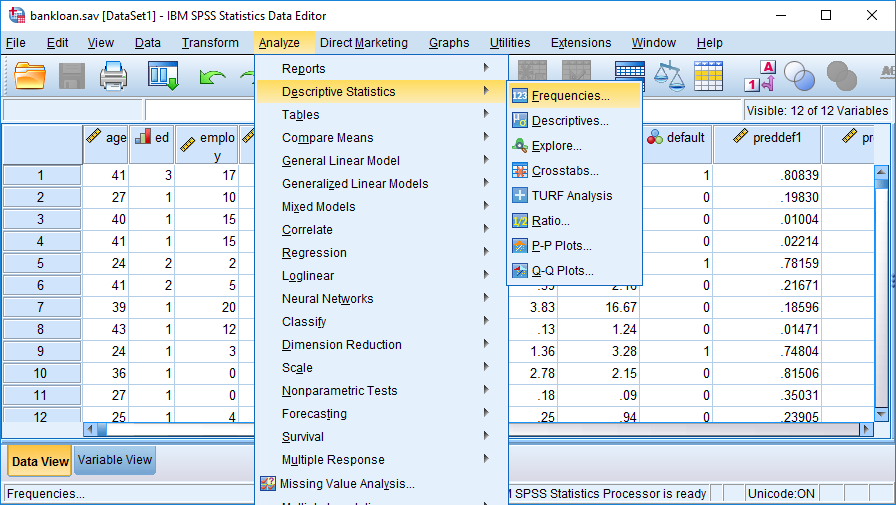
I spent approximately six hours debugging an issue in 2019 that turned out to be a weighting problem. I had applied a weight variable using Data > Weight Cases to account for survey sampling design. The analysis ran correctly on the first dataset I tested. On the second dataset, the results were wrong. The issue was that I had forgotten to turn off weighting between datasets. SPSS continues applying the weight to every subsequent analysis until you explicitly disable it. The output does not warn you. The weight variable just sits there silently distorting everything. Now I always check the status bar at the bottom of the Data Editor. It displays "Weighted by [variable name]" when a weight is active and "Unweighted Cases" when it is not. Five seconds to check. Six hours I wasted not checking. Missing data is the first problem. SPSS treats system-missing values differently from user-defined missing values. If you code missing responses as 99 or -1 without declaring them in Variable View, SPSS includes them in calculations. A mean of 5.2 might actually be 5.2 based on valid responses, or it might be dragged downward by fifty 99s. Declare your missing values before analysis. Analyze > Descriptive Statistics > Frequencies will show you the N for each variable and flag unexpected responses. Outliers distort everything. Box plots under Explore will show them. I usually run Descriptives with the Export option to see z-scores. Any value beyond |3.5| is worth investigating. You can cap outliers through recoding or exclude them, but document whatever you do. Removing outliers without documentation is a reproducibility problem.

Levene's test for equality of variances appears in t-test output. If the p-value is below .05, the variances are significantly different and you should read the "Equal variances not assumed" row, not the first row. Most people read the first row by habit. The difference between the two rows can change a non-significant result into a significant one, or vice versa.
Using Syntax Instead of Point-and-Click
Point-and-click works for one-off analyses. Syntax is necessary when you run the same procedure on twenty datasets or need to reproduce your work exactly. Every dialog action can be converted to syntax. Click Paste in any dialog box and SPSS generates the command. The syntax window shows you the exact structure. It also runs faster than repeated menu navigation. A typical syntax block for a t-test looks like this: T-TEST GROUPS=gender(1 2)
/VARIABLES=scores
/CRITERIA=CI(.95).
Adding BOOTSTRAP=1000 to that command gives you bias-corrected confidence intervals without extra clicking. The command takes about two seconds longer to execute than the standard test, and the results are more reliable for non-normal data.
When SPSS Is the Wrong Tool
SPSS handles regression, ANOVA, factor analysis, and basic clustering well. It does not handle multilevel modeling efficiently. The Mixed Models module exists but requires a separate license add-on. For hierarchical data, R with lme4 or Python with statsmodels is faster and more flexible. SPSS also struggles with large datasets. Files above 2 gigabytes slow down considerably, and some procedures will not run at all past a certain row count. If you are working with more than 500,000 records regularly, consider switching to a database-backed workflow instead. Bayesian statistics are essentially unavailable in SPSS. The software does not support MCMC sampling or posterior distribution estimation. If your research requires Bayesian analysis, SPSS is not the right choice regardless of how comfortable you are with its interface.
Getting SPSS
IBM offers a 30-day trial at ibm.com/products/spss-statistics/trial. Academic licenses are available through most universities, typically at reduced cost or free for students and faculty. The standard edition covers most needs. The Professional edition adds advanced modules like bootstrapping, complex samples, and bayesian analysis, but those modules exist as separate installable components even in the standard version—you just need the additional licenses. Evaluation copies are legitimate for learning. Full licenses are required for published work. Always save your syntax alongside your data files. The .sav output from the Viewer is not a record of what you did. It is a snapshot of results that may not reproduce if you update your data. The syntax file is the actual record. I keep a dated folder for every project with raw data, cleaned data, syntax, and output all in one place. It takes ten minutes per project and prevents three-hour searches later. Run Descriptives on every continuous variable before any inferential test. Skewness and kurtosis values outside the range of -2 to +2 suggest non-normality. Sample sizes above 100 per group tend to be robust to mild violations, but smaller samples require transformation or non-parametric alternatives. Mann-Whitney U replaces the independent t-test. Wilcoxon signed-rank replaces the paired t-test. Kruskal-Wallis replaces one-way ANOVA. These tests are in the same Analyze menus, just one sub-menu down.
SPSS is not the fastest statistical tool available. It is not the most flexible either. It is the tool that most social science departments require because the interface is accessible and the documentation is extensive. If you are learning statistics, it is a reasonable starting point. If you are doing advanced methodological work, plan to supplement it with something else eventually.


