Getting Past the Point-and-Click Wall
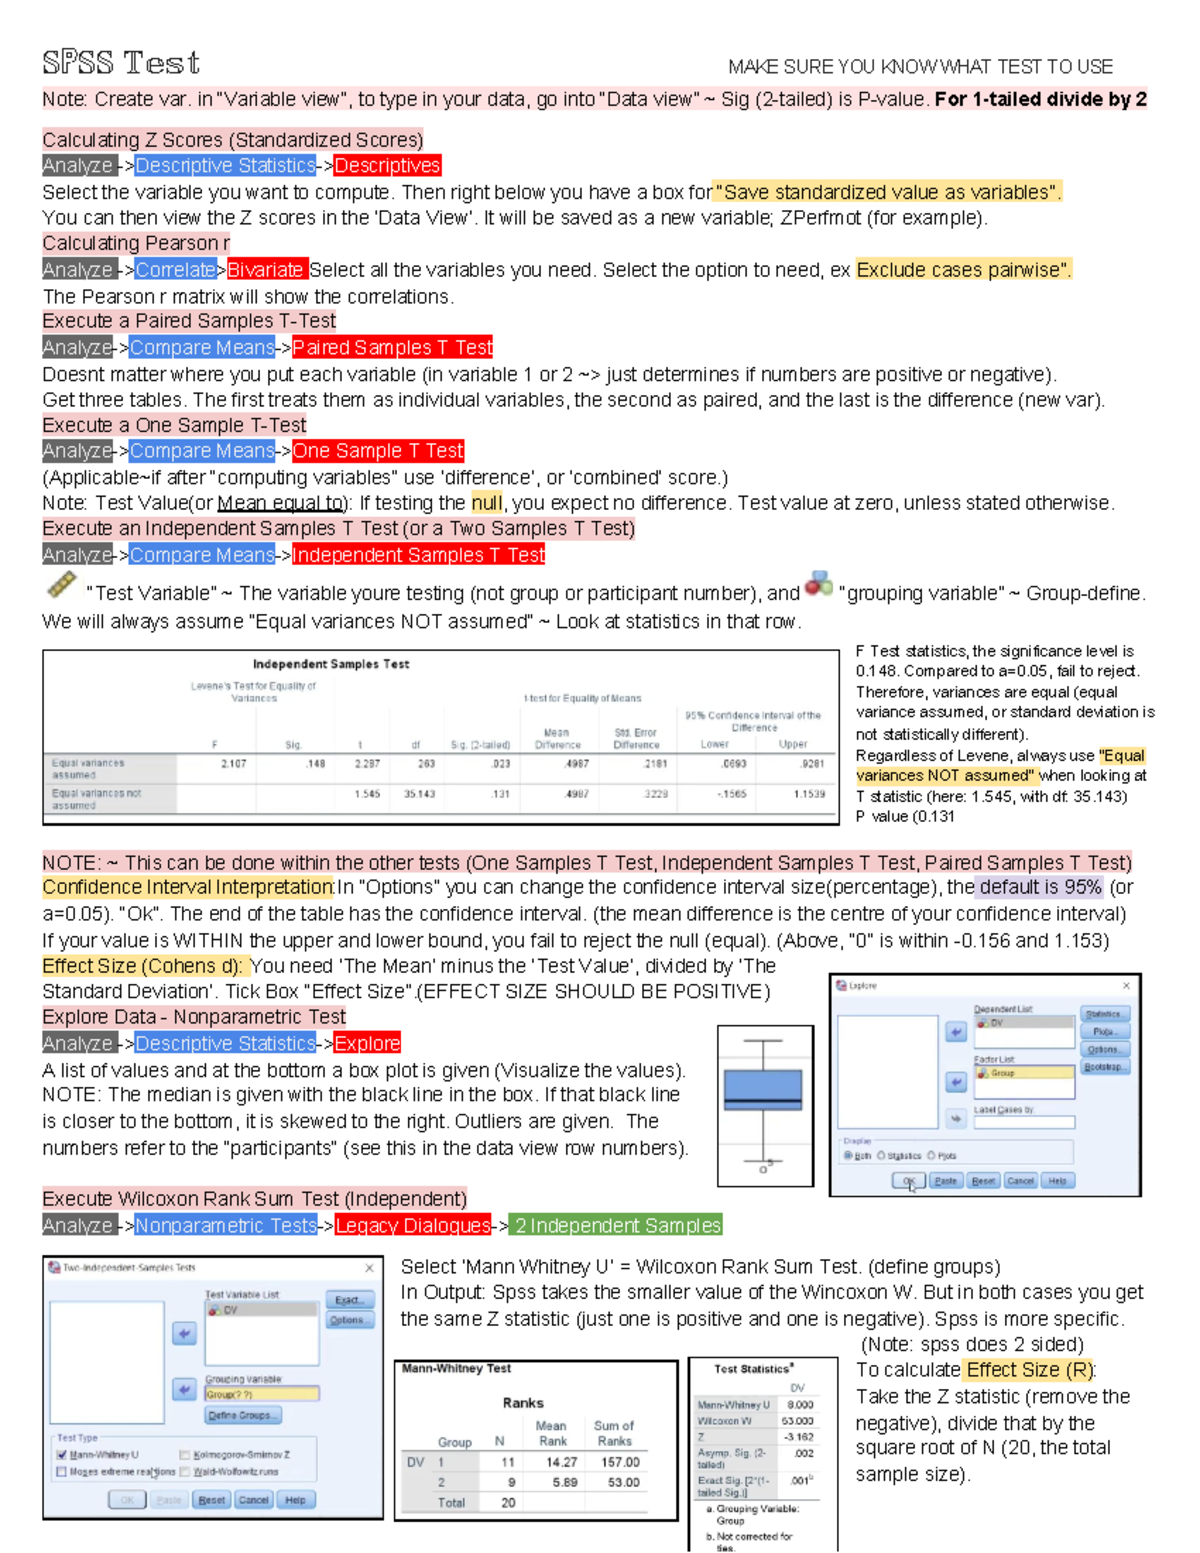
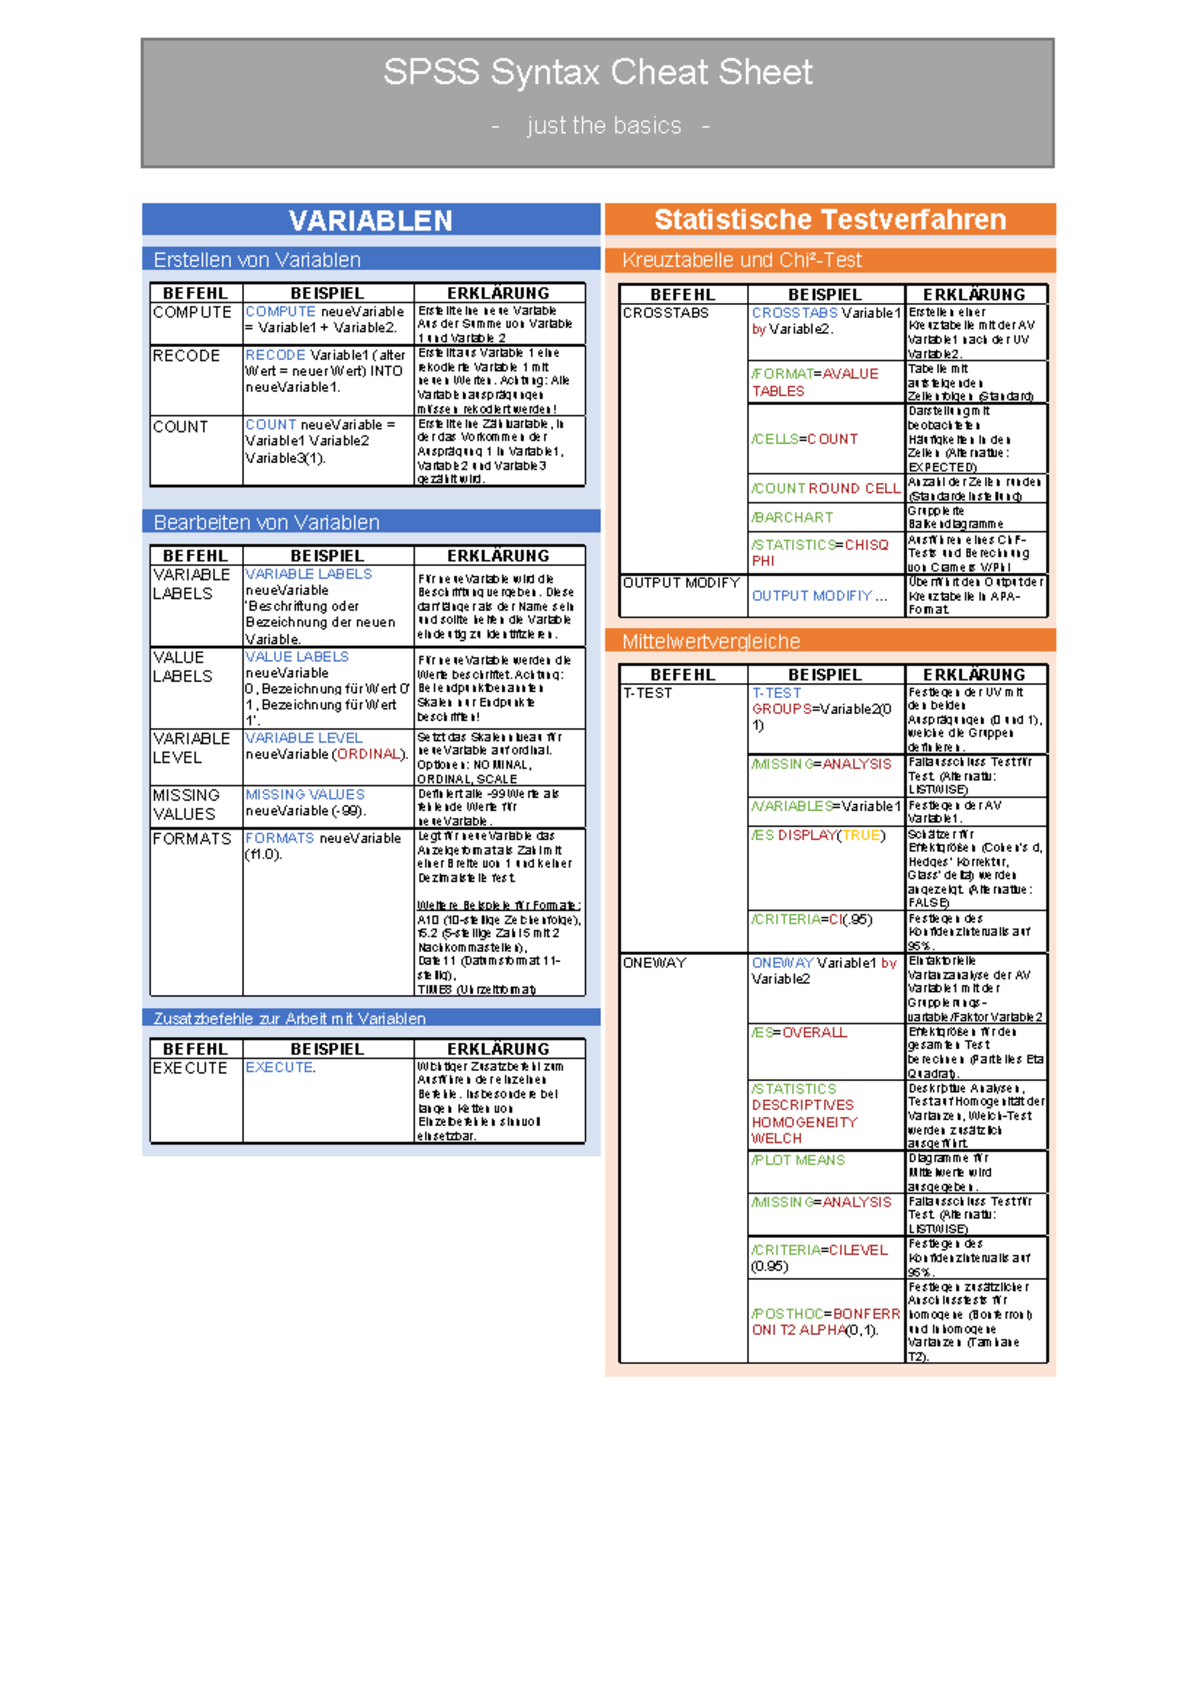
Most people who end up writing SPSS syntax never set out to become programmers. They click through menus for six months, run the same five procedures, and then hit a wall where the GUI simply cannot do what they need. That wall usually arrives when you have to repeat an analysis across 47 different variable subsets, or when a complex conditional recode requires a loop. I learned this around 2014 on a project where I needed to recode 120 survey items based on region, response pattern, and skip logic. The menu system would have taken me three days of laborious clicking. The syntax did it in about forty minutes. A Spss Syntax Cheat Sheet is not a textbook. It is a quick reference for the commands, keywords, and structural patterns you actually use day to day. Below is something close to one, organized by what you will reach for first.
Essential Commands You Will Use Constantly
Data and file management: GET FILE='C:\data\study02.sav'. SAVE OUTFILE='C:\data\study02_cleaned.sav'.
DATA LIST FILE='raw.txt' /id 1-4 age 6-8 gender 10. These three lines handle the two moments where you are most likely to get stuck early on: loading a dataset and writing it back out. Note that GET FILE is deprecated in newer SPSS versions in favor of the FILE HANDLE approach, but it still works in every version people actively use. If your file paths contain spaces or special characters, wrap them in single quotes and use forward slashes even on Windows. Variable labeling and measurement levels:
VARIABLE LABELS q1 'Overall satisfaction' q2 'Ease of use'.
VALUE LABELS gender 1 'Male' 2 'Female' 9 'Missing'.
Variable Level age (Scale) gender (Nominal) education (Ordinal). This is where the GUI hides things from you. You can run perfectly valid analyses and get garbage output if your variable measurement levels are wrong. Nominal versus ordinal matters for some procedures but not others, which is a common source of confusion. Always set these explicitly at the top of your syntax, before any analysis. Filtering and case selection:
Get the Full Details

SELECT IF (age GE 18 AND gender EQ 1).
IF (response NE 9) KEEP. SELECT IF permanently removes cases from your active dataset. Use FILTER IF instead when you want to exclude cases from output without deleting them. I have seen people use SELECT IF when they meant FILTER IF and then spend two hours wondering why half their sample disappeared from the working file. The difference sounds semantic but it matters a lot when you are building a reusable workflow. Creating and recoding variables:
COMPUTE newvar = SUM(item1, item2, item3).
RECODE age (20 THRU 35=1) (36 THRU 50=2) (ELSE=9) INTO age_group.
IF (income LT 0) income = SYSMIS. The RECODE command alone has more syntax variations than most users ever learn. The range syntax (THRU) is useful but easy to mess up when your cutoff values overlap or when you have missing values scattered through the data. I once spent an afternoon debugging a recode where a group of respondents with blank income values were being silently assigned to a numeric category instead of staying missing. The fix was adding (SYSMIS=SYSMIS) to the RECODE statement explicitly, which tells SPSS to preserve missing values through the operation rather than trying to force them into a category. Aggregation:
AGGREGATE
/OUTFILE=* MODE=ADDVARIABLES
/BREAK=id
mean_score=MEAN(q1 TO q10). AGGREGATE is one of the most powerful commands in SPSS and also one of the least understood. The MODE=ADDVARIABLES option keeps your original records and just attaches the aggregate values to each row. Use MODE=BREAK without OUTFILE to collapse the dataset entirely. Use MODE=ADDVARIABLES with BREAK when you need group-level means or sums alongside individual-level data, which comes up constantly in multilevel work.
Statistical Procedures
Descriptives and frequencies: DESCRIPTIVES variables=q1 TO q10 /STATISTICS=MEAN STDDEV MIN MAX. FREQUENCIES VARIABLES=q1 TO q10
/ORDER=ANALYSIS.

DESCRIPTIVES is faster when you just need summary numbers. FREQUENCIES gives you tables and charts but runs slower on large datasets. If you are running frequencies on 500 variables, your machine will chew on it. Use CHART=BAR for quick visual checks without waiting for full histogram computation. Cross-tabs: CROSSTABS /TABLES=q1 BY gender
/CELLS=COUNT COLUMN.
Always specify what cell values you want. The default output from CROSSTABS includes counts but often not the percentages you actually need. COLUMN gives you column percentages, which is what you want when comparing response distributions across groups. ROW gives row percentages, which is backwards for most comparisons researchers make. I have corrected this mistake on more manuscripts than I want to admit. T-tests: T-TEST GROUPS=gender(1 2)
/VARIABLES=score
/CRITERIA=CI(.95).
The GROUPS subcommand requires you to list the actual numeric codes used in your data. This is a very common error point. If your gender variable uses 1 and 2, you write (1 2). If you write (Male Female) it will fail with a type mismatch. Also check Levene's test before trusting the t-value. SPSS gives you both the equal-variances-assumed and equal-variances-not-assumed rows. Pick the right one or your p-value is wrong. ANOVA: ONEWAY score BY treatment
/STATISTICS DESCRIPTIVE HOMOGENEITY
/MISSING ANALYSIS.
Add the /MISSING ANALYSIS option. Without it, SPSS uses listwise deletion by default, which silently drops any case with a missing value on any variable in the procedure. If your dataset has even modest missingness, your effective sample size can drop dramatically and you will not see it in the output unless you check the N values carefully. /MISSING ANALYSIS switches to pairwise deletion for the omnibus test, which is usually what you actually want. Regression: REGRESSION
/DEPENDENT outcome
/METHOD=ENTER pred1 pred2 pred3
/STATISTICS COEFFICIENTS R ANOVA
/SAVE PRED(reshaped_pred).

The /SAVE PRED option writes predicted values back into your dataset, which is necessary if you want to compute residuals or validate the model afterward. The METHOD=ENTER subcommand is worth spelling out explicitly rather than relying on defaults, because later methods like STEPWISE can introduce subtle overfitting issues that are hard to detect without knowing what happened.
Structural Patterns That Make Syntax Actually Work
SPSS syntax has a few structural conventions that are not obvious until you write enough of it. Every command ends with a period. The period is not optional. A missing period will cause SPSS to treat the next command as a continuation of the current one, which produces errors that are genuinely difficult to trace because the error message points to line 200 when the problem is on line 199. Indentation does not affect execution but it affects whether you can read your own code two weeks later. Use two-space indentation for subcommands. Keep related commands grouped together. Name your output: OUTPUT TITLE 'Descriptives for baseline sample'. Looping and repetition:
LOOP #i = 1 TO 10.
DO IF ($CASENUM GE #i).
COMPUTE var_#i = RV.NORMAL(0,1).
END IF.
END LOOP. Loops in SPSS are clunky compared to R or Python but they get the job done for batch processing. The #i syntax creates macro variables that you can insert into command strings. This is how you automate repetitive operations across dozens of variables without copying and pasting the same block ten times. Split file for grouped output:
SPLIT FILE BY gender.
FREQUENCIES VARIABLES=status /ORDER=ANALYSIS.
SPLIT FILE OFF. SPLIT FILE runs every subsequent procedure separately for each group. Turn it back off with SPLIT FILE OFF immediately after. I have lost output to forgotten split files more than once. You will run a procedure, look at the output, and wonder why it only shows results for one group when your data clearly has multiple groups. Check SPLIT FILE status before panicking.
Common Pitfalls and Where the Tool Breaks Down
SPSS syntax is reliable for standard statistical work but it has real limitations. It does not handle nested data structures well natively. If you are working with panel data or hierarchical models, GLM mixed procedures exist but they are slower and less transparent than running the same analysis in R or Stata. The syntax for MIXED models is verbose and the convergence diagnostics are easy to miss. I switched most of my longitudinal work to R after spending too much time fighting SPSS to produce correct standard errors for clustered data. String manipulation is another weak spot. COMSTRING, SUBSTR, and INDEX commands exist but they are primitive compared to anything in modern data languages. If your workflow involves heavy cleaning of text variables, you will wish you were somewhere else. Memory is a practical constraint. SPSS loads entire datasets into RAM. A dataset with 5 million cases and 200 variables will crush a typical workstation. There is no true out-of-core processing. If your data is that large, consider using SQL or a database-backed approach before pulling it into SPSS at all.
Another thing people miss: the difference between system-missing and user-missing values. SPSS allows you to define custom missing values with the MISSING VALUES command. A value like 999 can be declared missing, which excludes it from means and counts. But if you forget to declare it, SPSS treats it as a real data point and your averages will be wrong. I once had a client who thought they had clean data and we spent an hour tracking down a systematic bias that turned out to be undeclared coded-missing values in three key variables.
How to Build Your Own Working Cheat Sheet
The best reference is not a downloaded PDF. It is a living document built from the commands you actually use. Start by saving the syntax you write for every project in a organized folder. When you hit the same problem twice, add the solution to your personal reference. Over six months this accumulates into something far more useful than any generic cheat sheet you will find online. Bookmark these built-in resources: the Online Help system under Syntax Reference is accurate and searchable. The Commands Index lists every command with its full syntax. When you need to know the exact keyword order for AGGREGATE or the available STATISTICS options for a given procedure, the help system is faster than any third-party document. If you want a downloadable reference, search for the official IBM SPSS Statistics Commands reference documentation. It is comprehensive and freely available from IBM's website. It is not a cheat sheet in the traditional sense but it is the authoritative source when you need to verify exact syntax. Third-party cheat sheets circulate widely but they are often outdated for newer SPSS versions, especially around the syntax changes introduced after version 25.
The most practical takeaway is to treat syntax as a workflow tool, not a memorization exercise. You do not need to know every command by heart. You need to know the structural patterns, understand when the GUI is limiting you, and have a reference you can drop into when you are stuck. Write the syntax, run it, check the output, and iterate. That process is faster than you think once you stop fighting the interface.