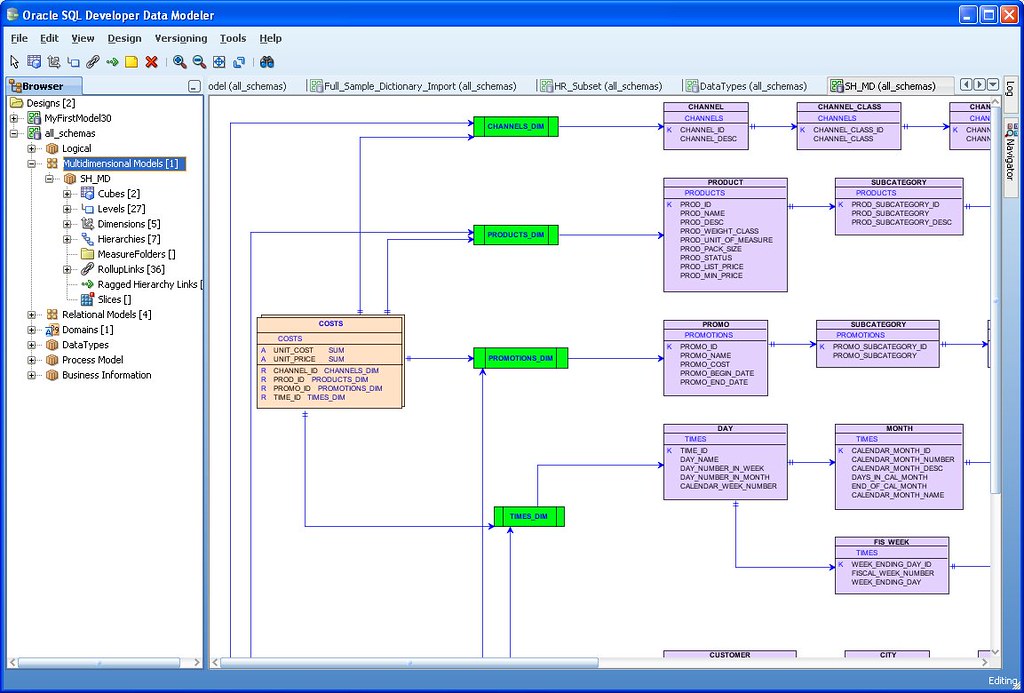
Getting Started With Visual Modeling
Sql Developer Data Modeler is Oracle's free tool for designing database schemas visually before you ever write a CREATE TABLE statement. It handles forward engineering, reverse engineering, and documentation generation all in one package. Most people encounter it when they need to model a relational schema without paying for Toad or ERwin. The download comes directly from Oracle. You can find it at oracle.com/tools/sql-developer-data-modeler.html. Just grab the latest version, install it, and you're running it. No license key, no serial number, no activation dialog. It's just there.
Sql Developer Data Modeler in Practice
I set up a project for a client last year where we needed to model a schema with roughly 80 tables, multiple inheritance hierarchies, and audit columns across everything. I imported the existing Oracle database using the reverse engineering function. It picked up most of the relationships correctly, but foreign keys defined through triggers didn't show up as model-level relationships. They showed up as comments on the table notes. I had to manually reconnect about twelve of them. The workaround was straightforward but not obvious. I opened the SQL workspace, ran a query against ALL_CONSTRAINTS joined to ALL_CONS_COLUMNS filtering by the schema owner, and then used the relationship editor to map each constraint by name rather than by column matching. Column matching alone fails when trigger-based FKs exist because the optimizer doesn't treat them the same way.
The Forward Engineering Pipeline
This is where the tool earns its keep. You design the model, then click Generate Database. It produces a script that creates tables, indexes, constraints, and sequences in the right order. For Oracle databases it handles PL/SQL objects too. For PostgreSQL or SQL Server it generates dialect-specific syntax. The key setting you need to check is under Tools > Model Options > Generation. The default generation order is usually correct: tables first, then constraints, then indexes, then triggers. But I've seen projects where dependent views or materialized views come before their base tables because someone added them in the wrong order in the diagram. The generator respects the order objects appear in the diagram canvas, not the dependency tree. Set it to sort by dependencies under the generation options and it fixes most of this.
Get the Full Details

Reverse Engineering Nuances
Reverse engineering works well for straightforward schemas. It maps tables, columns, primary keys, and standard foreign keys with reasonable accuracy. There are several known gaps though. Generated columns in MySQL don't always preserve their expression. Views get pulled in as base tables sometimes, which makes the model noisy. Synonyms get ignored unless you explicitly enable them in the reverse engineering options. The biggest gotcha is that reverse engineering does not create relationships between tables that are enforced only through application logic or stored procedures. If your team uses soft FK patterns where the constraint lives in the ORM or migration script rather than the database layer, those relationships simply won't exist in the model. You'll need to draw them manually after import. Budget extra time for that step on legacy systems.
Version Control Integration
The project file is essentially a zip archive containing XML files. You can diff them, but the output is noisy because column ordering and element sequencing change even when the logical schema hasn't. I recommend keeping the model as your source of truth and using the built-in compare feature rather than relying on git diff for schema changes. The compare tool handles additions, deletions, and modifications at the table level with useful color coding. For teams that need true schema-as-code workflows, the export to SQL option gives you a clean script. Combine that with a migration framework like Flyway or Liquibase and you get version control that actually works for schema tracking. Sql Developer Data Modeler doesn't manage migrations itself. It generates artifacts that other tools consume.
Performance Reality Check
The tool gets sluggish past roughly 150 tables on a model. Not unusable, just slow. Pan, zoom, and select operations take noticeable time. I learned this the hard way on a project with an over-engineered data warehouse model containing partitioned tables, materialized views, and summary tables all on one canvas. Opening the file took forty seconds. Editing a single column name froze the UI for about fifteen. Closing and reopening cleared it, but the freeze came back after the third edit. Split large models into separate physical and logical layers. Use the sub-model feature to break things apart. This isn't perfect but it keeps the main workspace responsive. Another option is to use the lightweight text editor mode for bulk changes instead of dragging elements around in the graphical interface.
Common Mistakes
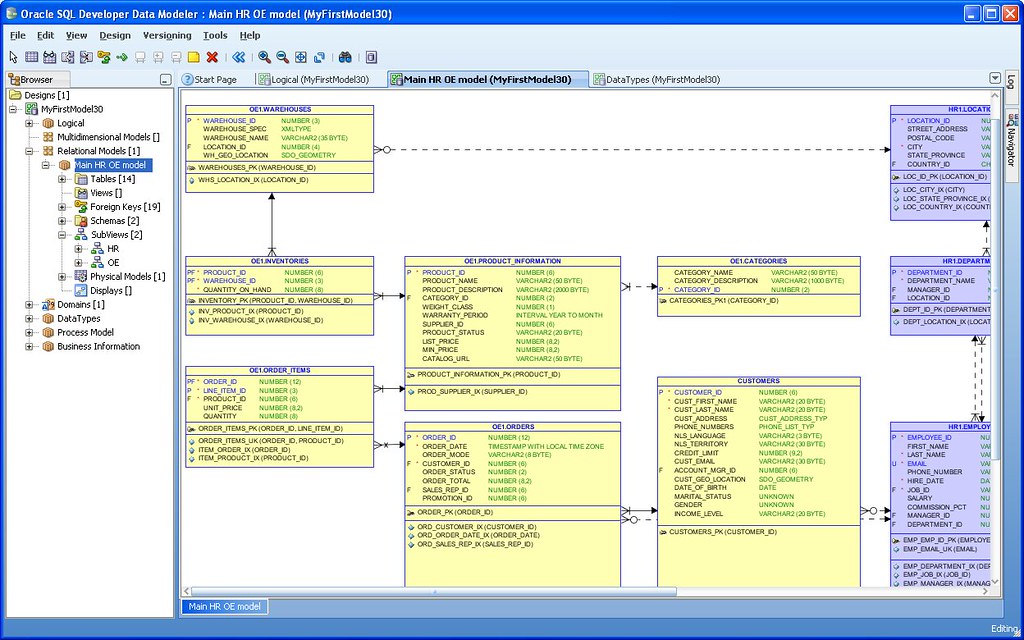
People tend to treat the tool as both a design surface and a documentation generator. It can do both, but the output quality for documentation depends heavily on how much metadata you actually populate. A table without a description, column comments, or cardinality notes produces almost useless reports. Spend the time filling in the properties pane during design. It saves hours later when someone asks for an ER diagram PDF. Another frequent issue is mixing conceptual and physical models. The tool supports both levels, and switching between them changes how constraints and data types behave. A NOT NULL constraint means something different at the conceptual level than at the physical level. I've seen models where someone promoted everything to physical too early and then couldn't reuse the same structure for a different target database. Keep the conceptual layer clean and promote only when you're ready to lock in the dialect-specific details.
When It Falls Short
If you're working primarily with NoSQL schemas, graph databases, or event-sourced architectures, this tool will frustrate you. It's built for relational modeling. There's no support for document stores, key-value pairs, or Cassandra-style wide rows. For those cases you'd be better off with something like dbdiagram.io or even just writing the schema directly in code. Similarly, if your organization requires cloud-native database design with live collaboration features, you'll want Looker Studio integrations or tools like Prisma Schema Editor instead. Sql Developer Data Modeler is desktop-only, file-based, and synchronous. Two people cannot work on the same .mdf project file at the same time without merge conflicts. We've all been there.
The Bottom Line
It's free, it's capable, and it handles most relational modeling tasks without fuss. The learning curve is shallow for basic work. The edge cases bite you eventually, but they're manageable once you know where to look. I keep it installed alongside my standard toolchain because the one-time cost of importing a legacy schema and having it produce clean DDL is worth the occasional frozen UI state.