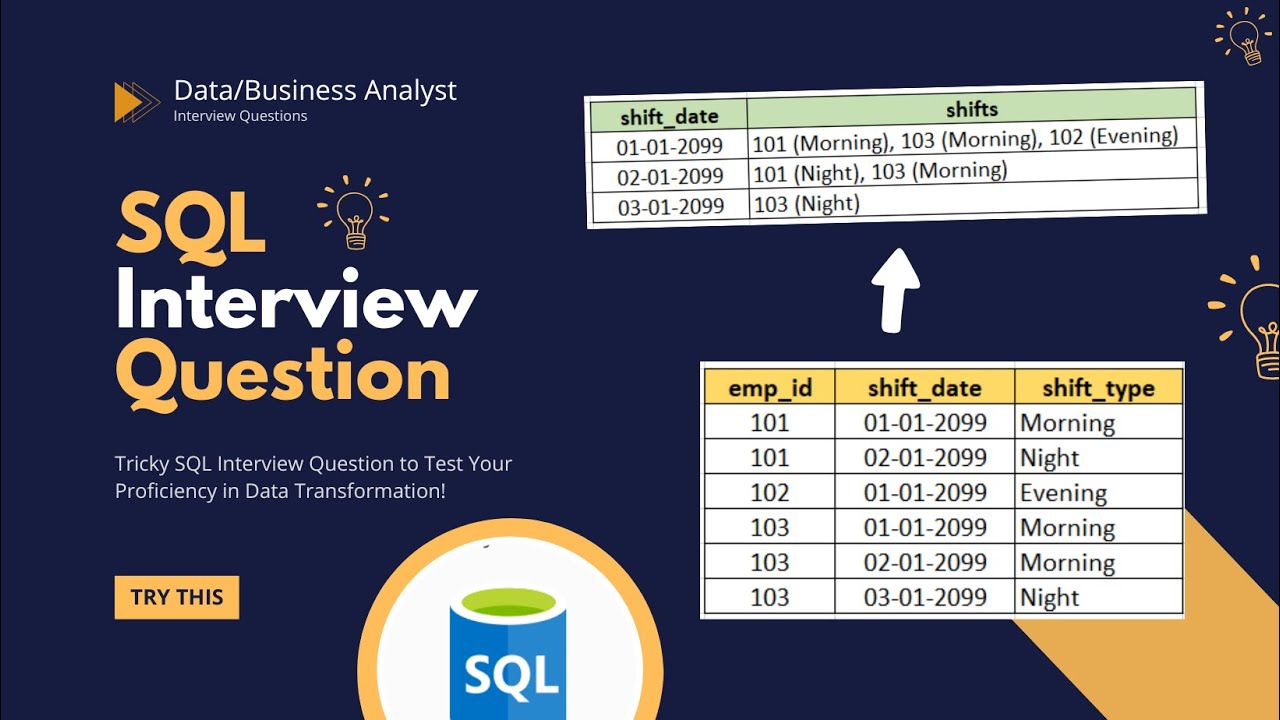
SQL is the single most important technical skill for a business analyst role. Most candidates fumble it because they've never actually worked with messy data.
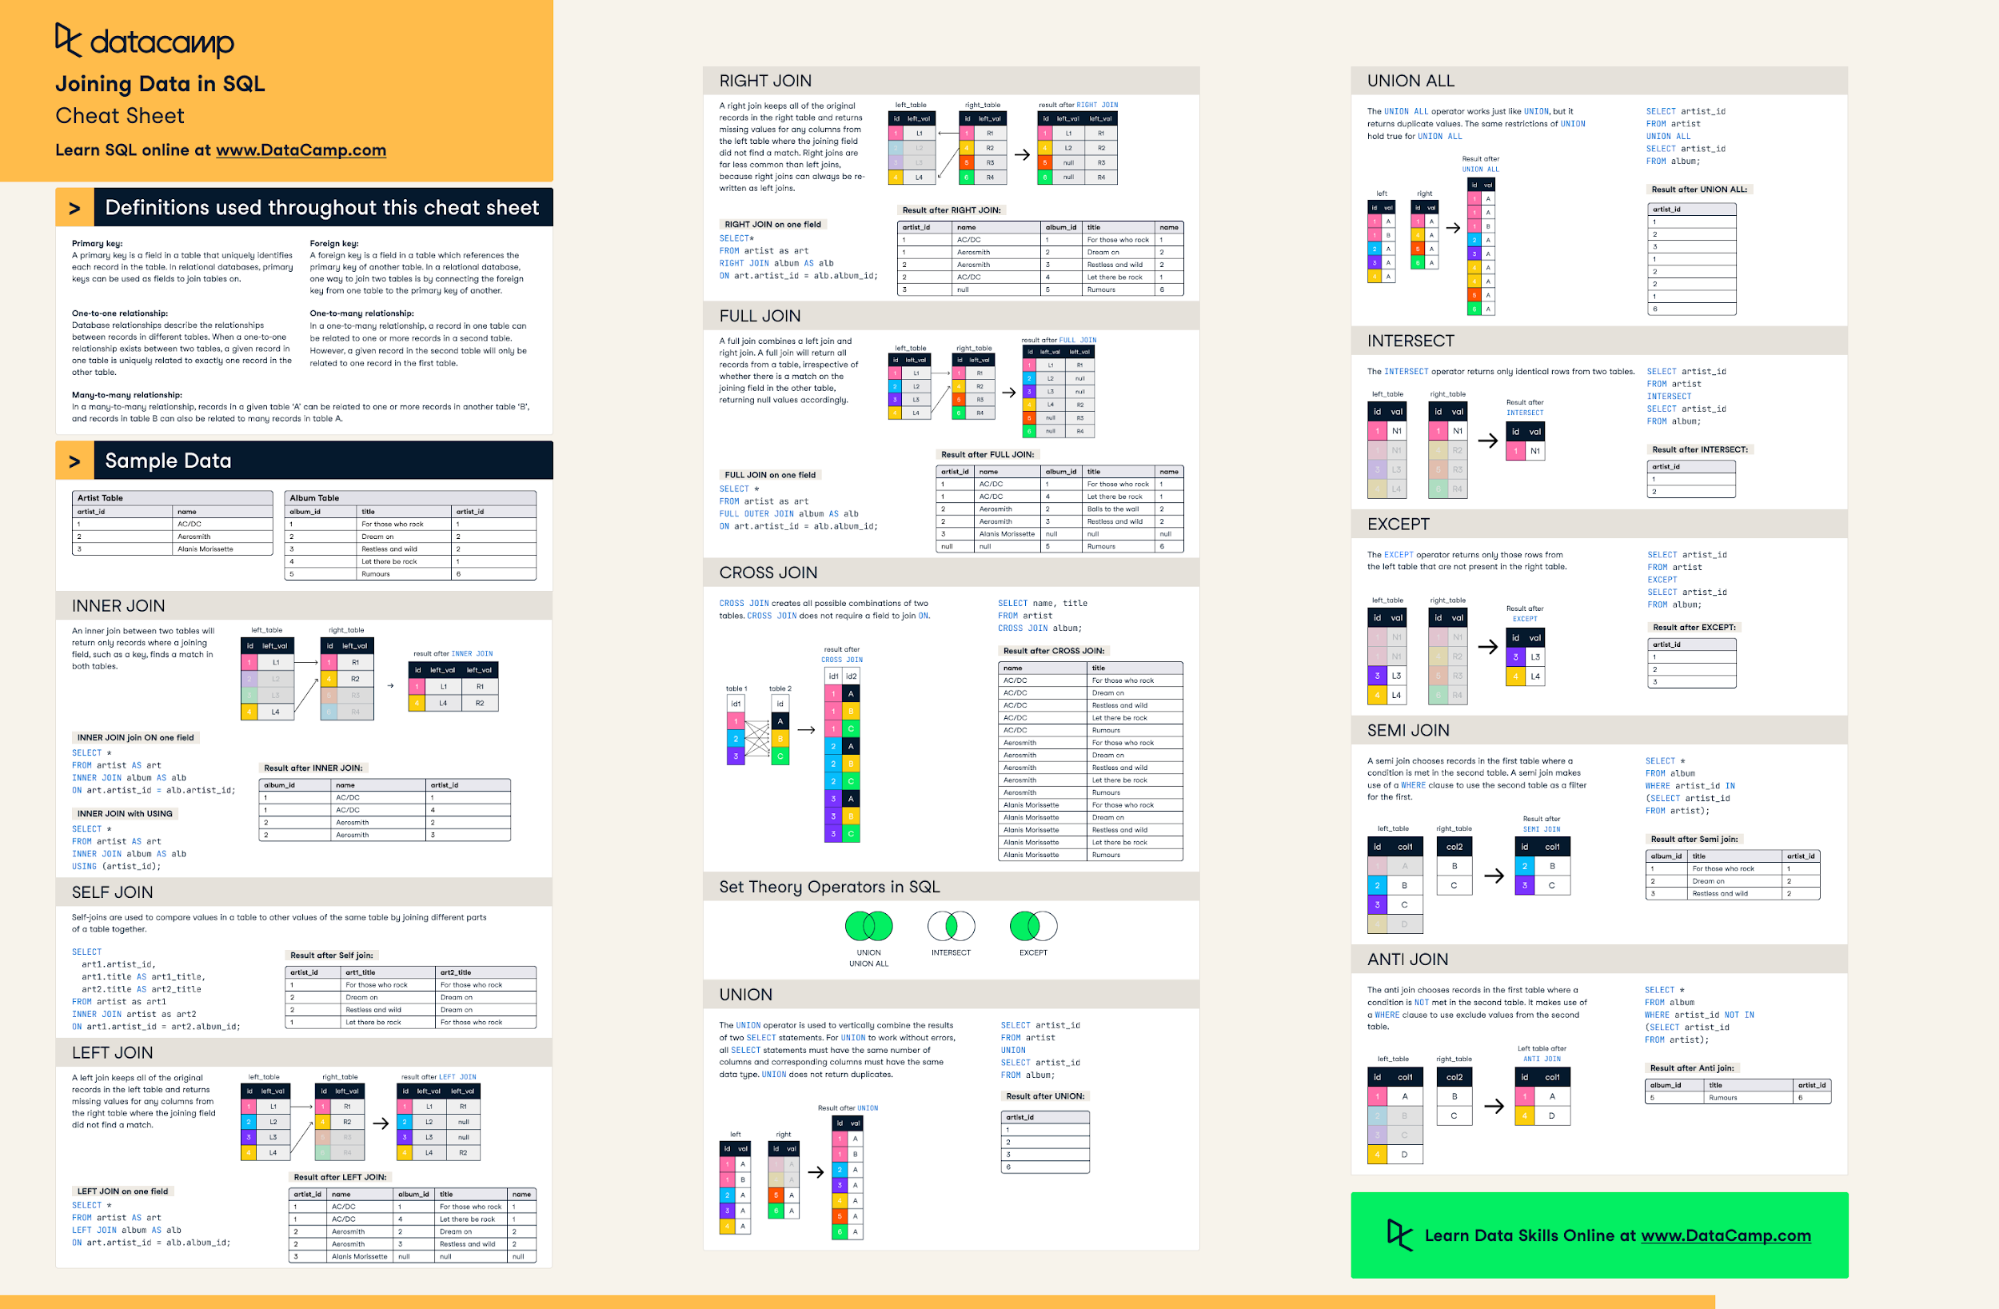
I watched a guy blank on a LEFT JOIN vs INNER JOIN question last year. He'd been doing analysis for three years but apparently never had to combine tables that didn't line up perfectly. That's the gap. Most interview prep teaches you syntax in a vacuum. Real interviews test whether you understand what happens when data doesn't cooperate. Let me walk you through the actual Sql Interview Questions For Business Analyst that come up, the ones that matter, and where people typically trip up.
Common SQL Interview Questions For Business Analyst Positions
Window functions come up constantly. Specifically ROW_NUMBER, RANK, and DENSE_RANK. They look similar. They're not interchangeable. When I interviewed someone who couldn't explain the difference between RANK and DENSE_RANK, I knew immediately they hadn't dealt with tied values in a production environment. RANK skips numbers after a tie. DENSE_RANK doesn't. That matters when you're calculating monthly revenue leaderboards and two people tie for second place. With RANK, the next person gets fourth. With DENSE_RANK, they get third. The business stakeholder will ask about that discrepancy. You need to know which one produces the answer they expect. GROUP BY with HAVING versus WHERE is another classic. WHERE filters rows before aggregation. HAVING filters after. People mix these up constantly. A typical question might ask you to find departments where average salary exceeds 75000. You'd use HAVING AVG(salary) > 75000, not WHERE. If you put it in WHERE, the query either errors or returns meaningless results depending on your SQL dialect. This comes up in interviews because it separates people who've actually written production queries from people who've only run SELECT * from their tutorial databases. CTEs versus subqueries. Modern interviews expect you to know Common Table Expressions. They're cleaner and more readable than nested subqueries, and most databases support them now. I once spent two hours debugging a query someone wrote with five levels of nested subqueries. A CTE would have made it three lines instead of thirty. In an interview, showing you can structure a complex query with CTEs signals that you write code other people can maintain. That's what hiring managers actually care about.
Self-joins are less common but they show up. A self-join is when you join a table to itself. A typical example involves an employee table with a manager_id column. You join the table on employee.id = manager.employee_id to pull both the employee name and their manager name in one query. I remember a client who needed a report showing every product category alongside its parent category. The schema had a single categories table with a parent_id column referencing itself. A self-join solved it in minutes. Without that knowledge, someone would have tried multiple queries or worse, done it in application code.
Get the Full Details
What Interviewers Actually Want to See
They want you to think out loud. I've seen candidates nail every technical detail and still not get the job because they stayed silent for five minutes while staring at a whiteboard. Speaking your thought process matters more than getting the perfect answer immediately. Start by restating the problem. Ask clarifying questions about the schema. Mention edge cases before you write a single line of code. Tell me what happens if the date field is null. What if there are duplicate customer IDs. Those questions alone often separate the analysts who ship production code from the ones who don't. Performance awareness is another filter. Write a query that returns all orders from the last six months joined with customer data and product data across three tables. Most people write a straightforward query. The follow-up question is always the same: this query is slow. How do you make it faster. The answer involves examining the execution plan, checking for missing indexes on the join and filter columns, and considering whether you actually need all those columns. Often the real issue is that someone wrote SELECT * and pulled millions of unnecessary rows. Filtering earlier, using covering indexes, and avoiding functions on indexed columns in WHERE clauses usually moves the needle. I had a report that took fourteen minutes running a query with a LIKE '%text%' pattern on a five-million-row table. We replaced it with a full-text search index and it dropped to under three seconds. The interview question is theoretical but the thinking behind it is practical. Data type knowledge separates the juniors from the seniors. TIMESTAMP versus DATE, VARCHAR versus NVARCHAR, INT versus BIGINT. These aren't trivia. They affect query performance, storage costs, and correctness. A candidate who knows that comparing a VARCHAR column to a numeric value causes implicit conversion and kills index usage has learned something most bootcamp graduates miss. I once found a bug where a date comparison was returning wrong results because the column was stored as VARCHAR and the format was MM/DD/YYYY instead of YYYY-MM-DD. Lexicographic sorting broke the entire query. The fix was converting the column to DATE at the source, but by then we'd lost three months of historical accuracy on that metric.
Practical Setup Questions
Some interviews give you a schema and ask you to write queries from scratch. A typical setup might involve tables like customers, orders, order_items, and products. From there they'll ask things like calculate the monthly repeat purchase rate. This requires joining orders to itself on customer_id and checking whether the same customer appears in consecutive months. A PARTITION BY clause inside a window function or a simple self-join with date comparison gets you there. The trick is defining what "repeat purchase" means clearly before coding. Does it mean any purchase within thirty days? Within the same calendar month? Buying the same product again? I've seen teams build entire dashboards on ambiguous definitions and then spend weeks arguing about whose numbers were right. Another standard question involves calculating running totals or moving averages. You can do this with a subquery correlating on date, but a window function with ORDER BY and a frame clause is cleaner and faster. SUM() OVER (ORDER BY date ROWS UNBOUNDED PRECEDING) gives you a cumulative total. The frame specification matters. If you omit ROWS UNBOUNDED PRECEDING, some databases default to RANGE which includes all rows with the same value in the ORDER BY column, producing incorrect results when dates repeat. I learned this the hard way on a daily sales dashboard where the cumulative column showed wrong values on holidays that shared the same date across different store locations. The fix was explicit ROWS framing, not RANGE.
When SQL Isn't the Answer
Here's something most prep guides won't tell you. Sometimes the interview question is designed to see if you'll reach for SQL when you shouldn't. "How do you merge two datasets in Excel?" or "How would you handle this transformation in Python?" The correct answer depends on the context. If you're working with a dataset that's already in a database, SQL is usually right. If you're doing iterative prototyping with a small dataset that doesn't fit in memory, or if the transformation involves complex string manipulation that's painful in SQL, a programming language might be the better call. I once had a candidate who wrote an elaborate SQL query to parse JSON data from a web API response. When I asked why they didn't use Python's json module, they couldn't answer. SQL isn't a universal solution. Knowing its limits is part of being hireable. Similarly, some questions test whether you understand the business context behind the technical request. "Find the top ten customers by revenue." Simple on the surface. But which revenue? Gross or net? Including or excluding returns? Per order or per invoice? Over what time window? I've seen senior analysts get stuck on a basic aggregation question because they never considered whether the interviewer wanted trailing twelve months or calendar year data. Always clarify the business definition before optimizing the query.

Preparation Strategy That Actually Works
Most people drill LeetCode-style problems. That helps with syntax but misses the analyst-specific stuff. You need practice with messy real-world schemas. Grab a public dataset like the Northwind database or Kaggle's e-commerce data and write queries that answer actual business questions. Calculate customer lifetime value. Identify churn risk patterns. Build a cohort retention table. These exercises force you to handle NULLs, duplicate keys, and irregular time periods, which is what real work looks like. Also practice explaining your queries in plain English. I've had analysts write correct SQL but fail to articulate what it does when asked. If someone who doesn't know SQL can't understand your query explanation, you're not ready for a BA role. The goal isn't to impress with complexity. It's to show you can translate business questions into data answers reliably. Finally, review EXPLAIN plans. Most interviews won't ask you to actually run one, but mentioning that you'd check the execution plan when a query performs poorly shows experience. Understanding whether the database is doing a sequential scan or using an index, whether it's hashing or sorting a join, these details separate people who write queries from people who write queries that scale. I spent a quarter optimizing a report that hit a memory limit because the intermediate result set from a GROUP BY was larger than available RAM. Switching to a streaming aggregation approach and adding a temporal filter first brought it down to under two minutes. Same logic, completely different execution path.