Why Most SQL Data Projects Fail Before They Start
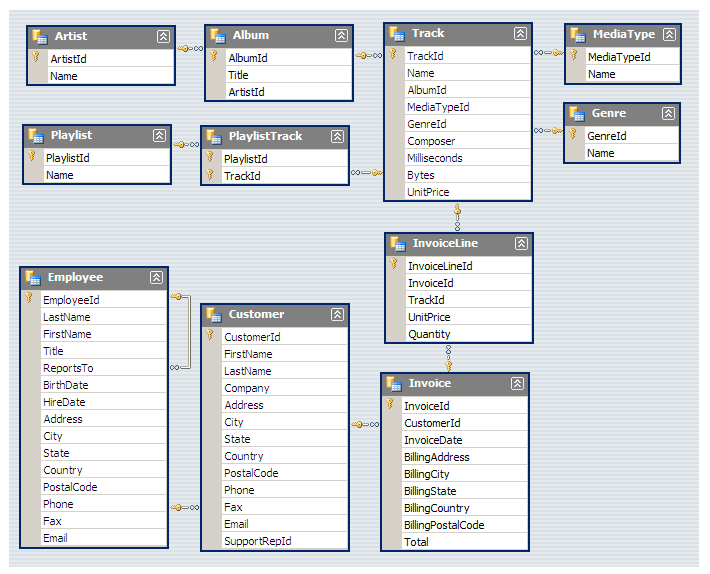
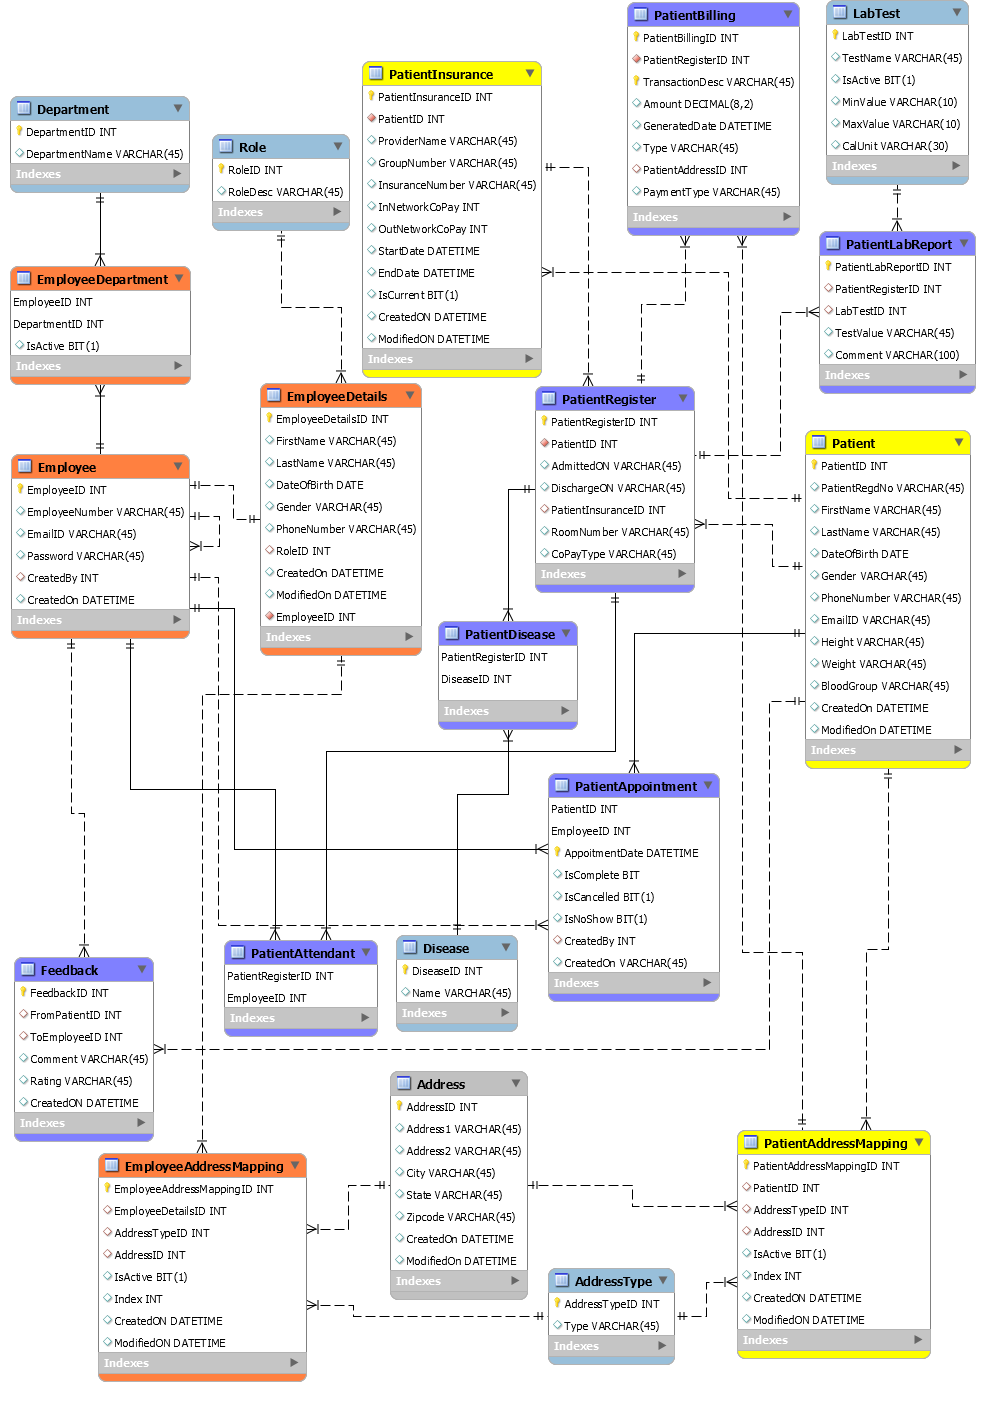
The biggest mistake I see is people treating SQL like a programming language when it's actually a querying language. It doesn't matter how elegant your JOIN looks if the query planner decides to do a nested loop over two million rows because you didn't have the right index. I spent three weeks building a data analysis pipeline last year only to realize my CTEs were being re-evaluated on every reference instead of cached, which turned a 40-second query into a 12-minute one. The fix was wrapping those CTEs in a temporary table so Postgres would physically materialize the intermediate result. That one change dropped the execution time to under two seconds. Let me walk through what these projects actually look like and how they're structured in practice, not some idealized tutorial version. A proper SQL data analysis project starts with understanding your source data schema. This sounds obvious but it's where most people skip ahead and start writing queries they don't actually need. Pull the table definitions first. Check the data types. Run a quick SELECT DISTINCT column_name FROM table LIMIT 20 on the key columns before you commit to any analysis path. I once built an entire customer segmentation model on a column labeled customer_id only to discover it was a VARCHAR containing mixed numeric and alphanumeric strings because the sales team had been pasting external partner IDs into the field. The segmentation was wrong from line one and I'd already written 400 lines of code.
Start each project by answering three questions: What grain is the data at? What are the known missing data patterns? What's the expected volume? Once you know those, you can pick the right approach. If you're working with millions of rows and need aggregations across multiple time periods, window functions are your default tool. ROW_NUMBER(), RANK(), LAG(), LEAD() — these are workhorses, not fancy features. Beginners tend to reach for subqueries when a window function would be 10x faster and much more readable. Here's a practical example that comes up constantly. You have a sales table with transactions, and you need month-over-month growth rates by product category. The naive approach writes a self-join on date truncation. The right approach uses LAG(): SELECT
product_category,
transaction_month,
total_sales,
ROUND((total_sales - LAG(total_sales) OVER (PARTITION BY product_category ORDER BY transaction_month)) / LAG(total_sales) OVER (PARTITION BY product_category ORDER BY transaction_month) * 100, 2) AS mom_growth_pct
FROM (
SELECT
product_category,
DATE_TRUNC('month', transaction_date) AS transaction_month,
SUM(amount) AS total_sales
FROM sales
GROUP BY 1, 2
) monthly_sales;
This runs in the time it takes to scan the table once, not twice. The self-join version scans it twice and creates a massive intermediate result set. On a dataset with 50 million rows and 200 product categories, I've seen the difference between 8 seconds and 6 minutes.
Get the Full Details
Common Project Types and What to Watch For
Customer cohort analysis is probably the most common first project. You group users by their signup month and track their behavior over subsequent months. The trick isn't the grouping, it's handling inactive users who drop off. A simple COUNT(*) in each cohort column will show zeros for months where no activity occurred, which is correct, but you also need to make sure you're counting distinct customers, not transactions, or your retention numbers will look artificially high. I've seen this mistake in production dashboards where the churn rate appeared to improve because someone switched from counting transactions to counting events without adjusting the metric definition. Funnel analysis projects expose a lot of similar issues. You track how many users move from one step to the next. The standard approach uses conditional aggregation with CASE WHEN statements, which works fine for simple funnels. But when you have more than five steps or you need to handle users returning to earlier steps, the query gets unwieldy fast. A better approach for complex funnels is to use a recursive CTE that maps each user's path through the funnel, then aggregate the path lengths. This is noticeably slower to write but scales much better when the funnel definition changes, which it always does. Revenue recognition projects are where SQL gets messy because real business data is messy. You'll encounter orders with partial refunds, credits that span billing periods, and the occasional corrupted date field that's formatted as "Jan 15, 2023" instead of a proper DATE type. I had a project where roughly 0.3% of records had dates stored as strings in six different formats within the same column. The query that was supposed to aggregate monthly revenue failed silently for an entire quarter because the DATE_TRUNC function couldn't cast those mixed formats. I ended up writing a custom parsing function using CASE WHEN with multiple TO_DATE patterns and a fallback to NULLIF for truly unparseable values. The project took twice as long as estimated because of that one data quality issue.
Query Performance Is Not Optional
You can write correct queries that are unusably slow. This happens constantly. The query planner in modern databases like PostgreSQL and BigQuery is smart, but it's not a mind reader. When you write a query with multiple aggregations across joined tables, the planner will often choose the worst join order if you haven't given it hints or statistics are stale. Run EXPLAIN ANALYZE on every non-trivial query. It takes about 30 seconds and will show you exactly where the bottleneck is. I've found that simply adding LIMIT to an exploratory query to check intermediate results is the fastest way to catch a cartesian product before it processes millions of rows and times out. Partitioning matters more than most people think. If you're querying a table that's 500GB but your analysis only needs the last 90 days of data, make sure your WHERE clause references the partition column first in the predicate. A query that filters on a non-partition column first will do a full table scan regardless of how well-indexed that column is. This is one of those things that's documented everywhere but consistently ignored by people focused on getting the answer rather than the mechanism.
Tools and Where to Actually Run This Stuff
For local development, Docker running PostgreSQL is the standard. It's free, it's realistic, and it matches production setups closely enough that you won't be surprised by differences when you deploy. The official Postgres image on Docker Hub is straightforward, and you can mount a local directory for your data files so nothing gets lost if the container restarts. Set up a docker-compose.yml with the database and pgAdmin if you want a GUI, though I find the command line faster once you know your way around psql. For cloud-based projects, most people use BigQuery, Snowflake, or Redshift. BigQuery is the easiest to start with because there's no infrastructure to manage. You upload a CSV to a bucket, create a table, and query it. The free tier gives you 1TB of query processing per month, which is plenty for learning. Snowflake has a similar setup with a 30-day free trial. Redshift is more complex but closer to what you'd encounter in an enterprise environment. One tool worth mentioning specifically is psql with the \timing command enabled. It shows execution time for every query, which trains you to think about performance instinctively rather than treating it as an afterthought. After a few weeks of using it, you'll start estimating query runtimes in your head before you even submit the query.
There's no single download link for SQL projects because the work is in the data and the queries, not in installing software. What you download is the database engine, some sample datasets, and your own queries. Public datasets are available from sources like the UCI Machine Learning Repository, Kaggle, and government open data portals. Google's public datasets on BigQuery cover everything from GitHub commits to climate data and are free to query within reasonable limits. Those are useful because they're large enough to expose you to real performance issues without costing anything.
What These Projects Don't Cover and Why It Matters
Most tutorials stop at basic aggregation and JOIN operations. Real data analysis work involves things they don't teach you about. Data validation is one. Before you trust any number coming out of a query, you need a set of checks that verify the data makes sense. Total rows should match expectations. Distributions should be stable. Cross-references between tables should reconcile. I build validation queries into every project as a separate schema with tables named _validation_checks. It adds maybe 15% to the development time but catches issues that would otherwise surface weeks later when someone is presenting results to a stakeholder. Another thing tutorials skip is version control for SQL. People treat database queries as throwaway scripts and rewrite them constantly. I keep every project in a Git repository with separate files for raw queries, transformed views, and final output queries. The files are named chronologically with dates, so there's a clear history of how the analysis evolved. When a stakeholder asks why a number changed from last month's report, you can trace it back to a specific query file rather than guessing. Documentation is the third thing that gets ignored. A query file with no comments is useless six months later. I use a simple header block at the top of every SQL file that states what the query does, what the expected output shape is, and what assumptions it makes about the source data. It takes about 30 seconds per file and saves hours of confusion later.
The honest limitation of SQL as a primary tool for data analysis is that it struggles with iterative, exploratory work. When you're trying ten different ways to slice the same dataset, writing and rewriting the same query structure gets tedious. Python with pandas or DuckDB fills that gap reasonably well for the exploration phase, and then you can translate the final logic into optimized SQL for production. DuckDB is worth trying because it's an in-process SQL engine that reads Parquet files directly and runs SQL on them without needing a server. It's fast enough for datasets up to about 10GB and lets you iterate quickly before moving to a proper database. SQL also isn't great at handling unstructured data. If your analysis involves text parsing, natural language processing, or image data, you'll hit the ceiling pretty quickly. The workarounds exist — JSON functions in newer Postgres versions, udfs in BigQuery — but they're kludges compared to using the right tool for the job. Knowing when to leave SQL and switch to something else is probably the most valuable skill in this area, and it's something you only learn after burning time trying to force a square peg into a round hole. The bottom line is that SQL projects for data analysis are mostly about learning to think in sets and understand how the database processes your requests. The syntax is the easy part. Understanding query plans, indexing strategies, and data quality patterns is what separates someone who can write a working query from someone who can write one that actually scales. Start small, run EXPLAIN ANALYZE on everything, and don't be afraid to rewrite queries once you understand why the first version was slow.