What actually moves the needle when you're fighting slow Oracle queries
The execution plan doesn't lie. It just does it every single day and you end up treating it like static noise until a critical report hits the executive floor at 8 AM and sits there running for forty-five minutes. That's when people realize they don't actually understand what the plan is showing them. Most of the time the problem isn't a missing index. It's the optimizer making a reasonable decision based on stale statistics, or a bind variable peek situation that locked in a terrible plan during first parse and then refused to budge. I spent three years doing this full-time before I stopped reaching for ALTER SESSION SET trace as my default response. The tuning process is simpler than most guides make it sound, and significantly more annoying in practice. You start with the query, you get the plan, you find where the cost explodes, and you work backwards from there. The reverse direction matters more than people admit. Start at the symptom and trace your way to the root cause instead of guessing from the schema outward.
Sql Tuning With Oracle
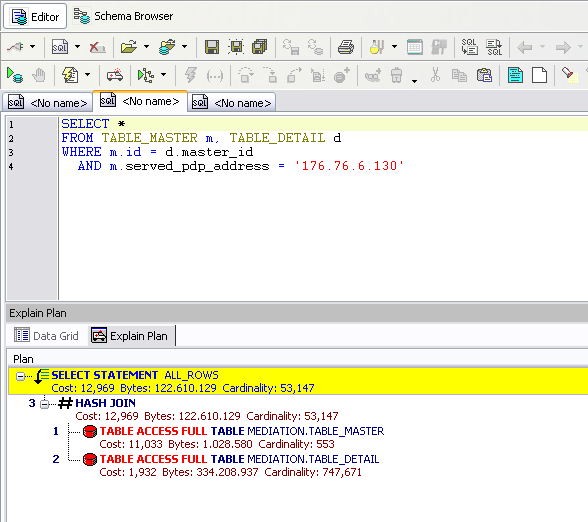
Oracle's approach to query tuning revolves around the CBO, or Cost-Based Optimizer, which has been the default since 8i. Before that era you were stuck with RBO rules that produced bizarre plans by modern standards. The CBO estimates costs using statistics gathered on tables, indexes, columns, and system parameters. When those statistics are accurate, the optimizer usually picks a decent plan. When they're wrong, everything downstream becomes a guessing game. The core tool in your kit is EXPLAIN PLAN. It shows you what the optimizer thinks it will do without actually executing the query. That distinction is important because it means you can see the plan for a query that would take six hours to run in under three seconds. The downside is that EXPLAIN PLAN uses the current session's environment, which might not match production settings. If you're tuning against a test database with different parameter values, the plan you get could be completely irrelevant to what happens in production. For actual execution data, you want SQL Trace with waits and binds enabled. The command looks like this:
ALTER SESSION SET sql_trace = TRUE;
ALTER SESSION SET events '10046 trace name context forever, level 8';
Level 8 gives you wait event information, which is where most of the useful diagnostic data lives. Without waits, you're only seeing CPU and logical I/O. The difference between a full table scan and an index scan is obvious in elapsed time. The difference between two index scans that look identical on paper is also obvious in elapsed time, but only if you're looking at the right trace output. After the query finishes, you convert the raw trace file into a readable report using TKPROF:
Get the Full Details
tkprof tracefile.trc report.out sys=no explain=username/passwordThe sys=no parameter strips out recursive SQL from the output, which otherwise drowns out the query you actually care about. Without it, a single user query can generate pages of system-level SQL that makes the report nearly impossible to parse manually. Most tutorials show you the plan format and move on. The thing nobody tells you is that operation order in an EXPLAIN PLAN output doesn't always reflect actual execution order. Oracle reorders operations internally during optimization, and the display can show them in a different sequence. What matters more is the cost, bytes, and cardinality columns. Those three numbers tell you whether the optimizer thinks a given step is expensive, how much data it expects to process, and how many rows it predicts will come out the other side. When cardinality is wildly wrong, the optimizer makes wrong choices. This is the single most common source of bad plans in my experience. A histogram on a skewed column can fix it, but only if you understand when the data distribution actually warrants one. Adding histograms to every low-cardinality column is a well-meaning mistake that increases compilation time and consumes unnecessary space in the data dictionary.
I once had a query that ran in 2 seconds with one set of bind values and 14 minutes with another. The same SQL ID, same plan hash value, completely different performance. Bind peeking was the culprit. Oracle peeked at the first bind value during hard parse, estimated row counts based on that value, chose a plan optimized for a small result set, and then executed against data that produced millions of rows. The workaround was straightforward: enable PASSWORD PROTECTED or use a SQL Plan Base from the SQL Tuning Set to lock in the correct plan regardless of bind values. Here's how you create a SQL Tuning Set and capture the problematic query:
BEGIN
  DBMS_SQLTUNE.CREATE_SQLSET(
    sqlset_name => 'problem_queries',
    description => 'Long running queries from production'
  );
END;
/
Then you load it from V$SQL or a workload repository, and run the tuning advisor against it: The output from DBMS_SQLTUNE.REPORT_TUNING_TASK will include recommendations like gather statistics, create indexes, or accept a SQL profile. The SQL profile recommendation is the one most people overlook. It lets Oracle store additional information about a specific SQL statement that influences the optimizer's choices without changing the statement itself or creating a baseline. It's essentially a persistent hint that doesn't require touching application code. Gathering stats on Oracle is deceptively simple. One command does it:

The CASCADE parameter gathers both table and index statistics in one pass. Without it you might gather table stats and then spend another twenty minutes waiting for index stats to complete on a large table. The real question is what degree of parallelism and what sample size to use. For a table with fifty million rows, sampling at 10 percent with degree of parallelism 4 usually produces statistics that are accurate enough for the optimizer and completes in under a minute. Full collection on that same table can take fifteen to twenty minutes with minimal improvement in plan quality. Stale statistics accumulate quickly in systems with heavy DML. If a table gets bulk inserted or truncated and you don't re-gather stats afterward, the optimizer is working with numbers from weeks or months ago. The STALE_STATS column in DBA_TAB_STATISTICS flags these. Query it regularly. Tables with a stale flag and active queries against them should be at the top of your tuning priority list. There is a tradeoff you need to accept. More frequent statistics gathering improves plan quality but increases the load on the database during collection windows. There's no free lunch. You schedule stats jobs during low-activity periods or use incremental statistics if your version supports it. Oracle 11g and later introduced incremental stats, which update statistics on modified partitions without rescanning the entire table. That feature alone cut my weekly maintenance window from four hours to about forty-five minutes.
Indexes and the traps around them
Adding an index is the easiest tuning action and often the wrong one. I've seen databases where every table had six to eight indexes, most of them unused, and query performance was worse than it would have been with none of them. Each index slows down INSERT, UPDATE, and DELETE operations because Oracle has to maintain every index whenever the underlying table changes. In a heavily written table, that maintenance overhead can dominate execution time. The Oracle Index Monitoring feature is useful here. You can mark an index as monitored and then check V$OBJECT_USAGE to see if it's ever been used:
ALTER INDEX index_name MONITORING USAGE;
-- run workload
SELECT * FROM V$OBJECT_USAGE WHERE INDEX_NAME = 'INDEX_NAME';
ALTER INDEX index_name NO_MONITORING USAGE;
If monitoring shows a statistically significant index has zero usage over a representative workload period, dropping it is usually safe. The uncertainty comes from periodic queries that run monthly or quarterly. If your monitoring window is too short, you'll drop an index that a rare but important report depends on. Function-based indexes are another area where people either ignore them entirely or overuse them. A function-based index on UPPER(last_name) makes a case-insensitive query fast without changing the application SQL. But it only helps if the WHERE clause uses the exact same function expression. UPPER(last_name) = 'SMITH' uses the index. last_name = 'SMITH' doesn't, no matter how obvious that seems. Write the query to match the index, or don't create the index.
Bind variables, cursor sharing, and why your plan changes
Cursor sharing is a setting that affects how Oracle matches incoming SQL statements to cached execution plans. The default behavior is EXACT, which means two statements must be character-for-character identical to share a plan. FORCE and SIMILAR modes attempt to substitute literals with bind variables to increase plan sharing. FORCE is aggressive and can cause problems. SIMILAR is more conservative and generally safer if you're dealing with literal-heavy queries that the application doesn't parameterize properly. The problem with literal SQL is that every unique value combination creates a new parse. The parser has to generate a fresh plan, validate permissions, check dependencies, and cache the result. Under high concurrency, this parse overhead alone can fill up shared pool and cause latch contention. Converting to bind variables eliminates that path entirely, but it reintroduces the bind peeking problem I mentioned earlier if the data is skewed. The practical solution for skewed data with binds is adaptive cursor sharing, available from Oracle 11g onward. The optimizer tracks the bind values a cursor uses across executions and can create multiple child cursors for the same SQL if different bind values produce significantly different plans. It handles the bind peeking issue automatically without manual intervention. Most databases already have this enabled by default, but it's worth verifying because some legacy configurations disable it.
When the tools don't help and you need a different approach
SQL tuning has limits. No amount of index management or statistics gathering will make a fundamentally poorly structured query fast if the query logic is wrong. Sometimes the application is doing a Cartesian product because a join condition was dropped during a rewrite. Sometimes it's doing a full table scan on a ten billion row table because the WHERE clause applies a function to the indexed column, preventing index usage. These aren't tuning problems. They're design problems, and the tuning tools won't fix them. The most reliable approach when tools fall short is rewriting the query. Break a monolithic query into smaller CTEs or temporary tables. Let the optimizer handle each piece independently instead of forcing it to solve the entire problem at once. This sometimes produces worse plans for individual steps but better overall performance because each step uses accurate cardinality estimates. Another option is materialized views for reporting queries that don't need real-time data. A pre-aggregated materialized view with a refresh strategy can replace a query that joins twelve tables and aggregates millions of rows. The refresh runs during off-peak hours, and the reporting query hits the view instead of the base tables. This is a structural change, not a tuning change, but it's often the only thing that moves the needle on reports that have been slow for years.
Download and resource links
The built-in Oracle packages for tuning require no separate download. Everything I referenced is part of the Oracle Database Enterprise Edition and can be verified with: If you need the SQL Trace and TKPROF utilities, they ship with the Oracle client installation. Download the appropriate client package for your OS from the Oracle Software Delivery Cloud at https://www.oracle.com/downloads/. Select your platform, download the basic client zip, and extract it. TKPROF is included in the bin directory of the extracted client. For automated tuning workflows, the Oracle SQL Tuning Pack is available as an add-on license. Check your current licensing with:
SELECT * FROM DBA_FEATURE_USAGE_STATISTICS WHERE NAME LIKE '%SQL%';If you're on Standard Edition, the SQL Tuning Pack features won't be available and you'll need to rely on manual analysis and the EXPLAIN PLAN method described above. That path is more work but covers most real-world tuning scenarios. The official Oracle documentation for each package is the most accurate reference. Search for the specific DBMS package name along with your Oracle version number. The documentation includes parameter defaults, usage examples, and known limitations that third-party summaries tend to omit. It's dense reading but it's the source, not a filtered interpretation.
What I wish I knew before starting
The first thing is that query performance is rarely a single factor problem. A slow query is usually slow because of three or four small issues compounding each other: slightly wrong cardinality estimates, a marginal index that only helps some of the time, suboptimal join order, and a statistics job that hasn't run in three weeks. Fixing one of them might not move the needle noticeably. Fixing all four together drops the runtime from minutes to seconds. The second thing is that you should never tune a query in isolation. The database is a shared environment. An index you create for one report might cause a bulk load job to slow down by twenty minutes. Resource management and tuning goals shift depending on what else is running. Always check the overall system state before and after changes, not just the single query you're focused on. The third thing is simpler than the other two. Keep records of what you changed and what happened. A tuning session without documentation is just noise. Note the original runtime, the plan hash before and after, the statistics level, and the specific change you made. Six months later when the same query slows down again, those notes are the only thing that separates you from starting over from scratch.