How I Actually Use Standard Deviation and the Bell Curve Without Losing My Mind
Most people learn about the bell curve in stats class and then never touch it again until they need it for something real. That's when things get messy. The Standard Deviation Bell Curve is one of those concepts that sounds straightforward until you're working with actual data and the numbers refuse to cooperate. Let me walk you through how this actually works in practice, not just the textbook version.The Standard Deviation Bell Curve Explained (And Where It Fails)
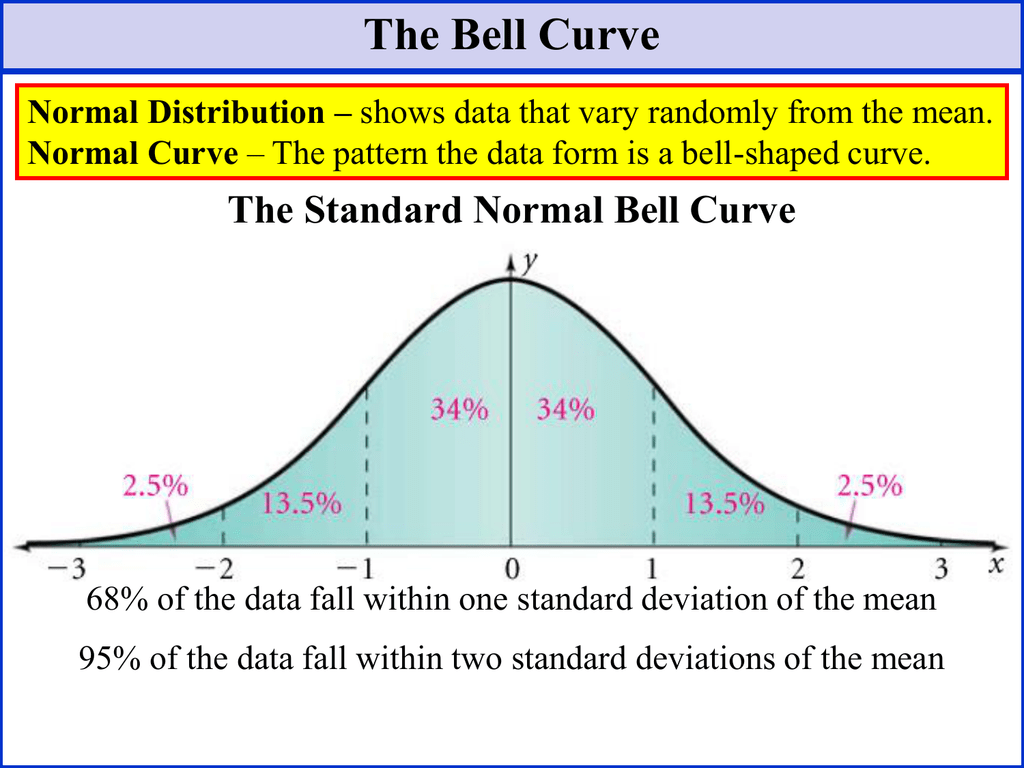
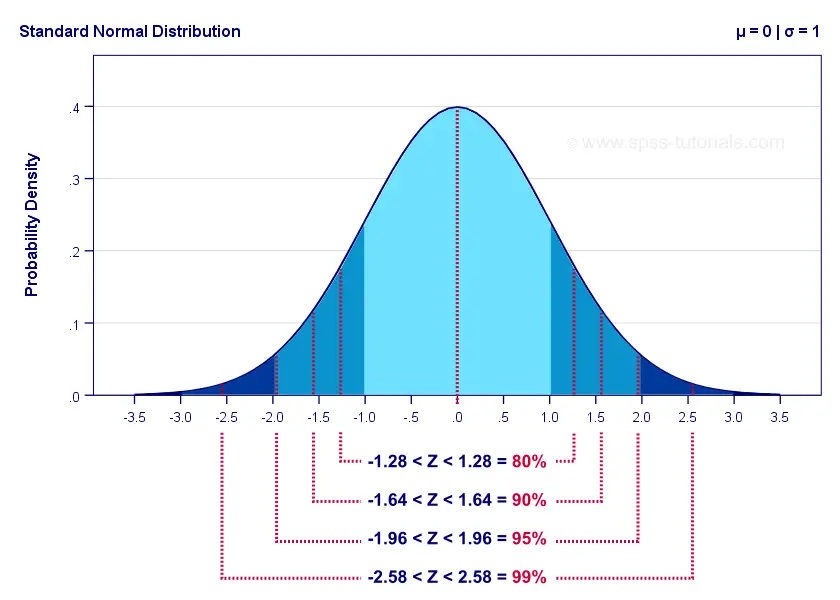
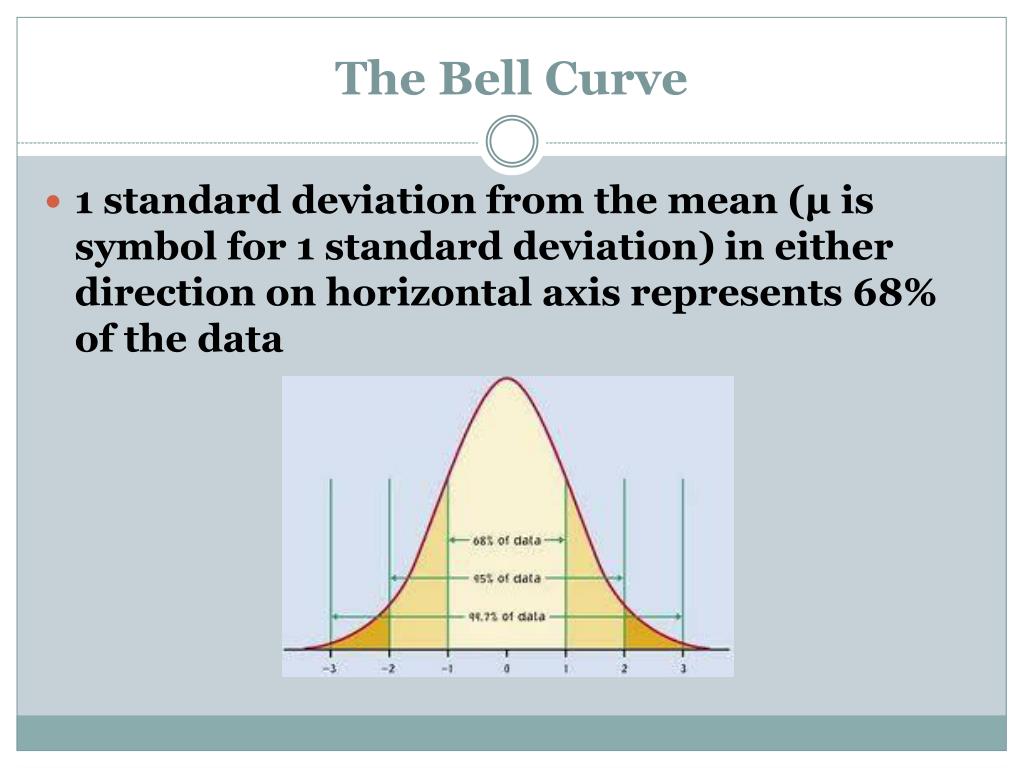
Standard deviation measures how spread out your data is. The bell curve, or normal distribution, is what happens when that spread follows a predictable pattern. One standard deviation from the mean covers about 68% of your data. Two covers roughly 95%. Three covers 99.7%. That's the shorthand everyone memorizes. Here's what nobody tells you: real data rarely fits this perfectly. I worked with a client who was running quality control on manufactured parts. The measurements looked normal at first glance. The bell curve was there. But when I calculated the standard deviation properly and mapped it out, the tails were fatter than they should have been. There were more extreme values than a true normal distribution would predict. We called that leptokurtic later, but at the time it just looked like our process was broken in ways we couldn't immediately see. The workaround wasn't fancy. We switched from using standard deviation alone to also tracking the interquartile range alongside it. The IQR doesn't care about outliers the way standard deviation does. By comparing both metrics, we could tell when the process had drifted beyond normal variation versus when it was just experiencing the occasional bad batch. It took us about ten minutes to set up after years of relying on the bell curve blindly.
Calculating Standard Deviation by Hand (Because Sometimes You Have To)
You don't need a calculator for this. Grab a piece of paper. Write down your dataset. Find the mean by adding everything up and dividing by the count. Then subtract the mean from each value, square the result, add all those squared differences together, divide by n minus one for a sample, and take the square root. Done. For a population, you divide by n instead. The difference matters. Using the wrong one will throw off your standard deviation enough that your bell curve assumptions become unreliable. I've seen this mistake cost teams weeks of re-analysis because someone plugged the formula into Excel without thinking about whether their data represented the entire population or just a sample of it. If you're working with large datasets, use the computational formula instead of the definitional one. It avoids subtracting every single value from the mean before squaring, which reduces rounding errors significantly. The difference is negligible with small datasets but becomes noticeable when you're dealing with hundreds or thousands of points. I learned this the hard way when building a real-time monitoring system where floating point precision mattered more than anyone expected.
When the Bell Curve Assumption Is Dangerous
Here's the uncomfortable truth I wish more people understood. Assuming your data follows a normal distribution is one of the most common errors in applied statistics. Income data doesn't follow a bell curve. It skews right. Reaction times don't either. They're positively skewed. Test scores often cluster at the top or bottom depending on difficulty. The list goes on. I remember analyzing survey response data for a product team. The average satisfaction score looked fine. The distribution was bimodal though — two distinct peaks instead of one. People either loved the product or hated it, with nobody in between. Treating this as a normal distribution would have led us to draw completely wrong conclusions about the customer base. We caught it because I plotted the histogram before calculating anything, which is something I should have been doing all along. The fix isn't always to abandon standard deviation. Often it's to transform the data first. Logarithmic transformation handles right-skewed data well. Box-Cox transformations are even more flexible if you're comfortable with the math. If the transformed data approximates a normal distribution, your standard deviation becomes meaningful again and the bell curve framework applies.
Get the Full Details

Common Pitfalls That Waste Time
Using standard deviation on ordinal data is one. Likert scale responses from 1 to 5 don't have equal intervals between values in any meaningful sense. The distance between "disagree" and "neutral" might be completely different from "neutral" to "agree." Yet you'll see standard deviation calculated for survey scores constantly, presented as if it tells you something precise. Another pitfall is conflating standard deviation with standard error. They're related but serve different purposes. Standard deviation describes your dataset. Standard error describes how precisely your sample mean estimates the population mean. If you're reporting confidence intervals or doing hypothesis testing, you need standard error, not standard deviation. Confusing the two will make your intervals too wide or too narrow depending on your sample size. I've also seen people calculate standard deviation on time series data where the mean itself is drifting. If your data has a trend, the standard deviation captures both the random variation and the trend magnitude. That inflates your standard deviation and makes your control limits useless. The fix is to detrend first, then calculate. Remove the moving average or fit a regression line and use the residuals.
A Practical Example That Actually Matters
Let me give you a concrete scenario. You manage a fulfillment center. Order processing times over the past month average 4.2 hours with a standard deviation of 0.8 hours. You want to set a service level target where 95% of orders ship within a certain timeframe. Using the bell curve assumption, 95% falls within about two standard deviations. So 4.2 plus 1.6 gives you 5.8 hours. That seems reasonable. Except the data wasn't normal. Processing times had a longer right tail. Some orders got stuck on hold for various reasons — missing information, weekend delays, special handling requirements. When we looked at the actual cumulative distribution, only about 92% of orders processed within 5.8 hours, not 95%. The gap isn't huge in this example but in high-volume operations that 3% difference translates to hundreds of missed targets per week. We adjusted by using the 95th percentile directly from the empirical distribution instead of relying on the bell curve approximation. That gave us a more accurate cutoff and aligned expectations with reality. It also highlighted which order types were driving the tail length so we could target improvements there rather than just expanding the window for everyone.
Tools and Resources
If you need to calculate standard deviation regularly, any spreadsheet software will do it. Excel has STDEV.S for samples and STDEV.P for populations. Google Sheets uses the same functions. For more advanced work, R has rnorm for generating normal distributions and shapiro.test for checking normality. Python's scipy.stats module handles everything from calculation to testing. I use a custom dashboard built in Python that pulls from our databases, calculates relevant statistics, and plots the distributions automatically. It saves maybe twenty minutes per report cycle compared to doing it manually. The real value isn't the time savings though. It's that the visualization catches anomalies I'd otherwise miss because I was too focused on the summary numbers. For people starting out and wanting to understand the mechanics without jumping straight to software, I recommend working through a small dataset by hand first. Five to ten numbers is plenty. You'll see exactly how each value contributes to the standard deviation and why outliers pull it in their direction. That intuition carries over when you eventually move to automated tools.
The Bottom Line on Standard Deviation and the Bell Curve
The Standard Deviation Bell Curve framework is useful but overused. It works well when your data is actually normally distributed or close enough that the approximation holds. It breaks down clearly when your data is skewed, multimodal, or has heavy tails. Before applying it, check the distribution. Plot a histogram. Run a normality test if you want to be formal about it. Don't skip that step because it takes thirty seconds and saves you from building decisions on faulty assumptions. Standard deviation is a descriptive statistic. It tells you about spread, not about causes. A small standard deviation doesn't mean your process is good. It just means your data points are close together. They could be close together around a wrong mean. A large standard deviation doesn't mean your process is bad either. It means there's variation worth investigating. The number itself doesn't judge. You do that based on context and requirements. The bell curve is a model, not a law of nature. Nature doesn't care about it. Data only approximates it under certain conditions. Remember that distinction and you'll avoid most of the problems people run into when they treat these tools as gospel instead of what they actually are — useful approximations that require verification before application.