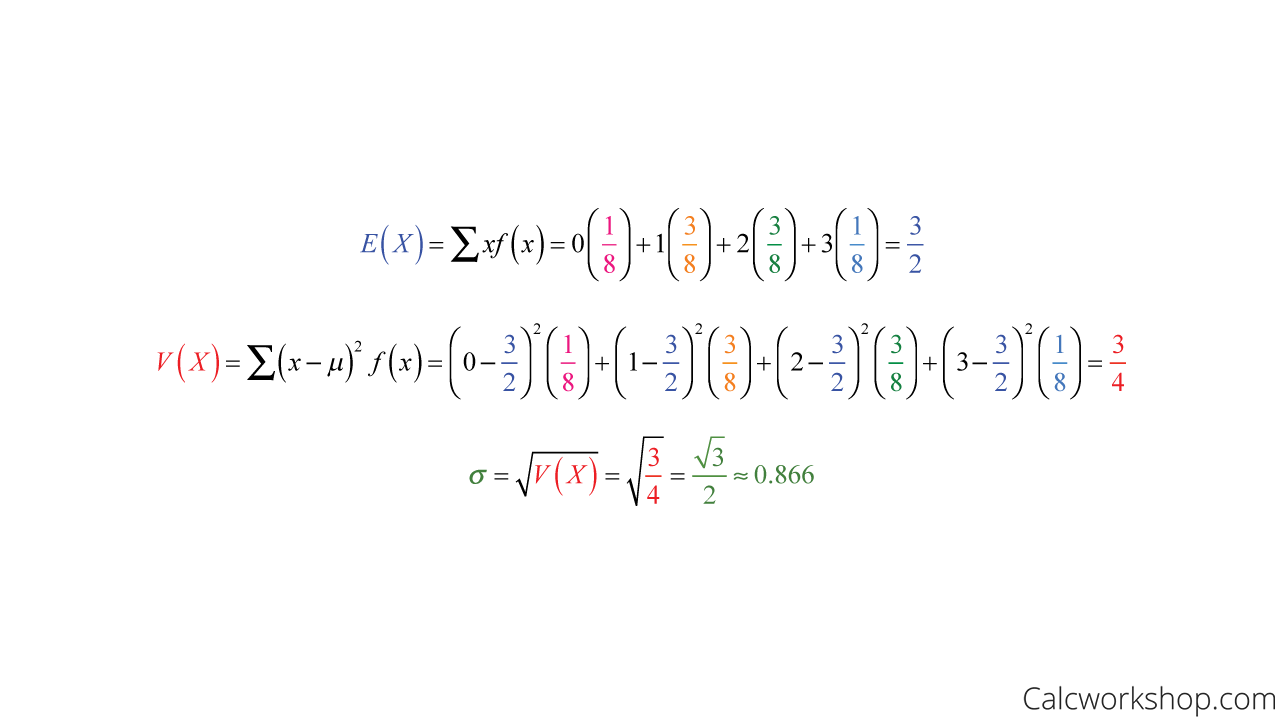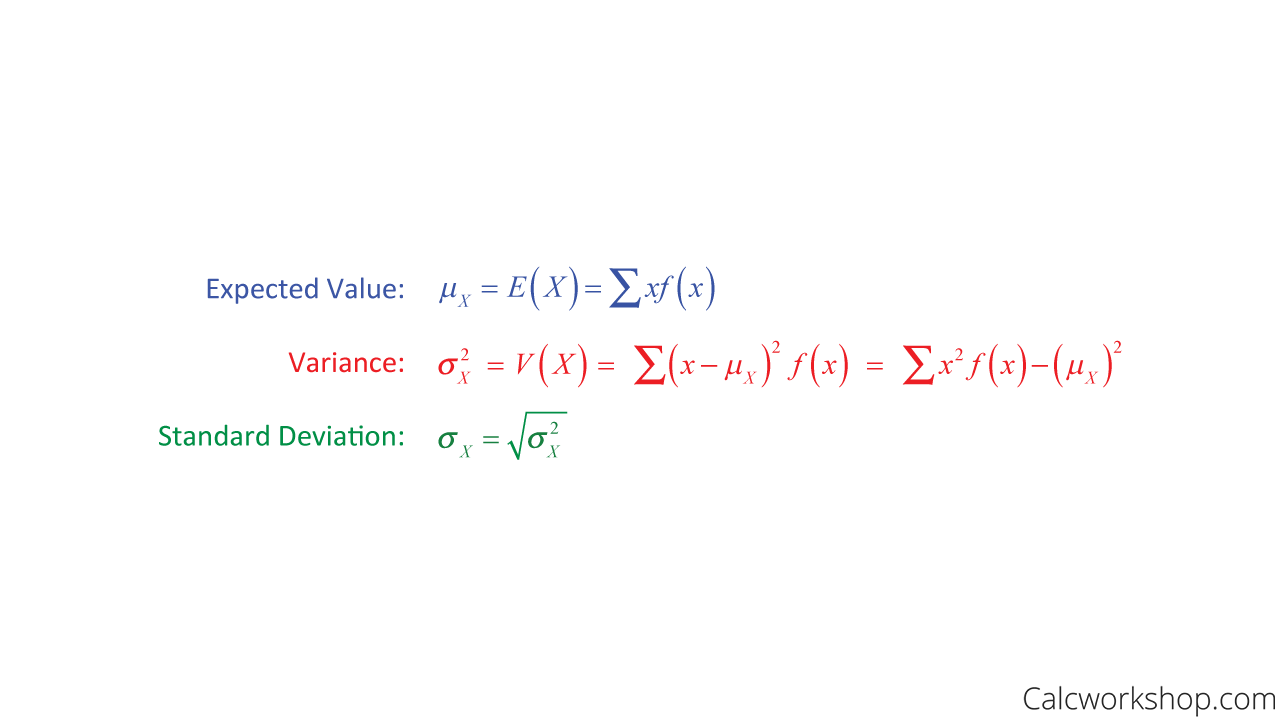
Working With Standard Deviation Of Expected Value In Practice
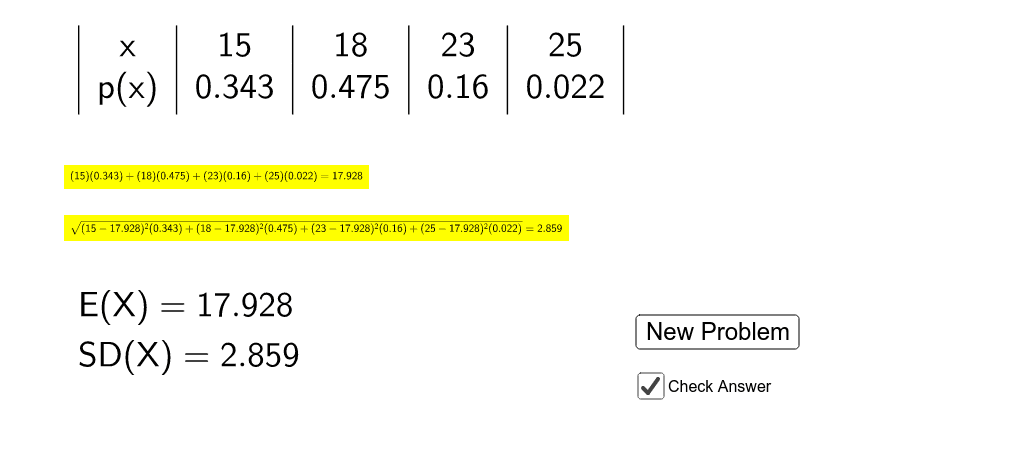
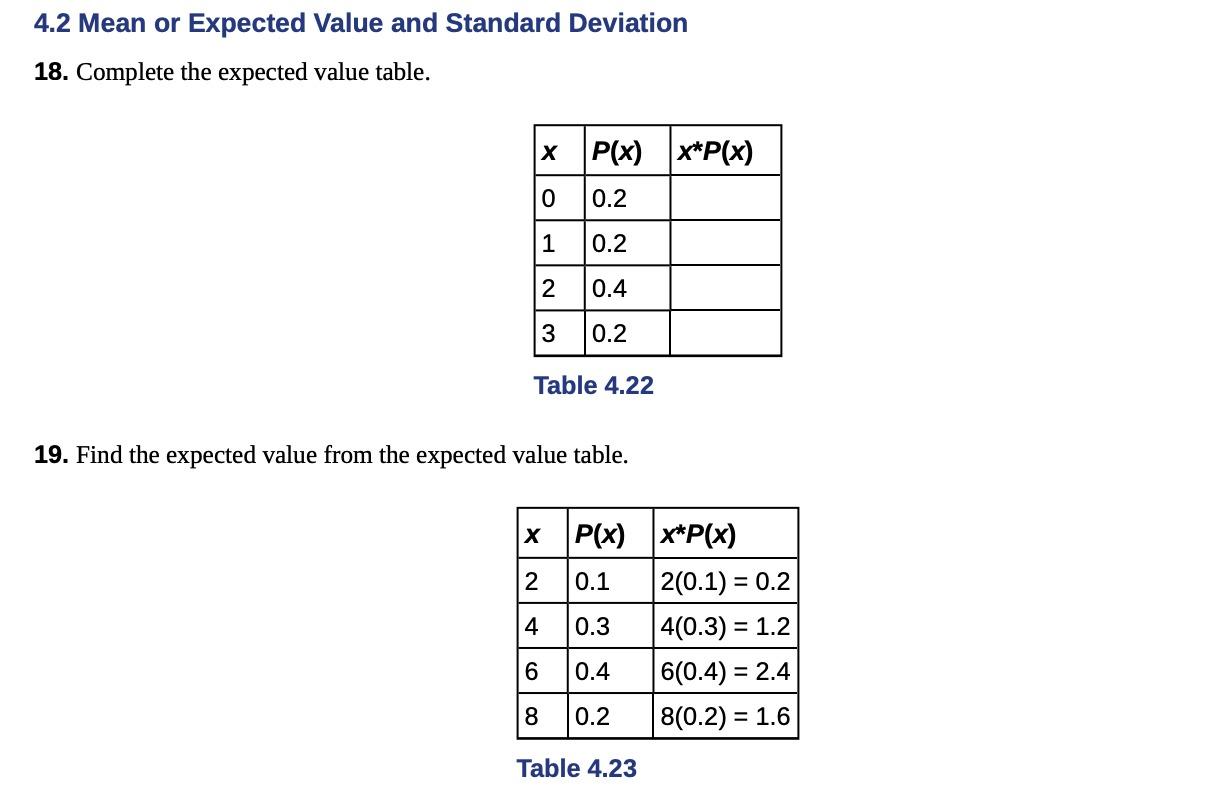
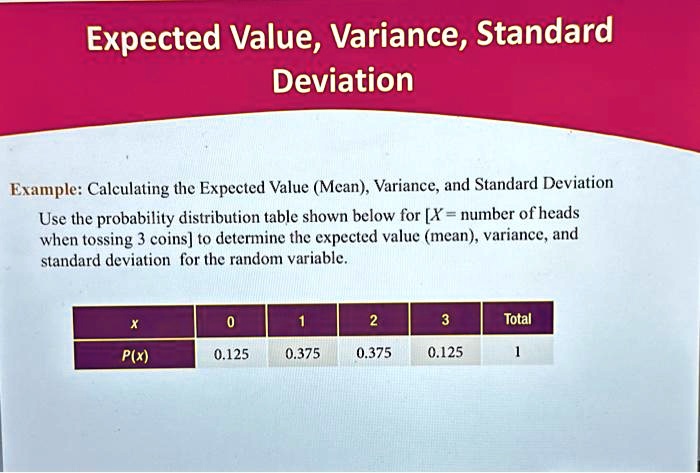
I see this question come up a lot, usually from people who are reading about risk models and getting tangled in the notation. Let me just walk through how to actually compute it and what it means when you put it on a real spreadsheet. First, the computation. Say you have a random variable X and its probability distribution. You start by finding E[X], the expected value, which for a discrete distribution is just the sum of each outcome multiplied by its probability. For a continuous distribution, you integrate x times the probability density function over the full range. That gives you a single number—the mean of the distribution. Then you take each outcome, subtract that mean, square the result, weight it by the probability, and sum or integrate again. That gives you the variance. Take the square root and you have the standard deviation. The whole thing, sometimes written as (X), measures how far outcomes typically land from the expected value.
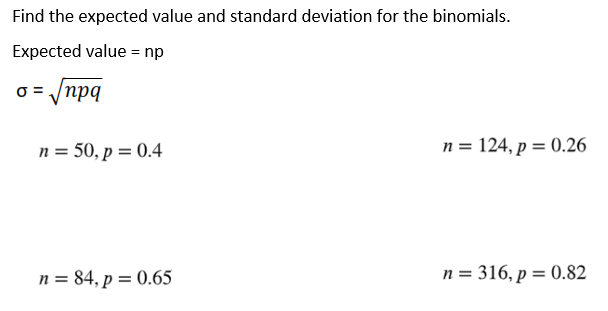
Here's where it gets tricky, and this is the part most guides skip. The expected value E[X] itself is a constant. The standard deviation of a constant is zero. So strictly speaking, (E[X]) = 0. What people actually mean when they say "standard deviation of expected value" is usually the standard deviation of the underlying random variable X, computed from the same distribution whose mean is E[X]. They're talking about the spread around the mean, not the spread of the mean itself. Getting this distinction straight matters because it changes what you do next with the number. I worked on a project last year building a Monte Carlo model for commodity price hedging. We had a portfolio of energy contracts and needed the standard deviation of the expected cash flow distribution to set reserve margins. The distribution wasn't normal—it had a fat right tail from spike events. My first run with 10,000 paths gave a standard deviation that looked reasonable on paper, but when I broke it down by percentile, the 99th percentile was wildly far out because those few extreme scenarios dominated the variance calculation. I ended up switching to a bootstrapped confidence interval around the standard deviation estimate itself, because the point estimate was too sensitive to the tail. That workaround took about an extra hour of runtime but saved us from setting reserves that were off by roughly 40 percent compared to a more robust estimate. The formula you will use most is = [ p_i · (x_i )²] for discrete cases and = [ (x )² · f(x) dx] for continuous ones, where is E[X]. In practice, if you're pulling this from a sample rather than a known distribution, use the sample standard deviation with Bessel's correction—divide by n 1 instead of n. The difference is small with large samples but noticeable when you're working with fewer than a hundred data points.
A counter-intuitive thing to keep in mind: the standard deviation is not a measure of central tendency. Two distributions can share the same expected value and have very different standard deviations, or share the same standard deviation and have totally different shapes. A bimodal distribution and a normal distribution can have identical means and standard deviations, but the risk profile between them is completely different. If you're using standard deviation as a proxy for risk without checking the shape of the distribution, you're leaving money on the table or exposing yourself to surprises. Another thing people miss is that standard deviation assumes finite variance. If your distribution has heavy tails—Pareto-type behavior, for example—the variance may not exist at all, and the standard deviation becomes meaningless. In those cases, you need to switch to interquartile range or median absolute deviation. I ran into this with a portfolio of venture-style investments where returns followed a power law. The standard deviation was enormous and changing dramatically with each new deal, which made it useless for comparison. Switching to log-space returns and using the standard deviation there instead gave a stable, comparable metric in about five minutes of recalculation. If you want a quick reference or a calculator, most statistical packages handle this directly. In Python, numpy's std function or scipy.stats provides everything you need. In Excel, STDEV.P for population data and STDEV.S for sample data. These tools compute the same underlying formula, just with different handling of the denominator depending on whether you're describing a population or estimating from a sample.
Get the Full Details
The main limitation of relying on standard deviation of expected value is that it treats upside and downside deviations symmetrically. For risk management, that symmetry is often wrong. Downside moves matter more than upside moves. When that asymmetry is important, consider semi-variance or conditional value at risk instead. These focus on the left tail specifically and tend to give a more useful picture for decision-making, even if they require a bit more setup.