Understanding What Actually Happens When You Take Repeated Samples
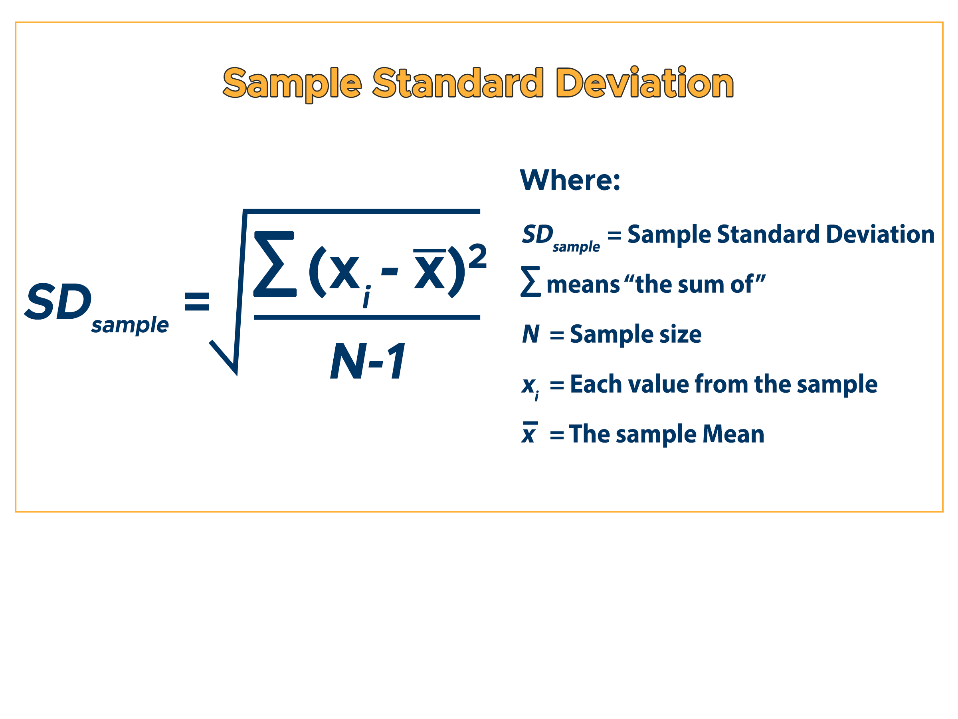
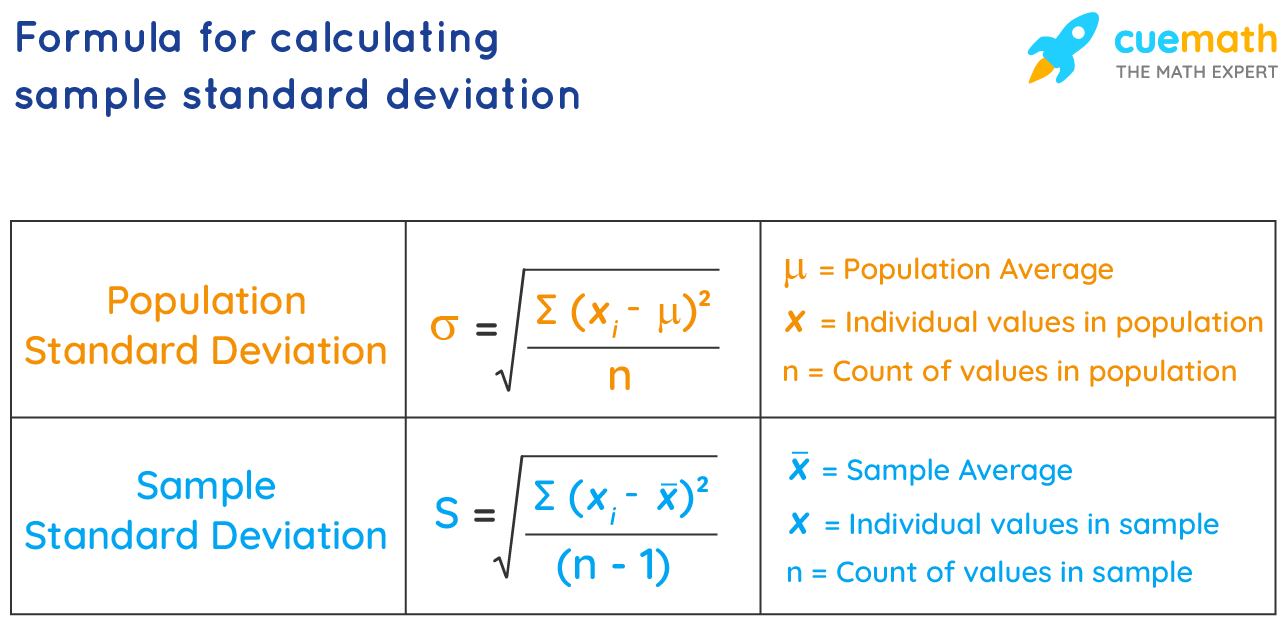
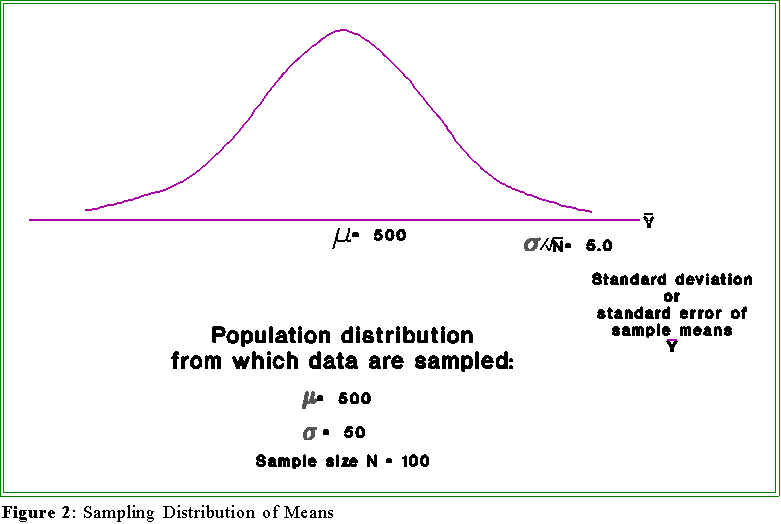
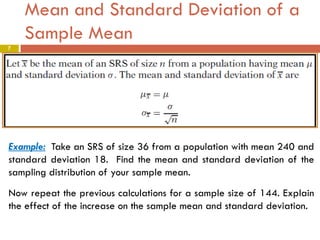
Most people learn this concept in a statistics class and then immediately forget it because the textbook version is too abstract to be useful. I ran into this issue constantly when doing quality control work for a manufacturing client, trying to explain why their process variation measurements looked wrong after sample sizes changed. The standard deviation of sampling mean is really just the spread you'd see across the means of many samples pulled from the same population. It is not the same thing as the population standard deviation, which is a common mix-up that costs people points on exams and causes real problems in practice. Start with the population standard deviation. Divide it by the square root of your sample size. That gives you the standard error, which is another name for the standard deviation of sampling means. The formula looks like this: x = / n. Simple to write. Easy to mess up when you apply it without understanding what each piece represents. Here is a concrete example from actual work. I was analyzing cycle time data from a call center. The population standard deviation of individual call lengths was 4.2 minutes. We were pulling samples of 36 calls at a time. The standard deviation of sampling mean worked out to 4.2 divided by the square root of 36, which equals 0.7 minutes. That means if we kept taking groups of 36 calls and recording their average length, those averages would cluster around the true population mean with a spread of roughly 0.7 minutes. The individual calls themselves varied by 4.2 minutes. The averages vary much less because extreme values cancel each other out within each sample group.
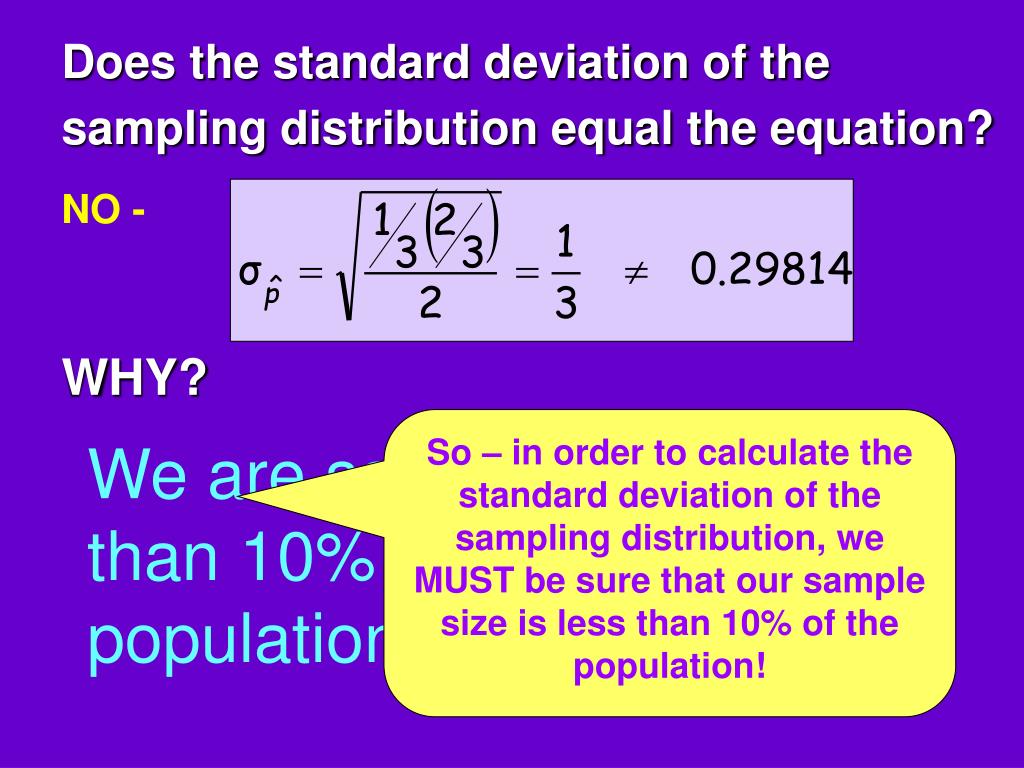
Sample size matters more than most people expect. Going from n=4 to n=16 cuts the standard error in half, but going from n=100 to n=400 only halves it again. The returns diminish quickly, and that is something I wish every beginner understood before they designed their first study. I once spent two weeks troubleshooting why a client's A/B test kept showing inconsistent results. The problem was not the treatment effect, it was that their sample sizes were too small to get a stable estimate of the sampling distribution. They had n=9 per group, which gave them a standard error roughly three times larger than it should have been for a properly powered test. Increasing to n=36 per group dropped the standard error to an acceptable range and the results became interpretable within a week. The central limit theorem is the reason any of this works at all. It states that the sampling distribution of the mean approaches normality as sample size increases, regardless of the population's underlying distribution. In practice, this means you can use this calculation even when your data is skewed, as long as your sample size is reasonable. A rule of thumb is n30 for most real-world distributions. If your population is already normal, you do not need that large of a sample. I have seen people apply this blindly to samples of five from heavily skewed distributions and get wildly inaccurate confidence intervals. The math looks clean on paper, but the assumptions behind it are easy to violate. One counter-intuitive point that rarely gets explained clearly: the standard deviation of sampling mean does not depend on the population size, only on the sample size and population standard deviation. This surprises people who assume that surveying 1,000 people out of a population of 10,000 gives a different result than surveying 1,000 out of 1,000,000. For sampling with replacement, they are identical. Even with finite populations, the correction factor is usually negligible unless your sample is more than 5 percent of the total population. When that happens, you apply the finite population correction: multiply by the square root of (N-n)/(N-1), where N is the population size and n is your sample size.
Here is where things get messy in practice. Real data is rarely a clean random sample from a known population. Selection bias, non-response, clustering, and measurement error all distort the sampling distribution in ways that the basic formula does not account for. I worked on a project where the standard error calculation suggested a margin of error of ±2 percent, but the actual precision was closer to ±8 percent because the survey was conducted through an opt-in panel. The math was correct, but the sample was not representative, so the standard deviation of sampling mean was misleadingly small. This is a fundamental limitation: the formula tells you about random sampling variability, not about systematic errors in how you collected the data. Another practical issue is that in most real situations you do not know the population standard deviation, so you have to estimate it from your sample. When you substitute s for , you are no longer working with the normal distribution, you are working with the t-distribution. For small samples this makes a meaningful difference. With n=10, the t-value for a 95 percent confidence interval is about 2.26 instead of 1.96, which widens your interval by roughly 15 percent. Many tools and textbooks gloss over this distinction, which leads to overconfident conclusions from small samples. Bootstrapping is a useful alternative when your data violates the assumptions needed for the standard formula. You resample your observed data with replacement many times, calculate the mean for each resample, and then take the standard deviation of those bootstrapped means. This gives you an empirical estimate of the standard error that does not rely on the central limit theorem or any distributional assumptions. It is computationally heavier but usually more reliable for complex or non-standard data. I default to this approach when dealing with skewed reaction time data or bounded proportions where the theoretical formula tends to underperform.
Get the Full Details
If you are implementing this yourself, a couple of practical notes. Use at least n=30 when applying the normal approximation unless your population is known to be normal. Apply the finite population correction when your sample exceeds 5 percent of the population. Switch to the t-distribution when you are estimating from your sample and n is below about 30. And always question whether your sample is actually random before trusting any standard error calculation. The formula is a tool, not a guarantee of accuracy.