Working With Sampling Distributions In Real Data Projects
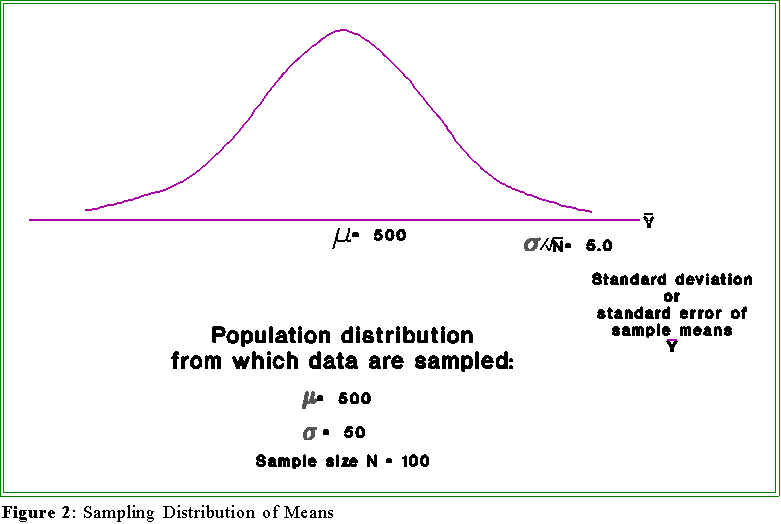
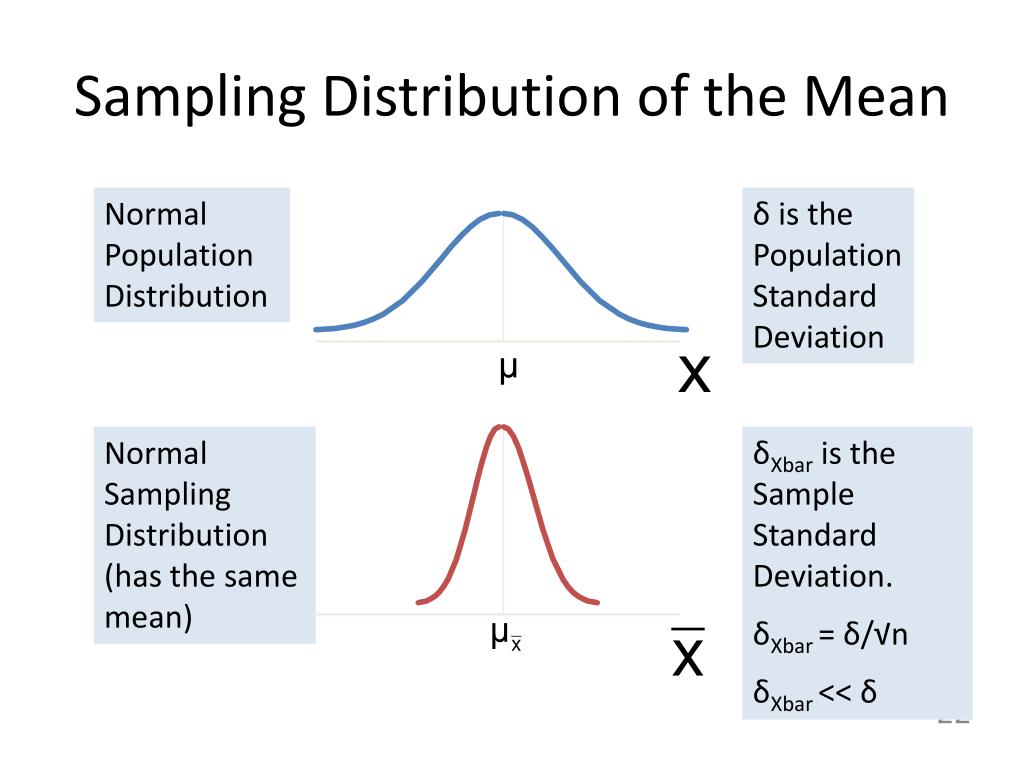
You run a simulation, you pull 1,000 samples from a population, you calculate the mean for each one, and then you try to figure out how spread out those means actually are. That spread is what people call the Standard Deviation Of The Sampling Distribution, though most of us just refer to it as the standard error of the mean after the first week on the job. It is a measure of how much sample means vary from one sample to the next when you keep drawing repeated samples of the same size from the same population. It is not the standard deviation of your original data. It is the standard deviation of the distribution formed by all possible sample means. That distinction matters more than people let on because mixing them up will throw off your confidence intervals and your power calculations. The formula is straightforward when your population standard deviation is known and your sample size is moderate to large. You divide the population standard deviation by the square root of your sample size. I see it written as sigma over the square root of n, which is fine for textbooks. In practice, you rarely know sigma, so you substitute your sample standard deviation s and treat the result as an estimate.
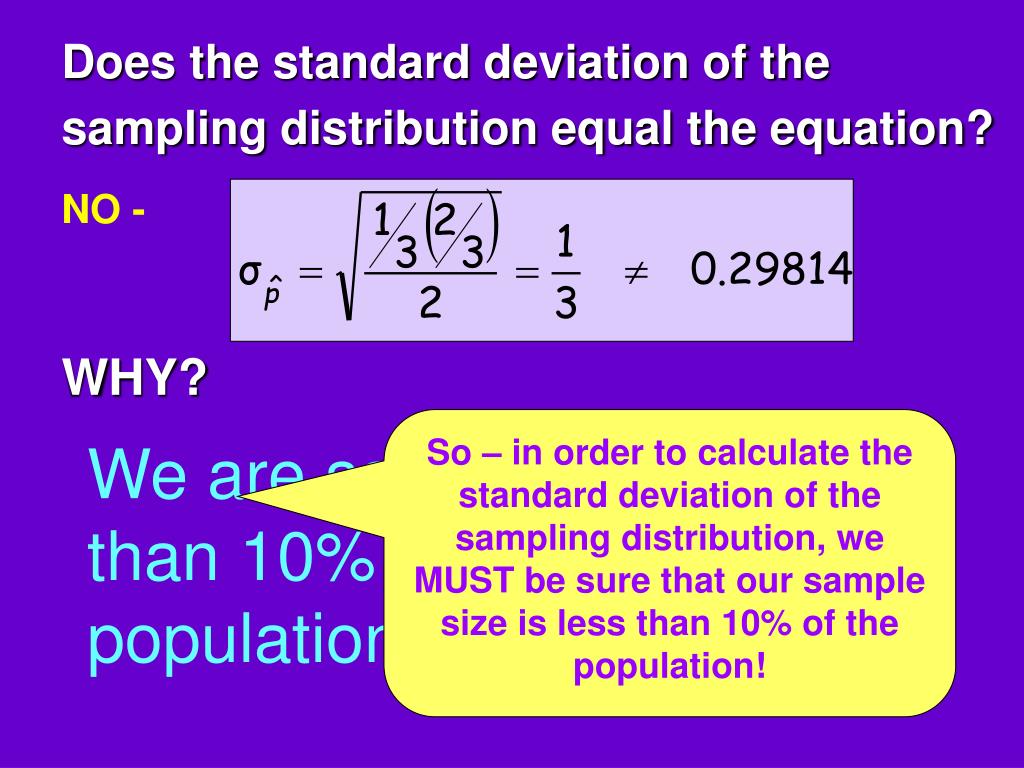
There is a finite population correction factor you need to apply when your sample is more than about 5 percent of the population. Without that adjustment, your standard error will be too large. The corrected version multiplies the basic formula by the square root of N minus n divided by N minus 1, where N is the population size and n is your sample size. I learned this the hard way on a project where I was sampling roughly 8 percent of a client's transaction records. My initial standard error estimates were inflated by about 4 percent compared to what they should have been. Once I applied the correction, my confidence intervals tightened enough to change the business decision. The difference mattered. Here is the practical workflow I use when I need this number. First, I confirm the sampling design. If you are doing simple random sampling without replacement from a finite population, you need the correction factor. If it is with replacement or the population is effectively infinite, you do not. Second, I pull the population or sample standard deviation. Third, I divide by the square root of the sample size. Fourth, if applicable, I multiply by the finite population correction. Fifth, I verify the result with a bootstrap check rather than trusting the formula blindly.
I bootstrap by resampling with replacement from your actual data many times, calculating the mean for each resample, and then computing the standard deviation of those means. If the bootstrap standard deviation is within a reasonable range of your analytical calculation, you are probably fine. If it diverges significantly, you need to check whether your data violate the assumptions behind the standard formula. One thing beginners consistently miss is that the Central Limit Theorem does not save you from everything. The sampling distribution of the mean approaches normality as sample size increases, but the rate of convergence depends heavily on the shape of your underlying population. If your population is heavily skewed or has extreme outliers, you may need a sample size of 100 or more before the standard error formula gives you reliable results. I worked on a project once where the underlying data had a lognormal distribution with a very long right tail. We tried using the standard error formula with samples of 30. The coverage probability on our confidence intervals was nowhere near the nominal 95 percent. It was closer to 82 percent. We switched to bootstrapping and got acceptable coverage with far less hassle. Another counter-intuitive point is that the standard error of the mean does not depend on the shape of the population distribution in the formula itself. It only depends on sigma and n. But it absolutely depends on those things being stable and on the samples being independent. If your sampling is clustered or correlated, your effective sample size is smaller than the nominal n, and your standard error estimate will be wrong. I have seen this happen in survey work where respondents came from the same households or the same geographic blocks. The raw standard error looked fine on paper, but the real variability was much higher because the observations were not independent.
Get the Full Details

When independence is in question, you can estimate the true standard error by using a block bootstrap or by calculating the design effect based on your clustering structure. The design effect multiplies your naive standard error. For mildly clustered data, it might be 1.2 or 1.5. For tightly clustered data, it can be much larger. Ignoring it makes your confidence intervals too narrow and your p-values too small. If you want a quick way to compute this without writing code from scratch, there are downloadable utilities out there. A simple spreadsheet template that handles the basic formula, the finite population correction, and a bootstrap verification step will cover most routine needs. I use one that takes your raw data, your sample size, and your population size as inputs and outputs the standard error along with a bootstrap confirmation. It saves me from reinventing the wheel every time I start a new analysis. The main limitation of relying on the analytical standard error is that it assumes a known or well-estimated population standard deviation and independent sampling. When either of those fails, the formula gives you a number that looks precise but is actually misleading. In those cases, bootstrap resampling is the safer route. It is computationally slightly more expensive, but for sample sizes under a few thousand, it runs in a fraction of a second on modern hardware.
One more edge case worth mentioning. When your sample standard deviation is computed from the same data you are using to estimate the standard error, the estimate has extra uncertainty. For small samples, that matters. The standard error formula treats s as if it were the true sigma, which it is not. If your sample size is below about 30, I prefer to use the t-distribution adjusted interval rather than a plain normal interval, even though the standard error itself is still calculated the same way. The interval width changes, but the standard error estimate does not. Bottom line for anyone actually doing this work. Compute it carefully. Check independence. Apply the finite population correction when relevant. Verify with a bootstrap. Do not trust the formula when your data are clustered, heavily skewed, or small. That is where the method breaks down and where you need a different approach.