Working with Standard Error Of The Estimate in Regression
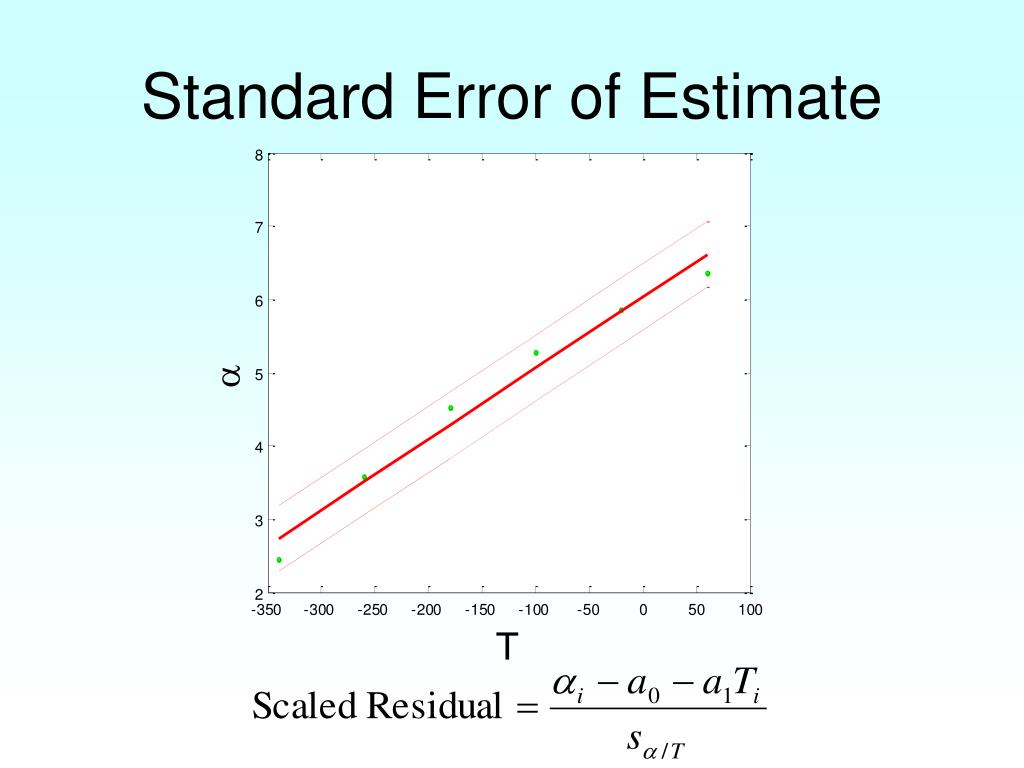
The Standard Error Of The Estimate is essentially the standard deviation of your residuals. It tells you how far your actual data points tend to sit from the regression line on average. That's the textbook version. Here's the part people rarely get right in practice: it doesn't measure predictive accuracy the way most analysts treat it. I spent years working with regression models for operational forecasting, and the first thing I learned was that a small SEE doesn't mean your model is good. It means your model is precise about something. Those are different things. I once ran a model with an SEE of 1.2 — looked fantastic on paper — and then realized the dependent variable was measured in thousands. My model was off by roughly the width of a grain of rice, which sounded impressive until you multiplied it against actual dollar figures and found it was predicting to within pennies when the real variance was in the hundreds.
Understanding Standard Error Of The Estimate
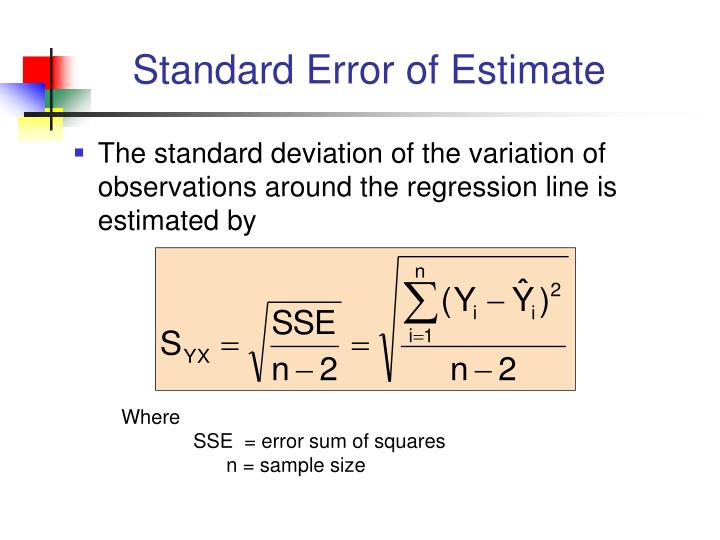
The formula itself is straightforward. You take the sum of squared differences between observed values and predicted values, divide by n minus k minus one where n is your sample size and k is your number of predictors, then take the square root. The degrees of freedom adjustment matters more than people think. With small samples, the unadjusted version will give you a biased underestimate, and you won't know it until your out-of-sample performance falls apart. What's counter-intuitive about SEE is that adding more predictors will always, always decrease it. Even junk predictors. Even random noise variables. This is one of the most common traps I see in junior analysts' work. They'll throw twelve variables into a regression, watch the SEE drop from 45 to 28, and declare victory. The model got better at fitting noise. Your out-of-sample error went the other direction entirely.
How to Calculate It Properly
Start with your regression output. Most software packages give you the residual sum of squares directly. If you're doing this by hand or in a spreadsheet, you need the individual predicted values, subtract each from the actual observation, square those differences, and sum them up. Then apply the degrees of freedom correction before taking the square root. The correction factor itself is n minus k minus 1. So with 200 observations and 3 predictors, you're dividing by 196, not 200. That two percent difference is negligible in large datasets but becomes material when you drop below fifty cases. I once had a client using what looked like Excel's default regression function on a dataset of thirty-four observations, and the SEE was underestimating by roughly four percent because the software wasn't applying the correct denominator. Fixed it by switching to the manual calculation with the proper divisor. Here's a practical workflow I've used for years now: run the regression, pull the residuals directly from the output rather than recalculating predictions yourself, compute the SEE from those residuals with the correct degrees of freedom, then immediately compare it against the standard deviation of the dependent variable. That ratio gives you an intuitive sense of whether your model is actually doing anything meaningful. If your SEE is 90 percent of the dependent variable's standard deviation, your model barely improves things over just predicting the mean every time.
Get the Full Details

Interpretation and Common Pitfalls
The SEE is expressed in the same units as your dependent variable, which makes it more intuitive than R-squared for communicating results to non-technical stakeholders. Saying "our predictions are off by about $3,400 on average" lands better than "R-squared is point-four-seven." But the units-only advantage is also where things get dangerous. SEE is completely sensitive to scaling. Multiply your dependent variable by a thousand and your SEE multiplies by a thousand too. It tells you nothing about proportional error. Another issue that bites people regularly: SEE assumes your residuals are normally distributed with constant variance across all predicted values. If you have heteroscedasticity, which is extremely common in real-world data, the SEE becomes unreliable as a summary statistic. The error might be tiny at low prediction values and massive at high ones, and SEE will report a single number that masks this entirely. I've seen this destroy forecasting models in manufacturing settings where the variance in defects increased sharply with production volume, making the SEE misleadingly low for the high-output scenarios that actually mattered to the business. The fix for heteroscedasticity is usually weighted least squares or transforming the dependent variable, most commonly taking the logarithm. Log transformations tend to stabilize variance in right-skewed data and make the SEE more meaningful across the full range of predictions. Not a perfect solution, but it's almost always better than ignoring the problem.
When SEE Fails Completely
There are situations where SEE should not be your primary metric at all. Time series data with autocorrelation is the biggest one. When your residuals are correlated over time, the degrees of freedom adjustment is wrong because the observations aren't independent, and your SEE will be systematically underestimated. You'll think your model is more precise than it actually is. In these cases, you need Newey-West standard errors or a time series modeling approach instead. I encountered this with demand forecasting for seasonal products where the auto-regressive structure made the SEE look respectable until we tested it on holdout periods and found predictions were consistently drifting in the same direction for weeks at a time. Another scenario where SEE is nearly useless is when your dependent variable has a very limited range. If you're predicting exam scores that only range from sixty to eighty, a small SEE might look impressive numerically but the model is essentially predicting within a narrow band anyway. The contextual range of your data matters enormously for interpreting what a given SEE value actually means.
Practical Comparison with Related Metrics
Root Mean Square Error is closely related but uses n in the denominator instead of n minus k minus 1. For large datasets the difference is trivial. For small samples the RMSE is slightly larger and less biased if you're describing in-sample fit, but SEE remains the standard choice for inference because it accounts for the parameters you've estimated. Mean Absolute Error is another alternative that trades the squaring for absolute values, making it less sensitive to outliers but also less mathematically convenient for optimization. I use MAE alongside SEE routinely because they tell you different things. SEE penalizes large errors more heavily due to the squaring, so if your model occasionally makes huge mistakes, SEE will reflect that while MAE stays relatively calm. There's no universal recommendation on which to prefer. It depends on whether your business costs scale linearly with error magnitude or quadratically. If being wrong by twice as much costs you twice as much, use MAE. If being wrong by twice as much costs you four times as much, use SEE. Most real-world situations fall somewhere in between, which is why looking at both simultaneously is usually the right call. The bottom line is that Standard Error Of The Estimate is a useful diagnostic tool but it's easy to misuse if you treat it as a standalone measure of model quality. Run it alongside R-squared, check your residuals for patterns, account for degrees of freedom, and always validate against out-of-sample data before trusting the number. A well-interpreted SEE can save you from building a model that looks solid in the spreadsheet and falls apart the moment it touches real data.