
The Problem Nobody Talks About When They Start Building a Statistics Workflow
Most people approach statistics like it's a subject you read about, not a process you build. You download a library, you run a few commands, and somehow you expect reproducible results at the end of it. It doesn't work that way. I've watched junior analysts spend three weeks debugging why their significance values were drifting between runs. The issue was never the math. The math was fine. The issue was that nothing was being logged, validated, or tracked between the data ingestion step and whatever output they were feeding into their report. A proper checklist isn't motivational. It's the thing that keeps you from shipping a regression analysis where you accidentally weighted your dependent variable twice because you applied a transformation before splitting your sample. I know because I did it once and spent two days chasing the error.
Why You Need the Statistics Checklist Ultimate
The Statistics Checklist Ultimate exists because the statistical workflow is long, repetitive, and unforgiving of skipped steps. It covers everything from data cleaning through to final validation. Without it, you're relying on memory. Memory is unreliable. A checklist forces the same rigor every single time, and it catches the things that kill projects quietly instead of with a loud error message. I built mine after my second project got flagged for p-hacking. Not because I was doing anything intentional. Because I ran twelve different model specifications and reported only the significant ones. The checklist now forces me to log every specification I test before I write anything down.
The Core Checklist Sections
Data Acquisition and Ingestion Every project starts here. Before you touch any analysis software, document where your data came from, what format it arrived in, and when. Record the raw file hash so you can verify it hasn't changed. If you're pulling from an API, save the request parameters and the response timestamp. This seems obvious until someone asks six months later whether the dataset is the same version they approved in the original review. I once had a stakeholder dispute a finding because they assumed I was using last quarter's data when I was actually using the current quarter's. The checklist entry for recording data source metadata would have caught this before the meeting.
Get the Full Details

Data Cleaning and Validation This is where most breakdowns happen. Missing values, duplicate records, type mismatches, and outlier definitions all need explicit decisions recorded in the checklist. Don't just drop missing rows. Decide whether you're imputing, whether you're flagging them, or whether the missingness itself is informative. Document which you chose and why. Range validation matters too. If your salary variable goes from 0 to 15,000,000 in a dataset where the mean is forty-five thousand, that extreme value either belongs to a different entity or it's a data entry error. Run frequency tables on categorical variables before you start modeling. Cross-check totals against known benchmarks when available.
Exploratory Analysis Before any formal testing, you need distributions visualized and summarized. Run descriptive statistics. Check for skew. Look at scatter plots between your key variables. You don't need fancy PCA here. You need basic counts, means, standard deviations, and correlation matrices. Write down what you see. If the exploratory phase produces surprises, those are worth noting because they shape your modeling choices and should be documented, not silently ignored. Hypothesis Formulation and Model Specification
This is the section where most people skip ahead because they already know what they want the answer to be. Write out your null and alternative hypotheses before you run a single test. Specify your model type, your predictors, your expected directionality, and your significance threshold. If you're doing multiple comparisons, decide on your correction method upfront. Bonferroni is conservative but honest. Holm-Bonferroni gives you more power while maintaining family-wise error control. Decide before you look at the results. Assumption Checking Linear regression requires linearity, independence of residuals, homoscedasticity, and normality of residuals. Logistic regression has its own set: linearity of logits, absence of multicollinearity, independence of observations, and adequate sample size per predictor. Don't just run the model and assume the output is valid. Check the diagnostics. Plot residuals against fitted values. Run VIF scores for multicollinearity. Shapiro-Wilk or Q-Q plots for normality assumptions. This takes about ten minutes and saves you from publishing a result that falls apart under peer review.

Model Fitting and Diagnostics Fit your models. Record convergence status. Note any warnings. If you're using iterative algorithms, set and log the seed for reproducibility. Compare alternative specifications. AIC, BIC, cross-validation error rates — these are tools for model selection, not for confirming your preferred model. Let the metrics decide. Interpretation and Reporting
Report confidence intervals alongside point estimates. Report effect sizes, not just p-values. A statistically significant result with a tiny effect size is often practically meaningless. Context matters. If your odds ratio is 1.03 with a p-value of 0.001, the effect is real but negligible in most practical terms. State both. Include your checklist version number in any deliverable so reviewers can trace your process.
Common Pitfalls That Skip By Undetected
Here are things I've seen go wrong repeatedly, none of which are covered in introductory textbooks. Temporal leakage. If your data has any time component, make sure your train-test split respects chronological order. Shuffling time-series data destroys the temporal structure and gives you inflated performance estimates. I saw a forecasting model claim 94% accuracy because the validation set contained observations from before the training period. The model was learning the future. Multiple testing without correction. Run enough comparisons and you'll find significance by chance. The more subgroup analyses you do, the more likely you are to report a false positive. This is the file drawer problem in action. Pre-register your primary hypothesis and treat everything else as exploratory. Label it clearly in your report.
Cocktail party analysis. Running multiple imputation methods, trying different transformations, and then picking whichever version gives the prettiest result is not science. It's fishing. The checklist requires you to commit to your preprocessing pipeline before you see the outcome distribution. If the cleaned data looks ugly, fix the data, not the analysis. Simpson's paradox blindness. Aggregated data can show the opposite trend of stratified data. Always check whether your apparent relationship holds within subgroups. I had a project where the overall correlation between study hours and exam scores was near zero. Once we controlled for course difficulty level, the relationship was strongly positive. The aggregate mask hid a real effect entirely.
How to Actually Use This Checklist Without It Becoming Busy Work
The biggest complaint I hear about checklists is that they slow you down. That's true the first time you use it. After that, it's faster than figuring out what you forgot. The trick is to make it a living document, not a rigid form. Version it. Add entries when you encounter new edge cases. Remove entries that become unnecessary as your tools improve. I keep mine in a plain text file with a simple header for each project. The header records date, data source, checklist version, and any deviations from the standard flow. Deviations are important. If you skip an assumption check because the data is continuous and normally distributed by construction, write that down. The checklist isn't about blind compliance. It's about intentional decision-making.
Statistics Checklist Ultimate Download
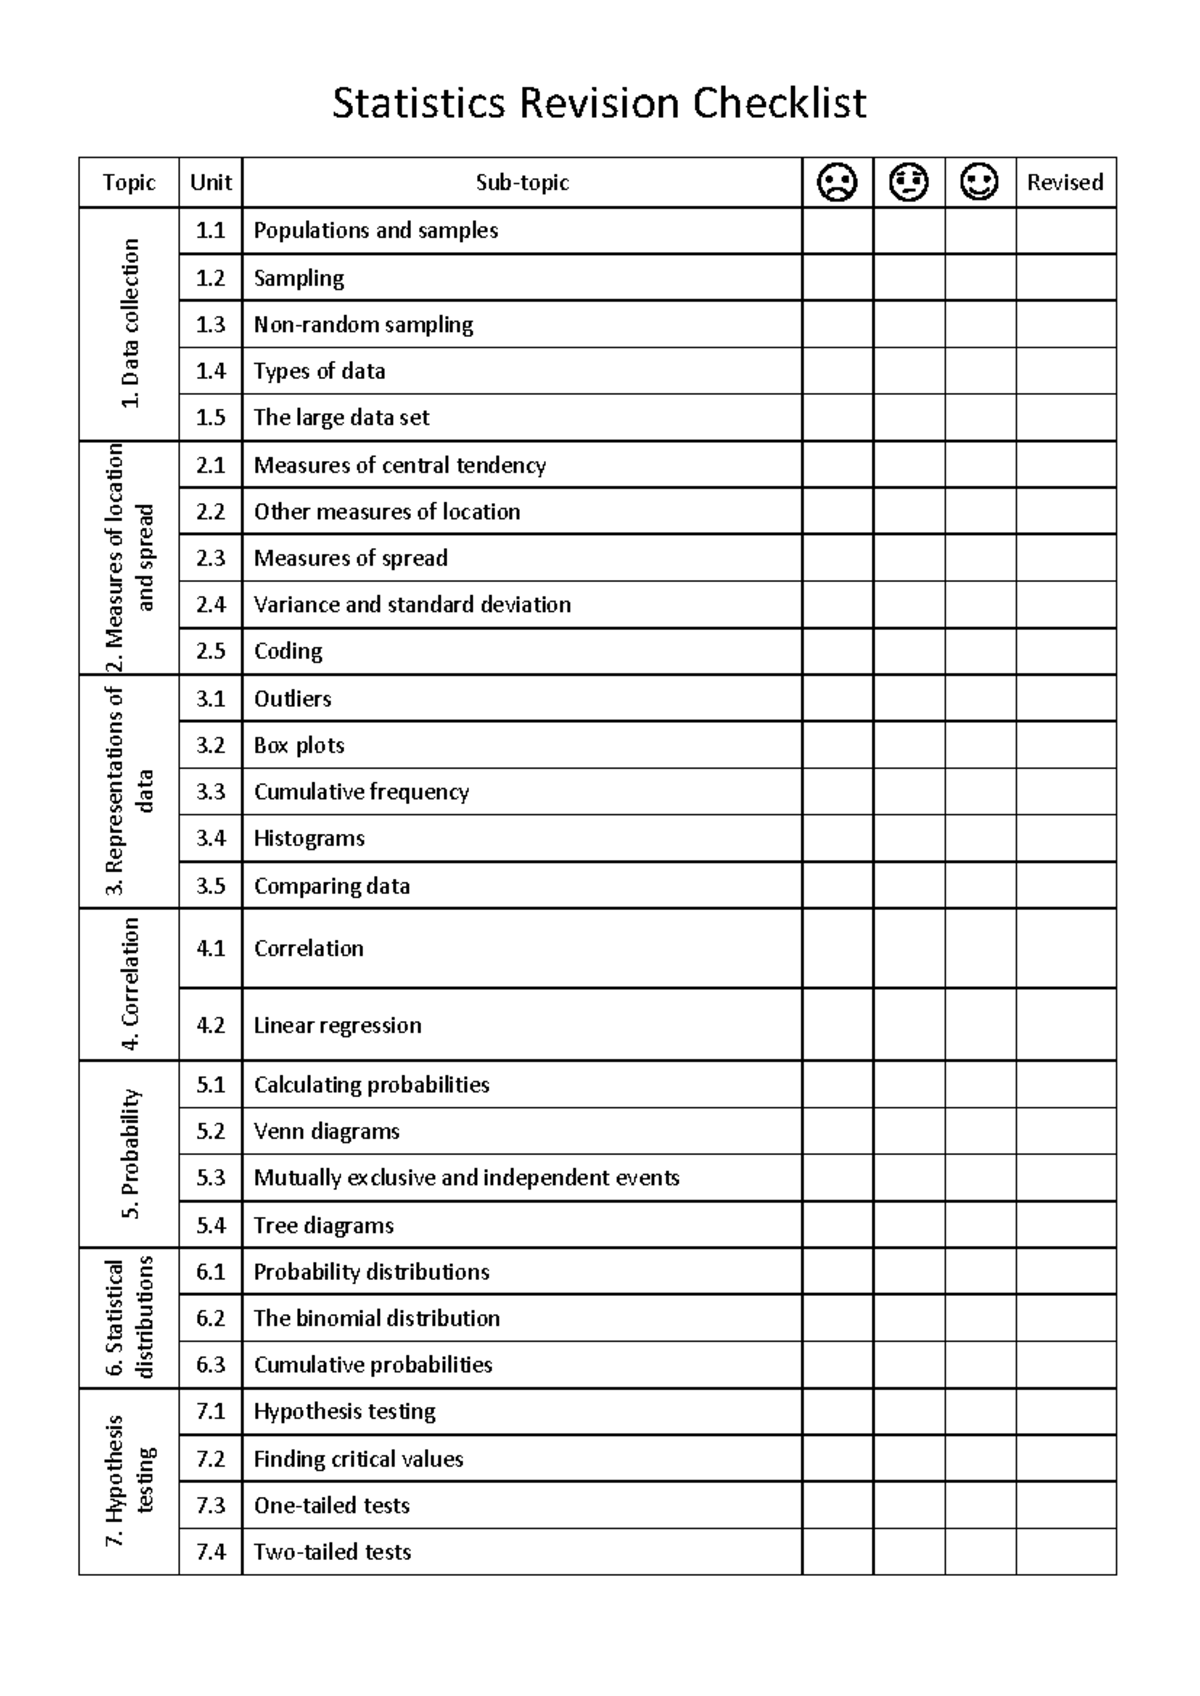
The full checklist is structured as a markdown file with sections matching the workflow stages outlined above. It includes decision trees for common scenarios — what to do when assumptions are violated, how to choose between parametric and non-parametric tests, and when to involve a domain expert versus running a diagnostic yourself. There's also a companion validation appendix that lists the exact R and Python code snippets for each assumption check, so you're not rewriting them from scratch every project. The current version covers univariate analysis, bivariate testing, regression modeling, time-series diagnostics, and Bayesian basics. Non-parametric methods are still being expanded. If you need chi-square exact tests or permutation-based approaches, those entries are marked as in-progress with references to the standard implementations.

What This Checklist Won't Fix
It won't save you from bad study design. If your sample is biased, no amount of statistical rigor will correct that. It won't compensate for unclear research questions or poorly defined variables. It also doesn't replace knowing your domain. The checklist tells you to check for outliers. It doesn't tell you whether that outlier is a data error or a genuinely important edge case that your model should actually be capturing. The checklist is a safety net, not a substitute for judgment. Use it alongside peer review, pre-registration where possible, and honest reporting of limitations. The best analyses I've seen were the ones where the authors explicitly listed what they couldn't conclude from their data, not the ones that made confident claims beyond what the numbers supported.

