What Statistics Examples Quick Actually Means in Practice
People throw this phrase around without defining it, and it ends up covering three different things depending on who you ask. Some treat it as a shortcut method for small sample work. Others use it to mean running reference tables by hand instead of relying on software. A third group means literally any worked example pulled from a textbook chapter. The confusion is real and it causes people to apply formulas wrong because they assume a distribution that isn't there. Statistics Examples Quick tends to come up when someone needs a fast sanity check before committing to a full analysis pipeline. I've seen analysts open a calculator, plug in n=14 and x=7, and declare a result without checking whether the data actually satisfy the test assumptions. That's not a quick example. That's a rushed guess wearing a lab coat.
Statistics Examples Quick: the practical version
The useful version is this: a concrete worked problem with visible inputs, a stated method, and an explicit note about where the method breaks down. Everything else is noise. When you see a proper example laid out like that, you can reuse the structure on your own data in under ten minutes. Skip the structure and you spend forty-five minutes debugging why your p-value looks wrong. I ran into this last year on a quality control project. We had batch counts that were heavily right-skewed with a long tail of outliers past the upper specification limit. Someone posted a standard normal example online claiming it applied directly. It didn't. The workaround I ended up using was a simple log-transform followed by a one-sample t-test on the transformed values, with the back-transformed confidence interval reported as the final answer. It took about six minutes once I stopped trying to force the raw numbers through a z-table.
Basic examples that actually hold up
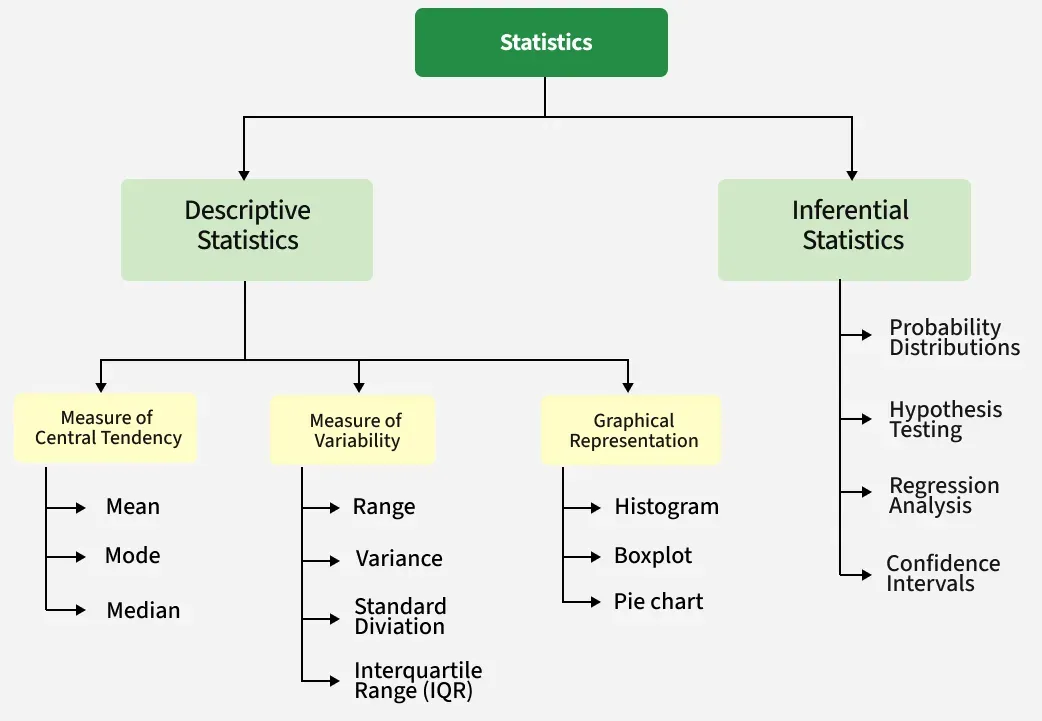
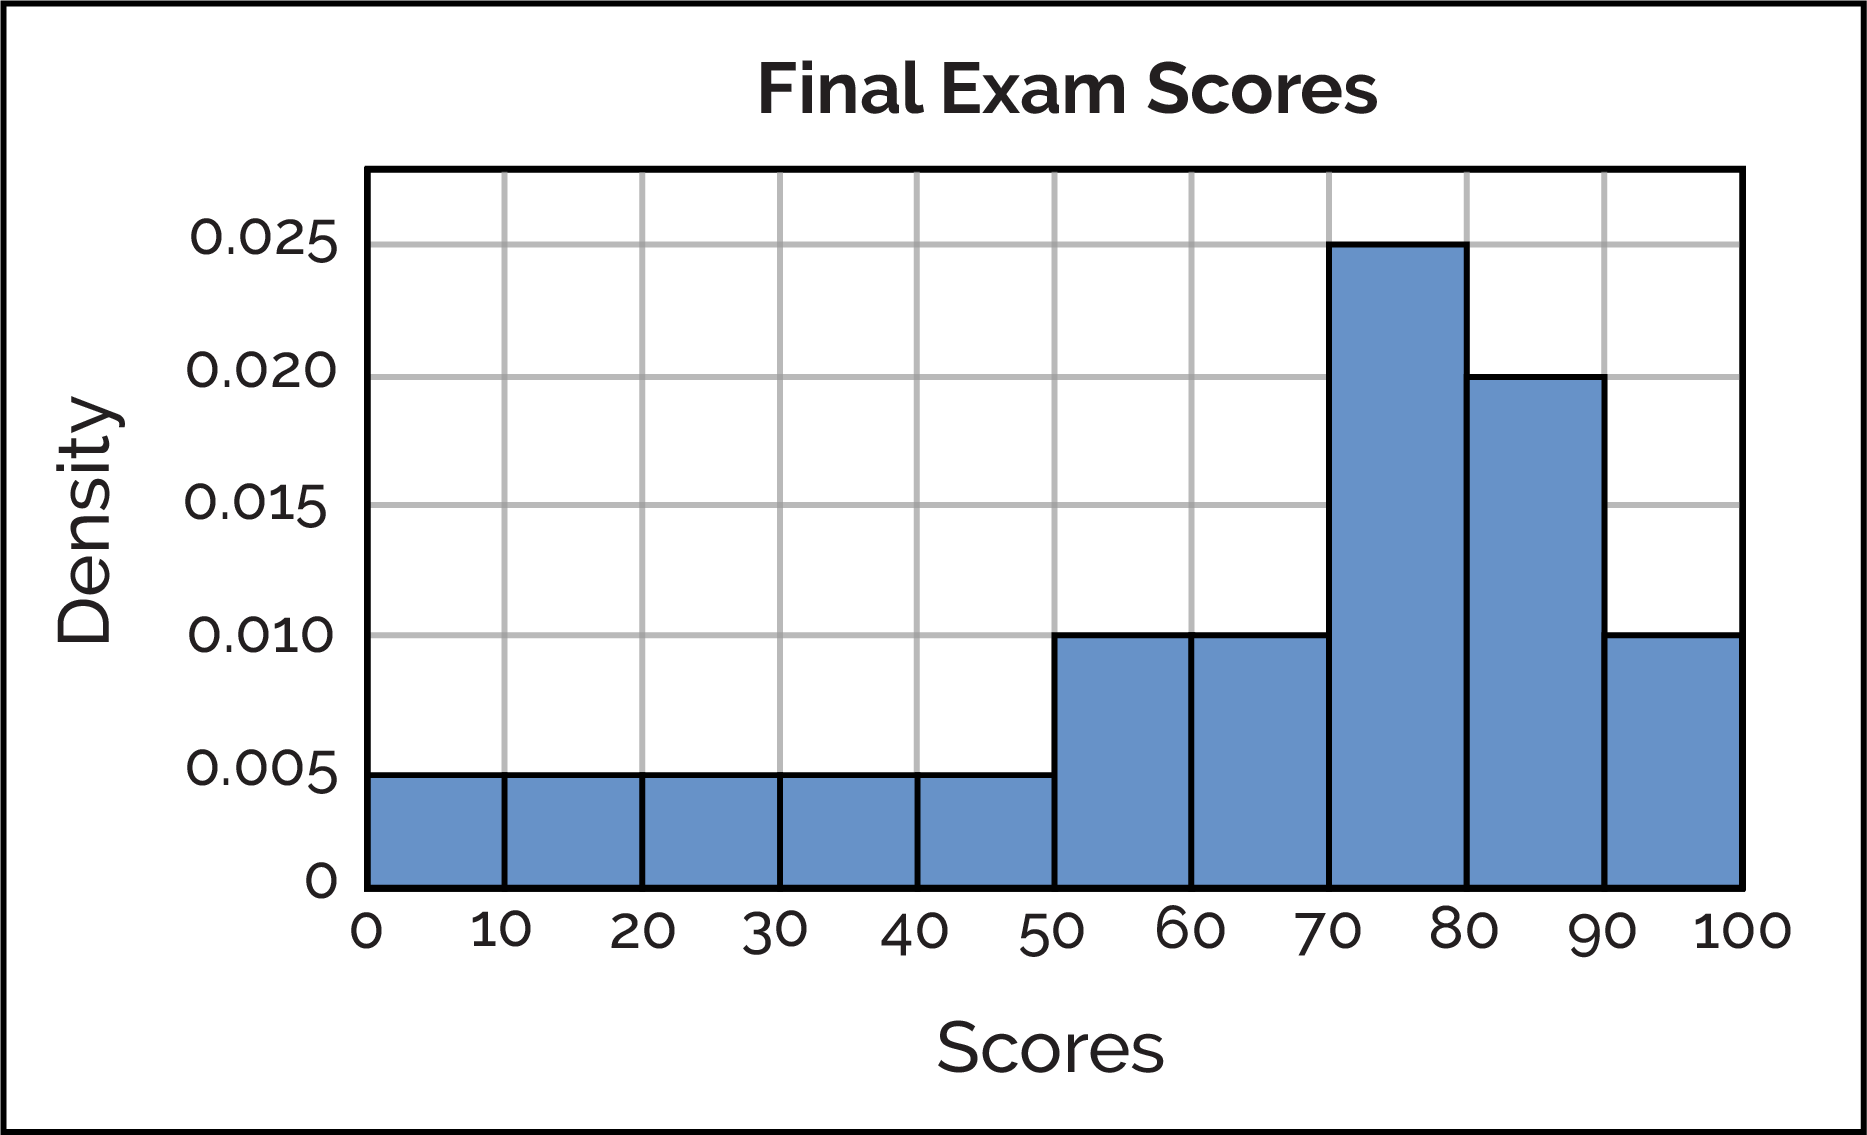
Start with descriptive stats. Take a dataset, compute mean, median, standard deviation, and quartiles. If you are doing this by hand, use a basic handheld calculator with a statistical mode. Modern calculators handle this in seconds. Excel or Google Sheets do it faster still. Don't skip the quartiles just because they look optional. I've watched people build regression models on trimmed data without noticing the outliers first, then wonder why their residuals behaved badly. Here is a clean, minimal example:
Get the Full Details

- Data: 3, 7, 7, 8, 12, 15, 19, 22, 22, 28
- n = 10
- Mean = 14.1
- Median = 13.5
- Standard deviation 7.54
- Q1 = 7, Q3 = 22
That's it. Nothing dramatic. But it tells you the distribution is slightly right-skewed because the mean exceeds the median, and the interquartile range spans 15 units while the full range spans 25. Use that before jumping into inference. This is where most people trip up. The rule is simpler than textbooks make it sound. If the population standard deviation is known, use a z-test. If you are estimating sigma from the sample, use a t-test. The difference shrinks as n grows, but for n below roughly 30 it matters. Using a z-table for small n gives you a false sense of precision. Example: a manufacturer claims a wire diameter has mean 2.00 mm and standard deviation 0.05 mm. You take a sample of 9 wires and get a sample mean of 2.03 mm. Because sigma is stated by the manufacturer and not estimated from your sample, a one-sample z-test is appropriate here. The test statistic is (2.03 - 2.00) / (0.05 / sqrt(9)) = 1.8. Compare that against the z critical value for your alpha level. If sigma were unknown and you used s = 0.06 from the sample instead, the correct path is a t-test with 8 degrees of freedom, and the critical value would be larger, reflecting more uncertainty.
People routinely swap these. It happens because the z-table is easier to find in older handbooks. The cost is a biased error rate. For alpha = 0.05 two-tailed, the t critical value with df = 8 is about 2.306. The z critical value is 1.96. That gap is wide enough to change a rejection decision in borderline cases.
Chi-square goodness-of-fit done cleanly
Another common case where Statistics Examples Quick shines is the chi-square test for categorical data. The setup is straightforward: observed counts, expected counts under a null hypothesis, then sum (O - E)^2 / E across all categories. The catch is that expected counts should generally be at least 5 per cell. If they aren't, the approximation breaks down and you should either combine adjacent categories or use an exact test. I had a situation where we were testing whether a die was fair. There were six faces, and we rolled it 60 times. Expected count per face is 10, which is fine. Suppose the observed counts were 8, 12, 7, 11, 9, 13. The chi-square statistic is (8-10)^2/10 + (12-10)^2/10 + (7-10)^2/10 + (11-10)^2/10 + (9-10)^2/10 + (13-10)^2/10 = 0.4 + 0.4 + 0.9 + 0.1 + 0.1 + 0.9 = 2.8. With 5 degrees of freedom, the critical value at alpha = 0.05 is 11.07. We fail to reject. The die looks fair enough for casual use. If we had only 12 total rolls, expected counts would be 2 per face, and the chi-square approximation would be suspect. In that case, I switch to an exact multinomial test or just simulate the distribution. That usually takes less time than arguing with a table that doesn't apply.
Confidence intervals without overcomplicating them
A confidence interval is not a probability statement about the parameter. It is a statement about the procedure. People confuse this constantly. The correct interpretation is that if you repeated the sampling process many times and built an interval each time, roughly 95 percent of those intervals would cover the true parameter. The parameter is fixed. The interval varies. For a single mean with unknown sigma and moderate sample size, the interval is x-bar ± t_(alpha/2, df) * s / sqrt(n). That formula covers most routine cases. Just verify that the data aren't wildly non-normal when n is small. If they are, consider a bootstrap interval instead. It takes longer to compute by hand but works better on skewed data.
Quick reference for common Statistics Examples Quick workflows
Keep this near your workspace. It cuts the setup time on standard problems from five minutes down to about thirty seconds. The column labeled common pitfall is worth more than the method column. That is where people lose time. You don't need a full software suite to understand simple linear regression mechanics. Given paired data, the slope is r * (s_y / s_x), and the intercept is y-bar minus slope times x-bar. The standard error of the slope feeds directly into the t-statistic for testing whether the slope differs from zero. That is the core. Everything else is implementation detail.
I used to have a messy spreadsheet where someone stored every intermediate product of the least-squares calculation and it broke whenever a new row was added. The fix was to use a single array formula for the slope and let the regression output handle the rest. It reduced the file size and eliminated a class of rounding errors that had been silently shifting the confidence interval by a fraction of a unit. Small thing, noticeable difference when you're presenting to stakeholders.

Nonparametric options when assumptions fail
Parametric tests are convenient, but they demand assumptions. If your data are heavily skewed, contain outliers, or come from an ordinal scale, a nonparametric alternative is often the right call. The Mann-Whitney U test replaces the two-sample t-test for independent groups when normality is doubtful. The Wilcoxon signed-rank test replaces the paired t-test. The Kruskal-Wallis test generalizes to three or more groups. These are not fallbacks out of laziness. They are better fits for certain data structures. One thing beginners miss: nonparametric tests do not test medians by default. They test whether distributions differ in location or shape depending on the specific test. Claiming a median difference without checking the shape assumption is a common error in applied work. I've corrected this in peer reviews more times than I care to count.
Power and sample size, the easy way
Running a power calculation doesn't require an advanced degree. You need five inputs: alpha, desired power, effect size, sigma or proportion difference, and whether the test is one- or two-tailed. From there you either solve for n or look it up in a table. G*Power handles the computation in seconds. If you need a rough hand calculation for a two-sample t-test with equal variances, an approximation is n per group 16 * sigma^2 / delta^2 for 80 percent power and alpha = 0.05 two-tailed, where delta is the mean difference you want to detect. It is not exact, but it puts you in the right neighborhood before you hand the work to software. The downside of this shortcut is that it assumes equal variance and normality. When those fail, the true required n can be substantially larger. I learned that the hard way on a clinical trial where the outcome was skewed. The power calculation said 64 participants total. The actual study needed over 100 because the effect size estimate shifted under transformation.
Where this approach fails outright
Quick examples break down when the data have complex dependence structures, like repeated measures, cluster sampling, or time series autocorrelation. A standard two-sample t-test on clustered data underestimates standard errors and inflates Type I error. The fix is mixed models or generalized estimating equations, which are not quick in the same sense. You also hit limits with rare events. Logistic regression with sparse binary outcomes can be unstable, and exact methods are slower and less commonly available in basic toolkits. If you find yourself in either of those zones, stop calling it a quick example and plan the analysis properly. Rushing these cases produces results that look plausible and are wrong in ways that are hard to detect afterward.
Statistics Examples Quick for day-to-day work
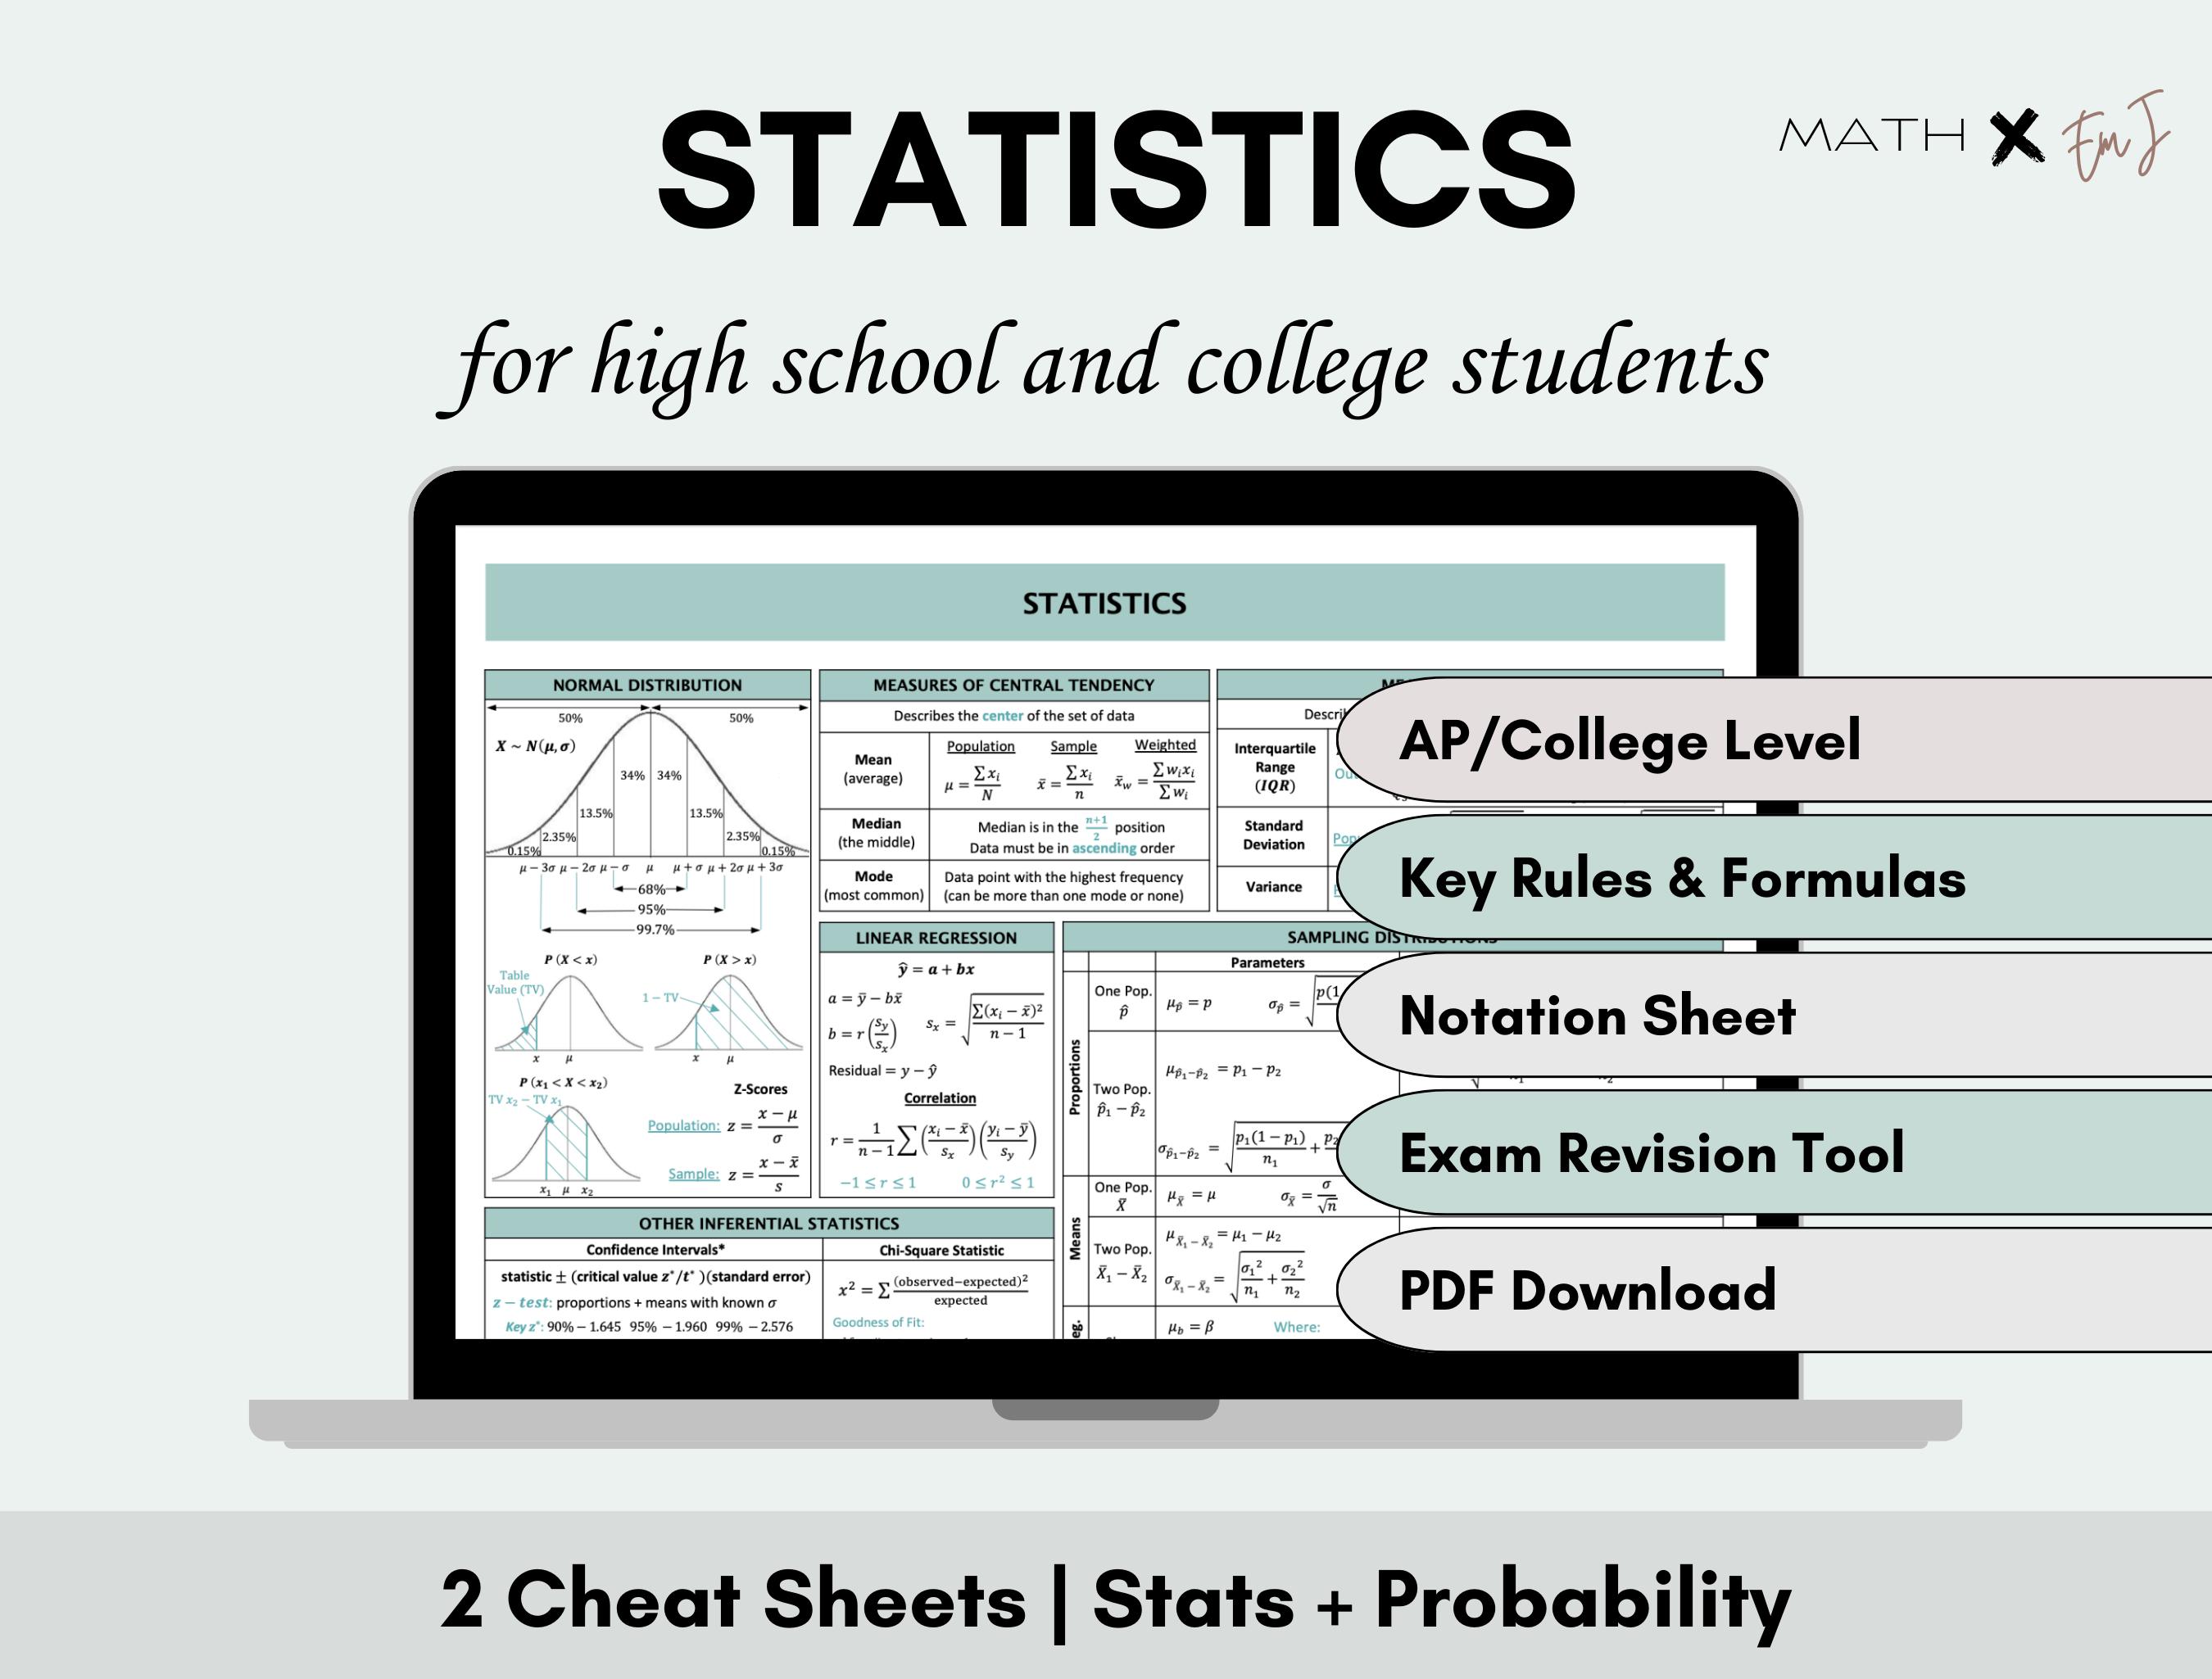
The practical takeaway is that you can move through standard problems efficiently if you keep the assumptions visible and the fallback options ready. Most routine work falls into the first six rows of the table above. Beyond that, slow down and pick the right tool. Speed comes from knowing where the shortcuts are safe and where they are not. I keep a one-page reference with the most common test selection rules, the expected-count threshold for chi-square, and the rule of thumb for t versus z. It reduces decision time and cuts the chance of posting a result that later requires a correction. That is the real value of working quickly and carefully at the same time.