Working Through Basic Statistical Analysis
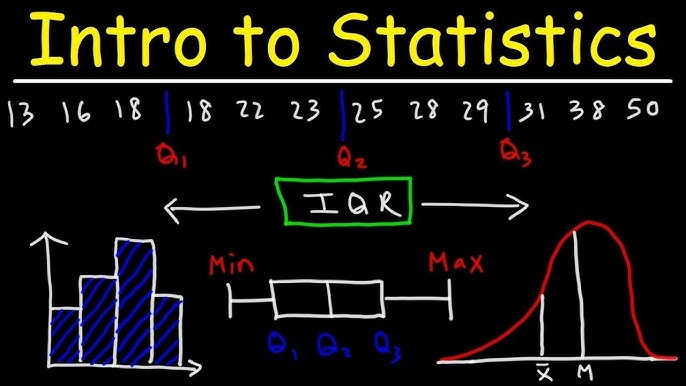
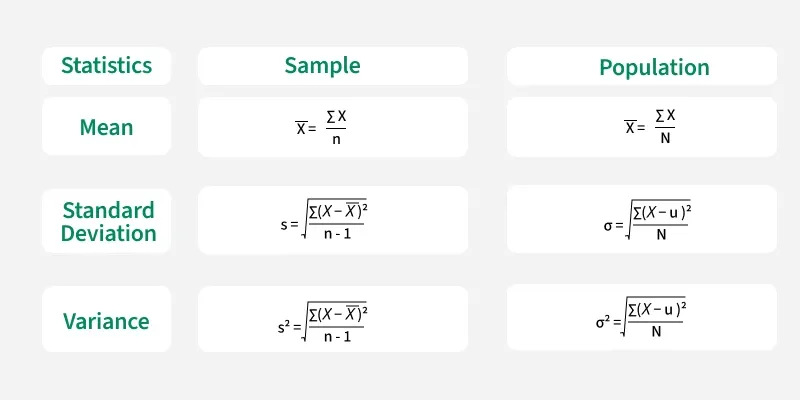
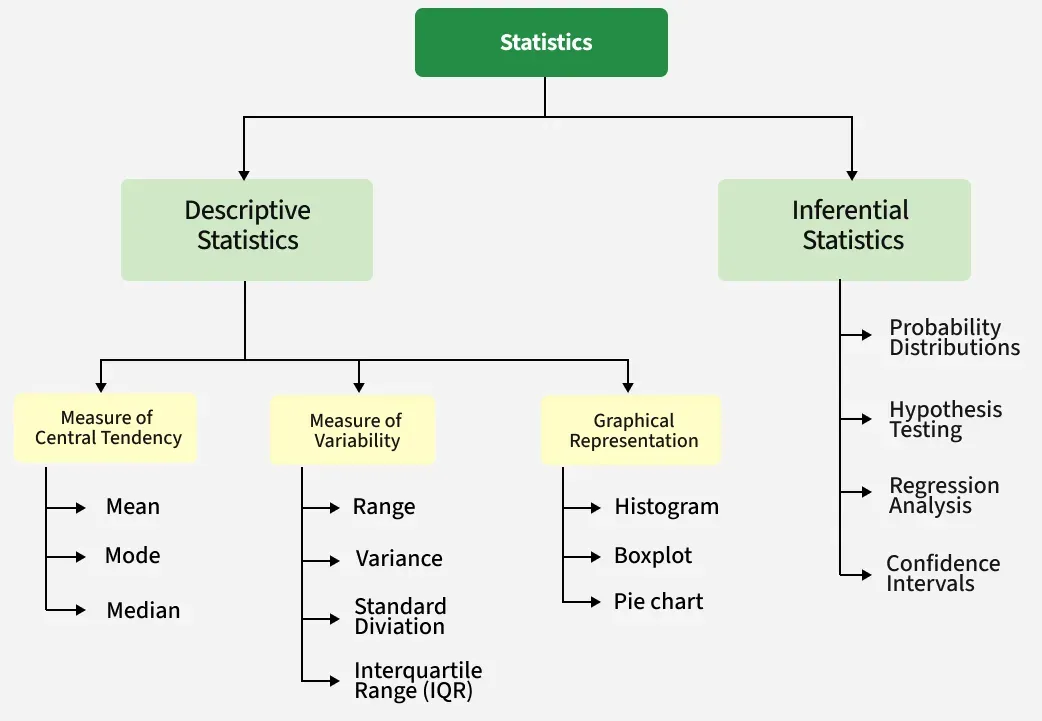
Statistics Examples Simple is exactly what it sounds like. It is a resource for people who need to understand how basic statistical methods work without wading through pages of theoretical proofs. I found myself coming back to straightforward examples more often than any textbook, mostly because I was dealing with real data that refused to behave like textbook problems. Let me explain the approach first since that is what actually matters. You start with your raw data and you organize it. That means cleaning outliers, checking for missing values, and making sure you know what variable is independent and which one is dependent. Most people skip this part because it is boring, and that is where things go wrong. You end up with results that look correct on paper but fall apart the moment someone asks a follow-up question about the methodology. Descriptive statistics is where you begin. This involves calculating measures like mean, median, mode, standard deviation, and range. These numbers summarize your dataset. If you have 100 observations, these statistics tell you where the center is and how spread out the data points are. That is useful on its own, but it is only the first step.
Understanding Statistics Examples Simple
The practical value of simple statistics examples comes when you see them applied to actual scenarios. I once worked with a client who had survey data from roughly 400 respondents about product satisfaction. The question was straightforward: did a price change affect satisfaction? Running a basic t-test seemed like the obvious move. The data passed the normality check using Shapiro-Wilk, the variances were approximately equal based on Levene's test, so an independent samples t-test was appropriate. But here is the thing most guides do not tell you clearly: even when your assumptions are met, the effect size matters more than the p-value. In that project, the p-value came back at 0.003, which looks significant at first glance. But Cohen's d was only 0.12, meaning the actual difference in satisfaction scores between the two price groups was negligible in practical terms. We told the client the change had no meaningful impact despite the statistically significant result. They would have made a different decision if they had only looked at the p-value. Another example that comes up constantly is correlation. People see two variables moving together and immediately assume causation. A scatter plot showing a strong positive correlation between ice cream sales and drowning incidents is the classic case. Temperature is the confounding variable. Running Pearson correlation gives you a number, usually r, that tells you the strength and direction of the linear relationship. But correlation alone never proves cause and effect. I would recommend adding a partial correlation or multiple regression analysis to control for that confounding variable before drawing any conclusions.
Running Common Tests Step by Step
Chi-square tests are another area where beginners make mistakes. You use them for categorical data to see if there is a relationship between two variables. Say you want to know if gender and voting preference are related. You collect your counts, build a contingency table, and run the test. The output gives you a chi-square statistic and a p-value. If the p-value is below your alpha level, typically 0.05, you reject the null hypothesis. But you need to check the expected frequencies. If more than 20 percent of your cells have expected counts below five, the chi-square test becomes unreliable. In that case, Fisher's exact test is the better option, though it gets computationally heavy with larger tables. Regression analysis is where simple statistics get more complicated quickly. Linear regression fits a line through your data points to model the relationship between a dependent variable and one or more independent variables. The equation is y = mx + b for simple linear regression with one predictor. The slope m tells you how much y changes for each unit increase in x. The intercept b is where the line crosses the y-axis. R-squared tells you what percentage of the variation in y is explained by x. An R-squared of 0.65 means 65 percent of the variability in your outcome is accounted for by your predictor. The remaining 35 percent comes from other factors or random noise. One thing about regression that trips people up regularly: adding more predictors will always increase R-squared, even if those predictors are meaningless. That is why adjusted R-squared exists. It penalizes you for adding unnecessary variables. If you are building a model and the adjusted R-squared drops after adding a new predictor, that predictor is probably not helping your model at all. Stick with the simpler model.
Get the Full Details
Common Pitfalls to Avoid
P-hacking is one of the most damaging practices in applied statistics. This happens when you run multiple tests on the same dataset until something comes out significant, then report only that result. If you run 20 independent tests at alpha = 0.05, you should expect one of them to be significant purely by chance. That does not mean you found a real effect. The fix is straightforward: pre-register your hypotheses and your analysis plan before you look at the data. If that is not possible, apply a Bonferroni correction by dividing your alpha level by the number of tests you are running. For 10 tests, your new alpha becomes 0.005 instead of 0.05. Small sample sizes create another set of problems. With fewer than 30 observations, the Central Limit Theorem does not apply reliably, and your confidence intervals become very wide. A 95 percent confidence interval around a mean of 50 with a small sample might stretch from 30 to 70. That is barely informative. You can use bootstrapping to generate more stable estimates with small datasets, but even then, the estimates are less reliable than what you would get with a larger sample. If you are working with limited data, be transparent about the uncertainty.
Statistics Examples Simple for Quick Reference
When you need to look something up quickly, having clear examples helps more than reading dense methodology sections. Here is a quick breakdown of the most common tests and when to use them. T-test: comparing means between two groups. Independent samples t-test for separate groups. Paired t-test for before-and-after measurements on the same subjects. ANOVA: comparing means across three or more groups. One-way ANOVA for a single factor. Two-way ANOVA when you have two independent variables. Post-hoc tests like Tukey's HSD are needed after a significant ANOVA to determine which specific groups differ from each other.
Mann-Whitney U test: the non-parametric alternative to the independent samples t-test. Use this when your data is not normally distributed. It compares whether two independent groups come from the same distribution. Kruskal-Wallis test: the non-parametric alternative to one-way ANOVA. Three or more groups with ordinal or non-normal continuous data. These tests cover the majority of everyday analysis situations. When your data structure gets unusual, like clustered data or repeated measures with more than two time points, you need more advanced techniques like mixed-effects models or generalized estimating equations. Those go beyond what Statistics Examples Simple typically covers, and that is fine. Understanding when a method stops working for your data is just as important as knowing how to apply it.
The real learning happens when you take an example, find a similar dataset, and work through the analysis yourself. Download some public data from sources like Kaggle or government open data portals, pick a question you want to answer, and apply the appropriate test. You will run into issues that no example can fully prepare you for, like imbalanced groups or violated assumptions, and that is normal. Working through those problems is what actually builds competence. After a while, the process becomes mechanical, and you can focus on the interpretation instead of the calculation. I keep a basic checklist for every analysis I run now. Data cleaned and documented. Assumptions checked. Test selected and justified. Results recorded with both statistical significance and practical significance noted. Effect size calculated. Limitations acknowledged. It takes maybe ten extra minutes per project, but it has saved me from making embarrassing mistakes more times than I can count. The checklist also makes it easier to explain your methodology to someone else when they ask how you arrived at a conclusion. That usually happens after you have submitted your findings, not before.