How Stem-and-Leaf Plots Actually Work
A stem-and-leaf plot is a way to display numerical data where each value gets split into two parts: the leading digit(s) become the stem and the final digit becomes the leaf. It is essentially a histogram that lets you see individual data points instead of just bars. The visual structure looks like a vertical list where stems run from top to bottom and leaves fan out to the right. You read it by combining each stem with its corresponding leaves. So a stem of 3 with leaves 1, 4, and 7 represents the numbers 31, 34, and 37.
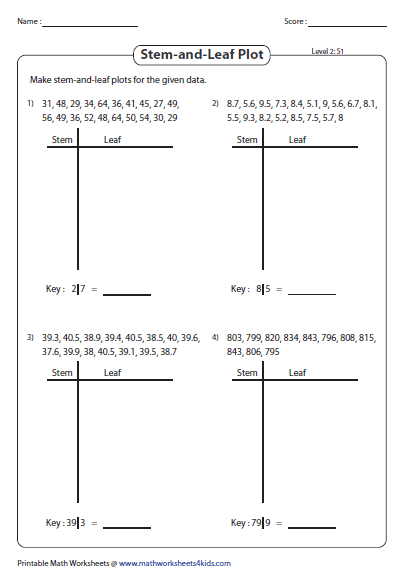
Working With Stem And Leaf Graph Worksheets
Most worksheets give you a raw list of numbers and ask you to construct the plot, then answer questions about the shape of the distribution. The first step is always finding the range. Subtract the smallest value from the largest to understand the spread. Then pick your stem unit. If your data runs from 12 to 98, single-digit stems from 1 through 9 work fine. If your data goes from 147 to 283, you would use stems for 14 through 28, which means treating the tens and hundreds digits as the stem group.
I once had a dataset where every value fell between 6 and 14, and the decimal point made everything messy. Values like 6.2, 7.8, 8.0, 8.3, and 9.5 are the kind of thing that throws people off because they do not neatly fit a whole-number stem system. My workaround was straightforward: I multiplied every value by 10 to eliminate the decimal, plotted 62, 78, 80, 83, 95 using stems of 6, 7, 8, and 9, then clearly labeled the stem unit as "tens" and the leaf unit as "ones" so anyone reading it understood the scale. That labeling step is something almost nobody includes on worksheets, and it is exactly what causes confusion later when someone tries to reconstruct the original data.
The ordering of leaves matters more than students realize. Every stem should have its leaves listed in ascending order. A worksheet answer key will often mark down a plot that has the right data but unordered leaves, even though the underlying information is identical. This is a pedantic grading convention, not a mathematical necessity, but it is one you need to know about early.
Key Structural Considerations
Stem-and-leaf plots have a built-in assumption that the data has consistent magnitude. When you mix values that span multiple orders of magnitude, the plot collapses into awkward empty rows. Data like 3, 45, 678, and 9102 should never be forced into a single stem-and-leaf plot because the stems become meaningless. In those cases, a box plot or a logarithmic transformation is the better choice. The plot is most useful when your data sits in a fairly narrow band, typically within one or two orders of magnitude of each other.
Another thing that trips people up is the decision of whether to split stems. If you have a lot of data concentrated in one range, a single stem can end up with twelve or thirteen leaves, which makes the plot hard to read. Splitting each stem into two rows solves that problem. One row holds leaves 0 through 4, and the other holds leaves 5 through 9. This doubles the number of rows but gives you much clearer density information. On a standard worksheet, you are usually told not to split stems, but in real work, splitting is often the only way to make the visualization useful.
I ran into this exact issue when helping someone analyze a set of test scores that clustered heavily in the 70s and 80s. Without splitting stems, those two stems were drowning in leaves while the lower and upper ranges sat nearly empty. After splitting, the distribution became immediately readable and the outliers jumped out without any extra calculation. It is a small change that makes a big difference for anything beyond textbook examples with small datasets.
Reading the Distribution Shape
One of the main reasons teachers assign these plots is to help students recognize skewness and clusters. A symmetric distribution has roughly equal leaf density on both sides of the center stem. A right-skewed distribution has a long tail of leaves extending toward the higher stems. A left-skewed distribution does the opposite. Clusters appear as dense groups of leaves across consecutive stems, while gaps show up as stems with no leaves at all between stems that do have data.
Identifying the median from a stem-and-leaf plot is one of its practical advantages. You count leaves from the top until you reach the middle value, then count from the bottom in the same way. You do not need to recalculate anything or rearrange the data, which is already sorted by construction. Finding the mode is equally direct. The stem with the most leaves represents the modal range. If a single leaf value repeats most often across all stems, that is your mode.
Common Mistakes to Watch For
The most frequent error is forgetting to sort the leaves within each stem before finalizing the plot. Students will often write leaves in the order the numbers appear in the original data, which defeats the entire purpose of the exercise. The plot is supposed to make the data ordered automatically.
Another common error is mislabeling the scale. A stem of 5 with a leaf of 3 could mean 53, 5.3, or 530 depending on the data. The worksheet should always include a key line somewhere that clarifies this, such as "5 | 3 = 53." If the key is missing, the plot is technically incomplete.
The decimal placement issue deserves more attention than it typically gets. When working with decimals, some educators treat the digits to the left of the decimal as the stem and the first digit after the decimal as the leaf. Others multiply everything by 10 or 100 first. Both approaches produce valid plots as long as the stem unit is clearly stated. The inconsistency between methods is a real source of confusion for students who encounter different conventions in different textbooks.
When This Method Breaks Down
Stem-and-leaf plots do not scale well. Once your dataset exceeds a few hundred values, the plot becomes visually cluttered and loses its readability advantage over a histogram. There is no practical benefit to using one for large datasets, and the time spent constructing it manually is wasted when software can generate a proper frequency distribution in seconds.
Negative numbers also create a structural problem. Most introductory worksheets never address this because the convention for handling negative stems is not standardized across curricula. Some systems place negative stems above positive ones with absolute values increasing downward. Others separate the negative and positive portions entirely. If your data includes negative values, you will need to establish a consistent convention yourself and document it clearly, or the plot will be ambiguous to anyone reading it.
For categorical or mixed data, the method simply does not apply. It only works with quantitative data that has a natural numeric ordering. If you are working with anything else, you should move directly to bar charts or other appropriate visualizations rather than forcing a fit.