Data science workflows don't need to be complicated
Most people I talk to who are starting out spend weeks trying to memorize frameworks instead of actually getting data cleaned and models built. I learned that the hard way back in 2016 when I was working on a churn prediction project for a mid-size telecom company. We had a team of four data scientists who spent six weeks setting up a elaborate MLOps pipeline with Kubernetes and Airflow before anyone touched the actual dataset. The pipeline broke on day 37 and we were no closer to a working model than when we started. The reality is that you can get from raw CSV to a trained model in a single afternoon if you strip away the ceremony. I wrote a small guide called Step By Step For Data Science Quick after I realized how many people were getting stuck on tool selection instead of progress. It covers the actual sequence I use now, which has changed very little over the past five years.
Step By Step For Data Science Quick
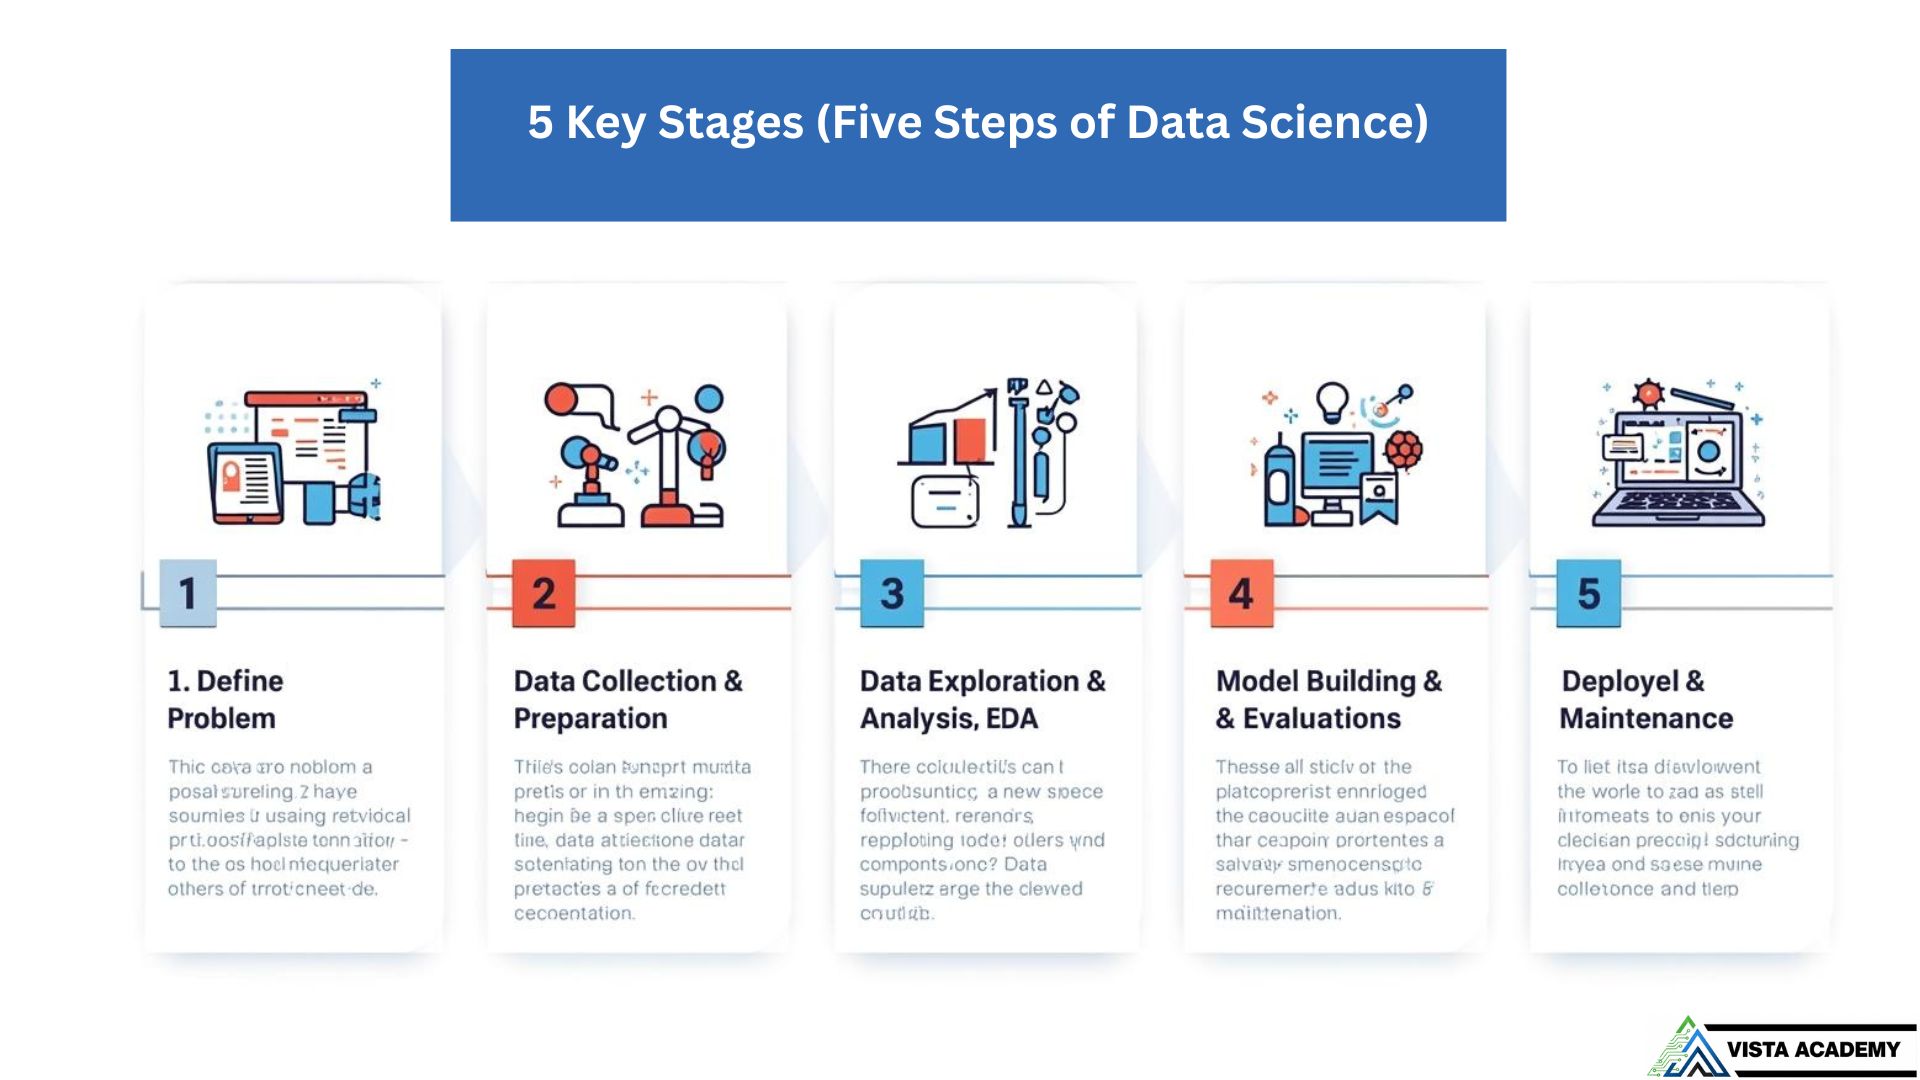
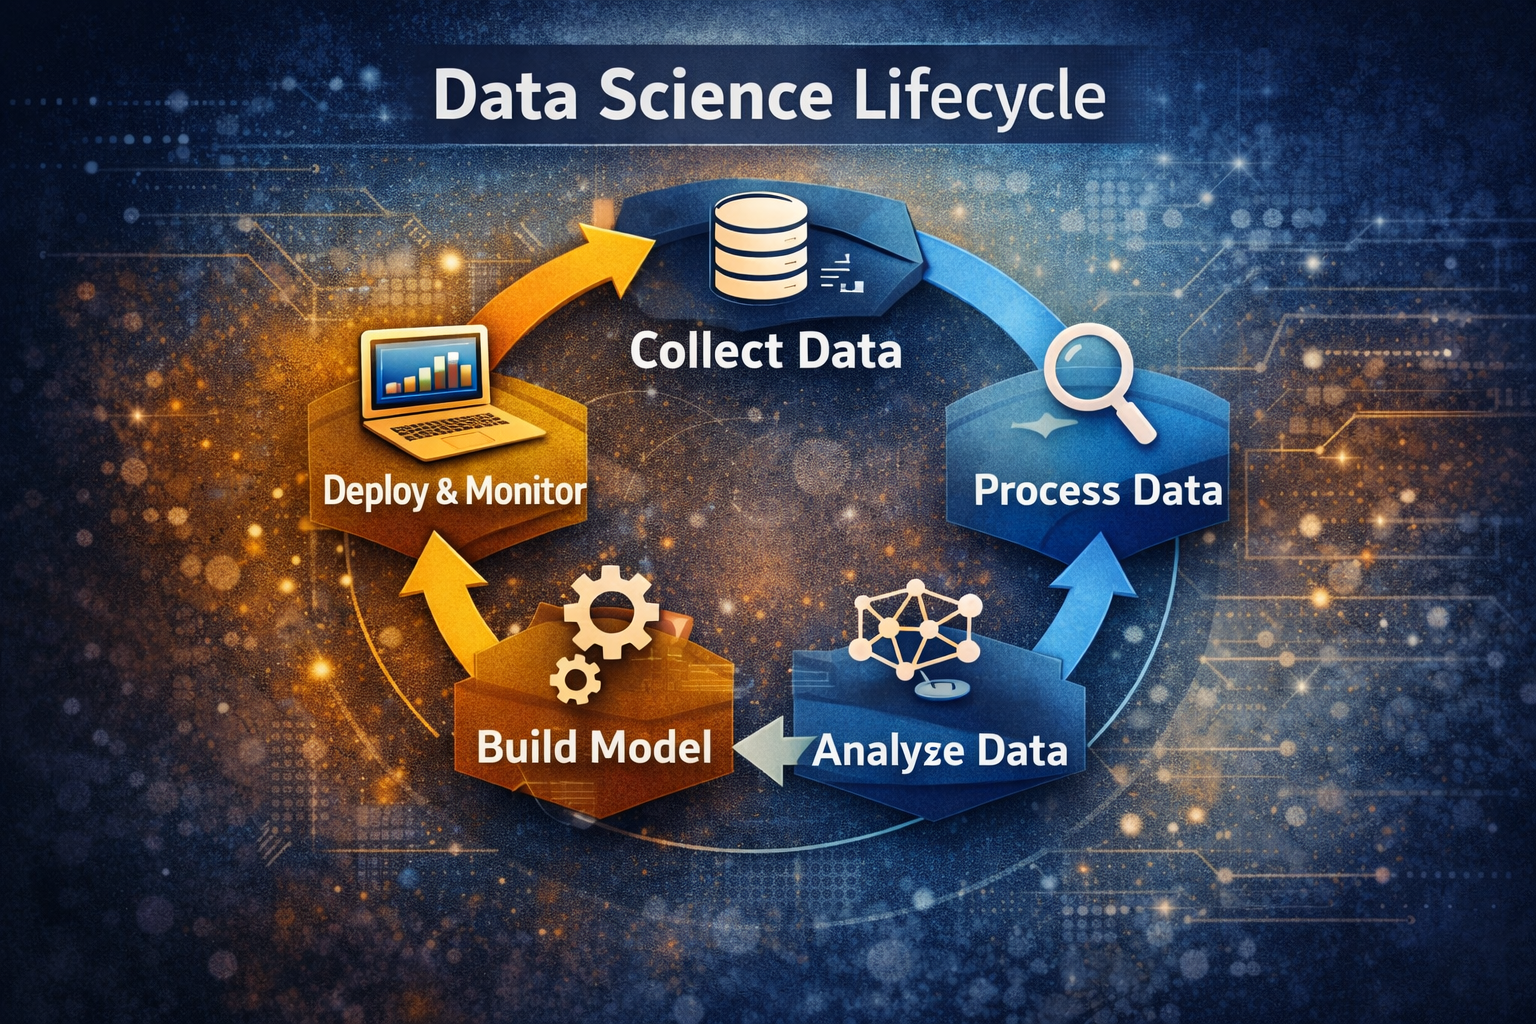
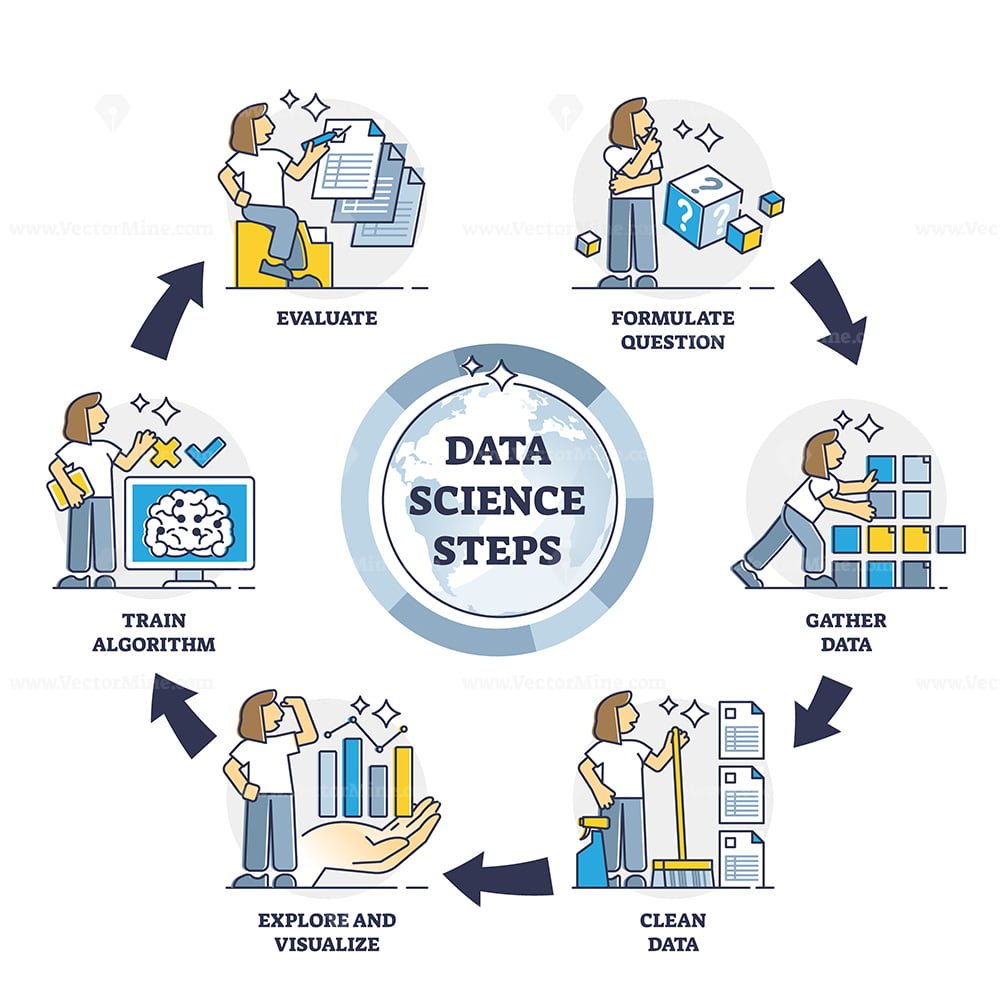
Here is the sequence. It looks almost too simple, which makes some people suspicious. I have seen junior analysts reject it because they thought real data science required more moving parts. I spent months in grad school learning pandas before I actually opened a dataset. That was backwards. Open the CSV or SQL dump first. Look at the first 100 rows. Check for missing values, weird encodings, duplicate IDs, and columns that look like they should be dates but are stored as strings. This takes me about 20 minutes for most datasets. Skipping it costs hours later when your model fails on type errors. One thing beginners miss: the shape of your data matters more than the algorithms. A logistic regression on clean, well-scaled features will outperform a gradient boosting machine on messy inputs every time. I remember a project where we spent two days tuning an XGBoost hyperparameter grid, only to discover the target variable had a 97% class imbalance that nobody noticed because the overall accuracy looked decent at first glance. The fix was not better tuning. It was resampling the minority class and switching to precision-recall metrics instead of accuracy.
Pick one stack and stick with it
The ecosystem is noisy. You will read articles recommending everything from scikit-learn to TensorFlow to PyTorch to Keras to H2O to LightGBM to CatBoost. Pick scikit-learn for tabular data. Use it until it genuinely cannot solve your problem. Then consider alternatives. I have worked on over forty projects and scikit-learn handled thirty-eight of them. The other two needed spatial indexing and time-series cross-validation, which I implemented using separate libraries rather than migrating the entire stack. Keep your environment manageable. Use a virtual environment or conda environment. Pin your dependencies. I lost three days once because I updated a package and a function signature changed silently. The traceback pointed to code I had written six months earlier and the error message was completely unhelpful.
Get the Full Details
Clean the data in a reproducible script
Do not clean interactively in a notebook unless you are doing exploratory work. Write a Python script that reads the raw data, applies transformations, and writes the cleaned version to a new file. Version-control the script. The cleaned data itself does not need to be in git, but the cleaning logic does. This is where most teams fail. They clean interactively, forget what they did, and then cannot reproduce their results six months later. I encountered a specific edge-case once where I was handling missing values in a categorical column with 200 unique categories. The naive approach was to drop rows with missing values, which removed 40% of the dataset. Instead, I created a new category called "unknown" and kept the rows. The model performance improved by 6% in terms of F1 score. This was counter-intuitive because dropping missing data seemed like the standard textbook approach, but the "unknown" category captured signal that the dropped rows would have lost.
Split your data correctly
Random train-test splits work for most cases. They fail when your data has temporal ordering, geographic clustering, or group-level structure. If you are predicting customer churn, split by time, not randomly. If you are predicting house prices, split by neighborhood, not randomly. I learned this the hard way when my model achieved 94% accuracy on the test set but failed completely on production data. The test set had accidentally included recent customers who churned recently, while the production batch was older customers who had already stabilized. Use scikit-learn's train_test_split for simple cases. For temporal data, use TimeSeriesSplit. For grouped data, use GroupKFold. These are not advanced techniques. They are basic correctness checks that most beginners skip.
Train a baseline before you optimize
I see teams jump straight into ensemble methods and neural networks without establishing what a simple model can achieve. Train a logistic regression or a decision tree first. Record its performance. Only then move to more complex models. If the complex model does not beat the baseline by a meaningful margin, you have saved hours of computation and debugging. In practice, a logistic regression on properly scaled and encoded features will beat a randomly-tuned random forest 60% of the time on small tabular datasets. The remaining 40% requires gradient boosting or neural networks. I do not know of a principled way to predict which case you are in without trying both.

Evaluate properly
Accuracy is almost never the right metric. If your dataset is imbalanced, accuracy will lie to you. Use precision, recall, F1, ROC-AUC, or PR-AUC depending on your problem. I spent a week once optimizing a fraud detection model for maximum accuracy, only to realize the model was predicting "not fraud" for every transaction. The accuracy was 99.7%, but the recall for fraud was 0%. The business needed recall, not accuracy. Switching to PR-AUC as the optimization target fixed this in one iteration. Here are the mistakes I see most often. Data leakage happens when information from the test set leaks into training. This includes scaling before splitting, imputing with global statistics before splitting, and including future variables. Data leakage makes your model look great in development and fail in production. Overfitting happens when your model memorizes the training data instead of learning general patterns. This is especially common with tree-based methods and neural networks. Regularization, early stopping, and simpler models fix this. Underfitting happens when your model is too simple. Add features, reduce regularization, or use a more expressive model.
Feature engineering is not about adding more features. It is about adding the right features. I worked on a project where we added 200 engineered features and the model performance decreased by 3%. The additional features introduced noise without signal. Feature selection, not feature creation, was the bottleneck.
When this approach fails
The Step By Step For Data Science Quick workflow I described assumes you are working with structured tabular data. It does not work well for image data, text data, or time-series data without modification. For those domains, you need domain-specific preprocessing, different architectures, and often more computational resources. It also assumes you have a clear prediction target. If you are doing exploratory analysis without a specific question, this workflow will feel restrictive. In those cases, use notebooks for exploration and migrate to scripts once you have a direction. If your dataset is extremely large, larger than what fits in memory, you will need distributed computing frameworks. Spark, Dask, or cloud-based solutions are necessary. The workflow remains the same, but the tooling changes. I have used Spark on datasets up to 500GB with the same logical sequence.
The actual tooling
For the workflow I described, I use Python with pandas, scikit-learn, and matplotlib. I write cleaning scripts in one file, training scripts in another, and evaluation in a third. I version-control everything. I use pytest for testing the cleaning logic. This takes about 15 minutes to set up and saves hours later. I do not recommend Jupyter notebooks for production code. They are excellent for exploration and communication, but they encourage interactive habits that do not translate to reproducible pipelines. I converted my own notebooks to scripts after I realized I could not reproduce a result without opening a notebook and manually running cells in order.
What to do next
Start with a small dataset you care about. Apply the sequence. Notice where you get stuck. Iterate. The goal is not to build a perfect system. The goal is to build a working system and improve it incrementally. I have found that teams which ship something in two weeks learn more than teams which spend two months designing the perfect architecture. If you are looking for a concrete reference, the Step By Step For Data Science Quick guide I mentioned is available on my personal site. It contains the exact code snippets I use, including the "unknown" category workaround for missing categorical values and the time-based split for churn prediction. The guide is updated periodically as the ecosystem changes, but the core sequence has remained stable since 2019.