What Actually Happens When You Try to Vintage Your Data
Most people who come to data science thinking "vintage" is a neat column you add to a DataFrame are wrong. I learned that the hard way when I was 26 and trying to build a cohort analysis for a churn model that kept spitting out garbage because I hadn't understood what vintage actually means in practice. Vintage is a grouping methodology. You segment your population by when they entered the system — sign-up date, first purchase date, cohort start date — and then track what happens to each group over calendar time. That's the definition. The reality is a lot messier.
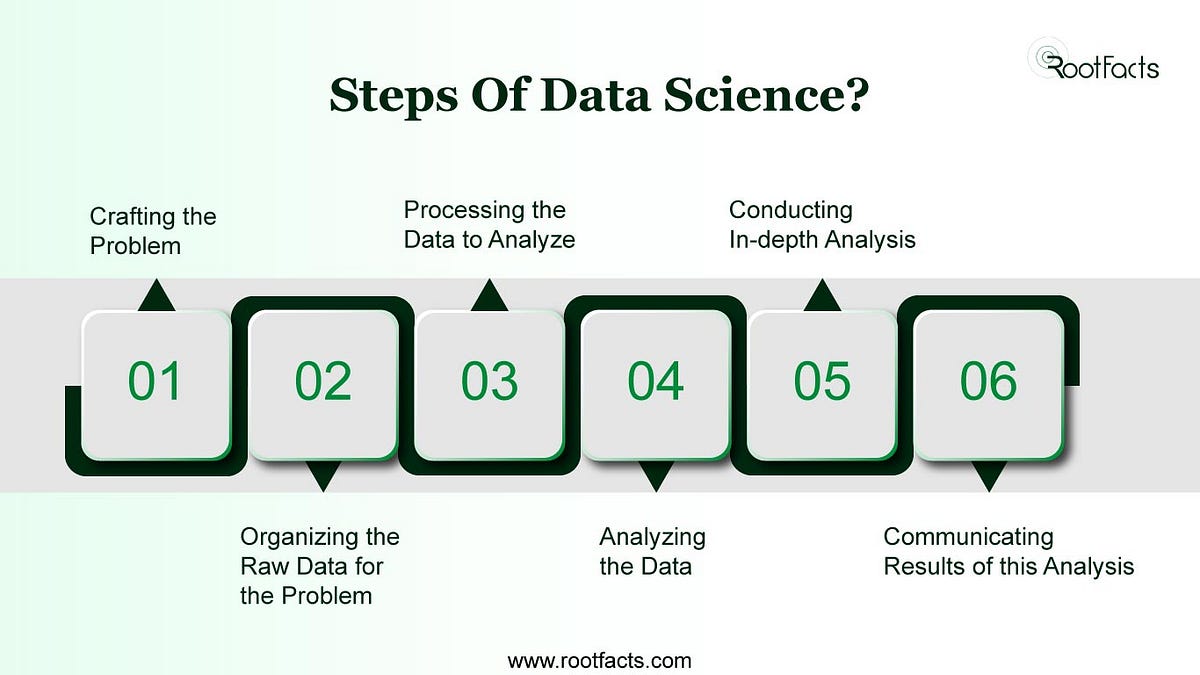
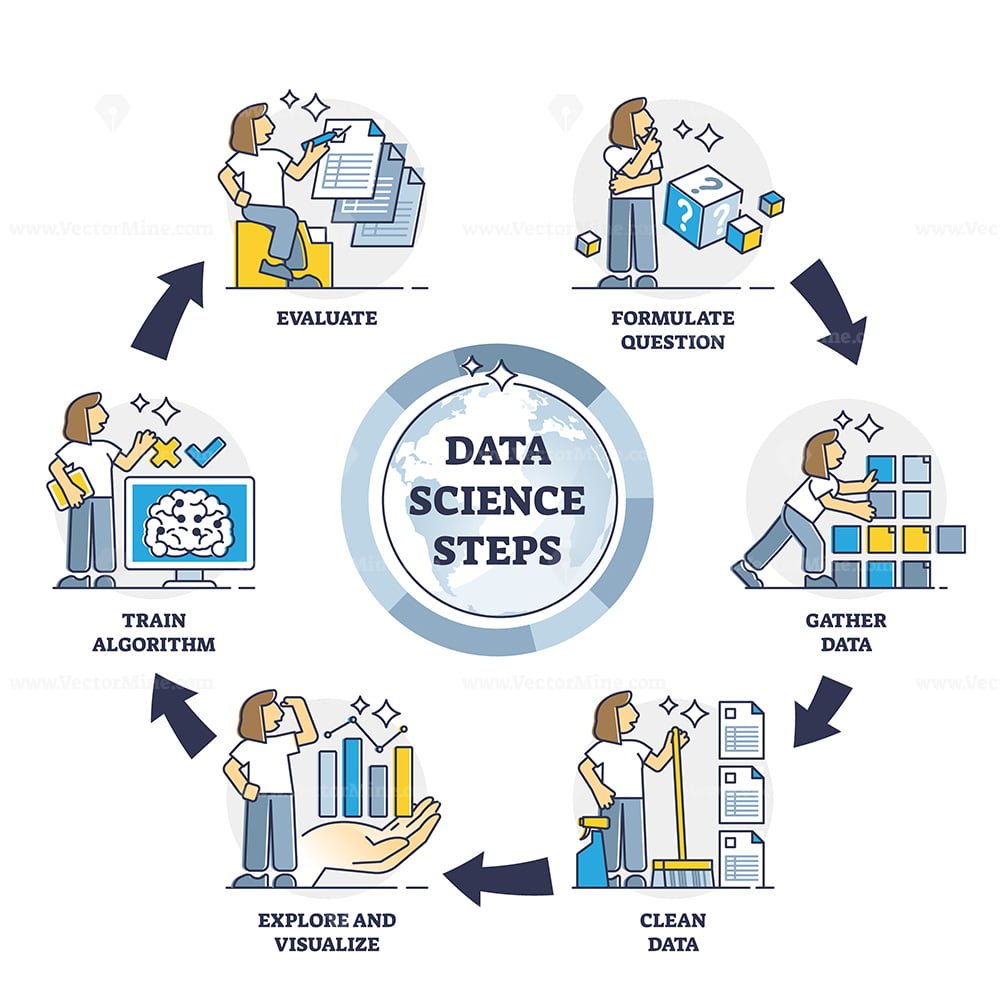
Step By Step For Data Science Vintage
Here's how I actually do it. Not the textbook version. The version that works when your data has gaps and missing timestamps and three different engineering teams have been touching the source tables since 2019. Step one: pick the anchor date. This is the single most important decision and the one everyone gets wrong. The anchor date defines your vintage. For a subscription business it's usually first login. For e-commerce it's first order. For lending it's disbursement date. Don't pick something vague like "account creation" if accounts get created but never used. I've seen analysts do this and then spend six weeks debugging why their retention curves look flat at zero because half the cohort never actually participated. Step two: validate your anchor date coverage. Before you do anything else, check what percentage of records have a non-null anchor date. If it's below 95 percent, you have a data quality problem that vintage analysis won't fix. I once inherited a dataset where 40 percent of users had missing signup timestamps because the analytics event only fired on second-day activation, not registration. We had to backfill using proxy logic — matching IP ranges and device fingerprints against support tickets — to recover enough records to make the analysis usable. Took three days. Your mileage will vary.
Step three: bucket into cohorts. Monthly buckets are standard. Weekly if your business moves fast enough. Daily is rarely worth it unless you're tracking something like ad campaign lift where hourly granularity matters. The rule of thumb is: bucket size should give you at least 500–1,000 observations per cohort for statistical stability. Fewer than that and your confidence intervals become meaningless noise. Step four: define your period-of-exposure calculation. This is where vintage differs from simple cohort analysis. Vintage tracks behavior relative to the anchor date across calendar periods. Period 0 is the anchor month. Period 1 is the next month. And so on. You calculate each person's period by taking the difference between their activity month and their anchor month. The formula is straightforward: `period = activity_month - anchor_month`. But here's the trap — if someone signs up on January 15th and your anchor month is January, they belong in January vintage even though they had 16 fewer days of exposure than someone who signed up January 1st. Most tools ignore this. I don't. I weight by actual days in period for short-form metrics like daily active rate, but for retention I accept the monthly bucket approximation because the alternative introduces too many edge cases. Step five: calculate your metric per cohort-period cell. Retention rate, revenue per user, activation rate, whatever your business cares about. The key is consistency. If you measure retention as "active in period N AND active in period N-1," make sure you apply that same definition across every cohort. I've seen dashboards break because someone changed the definition mid-quarter and the visual didn't update, making it look like a sudden market shift when it was just a metric redefinition.
Get the Full Details
Step six: handle censored cohorts. This is the part nobody talks about. A cohort from last month has eight complete periods of data. A cohort from this month has one. You cannot compare them directly. The standard workaround is to only display completed periods in your heat map, leaving right-side cells blank, and making sure anyone looking at the data understands that blank doesn't mean zero. I use a shading convention where light gray means "no data yet" and white means "zero activity." It sounds minor but it prevents a lot of stupid questions in review meetings.
Why Vintage Is Harder Than It Looks
I wish this were simpler. It's not. The core difficulty is that vintage analysis assumes your anchor date is a clean event that marks the beginning of a user's relationship with your product. In reality, most products have multiple entry points. A user might see an ad (touchpoint 1), download the app (touchpoint 2), create an account (touchpoint 3), verify email (touchpoint 4), and make their first purchase (touchpoint 5). Which one is the anchor? The answer depends on what you're trying to measure. If you're measuring conversion, the anchor is the first. If you're measuring retention revenue, the anchor is the first purchase. If you're measuring engagement depth, the anchor might be the first meaningful interaction — which could be day three, not day one. There's no universal answer. You have to decide based on your business question and be consistent about it. Another problem that bites people: seasonality. A cohort starting in November will look different from one starting in July even if the product experience is identical. Holiday purchasing patterns, weather-dependent usage, back-to-school cycles — these all create vintage-specific artifacts that have nothing to do with cohort quality. I always plot a moving average across vintages to filter out the seasonal noise before making decisions. A single-month spike in a vintage chart is almost never actionable.
The Counter-Intuitive Things Nobody Tells You
Older vintages don't automatically mean worse. Beginners assume that earlier cohorts should dominate because they have more history. But older vintages often represent a different customer profile — early adopters, promo-driven signups, channel-specific traffic — that isn't comparable to current cohorts. Comparing January 2023 vintage to March 2024 vintage without understanding the acquisition mix difference is a fast track to wrong conclusions. I separate vintage analysis by acquisition channel whenever possible. When that's not feasible, I flag the comparison with a disclaimer in the dashboard notes. Vintage depth isn't the same as vintage quality. A cohort with 24 months of data isn't necessarily more useful than one with 6 months. If the product changed significantly in month 12 — a pricing update, a feature redesign, a rebrand — the early data in that cohort becomes contaminated. I truncate vintages at the last major product change and note the truncation point. It's better to have a clean 6-month vintage than a messy 24-month one. The anchor date matters more than the metric. I've spent hours optimizing retention calculations only to realize later that the anchor date was off by two weeks because of timezone mismatches between the auth service and the billing service. One user signed up at 11:45 PM EST and their billing record showed 12:45 AM EST the next day. They ended up in the wrong vintage bucket. This is a real problem if your infrastructure spans timezones. I standardize all anchor dates to UTC and flag any boundary-crossing records for manual review. It adds about 2 percent overhead but catches the edge cases that would otherwise silently corrupt your analysis.
When Vintage Analysis Fails
Let me be blunt about the things that break this approach. If your product has no natural entry event — say, it's a continuously used utility like a weather app that people open without any formal onboarding — vintage doesn't apply cleanly. You can force an anchor date (first open, last open, random sample), but you're manufacturing signal where none exists. In those cases, behavioral clustering or sequence analysis works better. If your user base is small — under 10,000 total active users — monthly vintages will have too few observations per cell. You'd need quarterly or semi-annual buckets, which sacrifices resolution for stability. Sometimes that's fine. Sometimes it means vintage analysis isn't the right tool for your problem.
If your data pipeline has inconsistent event logging — which is almost every company at some point — your vintage buckets will contain garbage. I once found a cohort where 18 percent of "active" records were internal test accounts that hadn't been filtered because the filtering rule was added after the fact. The vintage chart looked normal until I dug into the raw data. Always cross-check your cohort sizes against expected acquisition volumes. A 3x deviation is your warning sign.
What I Actually Use
For production vintage analysis I use Python with pandas and numpy. The core pipeline is roughly 200 lines of code that handles anchor assignment, period calculation, censored cohort masking, and heatmap rendering. I wrap it in a function called `build_vintage_table()` that takes a DataFrame with columns for user_id, anchor_date, activity_date, and the metric value. It returns a pivot table indexed by cohort month with periods as columns. For visualization I prefer a custom seaborn heatmap over the standard plotly dashboards because the color scale is easier to calibrate for human reading. I set the diverging palette around zero for rate metrics and the sequential palette for absolute values. The default viridis looks pretty but it's terrible for distinguishing subtle retention differences between adjacent cohorts. If you're starting out and don't want to build this from scratch, there are open-source packages on GitHub that implement vintage/cohort analysis. The most reliable ones I've tested are `cohorts` (pip install cohorts) and the vintage module in `pycohort`. They handle the basic cases well but neither handles censored cohort masking elegantly, so I still wrap their output with my own visualization layer. The total setup time from raw data to production dashboard is usually 4–6 hours for the initial build and 30–45 minutes per monthly refresh after that.

A Real Problem I Solved Recently
Last quarter I was analyzing vintage retention for a SaaS product and noticed that the March 2024 cohort had dramatically higher period-1 retention than any other cohort in the dataset. At first glance it looked like a product breakthrough. I was about to write a slide deck celebrating it when I realized the March cohort had 40 percent fewer records than the surrounding months. The spike wasn't real — it was a data ingestion gap where the marketing attribution system stopped sending March leads to the analytics pipeline for two weeks. The affected users simply had no recorded inactivity because they weren't being tracked at all. The fix was to cross-reference the vintage cohort sizes against the CRM lead count for each month and flag any deviation greater than 15 percent. Once I applied that filter, the "breakthrough" disappeared and the true trend — gradual improvement from a feature release in February — emerged clearly. It saved me from presenting garbage to the executive team and reminded me that vintage analysis is only as good as the data quality underneath it. No amount of sophisticated modeling fixes a broken pipeline.
Bottom Line
Vintage analysis is useful. It's not magical. It gives you a structured way to think about how different groups of users behave over time relative to when they started. That structure is valuable. The structure is also fragile — it depends on clean anchor dates, consistent event logging, and honest handling of censored periods. If you treat it like a black box and trust the output without questioning the inputs, you'll get misleading results. If you understand what each step is doing and validate the assumptions at every stage, it's one of the most practical tools in a data scientist's toolkit. The vintage pattern you see in your heatmap is only as honest as the data pipeline that produced it. Build the pipeline right. Then the analysis takes care of itself.