Getting Into ML Without Burning Out
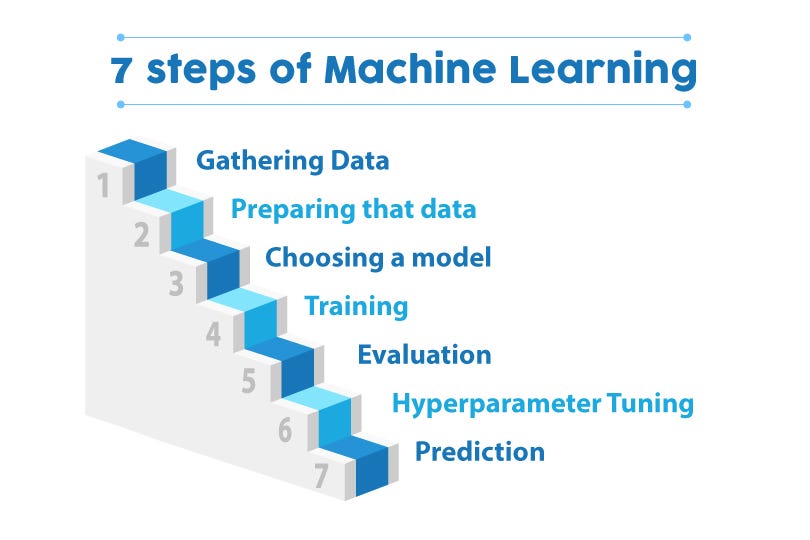
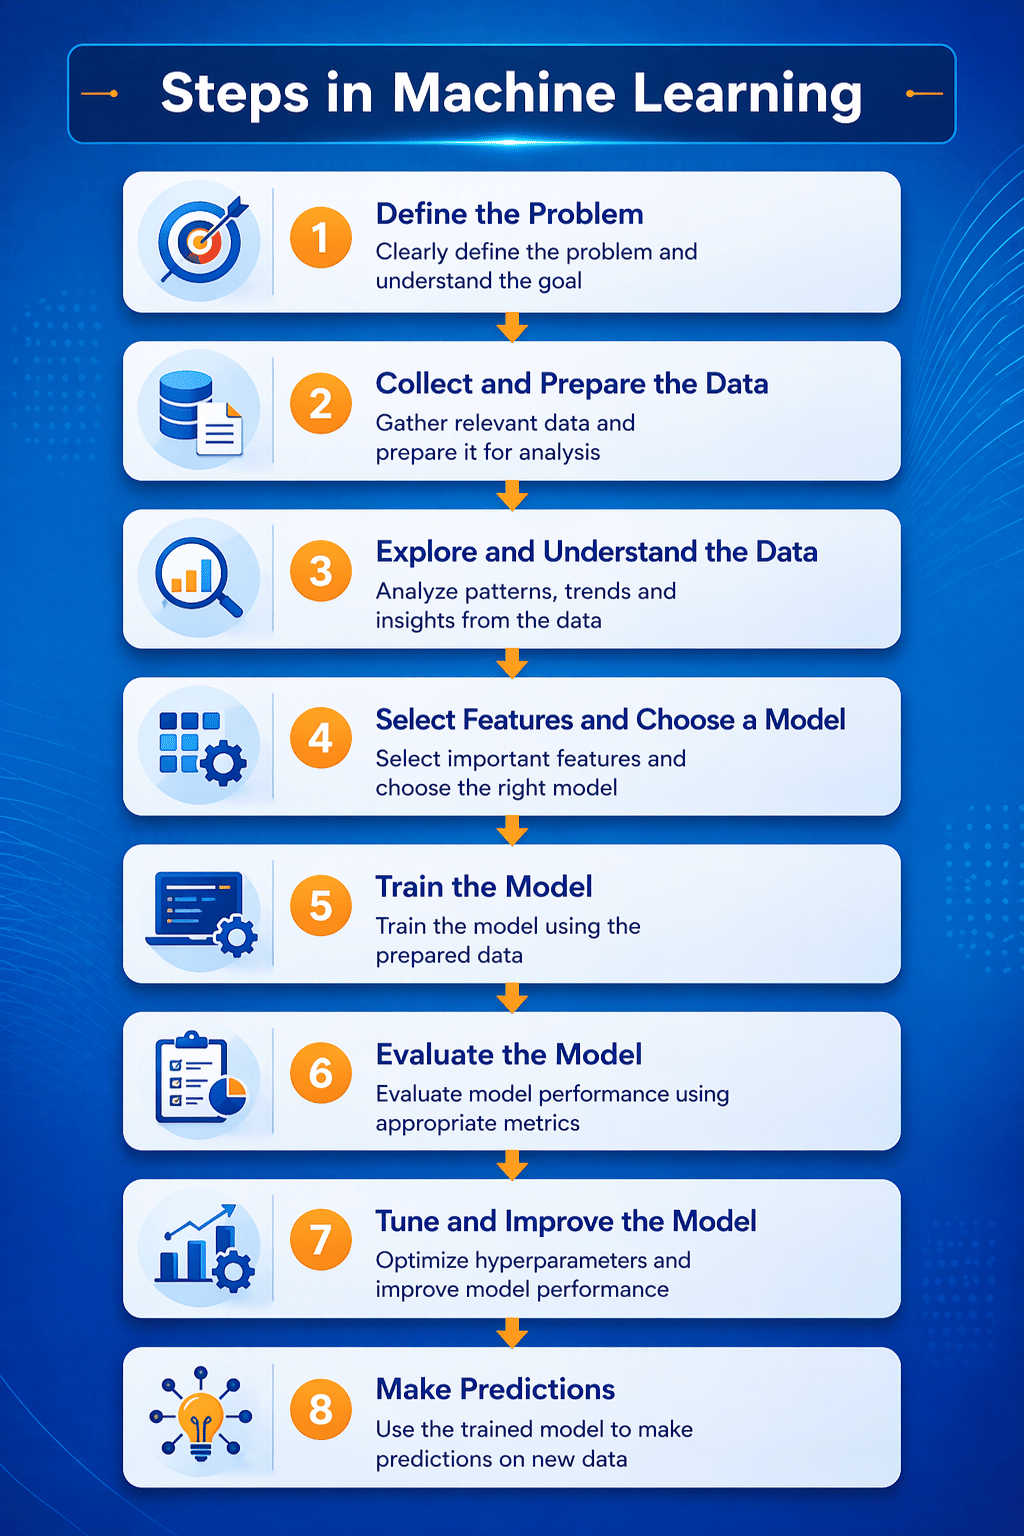
Most people jump straight into Python and start importing libraries they don't understand yet. That doesn't work. I watched a friend try to build a neural network for image classification after watching two YouTube videos. His model learned to associate the background of training images with the labels instead of the actual objects. He spent three weeks debugging something that was fundamentally a data problem, not a code problem. Don't do that. Start with scikit-learn and a tabular dataset. Something boring like the Breast Cancer Wisconsin dataset or the California Housing dataset. These have clean columns, no missing values that will break your pipeline, and the target variable is clearly defined. I know that sounds underwhelming compared to working with images or text, but you will actually learn something if you follow this path. Here is what the first week looks like. Install Anaconda if you don't have it. Open Jupyter and load the dataset. Print the shape. Print the first five rows. Check for missing values with a simple column-wise count. Then split your data into train and test sets using train_test_split from sklearn.model_selection. The default 80-20 split is fine for now. Don't overthink it.
Fit a baseline model. A logistic regression or random forest. Just one. Predict on the test set. Check accuracy. Now here is the part most tutorials skip: look at the confusion matrix and the classification report. Accuracy alone will lie to you. I had a client once building a fraud detection model that hit 99.2% accuracy. The fraud cases made up 0.8% of the data. The model predicted everything as legitimate and still hit 99.2%. It was useless. The precision-recall tradeoff matters way more than people admit early on. After the baseline, try a different algorithm on the same data. Gradient boosting. Then a support vector machine. Compare them using cross-validation, not just a single train-test split. Five-fold CV gives you a distribution of scores that actually tells you something about model stability. I usually run 10 folds when the dataset is small because five can still give you misleading variance. Once you have done this cycle two or three times with different datasets, move on to feature engineering. Learn what pandas is actually capable of. Create interaction features. Encode categorical variables properly using OneHotEncoder or OrdinalEncoder rather than just mapping strings to integers. That integer mapping trick destroys tree-based models because it imposes an artificial ordering on categories that have none.
The next layer is hyperparameter tuning. Start with GridSearchCV on a small parameter space. I usually limit it to three to four parameters max for the first round. Learning rate, number of estimators, max depth, and maybe one regularization parameter. Full grid searches on wide ranges will eat hours on a normal laptop. RandomizedSearchCV is faster and often finds equally good parameter combinations because most of the search space is irrelevant anyway. I cut my tuning time from about 45 minutes down to roughly eight minutes switching to random search on a housing dataset last month. Then handle pipelines. This is where things get practical. Scikit-learn pipelines chain preprocessing steps and the model together so you don't accidentally leak test data into your training process. I have lost count of how many times I have seen people fit their scaler on the full dataset before splitting, which is basically the most common rookie mistake in the field. It inflates your test scores artificially and your model fails in production. A simple Pipeline object with ColumnTransformer for mixed data types fixes this entirely. Once you are comfortable there, pick a project that genuinely interests you. Kaggle is fine for practice but the competition culture pushes people toward ensemble stacking before they understand basic feature importance. Build something small end to end. Load data, clean it, train, validate, save the model with joblib, write a script that loads it and makes predictions on new input. That last step matters more than people realize. A model you cannot deploy is just a Jupyter notebook experiment.
Get the Full Details

What Nobody Tells You About The Early Stages
Math will slow you down if you try to learn it all upfront. You do not need to derive backpropagation before building a model. Learn the math as you hit walls. If gradient descent is not converging, then go read about learning rates and initialization. That context makes the math stick because you actually need it. Otherwise it is just abstract symbols on a page. Neural networks are not the default answer. They are computationally expensive, sensitive to preprocessing, and usually worse than a well-tuned gradient boosting model on tabular data. I spent a week trying to get a simple feedforward network to beat LightGBM on a customer churn dataset. It did not. The tree ensemble was faster to train, required less tuning, and gave better AUC. Only reach for deep learning when your data is images, audio, or text at scale. Cross-validation on time series data is fundamentally broken if you use the standard KFold approach. Use TimeSeriesSplit instead. I learned this the hard way when I was predicting quarterly sales and got an artificially high R² because the CV split was letting future information leak into past folds. The model looked great in validation and failed immediately on real data.
Save your experiments. Use something like MLflow or even just a simple spreadsheet tracking model name, hyperparameters, CV scores, and notes. Without it, you will revisit the same dead ends repeatedly. I once spent two days reproducing a result only to realize I had changed a preprocessing step somewhere and forgotten about it. A single line in a log would have saved that. The field moves fast but the core concepts change very slowly. Random forests, gradient boosting, regularized logistic regression, basic neural networks. Those are still the workhorses. Frameworks come and go but the underlying mechanics remain identical. Focus on understanding why a model behaves the way it does rather than chasing the newest architecture. You will be more employable and your models will actually work when it counts.