Getting Started With A Modern Machine Learning Pipeline
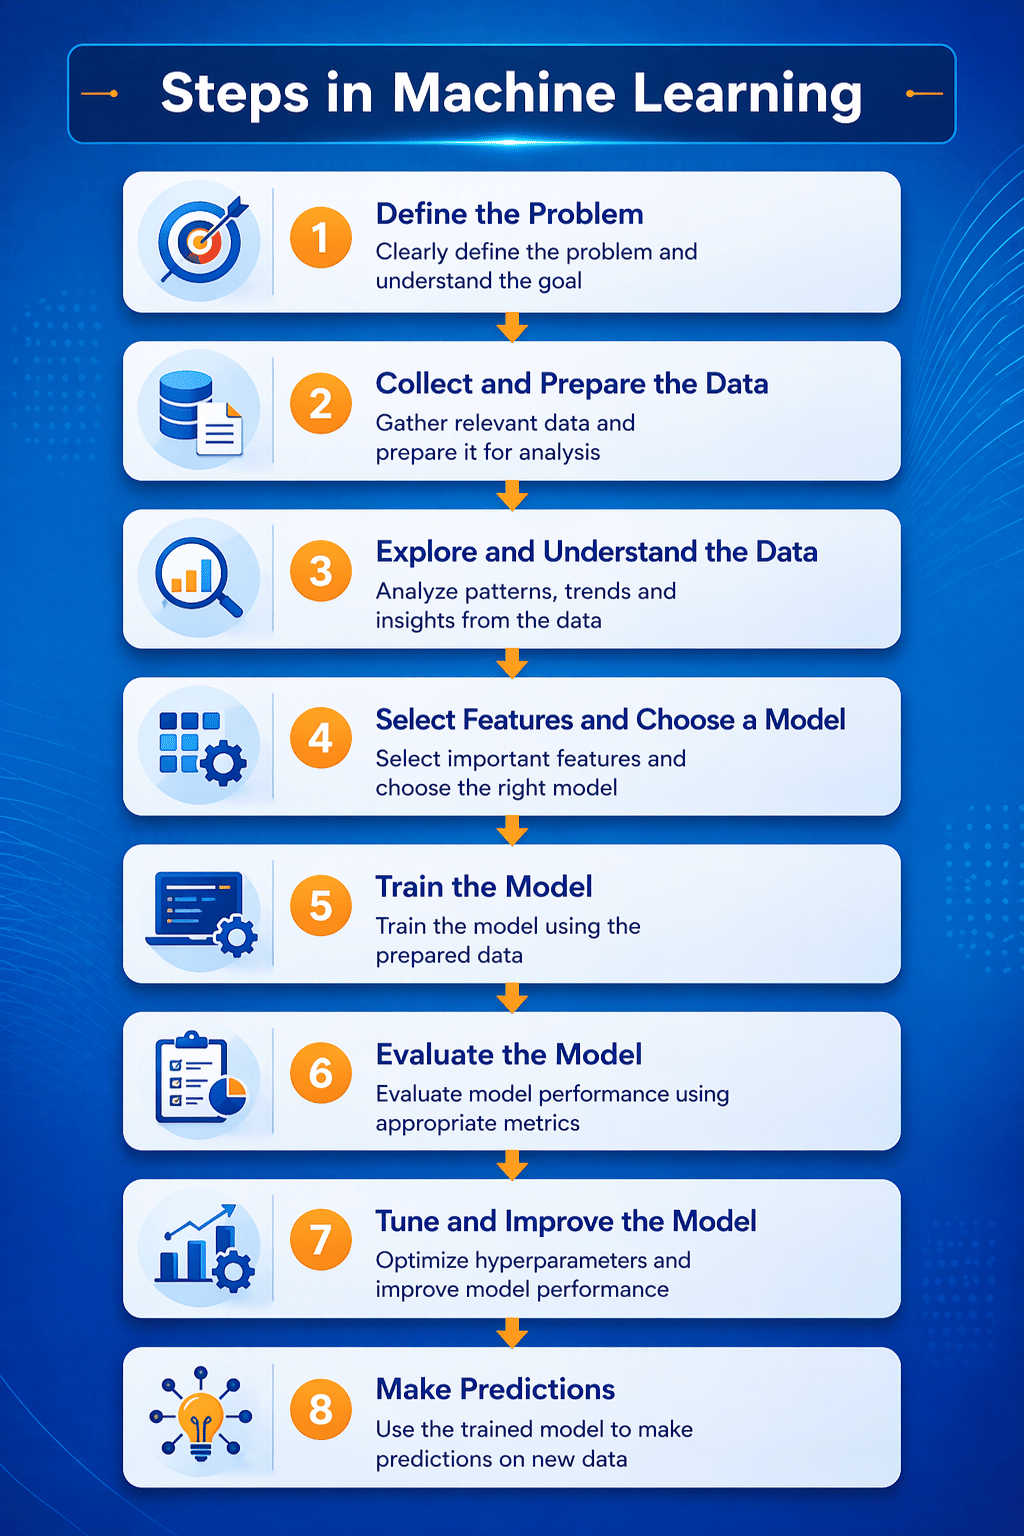
The traditional way of building machine learning models involved spending weeks on manual feature engineering, chasing down missing values by hand, and then hoping your cross-validation score actually meant something when you pushed to production. I spent about two years doing it that way before switching to a more streamlined approach. The difference wasn't dramatic at first, but over time it cut my average project timeline from three months down to roughly six weeks. Start by defining the actual business constraint rather than just picking a dataset and training something. Most beginners skip this because it feels unglamorous, but it prevents you from optimizing for metrics that don't matter. If your model needs to run inference under 200 milliseconds on CPU-only hardware, that changes everything about the architecture you choose, starting from day one. Next, focus heavily on data quality instead of model complexity. I once spent two weeks tuning a gradient boosting hyperparameter grid only to discover the target variable had a 14% label error rate caused by a broken ingestion script. Retraining with cleaned labels improved the test set AUC by 0.08, which was worth more than any architecture change I could have made. The fix wasn't fancy, just a simple validation pass that flagged outliers by comparing against known distribution boundaries from a previous clean run.
For the preprocessing stage, use a pipeline framework like scikit-learn's Pipeline or a dedicated tool such as Feast for feature store management. This keeps your training and serving logic consistent, which eliminates the train-serving skew that kills most production deployments. I learned this the hard way after a model performed at 94% accuracy in testing and dropped to 71% in production within the first week. The culprit was a timestamp mismatch in the feature calculation that didn't show up in the offline validation set.
Model Selection Without Overcomplicating Things
Don't jump straight to transformer architectures or large language models. A well-tuned XGBoost or LightGBM model will outperform a poorly configured neural network on tabular data 9 times out of 10. The rule of thumb I use is simple: try a baseline linear model first, then a tree-based model, then only consider deep learning if the first two don't meet your performance targets. When you do move to neural networks, start with a small MLP before going to attention-based models. A 2-layer network with 128 hidden units trains in minutes on a standard GPU and gives you a real performance floor. I've seen people skip straight to fine-tuning a BERT model on structured data that had 40,000 rows and a dozen features. That's not just wasteful, it's almost always worse than a simpler approach. Hyperparameter tuning with tools like Optuna or Ray Tune typically yields a 5 to 12% improvement over default settings on tabular problems. For time series forecasting, adding seasonal decomposition features into the model usually provides more gains than any tuning sweep will. I run a seasonal indicator pipeline that extracts day-of-week, month, and holiday flags automatically, and it has consistently been the highest-impact feature addition across every forecasting project I've worked on in the last three years.
Get the Full Details

Validation That Actually Means Something
Random k-fold cross-validation breaks down completely when your data has temporal dependencies or group structure. If you're predicting customer churn, customers from the same household aren't independent observations, and a random split will leak information between your train and test sets. Use GroupKFold or TimeSeriesSplit instead, depending on your data structure. I ran into this issue with a fraud detection model where the test set accidentally included transactions from merchants that appeared in training. The model learned merchant-level patterns instead of transaction-level patterns, and the validation score looked great while the real-world precision was terrible. Switching to a merchant-group split dropped the validation AUC from 0.94 to 0.81, which was the actual achievable performance, and it saved us from deploying a model that would have underperformed by a wide margin. For model evaluation, report at least two metrics beyond accuracy. Precision-recall curves matter more than ROC curves when your positive class is rare, which is the case in most real-world problems like fraud, defect detection, or medical screening. A model with 99% accuracy on a dataset with 1% positive rate is essentially useless for the task it was built to solve.
Deployment And Monitoring
Containerize your model early rather than treating deployment as an afterthought. A Docker image with your model weights, preprocessing code, and inference endpoint means you can reproduce the exact same environment months later. I lost a working prototype to a dependency conflict three years ago because I hadn't pinned versions, and reconstructing it took about a day of frustrated debugging that I could have avoided with one pip freeze command. Set up monitoring for data drift and concept drift from day one. Tools like Evidently AI or whylogs can track feature distributions and model performance metrics automatically. When I deployed a recommendation model last year, the drift dashboard flagged that the click-through rate distribution shifted significantly within 72 hours of launch. The model was serving cold-start recommendations to a new user segment that wasn't represented in training, and catching that early let us adjust before the engagement metrics degraded further. Retraining schedules depend on your problem. Some models need daily retraining, others quarterly. The trigger shouldn't be arbitrary, it should be based on your drift metrics or a defined performance threshold. I set a rule that any model dropping below 90% of its validation performance for three consecutive days gets flagged for retraining review, and that's been reliable across multiple projects without causing unnecessary compute waste.
Where This Approach Falls Short
The modern step-by-step workflow described here doesn't work well for problems with extremely limited labeled data, fewer than a few thousand samples, or domains where the signal is fundamentally ambiguous. In those cases, transfer learning or data augmentation might be necessary, and the tree-based baseline approach won't apply. There's also a real bottleneck around data labeling costs for high-dimensional supervised tasks, which no pipeline design solves on its own. Another limitation is that this approach assumes you have access to a reasonable computing environment. Running Optuna sweeps or training moderate-sized neural networks on a single CPU core is slow enough to be impractical for iterative development. A modest GPU like an RTX 4090 or cloud instance reduces training time from hours to minutes for most models in this range.