Machine Learning Workflow: The Practical Steps
Step By Step For Machine Learning Top 10
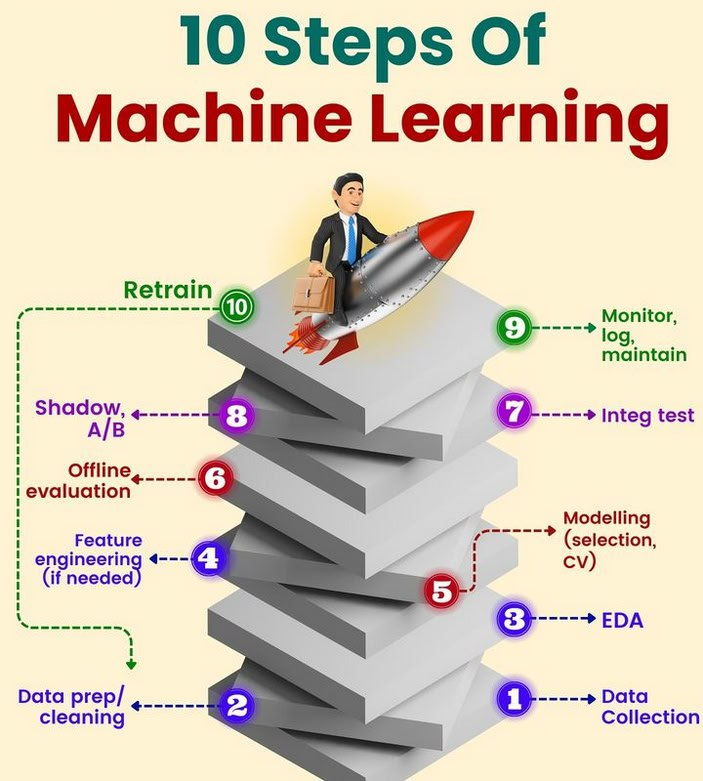
Most people jump straight into coding when they hear machine learning, which is why their projects fall apart. I've seen it a hundred times. Here's what actually happens, in order, and where things go wrong. 1. Define the problem clearly. Before touching any data, write down exactly what you're trying to predict or classify. Vague goals produce vague models. "We want to improve customer experience" is not a problem statement. "Predict churn probability within 30 days using last-90-days transaction data" is. 2. Gather and collect your data. This sounds simple and it isn't. Sources are scattered. Some are CSVs from a marketing platform, some live in a SQL database behind authentication you didn't set up, and some exist only as PDFs that someone scanned. I spent three weeks last year just connecting to a legacy CRM API that required a certificate rotation every 90 days. The workaround was a scheduled cron job that refreshed the cert and logged the rotation event for the next person. If you skip documenting your data pipeline here, you will be back here in six months not knowing where your columns came from.
3. Explore and understand the data. Run basic stats. Check distributions. Look at missing values per column. Plot feature pairs. This step usually takes longer than training the model itself. I once found a target leakage issue in an hour of exploration that would have cost us three days of debugging after deployment. The leakage was a column that contained the sum of the current day's transactions, while the target was also measured on the same day. The model wasn't learning anything; it was just copying the answer. 4. Clean and preprocess the data. Handle missing values. Encode categoricals. Scale numerical features when the algorithm requires it. This is where the work actually happens. I've found that simple imputation with median works better than most fancy methods for tabular data, unless you have a known mechanism for why values are missing. If data is missing at random, median is fine. If it's missing because a field only applies to a subset of rows, you need an indicator column plus the imputation. 5. Engineer features. This is the part that separates people who ship models from people who don't. Creating new variables from existing ones usually moves the needle more than swapping algorithms. Interaction terms, time-based aggregations, ratio features, lagged values for time series. Don't overdo it though. I built a model once with 400 engineered features and the validation score plateaued at 0.73. I dropped it down to 60 and got 0.76. Fewer features, easier to maintain, less prone to overfitting.
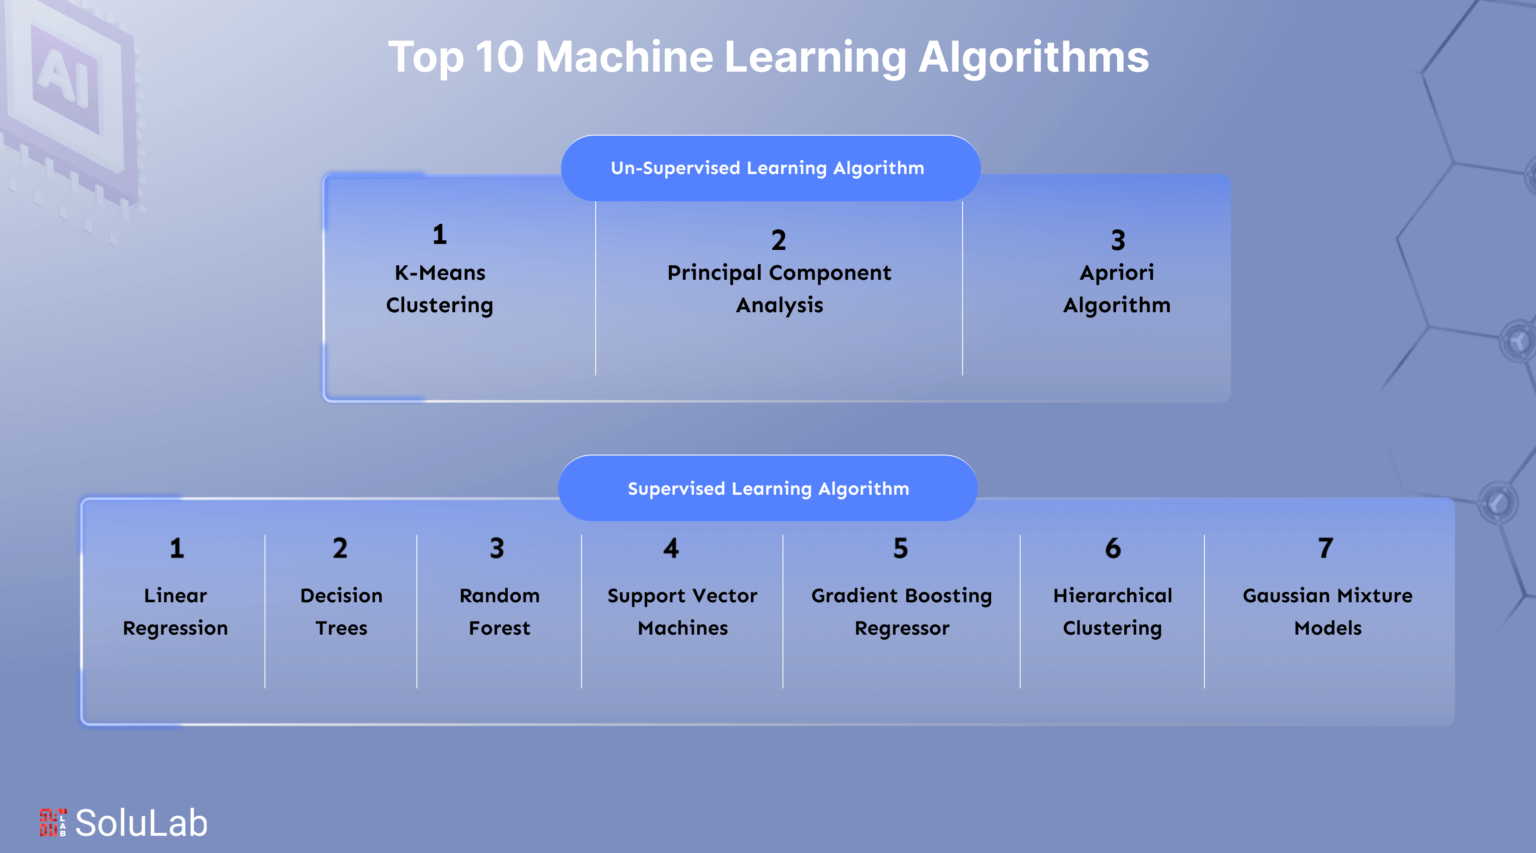
6. Split the data properly. Train, validation, test. Don't shuffle before splitting if your data has any temporal or group structure. I learned this the hard way with a fraud detection dataset where shuffling created impossible lookahead situations. A customer who committed fraud in March appeared in the training set alongside their January transactions after shuffling. The model learned to recognize fraud patterns because it had already seen the fraudulent transactions. Proper time-based splitting caught that immediately. 7. Select and train models. Start with a baseline. Logistic regression for classification, linear regression for prediction, a simple decision tree. Get a number on the board. Then move to gradient boosting, then neural networks if warranted. Most problems don't need transformers. XGBoost or LightGBM will beat a shallow neural net on tabular data 9 times out of 10, and it will run in minutes instead of hours. I trained a small sentiment classifier once with a BERT fine-tune and got 89% accuracy. A TF-IDF vectorizer with a linear SVM got 91% in under two minutes. 8. Evaluate properly. Accuracy is almost never the right metric. Use precision, recall, F1, AUC-ROC, or your domain-specific loss function. If your dataset is imbalanced, which most real-world datasets are, accuracy will lie to you. A model that predicts the majority class for every sample can hit 95% accuracy on a 95-5 split and be completely useless. Also separate your evaluation from your tuning. Keep the test set untouched until the very end.
Get the Full Details

9. Tune hyperparameters. Use randomized search or Bayesian optimization, not grid search. Grid search wastes compute on combinations that won't matter. Randomized search with 50-100 iterations typically finds a solid region of the parameter space faster. I run Optuna by default now. It prunes bad trials automatically and usually converges in a fraction of the time a manual grid search would take. 10. Deploy and monitor. This is where most projects die. You build a model, you're proud of it, and then nobody uses it because it lives on a Jupyter notebook on your laptop. Containerize it. Set up an API. Monitor drift. Models decay. Feature distributions shift. Input pipelines break. I had a model stop performing one Tuesday and it turned out the third-party data provider had changed a column name in their schema. The ingestion script failed silently because the error was caught and logged but the model kept running on cached fallback data. We had no alerting on the log files. The steps above aren't linear. You'll loop back constantly. Feature engineering will reveal you need more data cleaning. Evaluation will show you need different features. That's normal. The process is iterative, not sequential.
One thing nobody tells you: the model itself is the easiest part. The hard part is everything around it. Data quality, pipeline reliability, monitoring, stakeholder communication. A mediocre model in production with good monitoring beats a state-of-the-art model that nobody trusts because they don't understand how it works. If you're starting out, don't try to build the perfect system on day one. Get a simple model working end to end. Then improve each piece. The goal isn't to learn every algorithm. It's to ship something that solves a real problem and then make it better over time.