Doing Statistics Yourself Actually Works If You Stop Treating It Like Magic
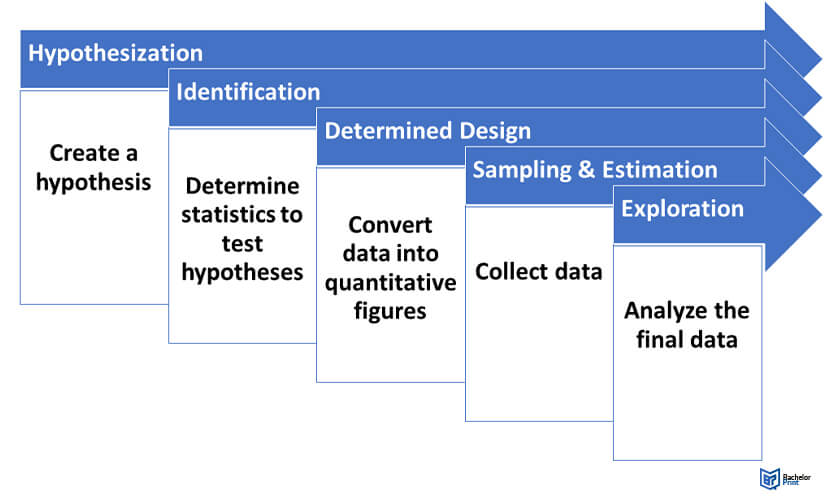
I spent years watching people either hire statisticians for $200 an hour or blindly click through SPSS menus until something popped out. Both approaches leave you with numbers you can't explain to anyone. The middle path is far more practical. You don't need a PhD to run valid analyses on your own data. You just need to understand what's happening at each step instead of treating software like an oracle. Start by getting your data into a clean sheet before you think about any test. I'm talking about checking for missing values, data types, and outliers that are actually mistakes rather than real observations. A lot of people skip this and spend three hours debugging why their regression won't converge when the real problem was a column full of text where numbers should have been. The first real analysis step is descriptive statistics. Mean, median, standard deviation, quartiles. Don't just run them and move on. Look at the relationship between the mean and median. If they're far apart your distribution is skewed and you shouldn't be reaching for a t-test without thinking about it. I had a client once who ran a paired t-test on response time data that was heavily right-skewed because a few users took fifteen minutes on a task that normally took forty seconds. The test was statistically significant but completely meaningless. Switching to a Wilcoxon signed-rank test fixed the validity problem and the p-value actually meant something.
After descriptives comes choosing the right test. This is where most DIY efforts fall apart. People see two groups and immediately think t-test. Three groups and they jump to ANOVA. The decision tree is more nuanced than that. You need to consider whether your data meets normality assumptions, whether variances are equal across groups, whether your samples are independent or paired, and what scale your measurement is on. If you're measuring something ordinal like a Likert scale, parametric tests are debatable at best. Non-parametric alternatives exist for almost everything and they're not harder to run in any modern tool. For the actual computation I'd recommend starting with R or Python if you're willing to invest a few hours in learning the basics. The learning curve is steep but once you have a script working you can reproduce every analysis in seconds. Excel is fine for straightforward stuff but it falls apart fast. Its t.test function doesn't even exist as a native command. You're relying on the Analysis ToolPak add-in or manually entering formulas that are prone to errors. I've seen people accidentally use the two-sample assuming unequal variance version when they should have used the equal variance version and not noticed because the outputs looked similar enough. Here's something most beginners miss. Statistical significance and practical significance are almost never the same thing. With a large enough sample size you'll find significant differences between groups that are so small they don't matter in the real world. A study with ten thousand participants might show that one treatment group scored 0.3 points higher on a fifty-point scale with a p-value of 0.001. That's statistically significant and practically irrelevant. Always calculate an effect size alongside your hypothesis test. Cohen's d, eta squared, odds ratios. These tell you whether the difference you found is actually meaningful.
Another counter-intuitive point that trips people up constantly. Running multiple tests on the same dataset inflates your false positive rate. If you run twenty independent tests at the 0.05 significance level you should expect about one of them to come out significant purely by chance. Bonferroni correction is the crudest fix and it's overly conservative. Holm-Bonferroni is better. False discovery rate control using the Benjamini-Hochberg procedure is often the right choice for exploratory work. Just be aware that you're playing whack-a-mole with Type I errors and document which correction method you used. When it comes to regression specifically, there are assumptions that people routinely violate without knowing it. Linearity between predictors and the outcome. Independence of residuals. Homoscedasticity, meaning the variance of residuals stays constant across all predicted values. Normality of residuals. I once spent two days trying to make a linear regression model fit properly before I realized the relationship was clearly curvilinear. Adding a quadratic term fixed everything. Diagnostic plots are essential here. Residuals versus fitted values plot will show you heteroscedasticity immediately as a funnel shape. A Q-Q plot reveals non-normality. These take thirty seconds to generate and save you hours of confusion. Sample size planning is another area where DIY analysts consistently underperform. Running an analysis and then checking if your results are significant is not a valid approach. You should estimate your required sample size before collecting data. G*Power is free and handles most common tests. If you don't know your expected effect size you can look at similar published studies or use a small effect as a conservative guess. The problem with underpowered studies is that they produce unreliable results even when they're statistically significant. A significant finding from an underpowered study is more likely to be a false positive than one from a well-powered study.
Get the Full Details
The biggest bottleneck I see in DIY statistics is interpretation. People get comfortable running tests but they can't honestly describe what the output means. If someone asks you to explain a p-value and your answer involves the word "probability" without being extremely careful about what probability you're actually referring to, you're not ready to present those results to anyone. A p-value is the probability of observing your data or something more extreme given that the null hypothesis is true. It is not the probability that the null hypothesis is true. These are different things and confusing them leads to seriously wrong conclusions. For validation purposes, split your data into training and test sets when building predictive models. Cross-validation is straightforward to implement in R with the caret package or in Python with scikit-learn. Five-fold or ten-fold cross-validation gives you a much more honest estimate of how your model will perform on new data than looking at fit statistics on the same data you trained on. Overfitting is the default behavior of any flexible model and unless you're actively guarding against it your results will look better than they actually are. Documentation matters more than people think. Every decision you make during analysis changes the outcome. Which outliers you removed and why. Which transformation you applied and what you were trying to achieve. Which tests you ran but didn't report because they weren't significant. Write this down as you go. Not at the end when you're trying to reconstruct your thought process from memory. I've lost track of how many times someone came back to me months later asking why their analysis included a log transformation and they had no idea themselves.
There are real limitations to doing statistics on your own. Complex experimental designs with nested structures or repeated measures across multiple time points require mixed effects models that are genuinely difficult to specify correctly without training. Survival analysis with censoring gets complicated quickly. Bayesian methods require understanding priors and MCMC convergence diagnostics. For these situations hiring someone who actually knows what they're doing is the rational choice. The cost of a wrong analysis far exceeds the cost of a consultation. But for standard t-tests, ANOVA, chi-square tests, linear regression, and basic non-parametric alternatives, the learning investment pays for itself within the first project. Download links for the tools I mentioned. R is at r-project.org and it's free. Python with pandas and scipy is at python.org. G*Power is at power.de. These are all legitimate, well-maintained resources. The rest is just practice and reading the documentation instead of watching five-minute tutorial videos that skip the parts that actually matter.