Getting a DNA sequence into protein
Translation is the cellular process where ribosomes read messenger RNA and assemble amino acids into a polypeptide chain. On paper it is straightforward. In practice, getting accurate results from raw sequence data involves several steps that are easy to botch if you are not careful about frame selection, start codon choice, and sequence quality. The core pipeline starts with a nucleotide sequence, usually in FASTA format, and produces an amino acid string. You need to establish the reading frame first, identify where translation begins, translate each codon using the appropriate genetic code table, then handle stop codons and any post-translational modifications if relevant. That is the skeleton. The details are where things get messy. I spent a lot of time debugging this pipeline early in my career. One project stands out. I was working with a draft genome assembly from a non-model organism, trying to predict protein-coding sequences from RNA-seq evidence. The organism used a slightly modified mitochondrial genetic code. I translated everything using the standard table, ran the proteins through a homology search, and got garbage results. Nearly zero hits against known databases. Took me three days to realize the issue. The organelle was using UGA as tryptophan instead of a stop codon. Once I switched the translation table to the correct variant, the homologs started showing up immediately. That kind of problem is invisible until your downstream analysis collapses.
Here is how I actually run this now, step by step.
Picking the right input sequence
Start with a clean, annotated coding sequence. Ideally you already know the orientation and frame. If you are working from raw genomic DNA, you need to account for introns first. Remove them. Translate the spliced mRNA, not the pre-mRNA. Using unspliced sequences will introduce frameshifts and premature stop codons that look like biological signals but are just artifacts. SeqCode I usually pull from RefSeq or Ensembl when possible. These sources have manually curated CDS annotations with verified start sites. If you are working with a less common organism, GenBank entries can work, but check the feature table carefully. Some older submissions have incorrect start codon annotations that propagate through automated pipelines.
Get the Full Details
Check the sequence length. It should be divisible by three if you expect a complete open reading frame without an in-frame stop. If it is not, decide whether you have a partial sequence, a sequencing error, or a frameshift mutation before proceeding. Do not force the translation. Note the discrepancy and investigate first.
Establishing the reading frame
This is where most beginners make mistakes. DNA is read in triplets, and the starting position determines every codon downstream. There are six possible reading frames on a double-stranded molecule. Three forward, three reverse. You need to know which one is correct before translating. If you have an annotated CDS, the frame is given to you. If you are doing ab initio prediction, you scan all six frames for open reading frames longer than a minimum threshold, usually around one hundred nucleotides. Longer ORFs are more likely to be real coding sequences. Shorter ones are probably noise. I typically run a quick ORF finder first to confirm the frame. Then I verify by checking whether the predicted protein makes biological sense. Does it contain the expected domains? Is the length reasonable for the gene family? If something looks off, I re-examine the frame rather than blindly trusting the output.
Choosing the genetic code table
The standard genetic code works for most nuclear genes in eukaryotes and many prokaryotes. But it does not work universally. The mitochondrial code differs. Some protozoans use alternative codes. Mycoplasma reassigns UGA to tryptophan. Certain ciliates repurpose stop codons as glutamine codons. Always confirm which code table applies to your organism. NCBI provides a comprehensive list of genetic code tables with their corresponding codon assignments. Table 1 is the standard code. Table 2 is the vertebrate mitochondrial code. Table 4 is the invertebrate mitochondrial code. Table 9 is the mold protozoan and Mycoplasma code. Pick the right one or your translation will be wrong in ways that are hard to detect without cross-validation. Most online tools let you select the genetic code. Command-line tools like EMBOSS getorf and seqret have flags for this. Make sure you set it explicitly. Do not rely on defaults if your organism is non-standard.
Running the translation
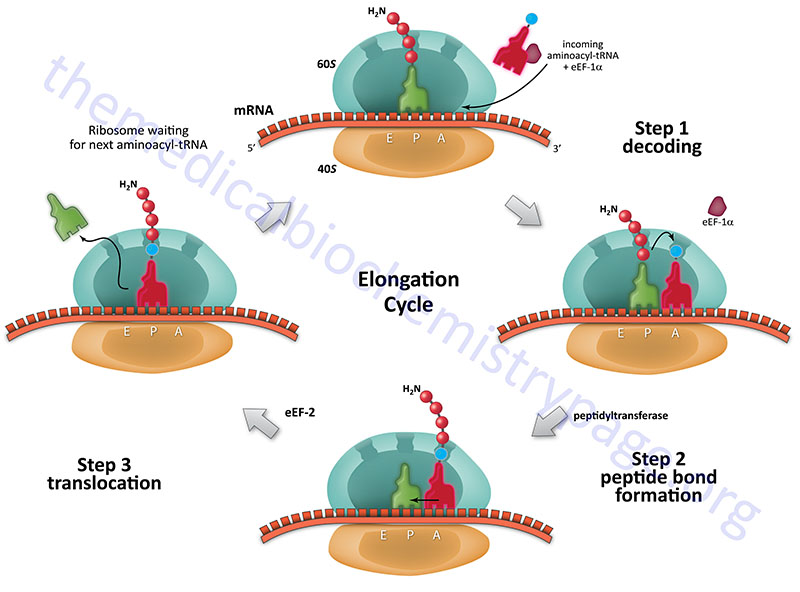
Once you have the frame and the code table sorted, the actual translation is mechanical. Each triplet of nucleotides maps to one amino acid. The ribosome reads five prime to three prime. The N-terminus of the protein corresponds to the five prime end of the mRNA. For manual translation or small-scale work, I use the ExPASy Translate tool. It handles all six frames, lets you pick the genetic code, and outputs both the nucleotide and protein sequences in parallel. Takes about two minutes for a typical gene. For batch processing dozens or hundreds of sequences, I switch to command-line tools. EMBOSS transeq is fast and scriptable. Biopython's Translation class works well inside custom pipelines. I recently automated a batch translation for a set of twenty-three gene families across twelve species. Used a Python script with Biopython that pulled CDS sequences from a local GenBank flat file collection, translated each one with the correct code table specified per organism, and validated that the output length matched expectations. The whole thing ran in under four minutes. Compared to doing it by hand through a web interface, which would have taken maybe two hours with a higher error rate.
Handling start and stop codons
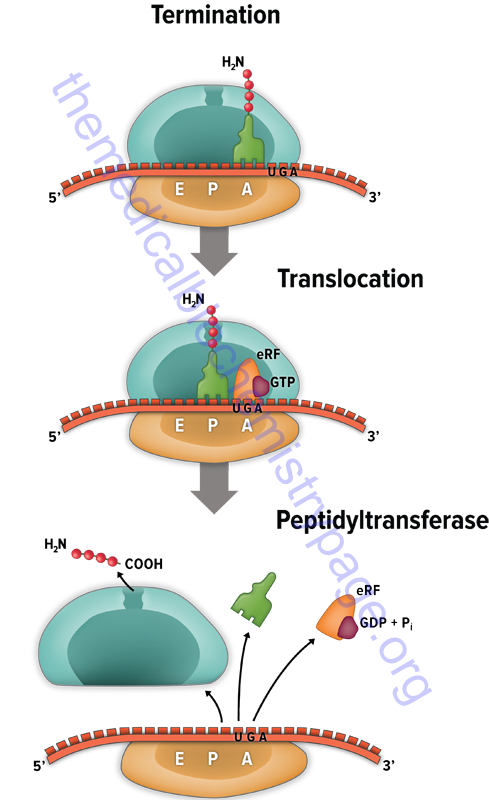
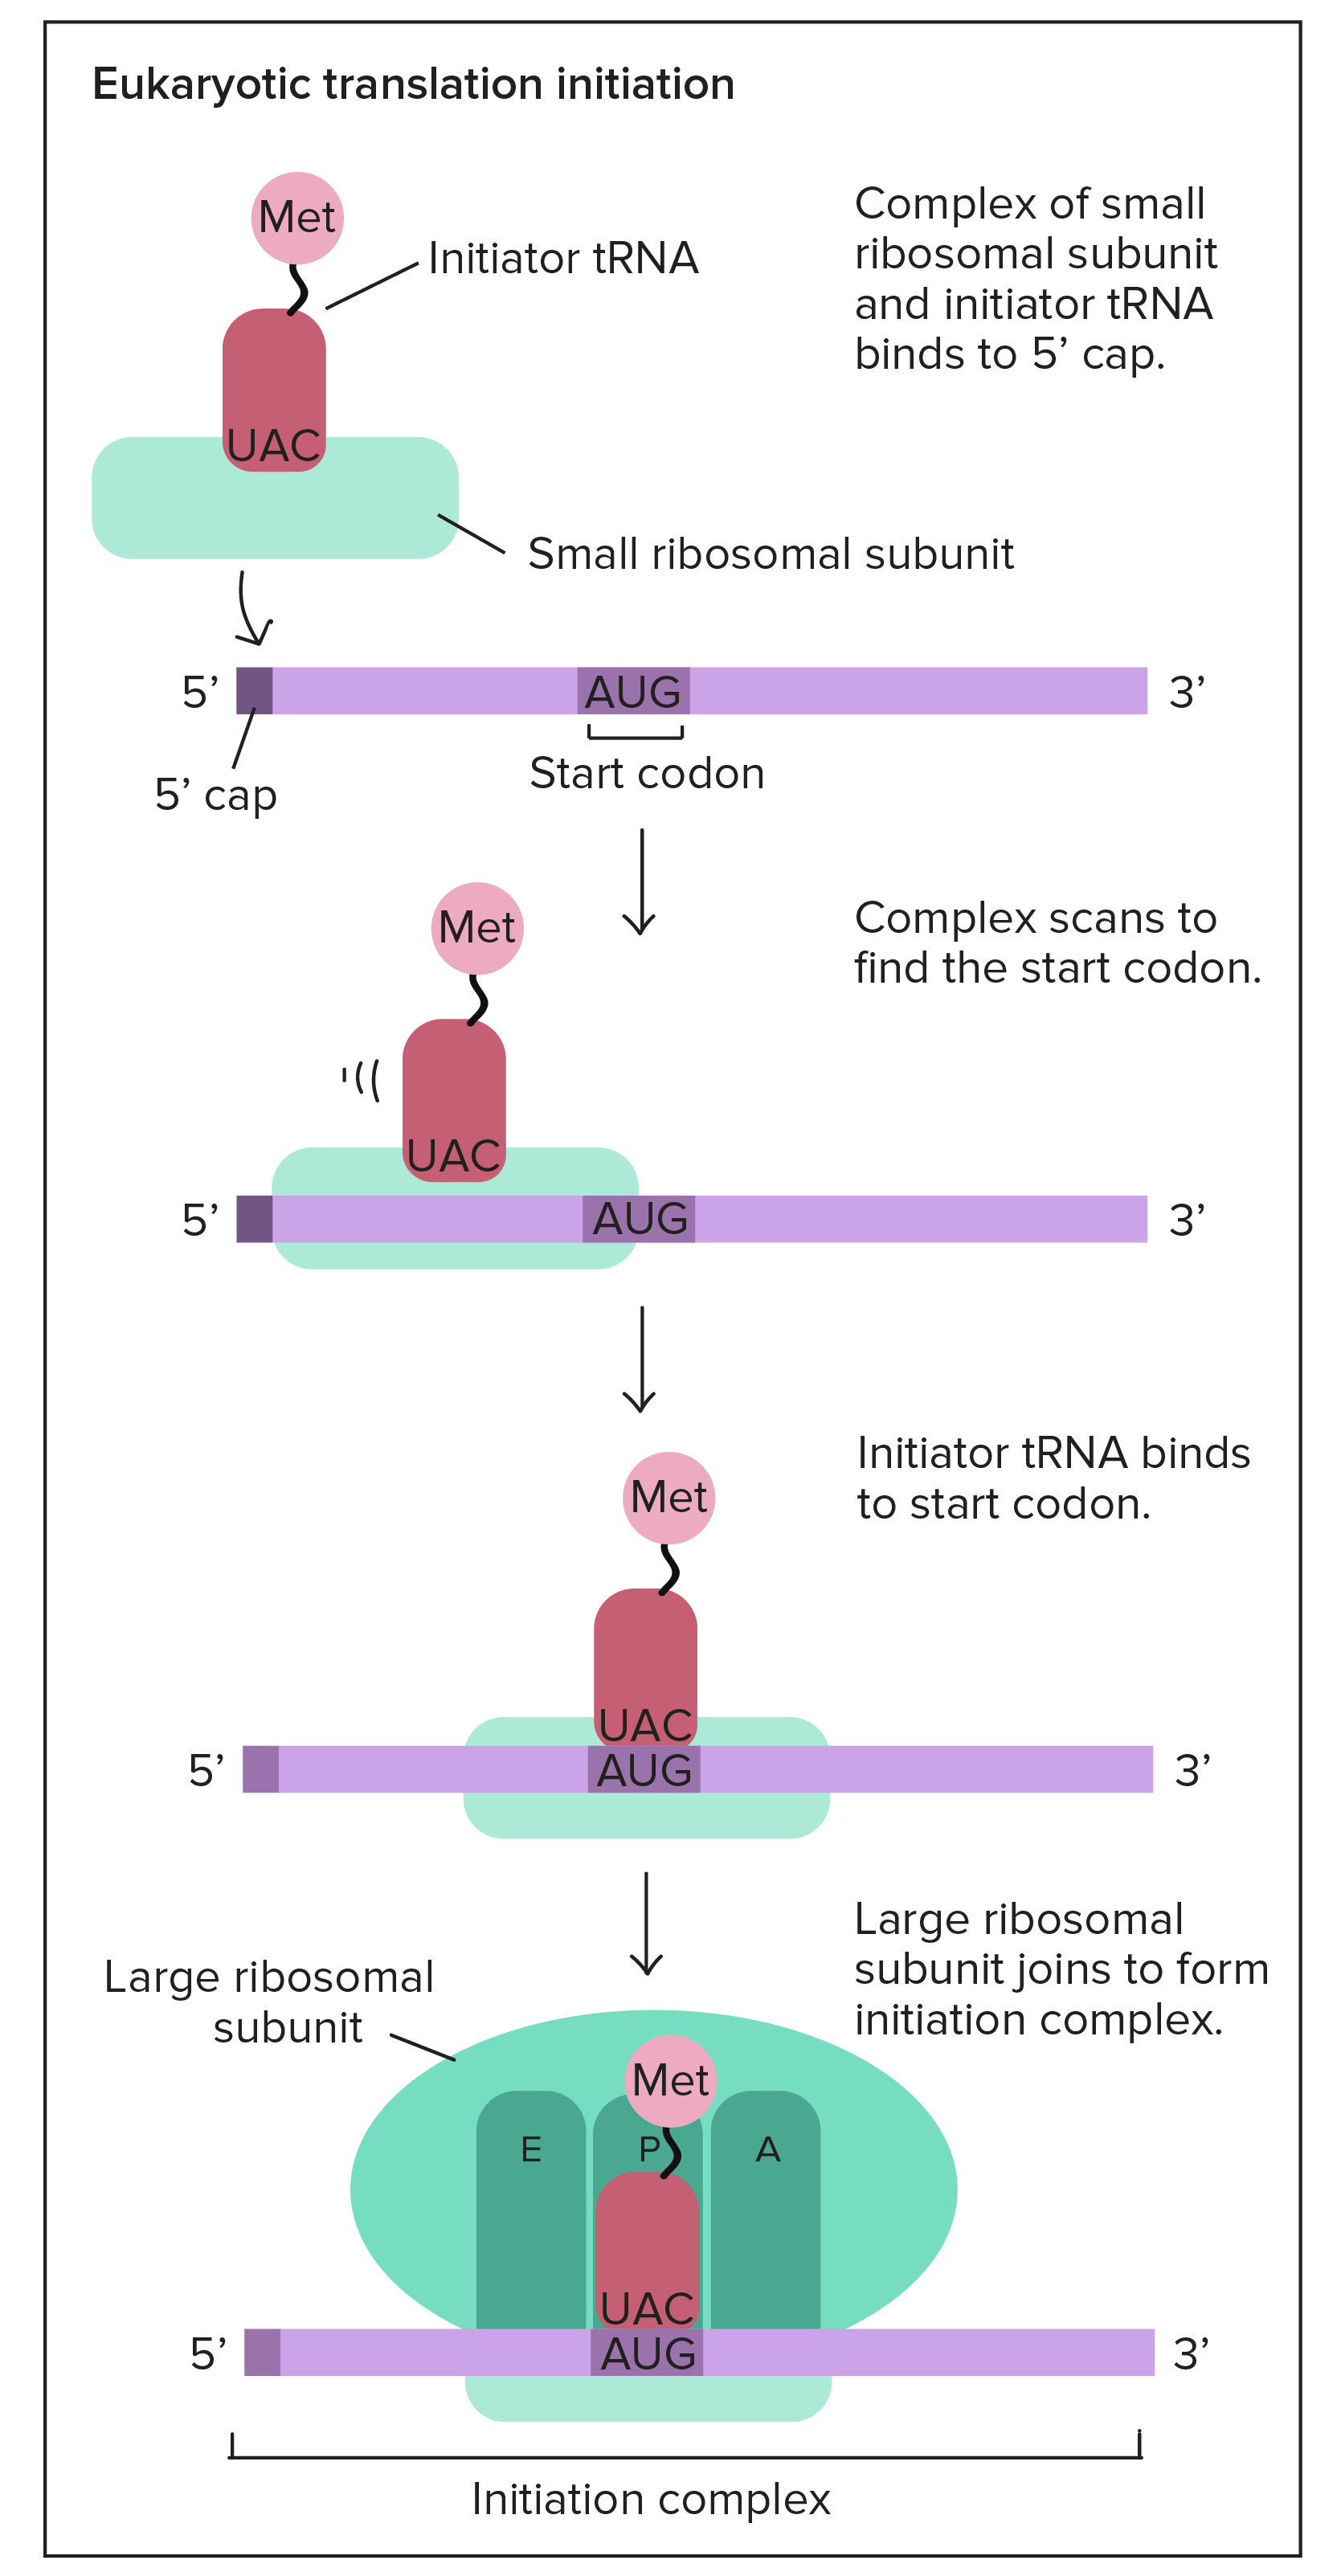
Translation initiation requires a start codon. ATG is the standard, encoding methionine. But GTG and GTT can also serve as start codons in bacteria, and occasionally in eukaryotes. When these are used, the initial methionine is still incorporated, then often removed by peptide deformylase and methionine aminopeptidase during maturation. Stop codons terminate translation. TAA, TAG, and TGA in DNA. These do not encode amino acids. The ribosome releases the polypeptide when it encounters one. In some cases, readthrough occurs, where a near-cognate tRNA inserts an amino acid at a stop codon and translation continues. This is rare but biologically significant in certain contexts, like selenoprotein synthesis where UGA codes for selenocysteine. If your translated protein contains an internal stop codon where you did not expect one, you have a problem. It could indicate a sequencing error, a pseudogene, or a genuine biological phenomenon like RNA editing. Do not ignore it. Check the raw sequence alignment against the reference. Verify the quality scores around that region. Low quality scores at the stop codon position often point to a sequencing artifact rather than a real biological event.
Validating the result
A correct translation should produce a coherent protein sequence. Run it through a basic quality check. BLAST it against a protein database to see if it matches anything known. Check for domain architecture using Pfam or InterProScan. A random sequence of the same length will not give consistent hits across multiple databases. Also check the molecular weight and isoelectric point. Tools like ProtParam give you these calculations instantly. If the values seem wildly inconsistent with related proteins, something went wrong. Either the frame is wrong, the genetic code is wrong, or there is contamination in your sequence. I had a case where a translated protein looked reasonable by BLAST but the predicted molecular weight was half of what it should be. Tracked it down to a misannotated intron boundary. The CDS annotation in the source database included part of an intron, causing a frameshift that introduced an early stop. The protein terminated prematurely. The BLAST hit was still significant because the N-terminal domain matched, masking the problem. Always validate beyond a single similarity search.

Common problems and workarounds
Frameshifts from sequencing errors are the most frequent issue. Small indels shift the reading frame and corrupt the entire downstream translation. These are especially problematic in old Sanger traces or low-coverage next-generation data. Align the sequence to a trusted reference before translating. Fix any obvious indels that break the frame. Do not translate through unverified regions. Partial sequences are another common source of error. If your CDS is missing the start or end, the translation will be incomplete. This matters for functional studies. An N-terminally truncated protein may lack a signal peptide or localization signal. A C-terminally truncated version may miss a degradation tag or membrane anchor. Flag partial translations clearly. Do not treat them the same as full-length predictions. Contamination is worth mentioning. If your sequence comes from a mixed sample, you may translate non-target DNA. I once processed what I thought was a fungal gene. The BLAST results came back as bacterial. The sequence had been contaminated during library preparation. A quick check against the source organism's genome would have caught this earlier. Always verify the taxonomic origin of your sequence before investing time in downstream analysis.
When standard translation fails
Sometimes the standard pipeline does not produce useful results. This happens with non-canonical genetic codes, sequences with extensive RNA editing, or genomes with unusual codon usage that confuses ORF detection. In these cases, you need alternative approaches. For organisms with variant genetic codes, you can manually adjust the codon table in your translation tool. For RNA editing sites, you need to incorporate the edited sequence before translating. Some tools like Ribo-seq based predictors can help identify actual translation products rather than relying solely on sequence features. These are more computationally intensive but more accurate for difficult cases. If you are working with metagenomic data, translation becomes even trickier. You are dealing with thousands of unknown sequences from mixed organisms. Gene prediction pipelines like MetaGeneMark or Prodigal are designed for this. They account for different genetic codes and avoid frameshift issues by training on genomic context. Use these instead of naive six-frame translation when the source material is complex.
Tools I actually use
ExPASy Translate for quick single-sequence checks. EMBOSS transeq for batch command-line work. Biopython for building custom pipelines. NCBI OrfFinder when I need a sanity check on ORF predictions. Prodigal for bacterial genome translation. These cover nearly all my needs. I do not bother with GUI-heavy alternatives unless I am training someone new and need visual feedback. The field has moved toward automated pipelines that handle translation as one step in a larger annotation workflow. Tools like BRAKER and MAKER combine gene prediction, translation, and functional annotation in a single run. They are efficient but require careful parameter tuning. A misconfigured pipeline will produce garbage faster than you can spot it. Understand what each step is doing before letting it run on your data.