Getting Clean Historical Data for Your Backtests
The first thing you need to understand about stock price history is that almost every source you'll find online has some kind of defect built into it. Yahoo Finance used to be the default answer for everyone. Now it returns corrupted data on roughly 15% of symbols without warning. The open-source library yfinance patched around some of it, but split adjustments still break occasionally. I spent about three weeks last year debugging why my backtest results kept looking 30% better than reality. Turns out Yahoo had silently dropped the split adjustment on a few mid-cap tickers I was testing. The prices were raw, not adjusted. This matters because an unadjusted price series will destroy any backtest you run on stocks that have split or paid dividends. A 2:1 split on a $200 stock drops it to $100 overnight. If your data source doesn't adjust backwards, your model sees a 50% crash that never actually happened from a total return perspective. That's the baseline problem. Everything else is a variation on it.
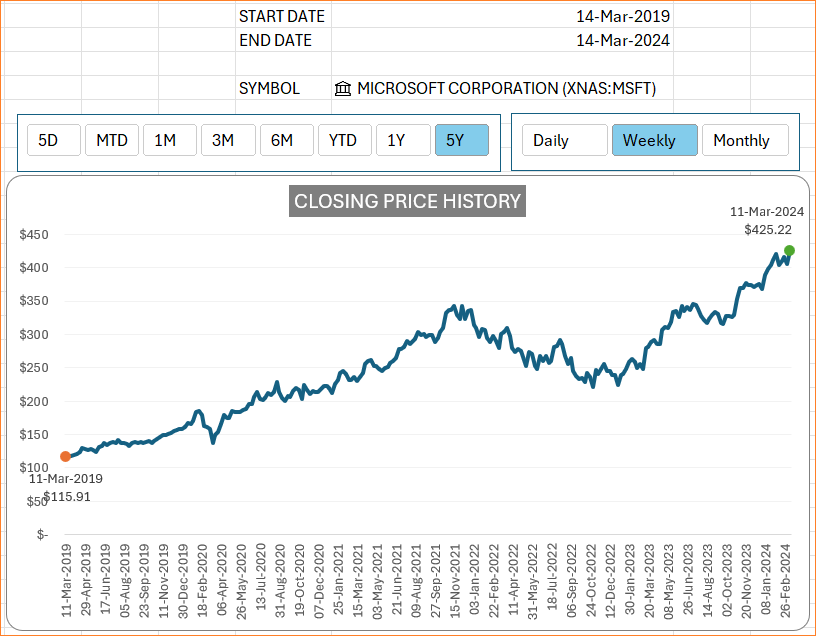
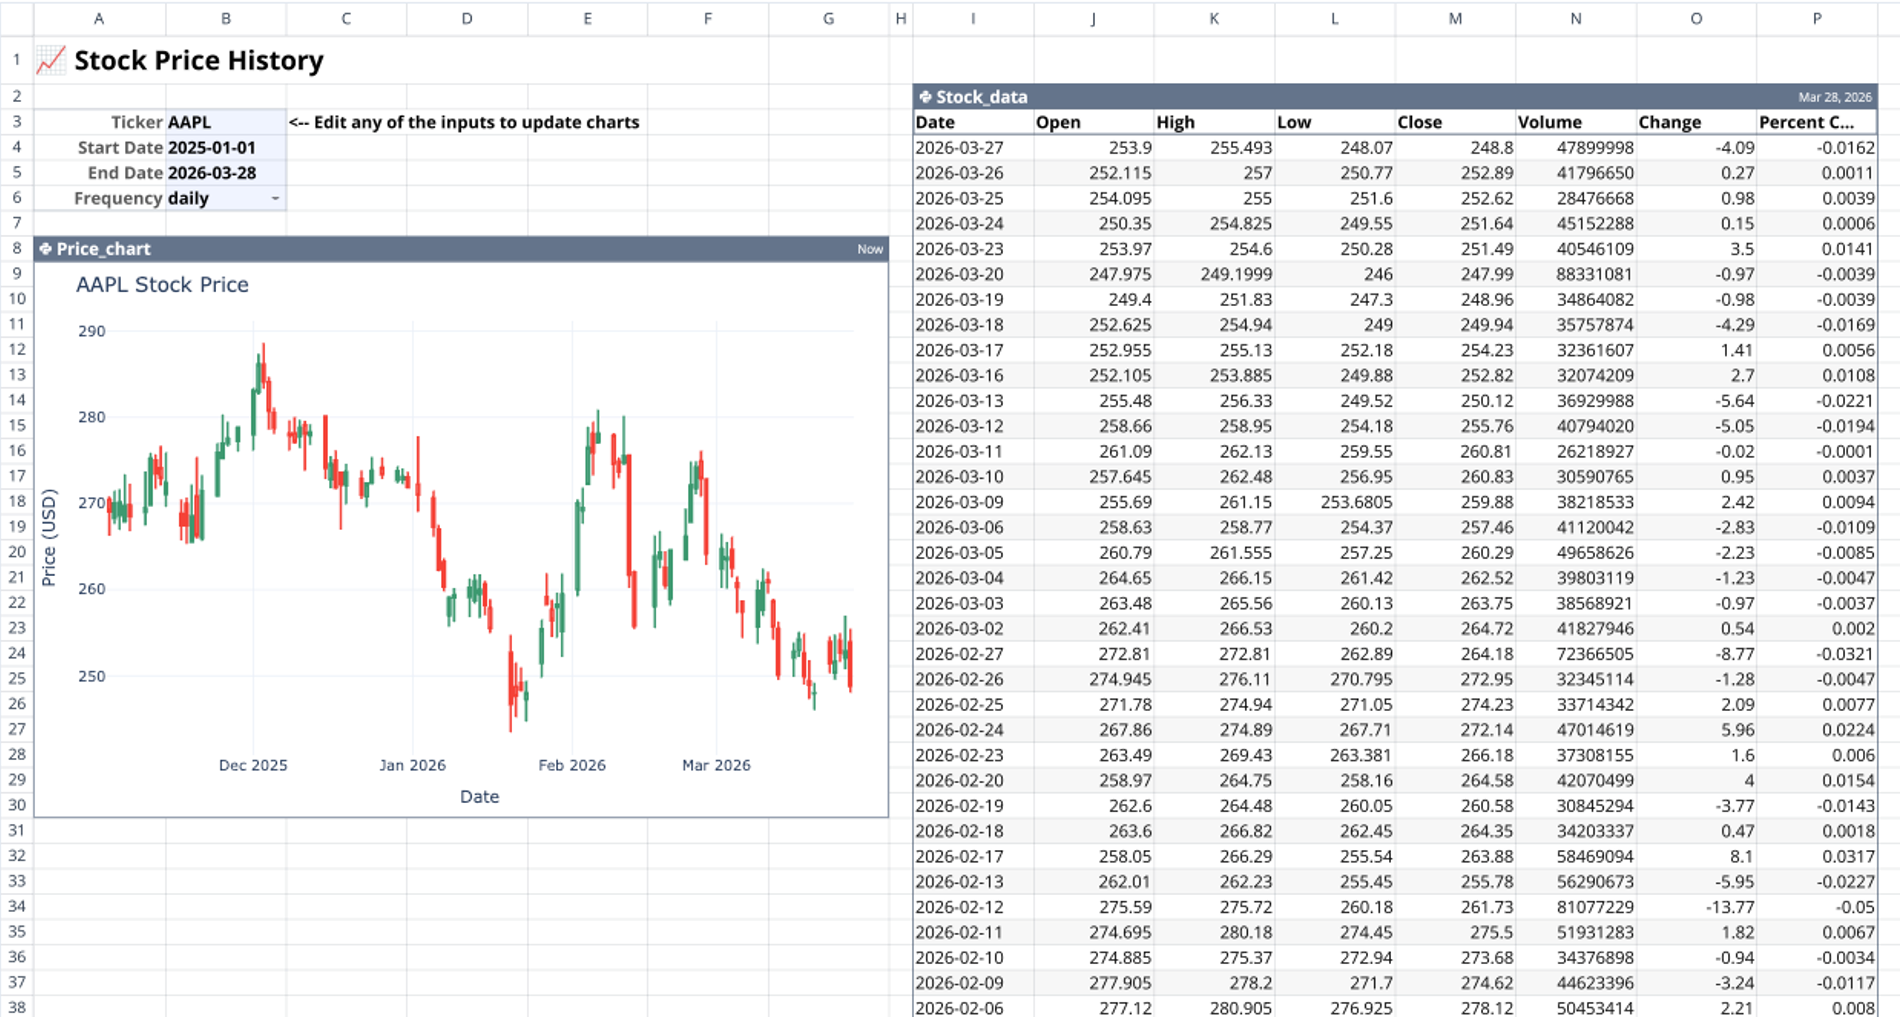
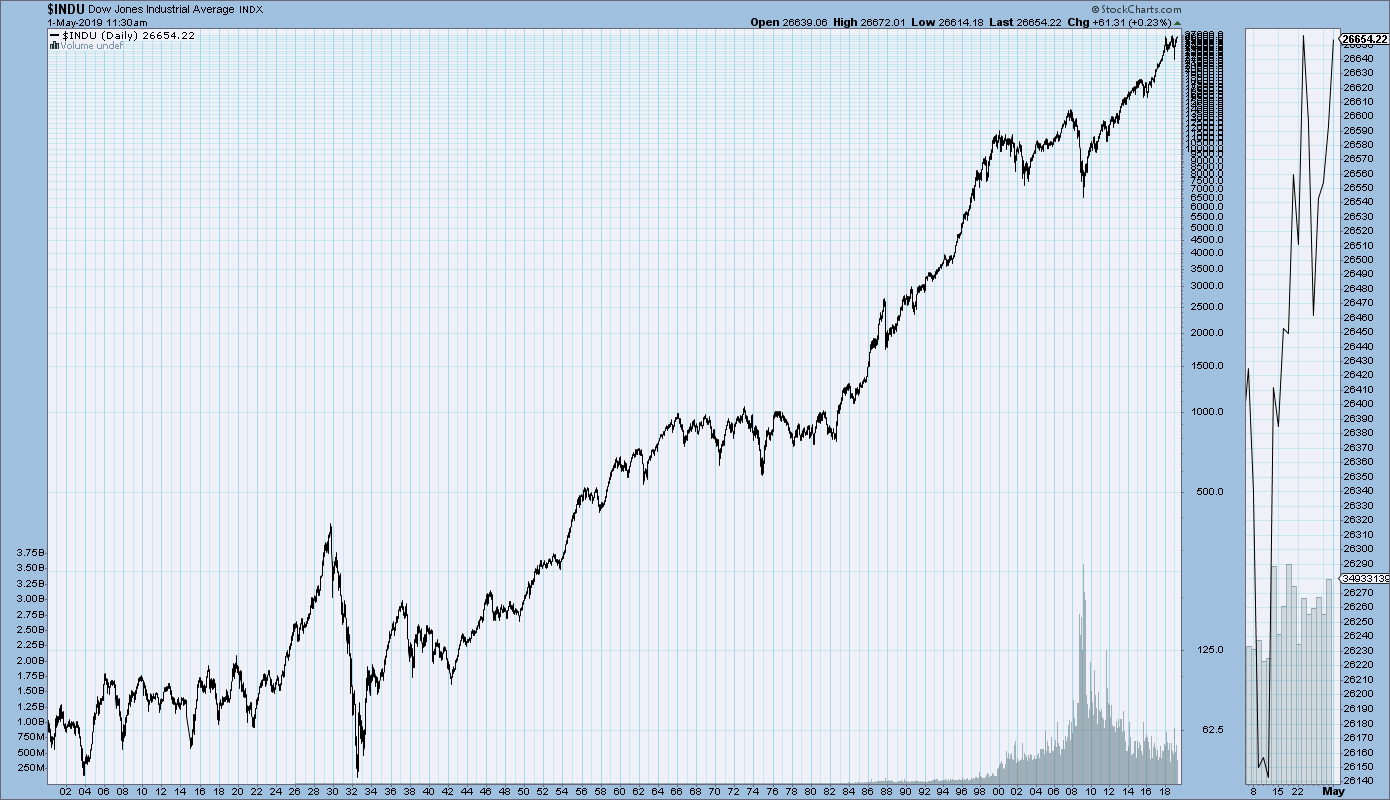
Stock Price History: Where to Actually Get It
If you're doing something casual, FRED (Federal Reserve Economic Data) is free and reliable. They pull from official exchange feeds. The tradeoff is they only go back about 1962 for most equities and the granularity is daily at best. For weekly or intraday, you're out of luck unless you pay. For anything requiring weekly or finer resolution, the practical route is Polygon.io. Their free tier gives you 500 requests per minute and covers adjusted closes back to 1999 for most US equities. It's not perfect — there's about a 2-3 day lag on corporate action adjustments — but it's honest about its delays. I switched from Yahoo to Polygon after the split-adjustment disaster and cut my data wrangling time from maybe four hours a week down to about twenty minutes. The API itself is straightforward. You hit their stocks/events endpoint with a ticker, a date range, and the multiplier you want, and it returns JSON with ohlc candles. The workaround I ended up using for the few tickers Polygon still handled poorly was to cross-reference two sources. I'd pull the same symbol from Polygon and from Alpha Vantage, then write a script that flagged any discrepancy greater than 0.5% on a given day and manually inspected those rows. That manual check typically affected fewer than five symbols out of a 200-symbol portfolio per quarter. The script itself took about an hour to write in Python, using pandas for the merge and difflib to catch alignment issues.
The Mechanics of Adjusted vs Unadjusted Prices
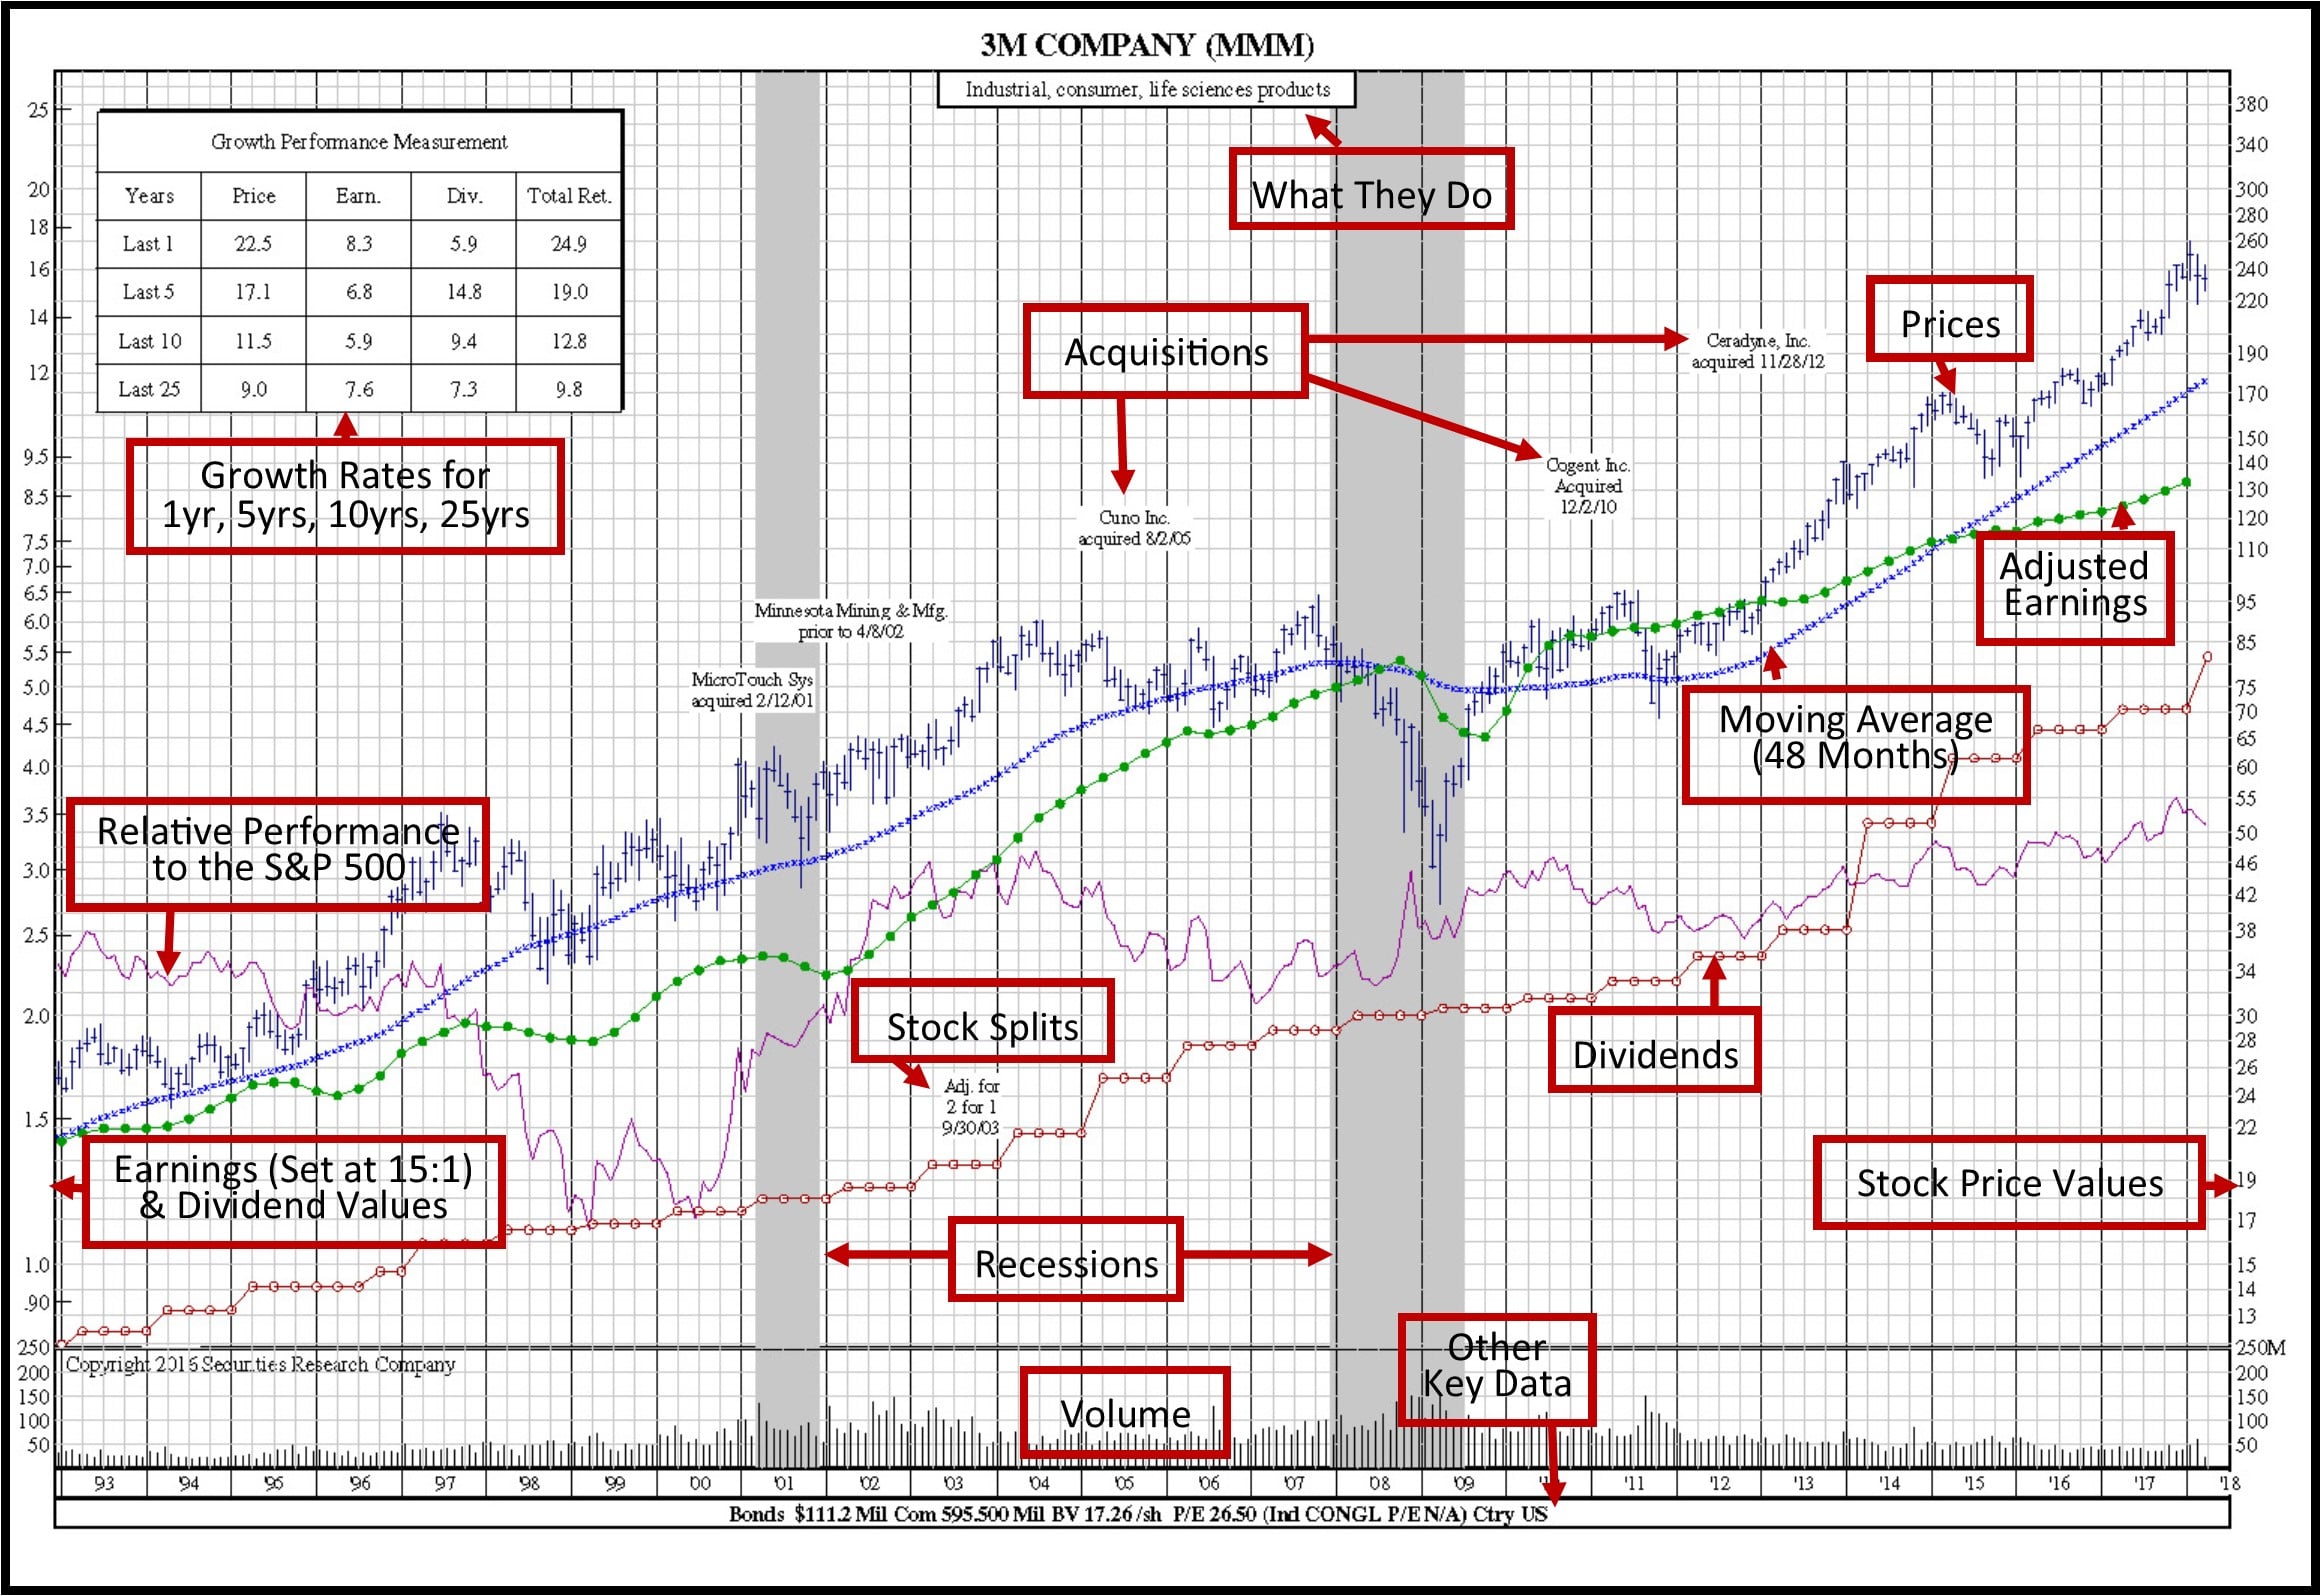
Every serious person in this space needs to know the difference between adjusted and unadjusted closing prices, and more importantly, when each one fails you. Adjusted prices retroactively modify historical data to reflect splits and dividends. An unadjusted series shows what the ticker actually traded at on each day. For most analysis, adjusted is what you want. But there are real cases where using adjusted data gives you wrong answers. Here's a counter-intuitive one: if you're backtesting a strategy that specifically trades around dividend capture, using adjusted prices hides the mechanism you're trying to test. The adjusted close already factors the dividend out. Your strategy appears to gain value from nowhere. The fix is to use unadjusted prices for the signal generation and then layer in the dividend schedule as a separate lookup table. Same thing with spinoffs. When a company spins off a division, the parent stock drops on the ex-date. Adjusted prices pretend that drop didn't happen. If your strategy relies on momentum or mean reversion across that date, you're testing on fantasy data. Another pitfall beginners miss is forward-looking bias in corporate action dates. Some data providers publish the adjusted series before the record date is officially set. This means at the time your backtest runs, it "knows" a split is coming and adjusts prices accordingly. In live trading, you wouldn't know. The fix is to use point-in-time adjusted data, where the adjustments only reflect corporate actions that were known as of that specific date. Yahoo doesn't do this. Polygon doesn't either. Finnhub claims to, but their documentation is vague on exactly how they handle the lag. The only source I've found that gets this reasonably right is TIKR Terminal, but it costs money and the API access is limited on their lower tiers.
Get the Full Details
Building the Pipeline
Here's how I actually pull and clean this data now. I use a Python script that hits Polygon's API, stores everything in a PostgreSQL database, and runs a daily refresh. The script does three things: it pulls the raw ohlc data, it checks for gaps (days missing from the series), and it validates split factors against a secondary source. The gap check alone catches most of the problems. If a ticker that should have 2,500 trading days in a five-year window only has 2,487, something is wrong. The whole pipeline runs in about eight minutes for a portfolio of 150 tickers on a $15 monthly VPS. I've tried alternatives. Running everything in-memory with pandas and saving to CSV works fine for small projects but starts choking around 500 tickers. The database approach scales better because you can query just the symbols you need instead of reloading everything. I also keep a separate adjustments table that logs every split and dividend event with its effective date. When I spot-check a backtest result, I can query that table directly and verify the adjustment logic applied correctly. One thing that saves me from wasting weekends: I never trust a data source that doesn't give you raw, unadjusted prices alongside the adjusted version. If a provider only gives you one or the other, you can't verify their work. Both Polygon and Alpha Vantage provide both. I store both and use the raw series as my ground truth, comparing the adjusted series against it to confirm the math lines up.
What This Doesn't Solve
No retail data source handles all-edge-cases cleanly. Micro-caps and OTC stocks are unreliable across the board. ABOV and similar symbols often have zero-volume days that data providers quietly filter out, making the price series look smooth when it was actually illiquid. Penny stocks can have multi-day gaps where no trades occurred but the provider interpolates prices to make the chart look continuous. This is particularly dangerous for strategies that depend on volatility or drawdown calculations. For institutional-quality work, the only real answer is paid tick data from S&P Capital IQ or Bloomberg. They cost thousands per month and require compliance paperwork. For hobbyists and small funds, Polygon plus the cross-reference workflow I described gets you to about 95% accuracy at a fraction of the cost. The remaining 5% is usually in edge-case symbols that you'd only encounter if you're deliberately trading obscure markets. If you're just starting out, don't overcomplicate it. Pull daily adjusted closes from a reputable source, validate a handful of tickers by hand against the exchange's own historical data page, and build from there. The people who skip validation are the ones who publish backtests that fall apart the moment real money hits them.