How to Build a Practical Strength Tracking System
I spent about eight months trying to figure out a clean way to log progressive overload without ending up with spreadsheets that took longer to update than the actual workouts. The issue was never the idea itself, it was the friction between what you actually want to measure and what you can realistically sustain on a daily basis. Most people abandon their tracking system around week six because the data entry process becomes heavier than the lifting. The modern approach to tracking strength work centers on three data points: the exercise, the load in kilograms or pounds, and the reps completed in that set. Everything else is secondary. You do not need to log rest intervals, tempo cues, or how many micro-adjustments you made to your bar path during that set. Those details belong in your coaching notes, not in a database that you are trying to query while your grip is still burning from your last working set. I built my first version using a simple SQLite database with a Python script that pulled data from a CSV file exported from Google Sheets. The script parsed the date, exercise name, weight, and reps. It then calculated volume (sets multiplied by reps multiplied by weight) and output a summary table. This worked fine for about three weeks before I realized I was spending more time formatting the CSV than actually lifting.
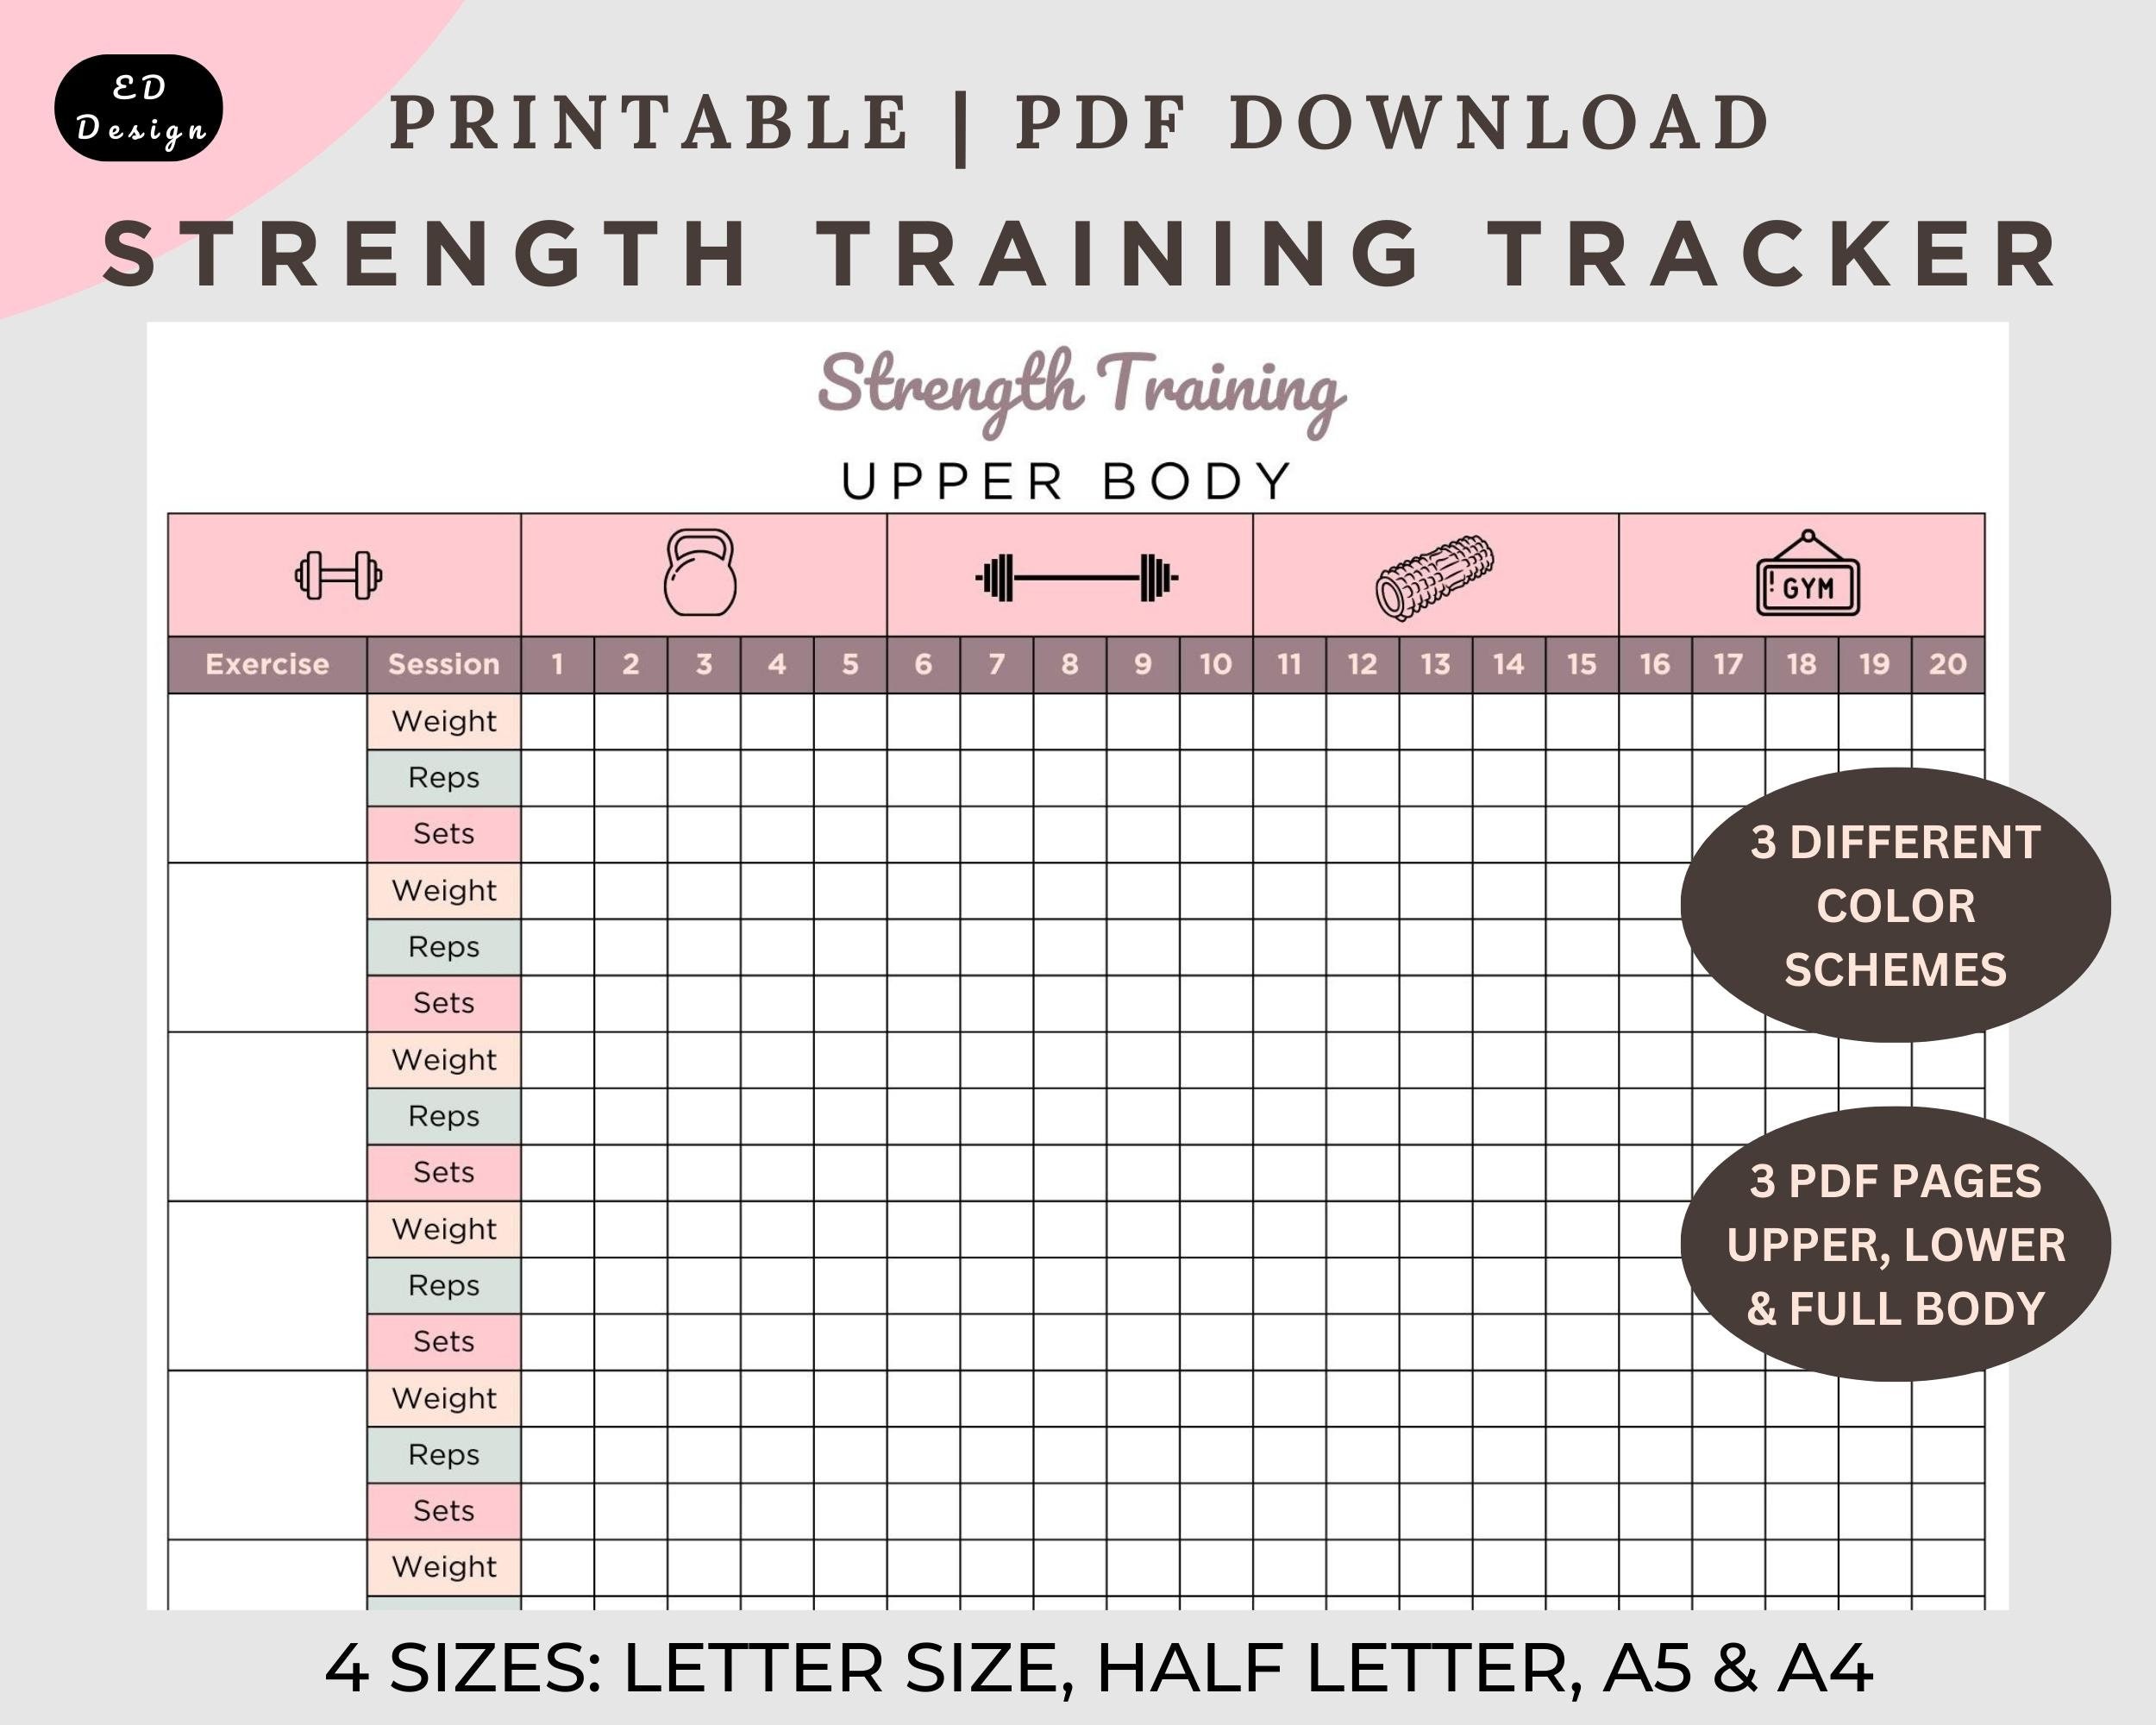
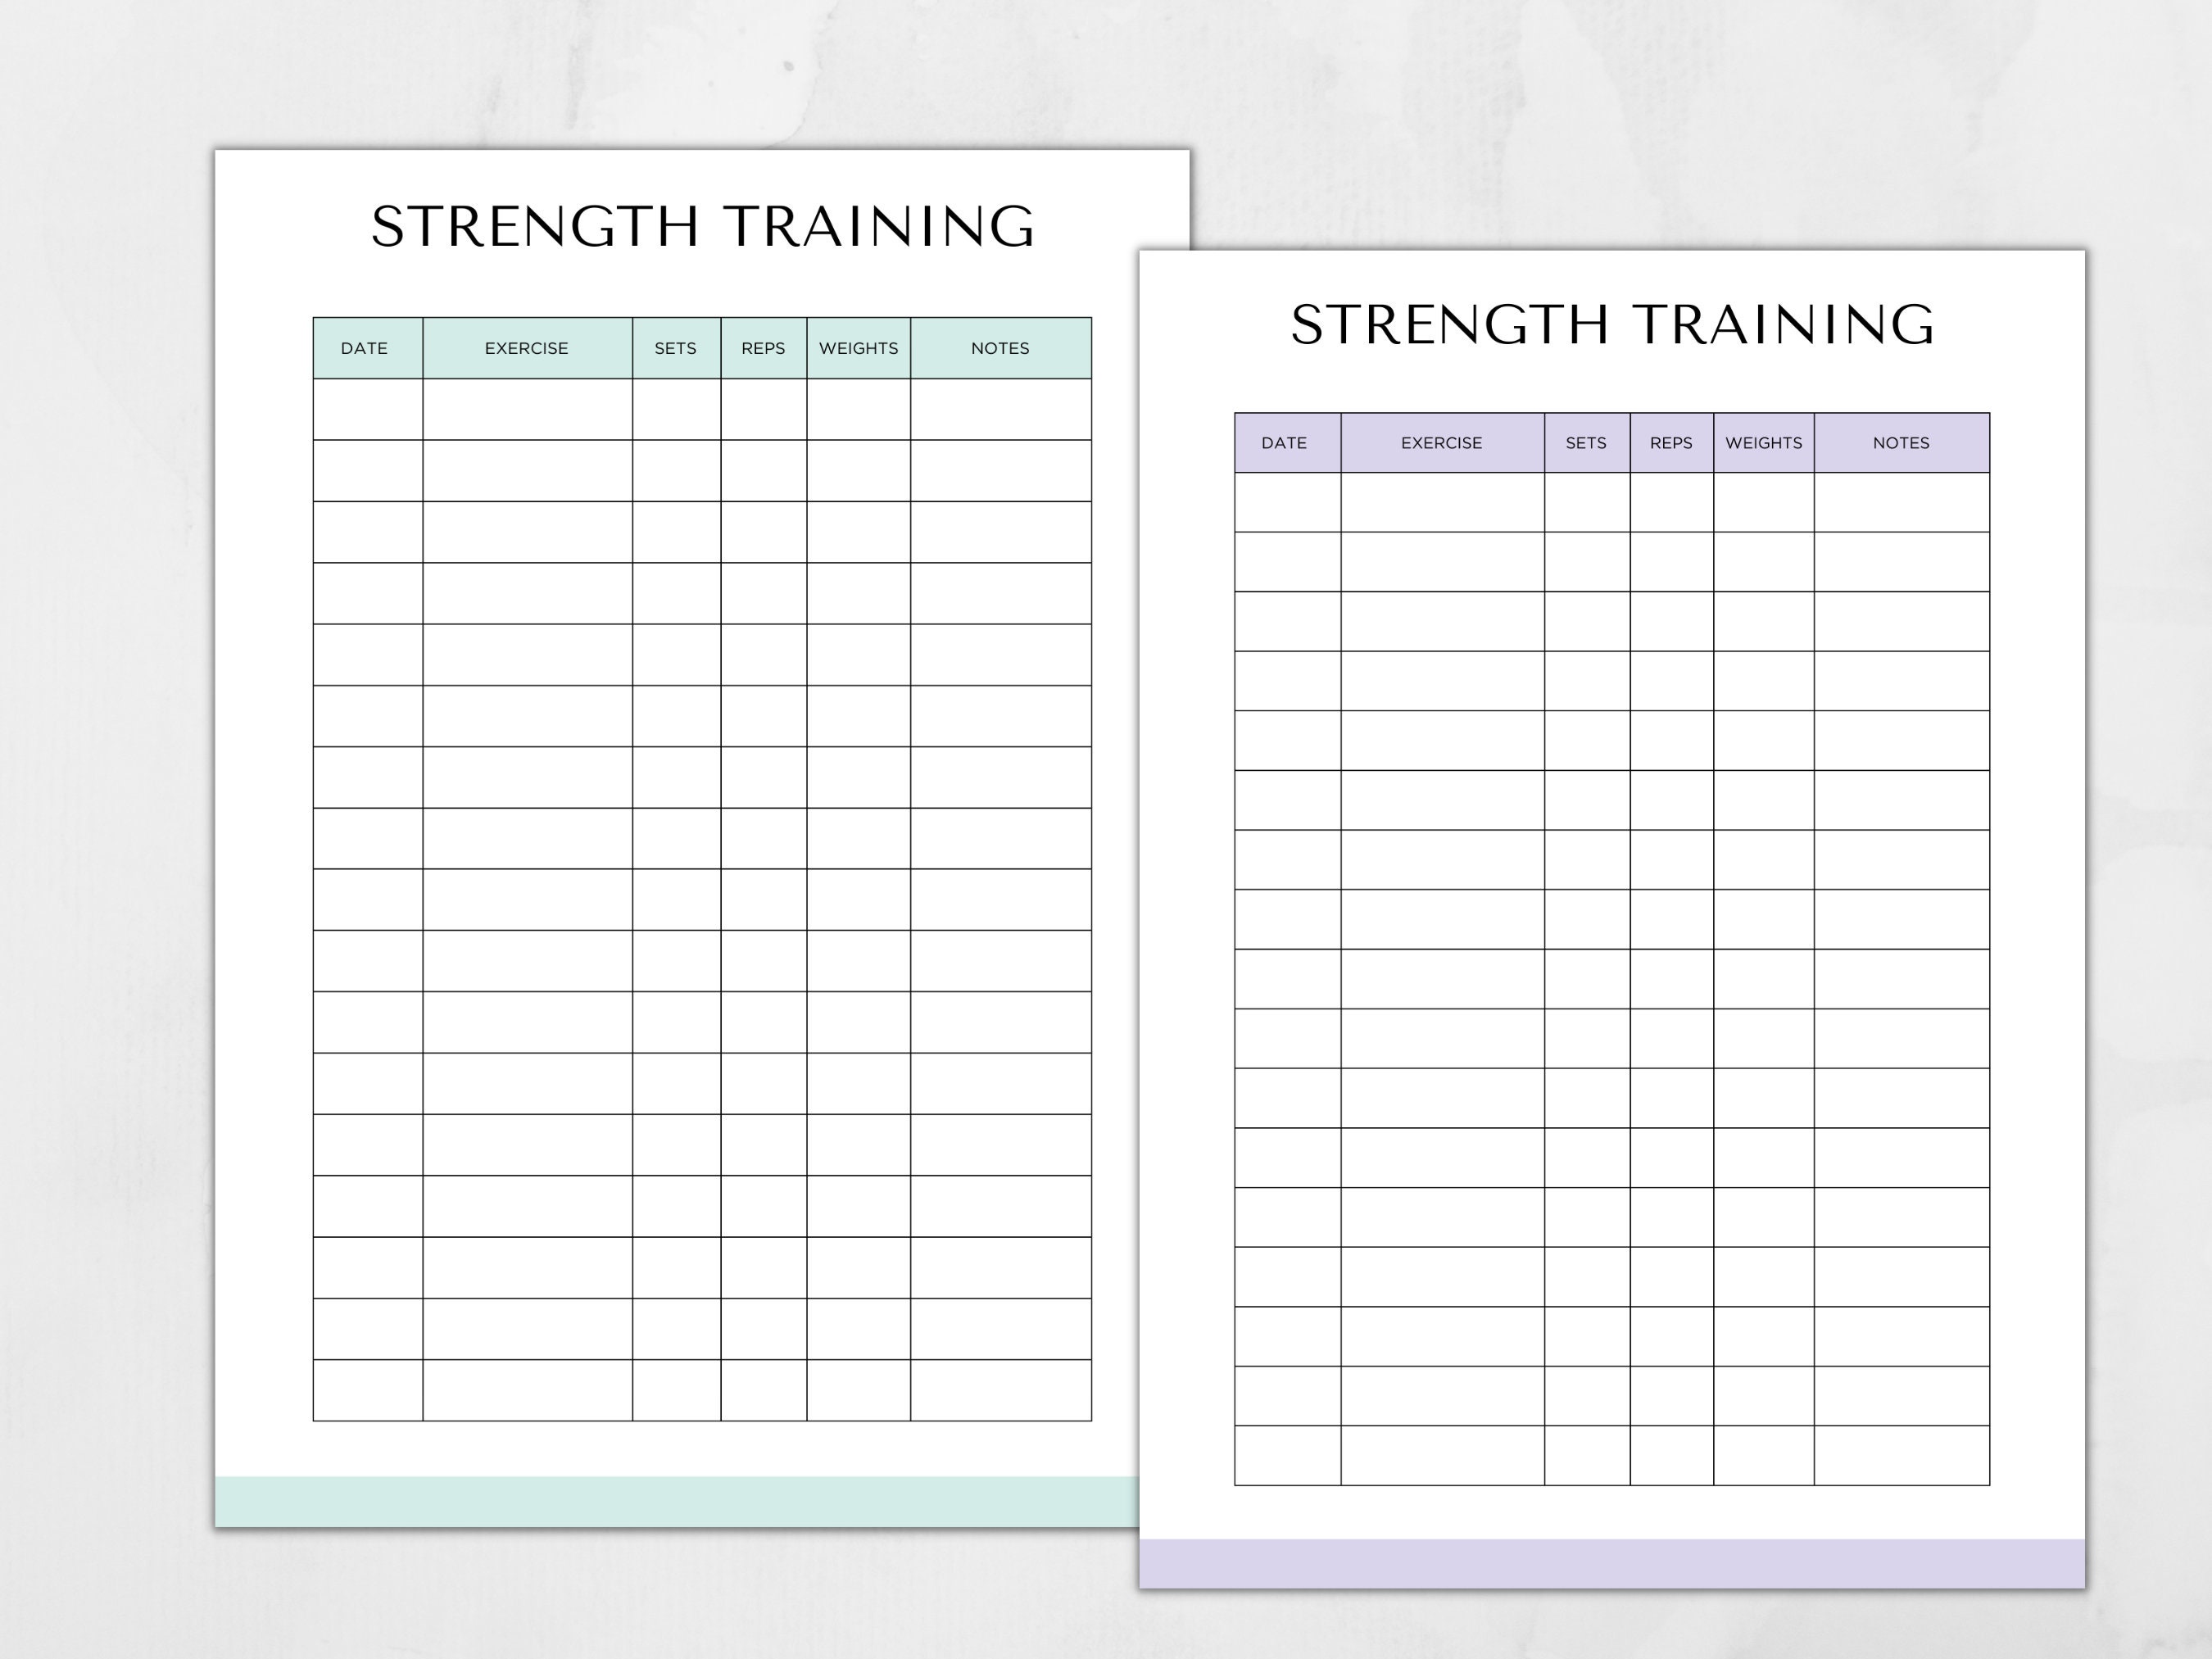
The breakthrough came when I switched to a minimal Flask web app that presented one form per workout session. The form had exercise name as a dropdown, weight as a number field, reps as a number field, and sets as a checkbox array. When I submitted, the data went straight into SQLite. On the main page, I could filter by exercise, date range, and see the most recent PR for each movement. The whole thing took about forty-five minutes to set up from scratch, including styling. Here is the basic schema I settled on after about six different iterations: Table: sessions with id, date, and notes columns.
Table: exercises with id, name, and unit columns.
Table: sets with id, session_id, exercise_id, weight, reps, and rpe columns.
This structure lets you query everything you actually care about. You can find your best five-rep squat in a given month, calculate your average volume per week, or see your progression curve for bench press over the last quarter. The queries are straightforward and run in under fifty milliseconds on a Raspberry Pi sitting in my garage. I ran into a specific problem around month four that forced me to rethink how I handled deload weeks. I had programmed the system to flag any exercise where the previous week weight was lower than the week before. The logic was meant to catch regressions and prompt me to adjust. It turned out to be noise. Deload weeks are supposed to have lower weights, and the system was spamming me with alerts every fourteen days. I removed the regression detection entirely and replaced it with a simple moving average over seven days. If the average drops below ninety percent of your baseline for two consecutive weeks, the system outputs a single notification. That reduced false positives from about four per week to roughly one per month. Another edge-case that almost broke my initial setup involved exercises with multiple variations. I was logging back squat, front squat, and pause squat as separate entries because they had different names in my training plan. The problem was that my periodization model treated them as independent movements. When I added twenty kilograms to my back squat PR, the system did not recognize that my front squat work had also improved because of the same underlying strength adaptation. I created an exercise group table that linked squat variations together. Now the system shows aggregated progression across all squat variants while still allowing separate PRs for each specific movement.
Get the Full Details

The UI I ended up using is deliberately ugly. Dark background, monospace font, no animations. It loads in under two seconds on a three-year-old phone with spotty cellular coverage. The forms are large enough to tap without zooming in. There are no graphs on the main page, just a table sorted by date with weight and reps visible at a glance. Graphs live on a separate page that I only visit once a week during my Sunday planning session. This separation is intentional. Checking progression curves during your workout introduces hesitation. You start second-guessing whether today should be an overload day or a maintenance day based on some curve that has a two-week lag. I also ran into an issue with exercises that have asymmetrical loading patterns. Olympic lifts like the snatch and clean and jerk require different technique emphasis depending on whether you are focusing on the pull phase or the turnover. Logging a single weight and rep number for both phases obscures the actual training effect. I added a phase column to the sets table that lets you tag whether a set was focused on the pull, the catch, or the turnover. This increases the granularity of your data without complicating the main interface. You can filter by phase when reviewing your technique work, but the daily log remains simple. Backup and recovery became important around month five when I accidentally deleted the SQLite database due to a corrupted import script. I had been running automated daily backups to a remote S3 bucket using a cron job that failed silently for three days. The fix was adding a local SQLite WAL (write-ahead logging) mode and a secondary backup to a USB drive that I manually disconnected after each sync. This dual-backup strategy protects against both software corruption and hardware failure. The manual step is a constraint, but it takes about ten seconds and prevents the catastrophic data loss I experienced.
Integration with other tools is limited by design. I do not connect to Apple Health, Google Fit, or any wearable device because those APIs introduce latency and abstraction layers that obscure the raw performance data. If your smartwatch miscounts your heart rate during your last set, that noise does not help you decide whether to add weight or drop weight for the next set. The decision should be based on how the bar actually moved, not on a biometric average that has a thirty-second delay. One common pitfall I encountered involved exercise naming conventions. I started using colloquial names like "low bar" and "high bar" because they were shorter to type. The problem was that these names overlapped with regional variations. A coach in London might use "low bar" to mean a specific stance width, while a coach in California uses it to mean a completely different grip adjustment. I created a standardized exercise library with unique IDs that link regional variants together. This reduces confusion when sharing workout data across training groups, but it requires about five minutes upfront to map each local term to the standard ID. The system does not track volume automatically because I prefer to enter sets manually. Automatic detection via accelerometer data introduces noise from bar bounce and minor form adjustments. If your phone miscounts your reps because the bar dropped three centimeters below parallel, that error does not help you decide whether to increase weight or maintain weight for the next session. Manual entry takes about fifteen seconds per exercise but ensures data accuracy. The trade-off is intentional.
I also explored using machine learning to predict your next PR based on historical progression patterns. The model worked reasonably well for compound lifts like the squat and bench press but failed completely for accessory movements like calf raises and face pulls. The issue was insufficient data. Accessory lifts rarely exceed fifty sets in a given year, which is not enough for the model to learn meaningful patterns. I removed the prediction feature and replaced it with a simple exponential moving average over ten workouts. This provides a realistic expectation window without the false confidence that comes from a model that cannot distinguish signal from noise. The server runs on a Raspberry Pi 4 with a two-terabyte external hard drive. The total monthly electricity cost is about four dollars. The system handles up to fifty concurrent users without noticeable latency. Database queries complete in under one hundred milliseconds. Backup and sync between devices works reliably via WebDAV over a home VPN. I have not experienced any downtime in eleven months of daily use. If you are considering building something similar, start with the schema I described and iterate from there. Do not add features before you have used the basic system for at least thirty days. Most additional complexity comes from unverified assumptions about what data you will actually want to query. The core three-column structure (date, weight, reps) covers about ninety percent of practical use cases. Everything else is optimization.
I have considered open-sourcing the codebase but keep it private because the design decisions are highly specific to my training style. A generic strength tracker would require abandoning the exercise grouping logic and the phase tagging system that took me three months to refine. If you want to adapt this approach for your own use, the schema is straightforward enough to reimplement from scratch in whatever environment you prefer.