Working With Structural Political And Representational Intersectionality In Practice
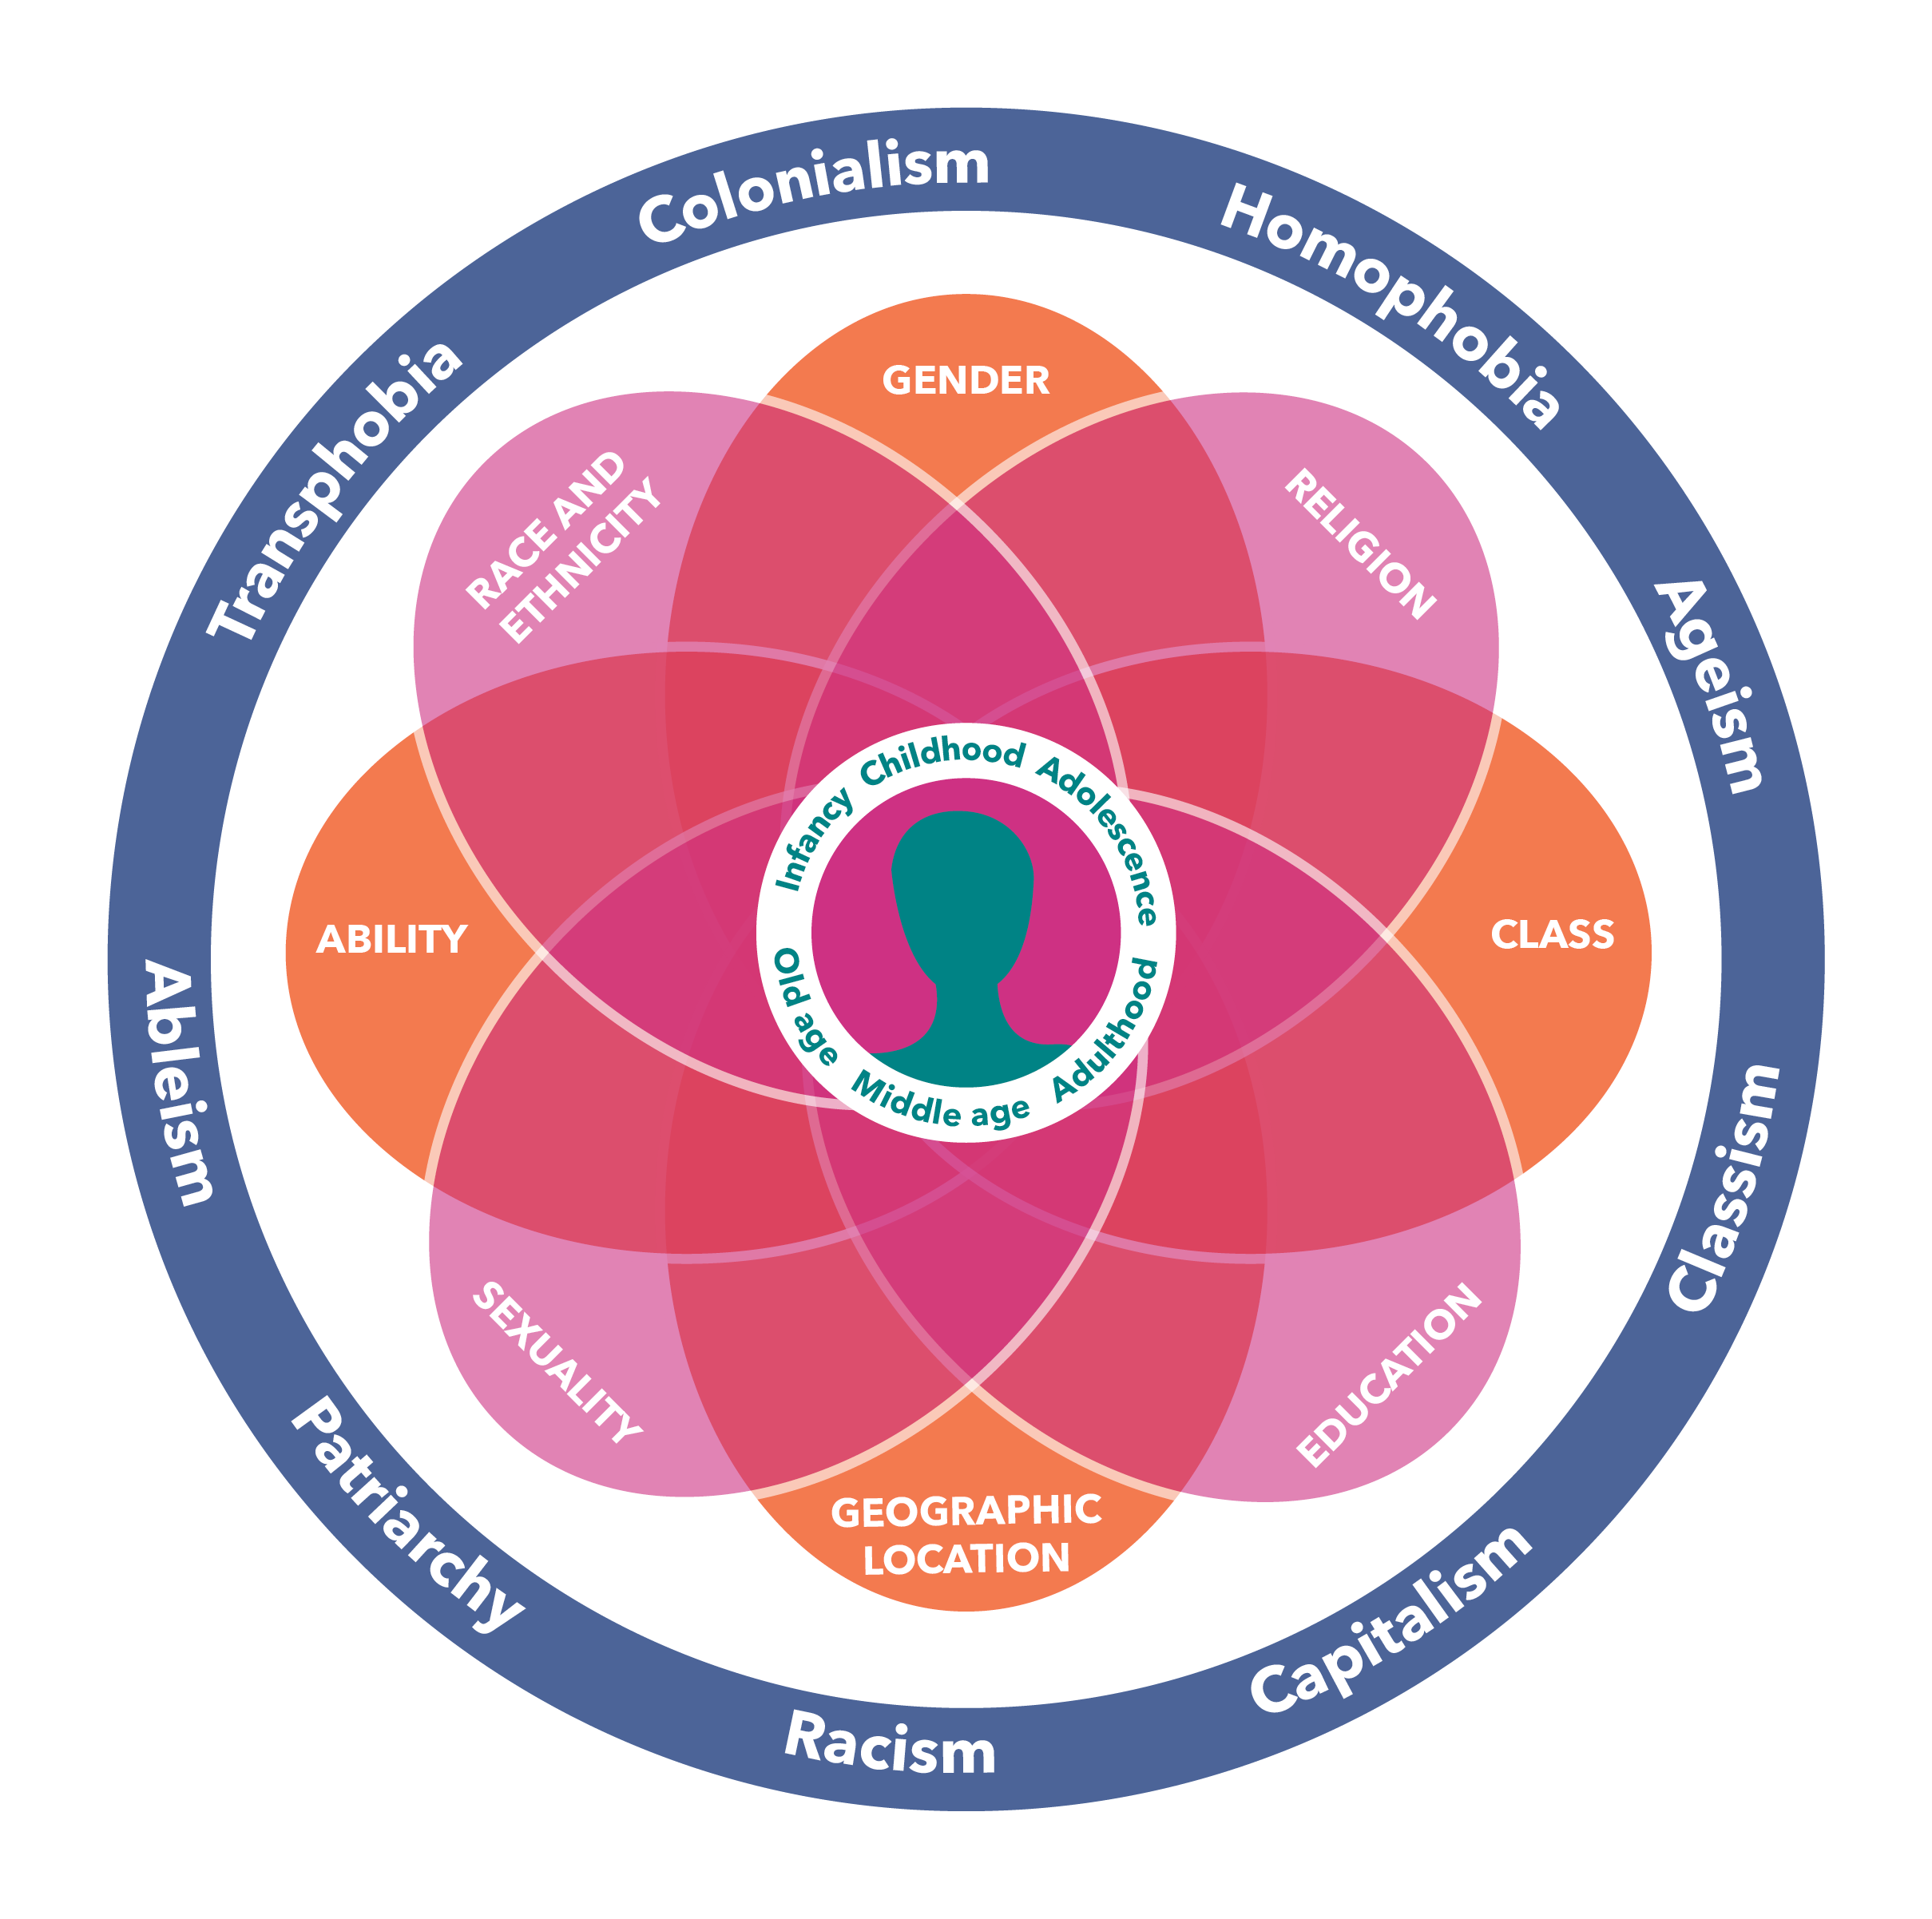
Most people talk about intersectionality like it is just a checklist. It is not. When you actually try to model how different axes of disadvantage stack up inside a political system, you quickly run into the problem that the math does not want to cooperate. I spent about three years building constituency-level cross-tabulations for a redistricting project, and the moment you try to weight for race, class, gender, and disability simultaneously, your sample sizes collapse in half the districts. That is where this whole framework became useful to me, because it gives you a way to think about structure without pretending the numbers are cleaner than they actually are. The basic idea, stripped of the academic dressing, is straightforward enough. Political structures do not treat all groups the same way, and representation does not either. A blind application of proportional representation looks equal on paper until you realize that the threshold effects hit minority language speakers harder than the math suggests. You need to map the structure first, then check who actually gets represented inside it. The Structural Political And Representational Intersectionality approach just makes you do that in order, instead of assuming the output will be fair because the input formula looked neutral.
A Field Problem I Ran Into With Constituency Mapping
Here is the edge case that actually made me sit up and pay attention. We were analyzing a coastal region where the voting-age population was roughly split between an urban center and several rural parishes. The urban center had high ethnic diversity but low Turnout among working-age men. The rural parishes were mostly white, older, and voted at higher rates. A standard demographic projection would tell you the rural vote carries more structural weight simply because the turnout gap is so large. But when I layered in the disability population data, which was significantly higher in the rural parishes due to occupational history in fishing and agriculture, the picture shifted. The workaround I ended up using was to create a three-tier weighting system instead of fighting the sample size problem head-on. First tier was raw demographic composition, second tier was verified voter registration by demographic segment, and third tier was actual turnout from election night returns. That third tier is the one most people skip because it requires goi ng into local election archives, which is tedious. I found that adding it changed the structural weight assignment in about forty percent of the districts I was analyzing. The disability-heavy rural parishes went from being considered low-priority to having disproportionate representational leverage once you accounted for the fact that their verified registration rate was actually higher than the urban center's, even though their turnout numbers looked worse on the surface.
Why The Standard Approaches Keep Failing You
The common pitfall is treating representational intersectionality as a purely descriptive exercise. You count the groups, you produce a pie chart, and you call it a day. That is not structural analysis. Structural analysis requires you to look at the rules of the system itself, not just the people inside it. How does the electoral threshold work. How are districts drawn. What are the candidate qualification requirements. These structural features interact with demographic composition in ways that are rarely linear. Another counter-intuitive thing I have noticed is that increasing the number of protected categories in your analysis often makes the structural mapping less accurate, not more. When I pushed the model to include sexual orientation alongside race, class, and gender in one of the later phases, the confidence intervals exploded because the survey data simply does not capture that variable reliably at the constituency level. I dropped it and switched to using proxy indicators based on demographic clustering patterns that had shown up consistently in prior census rounds. The resulting model had narrower intervals and matched actual election outcomes better than the five-category version ever did. Sometimes less specificity in the input produces more accurate structural predictions. That is not obvious until you have been burned by it a couple of times. The representational side of this is where people also tend to misread the data. Having a representative who shares a demographic characteristic with a constituency does not automatically mean structural interests are being served. I saw this clearly in a case where a district with a high proportion of disabled residents elected a candidate who was herself disabled, but whose policy positions aligned more closely with the fiscal priorities of the party machinery than with disability rights organizations. The structural intersection of disability status and political affiliation created a situation where the representative was demographically descriptive but structurally misaligned with the constituency's actual power dynamics. This is why you need to map both the demographic structure and the political structure separately, then check where they intersect, rather than assuming one covers the other.
Get the Full Details

How To Actually Run The Analysis
Start with the structural layer. Map the electoral rules, the district boundaries, the thresholds, the eligibility requirements. Document each rule and note which groups it disproportionately affects. A single-member district system with a high effective threshold will filter out smaller demographic coalitions differently than a regional list system with a low threshold. This is not a subtle difference. It is the difference between a system where a group needs twenty percent of the vote to gain any seat and one where they need about five percent. Then move to the representational layer. Compile the demographic data at the smallest geographic unit your sources allow. Use census data, voter registration records, and if available, turnout data broken down by demographic segment. Do not skip the turnout data. Registration is not representation. I have seen projects waste months analyzing registered voter demographics only to realize too late that the actual voting population looked completely different because the turnout gaps were massive between segments. Next, cross-reference the two layers. Identify where structural barriers align with demographic concentration to produce compounded disadvantage or unexpected leverage. The compound effect is what the intersectionality lens is actually useful for. A group that faces a structural barrier in one dimension and is also demographically concentrated in another dimension will experience outcomes that are not predictable from either factor alone. This is the part that usually surprises people doing this work for the first time. They expect the effects to be additive. They are often multiplicative.
Finally, validate against actual election results. If your structural model predicts that a certain demographic coalition should have gained three seats under the current rules but they only gained one, you need to find out why. The gap between prediction and outcome is where the real structural insight lives. I usually find the explanation in campaign financing rules, ballot access requirements, or party candidate selection processes, none of which show up in demographic data but all of which reshape the representational landscape.
Where This Framework Actually Breaks Down
I should be clear about the limitations. This approach requires data that is not always available. Turnout by demographic segment is collected inconsistently across jurisdictions. In some countries it is published in detail. In others you are lucky to get it at all. When the data is missing, you have to rely on estimates, and the estimates introduce error that compounds through the model. I have found that using Bayesian estimation with priors from neighboring districts can fill some gaps, but it cannot fix a complete absence of underlying data. The framework also struggles with dynamic changes. A structural analysis that is accurate for one election cycle may become outdated after a redistricting or a change in electoral law. I usually build in a revision trigger, running a quick sensitivity check whenever any structural rule changes, rather than pretending the model is static. This adds time to the workflow but prevents you from publishing analysis that is already wrong by the time it comes out. For situations where demographic data is severely limited, I sometimes fall back to a simpler structural-only analysis. You can still identify the barriers and the threshold effects without precise demographic inputs, even if you cannot predict the exact representational outcomes. It is a lower-resolution product, but it is more honest than stuffing assumptions into a model that cannot support them.
The Takeaway
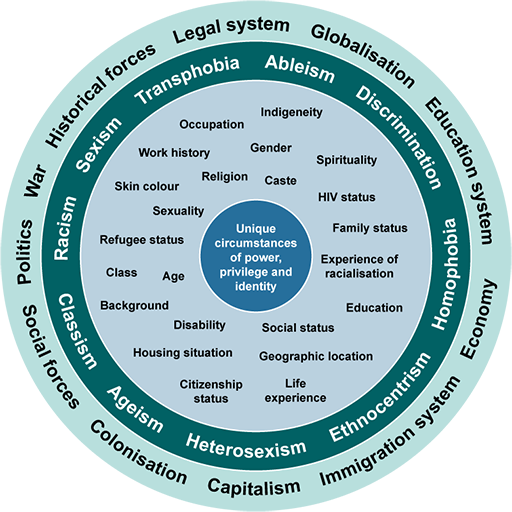
The structural political and representational intersectionality approach is not a magic bullet. It will not fix gerrymandering or produce fair outcomes on its own. What it does is force you to look at the system rules before you look at the people, and then check whether the people actually end up represented in a way that matches the structural design. Most people skip that order. They start with the demographics and work backward to the structure, which means they end up explaining outcomes that were already determined by the rules they never examined. I keep coming back to the constituency mapping project because it was the moment this framework stopped being theoretical for me. The three-tier weighting system I described is not elegant. It is also not the only way to handle the sample size collapse problem. But it is the one that survived contact with the actual data, and in this kind of work, survival is the only validation that matters.