Working with the Student T Distribution Table Without Losing Your Mind
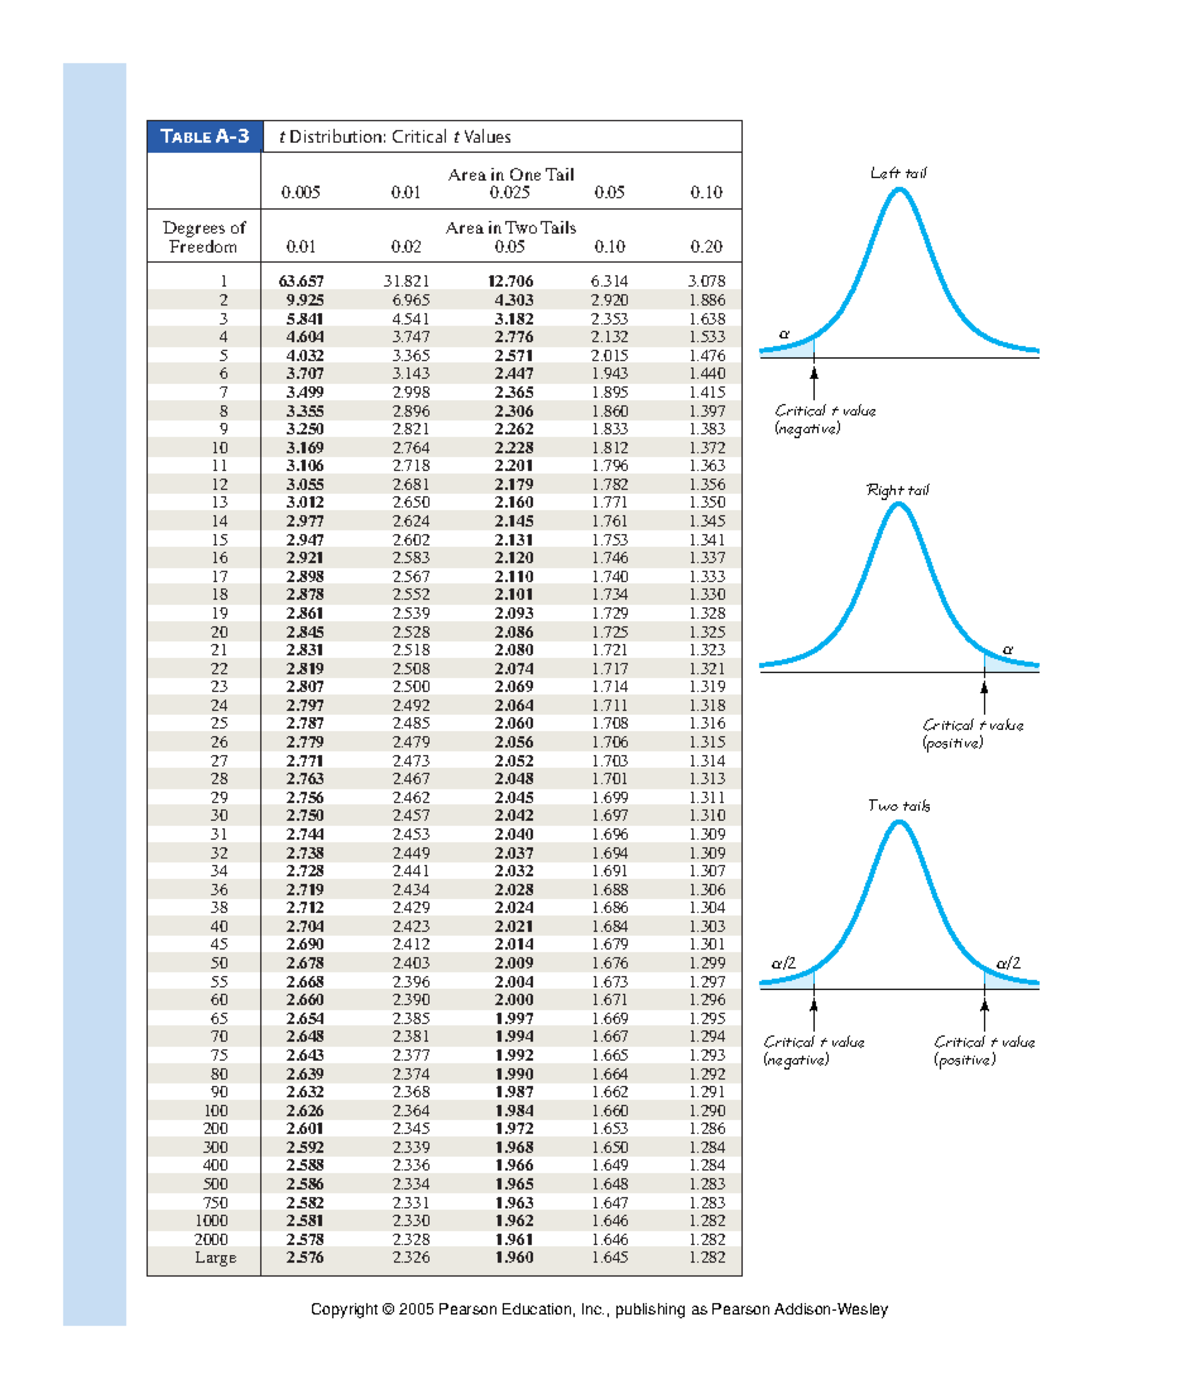
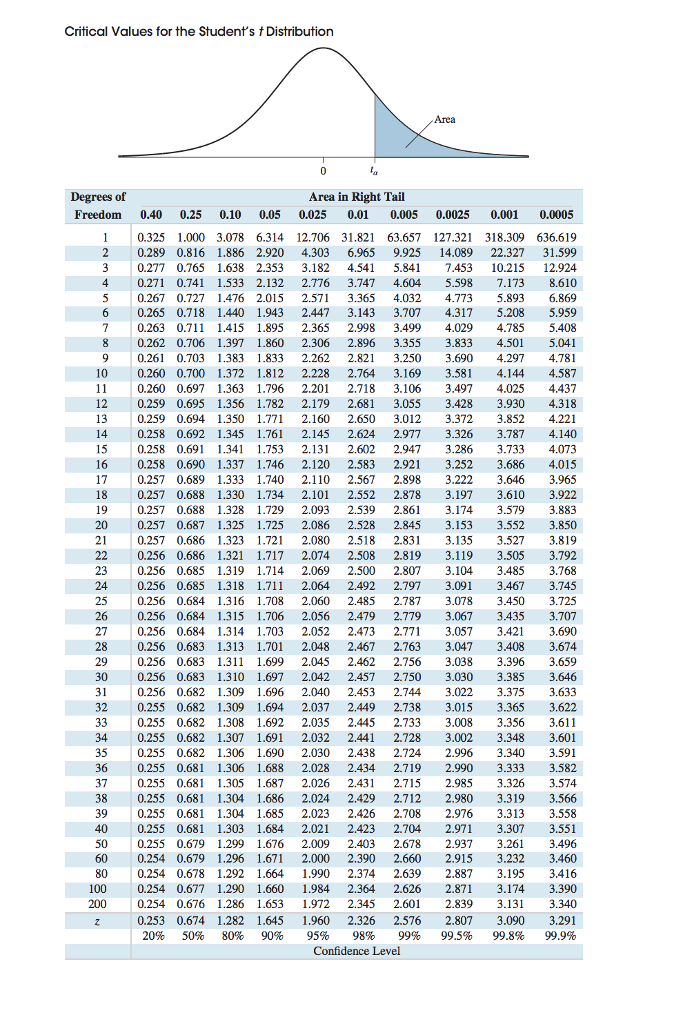
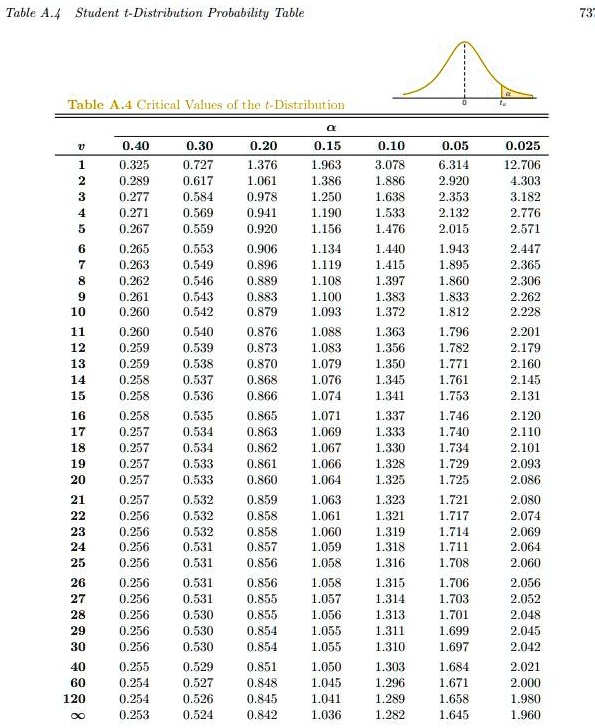
Most people look at the Student T Distribution Table and immediately get overwhelmed by all the columns and rows. It looks like a grid meant to confuse you, but it is actually simpler than the normal Z-table once you stop treating it like a puzzle. The t-distribution is used when your sample size is small and you do not know the population standard deviation. That is its entire purpose. You pull a t-score from your data, figure out your degrees of freedom, and look up the critical value or p-value in the table. The table has two main axes. The left column lists degrees of freedom, which for a single-sample t-test is just your sample size minus one. The top row shows significance levels, usually labeled as alpha values like 0.10, 0.05, 0.025, 0.01, and 0.005. Some tables split these into one-tailed and two-tailed sections, which is where most people make their first mistake. Here is the method I actually use when I need a quick critical value. First, decide whether your test is one-tailed or two-tailed. This changes which alpha column you read from. If you are doing a two-tailed test at the 5 percent level, you do not look under 0.05. You look under 0.025 because the table splits that alpha across both tails. I learned this the hard way during a graduate statistics course when I got a result that seemed wrong by almost exactly the critical boundary. My p-value was marginally significant when I should have used the two-tailed column. That mistake cost me about three hours of recalculating everything by hand before I caught it.
The degrees of freedom column runs from small numbers up to around 120 in most printed tables, and then it jumps to infinity. When the row hits infinity, the t-distribution has converged to the standard normal distribution. The critical value at infinity for a two-tailed 0.05 test is 1.96, which matches the Z-score you already know. If your degrees of freedom are larger than 120 and you only have a paper table, using the infinity row is acceptable and introduces negligible error.
What the Table Actually Represents
Under the hood, the Student T Distribution Table gives you the quantiles of the t-distribution for different degrees of freedom. Each cell tells you the t-value below which a certain proportion of the distribution falls. The distribution itself changes shape depending on your degrees of freedom. Low degrees of freedom produce heavier tails, which means extreme values are more likely. As degrees of freedom increase, the tails thin out and the curve approaches the normal distribution. One thing that is not obvious from most textbook explanations is that the t-distribution is not a single curve. It is a family of curves, one for each degree of freedom value. The table compresses all of them into one grid, which is convenient but also hides the fact that you are interpolating between discrete points. Most tables list df values like 1, 2, 3, 5, 10, 20, 30, 60, 120, and infinity. If your actual degrees of freedom fall between two listed values, standard practice is to round down to the nearest row. This gives you a slightly more conservative critical value, which is the safer choice in hypothesis testing. I encountered a specific edge case a few years ago while working on a clinical trial analysis where the effective degrees of freedom came out to something like 7.3 because of an unequal variance Welch correction. The table only had rows for 7 and 8. Rounding down to 7 was technically correct but felt unnecessarily conservative. I ended up linearly interpolating between the 7 and 8 rows for the alpha value I needed, which gave a critical t of about 2.33 instead of 2.365. The difference did not change the conclusion, but it mattered for a manuscript that was already under scrutiny. For most routine work, just rounding down is fine and saves you the extra arithmetic.
Get the Full Details
Common Pitfalls That Will Bite You
The biggest mistake people make is confusing the t-table with the Z-table. They are not interchangeable, especially at low degrees of freedom. Using the Z critical value of 1.96 for a sample size of 10 when you should be using the t-table will give you a false sense of precision. The actual critical value at 9 degrees of freedom for a two-tailed 0.05 test is 2.262, which is substantially wider. That difference compounds quickly when you are constructing confidence intervals for small samples. Another frequent error is mixing up one-tailed and two-tailed readings. If your research question is directional and you set up a one-tailed test, you look at a different column than if you set up a two-tailed test at the same overall alpha. Switching them mid-analysis is an easy way to get a p-value that is exactly half of what it should be, which either creates a false positive or hides a real effect. There is also a practical limitation with the table itself. Printed tables stop at a certain degree of freedom, and even digital versions often cap out around 1000 or so. For very large samples where degrees of freedom exceed that, the t-distribution and the normal distribution are essentially identical for all practical purposes. You can safely use Z-values when df is above 1000, and the error is well below any threshold that would affect a real-world decision. But if you are working with df in the hundreds and still want to be precise, a computational approach is faster than trying to approximate from a table.
When the Table Falls Short
The Student T Distribution Table is a lookup tool, not a calculation engine. It gives you critical values and approximate tail probabilities, but it cannot handle complex scenarios like multiple comparisons, adjusted degrees of freedom from mixed models, or non-standard experimental designs. If you are running a proper regression with several predictors, the degrees of freedom are n minus k minus one, where k is the number of predictors. The table still works for looking up the critical value, but figuring out the right df requires you to do the arithmetic first. The table will not do that for you. For anyone doing frequent t-tests or working with small samples regularly, relying on a printed table is slow and error-prone. A calculator or software function like T.INV in Excel or scipy.stats.t.ppf in Python will give you the exact critical value for any degree of freedom and alpha combination in under a second. The table is useful for understanding the concept and for exams where calculators are not allowed. After that, it is mostly a reference tool.
Downloading a Printable Student T Distribution Table
You can find a clean PDF version of the full Student T Distribution Table at most university statistics department pages. The version hosted by the UC Davis Mathematics Department is widely used and includes both one-tailed and two-tailed alpha levels up to 120 degrees of freedom plus the infinity row. It is roughly one page and prints cleanly, which is useful if you prefer working on paper during a test or field analysis. The underlying math for generating this table comes from the cumulative distribution function of the t-distribution, which involves the incomplete beta function. You do not need to derive it yourself, but knowing that the table values are numerically computed rather than approximate helps explain why computational tools are more accurate than anything you can read off a grid. The table entries are typically rounded to three decimal places, which is sufficient for most classroom and applied work but not for publication-level precision.