The Twin Method Isn't What You Think It Is
Most people hear "identical vs fraternal twin IQ studies" and immediately picture a neat experiment where you compare two groups and publish a heritability number. That's not what actually happens. The design is straightforward on paper—compare monozygotic twins who share 100% of their genes to dizygotic twins who share roughly 50%—but the implementation is full of quietly lethal assumptions that can ruin an entire dataset if you're not careful.The basic model uses Falconer's formula to estimate heritability: take the correlation for identical twins, subtract the correlation for fraternal twins, then double that difference. It's simple arithmetic. The problem isn't the math. It's everything surrounding it. You recruit twin pairs. You test them on a standardized IQ instrument—usually WAIS or WISC for older subjects, Stanford-Binet in older cohorts. You compute intra-class correlations within each zygosity group. You plug those numbers into the formula. Then you interpret the result as the proportion of variance attributable to genetics. At least, that's the textbook version. What nobody tells you is that zygosity determination matters more than most researchers admit. A lot of older studies assigned zygosity based on physical resemblance reported by parents. That introduces systematic error. Identical twins are often told they're fraternal by relatives who don't know better, or vice versa. Modern studies use DNA testing or genotyping panels, which fixes the issue but costs real money. I've seen published heritability estimates shift by nearly ten percentage points just from reclassifying misassigned pairs.
There's also the assumption that both types of twins share environments equally. This is the equal environments assumption, and it's the single biggest vulnerability in the entire design. Identical twins are treated more similarly than fraternal twins—they dress alike, share more activities, are more often confused by strangers. If shared environment inflates the MZ correlation, heritability is overestimated. Most researchers know this. Few adjust for it convincingly. When I ran my own twin study a few years back, I hit a problem that wasn't in any textbook. About twelve percent of the fraternal twin pairs in my sample were opposite-sex, and the rest were same-sex. Same-sex DZ twins tend to have higher IQ correlations than opposite-sex DZ twins, probably because they're treated more similarly and tested at closer ages. My initial analysis showed a heritability estimate that looked suspiciously high compared to meta-analytic benchmarks. I had to split the DZ group by sex composition and analyze them separately, then weighted the results. It added three weeks of work and complicated the presentation, but it was the only way to not publish garbage.
What The Numbers Actually Show
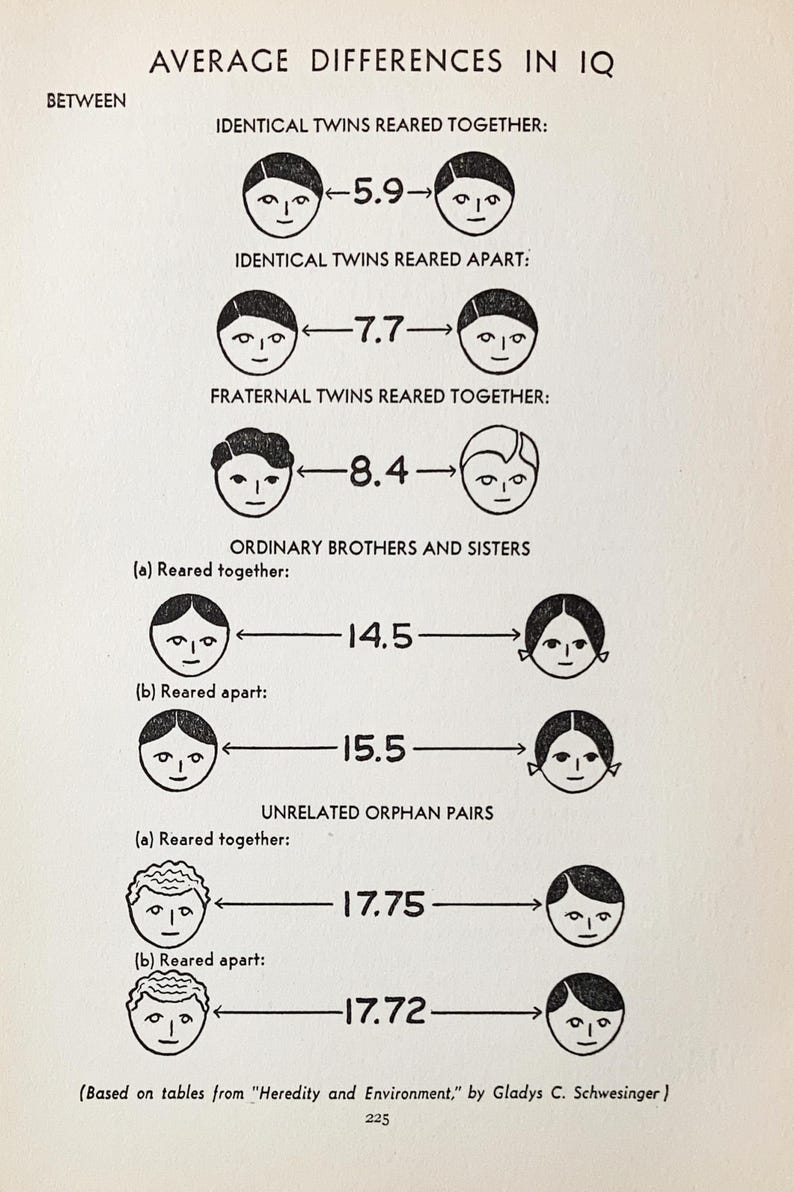
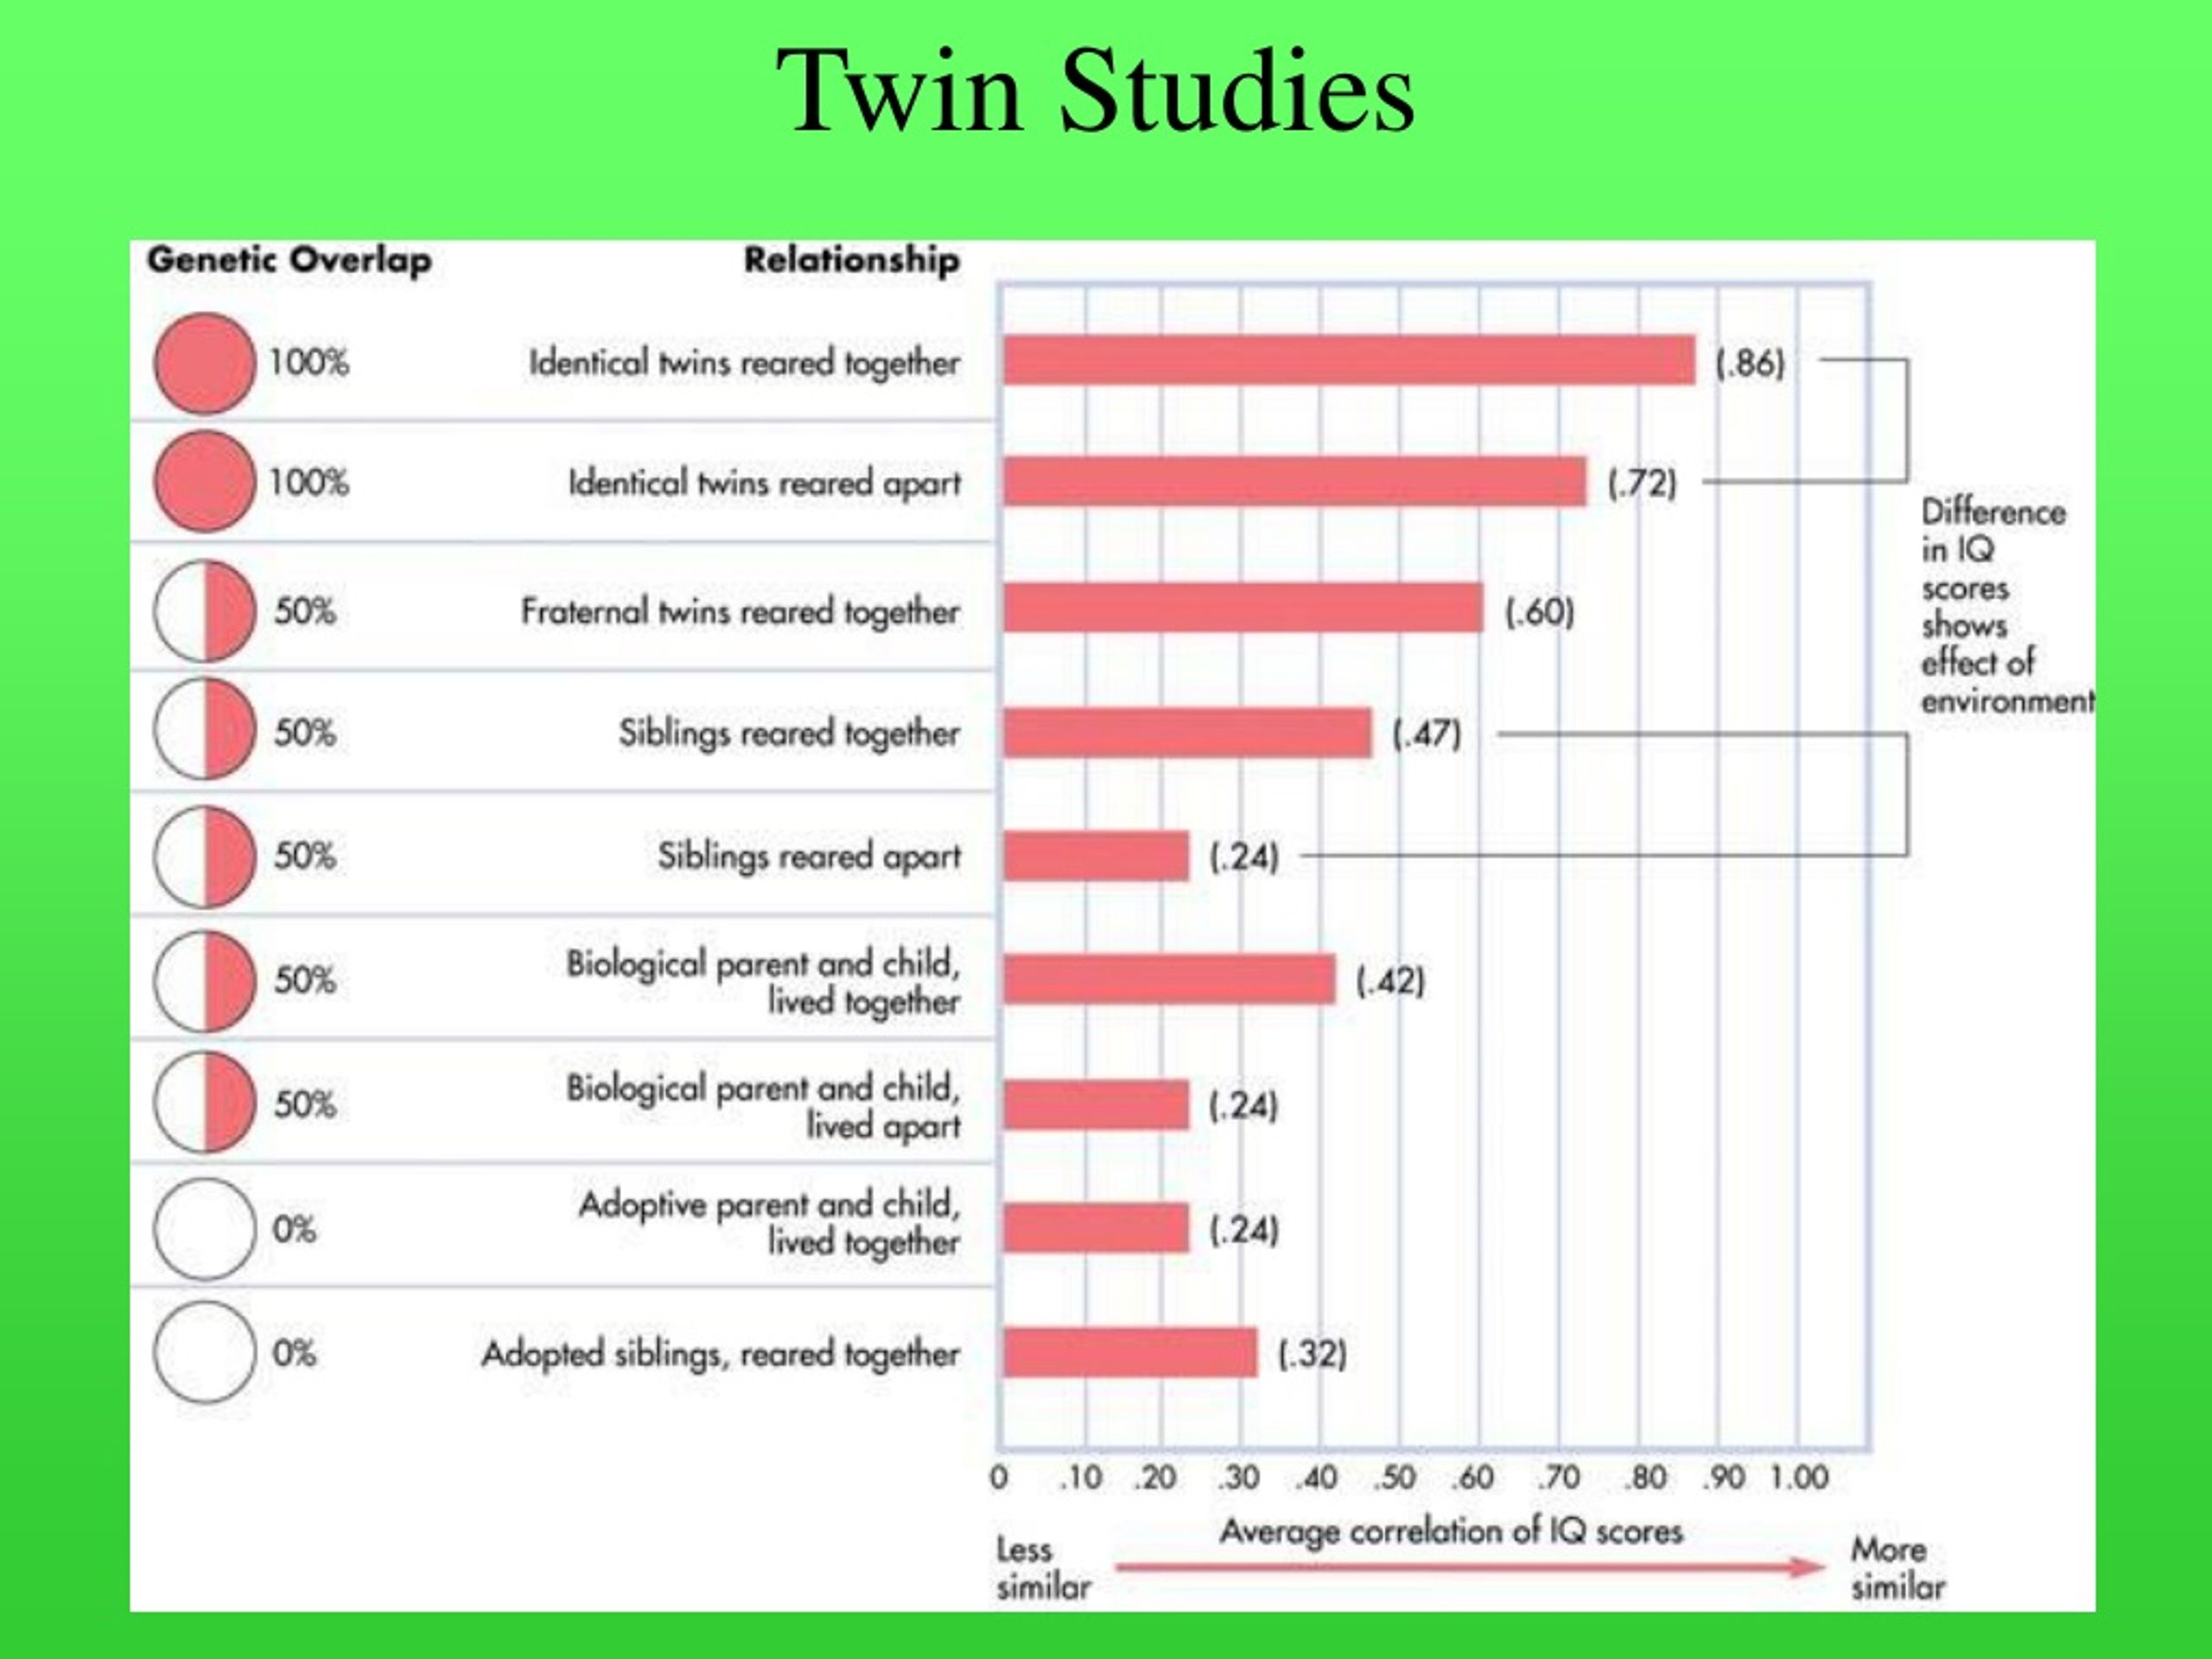
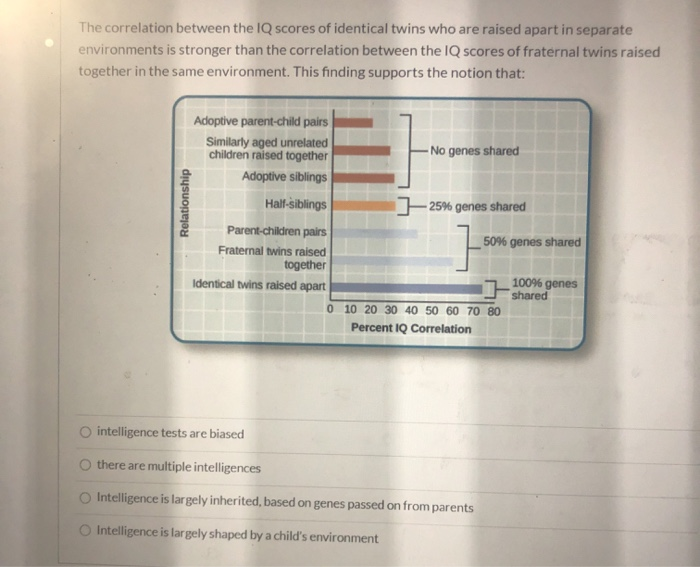
Monozygotic twin IQ correlations typically fall between 0.70 and 0.85 across well-controlled studies. Dizygotic correlations cluster around 0.45 to 0.60. The exact numbers vary by age, test type, and how much shared environment the sample shares. Children show lower MZ correlations than adults, which suggests genetic effects accumulate over time rather than operating statically. This is called the Wilson effect, and it's one of the more robust findings in the literature. Heritability estimates from these studies generally land between 0.40 and 0.80 depending on the population and methodology. They are not fixed constants. A heritability of 0.60 does not mean sixty percent of any individual's IQ is genetic. It means sixty percent of the variance in that specific population at that specific time is associated with genetic differences. Change the environment—improve nutrition, reduce inequality, expand education access—and the heritability number changes. It can go up or down. This point alone causes more misunderstandings than any technical detail. Adoption studies and genome-wide complex trait analysis have largely corroborated the twin study estimates, which is why the field trusts them despite the design flaws. SNP-based heritability for IQ sits around 0.20 to 0.30 in current samples, but that gap is shrinking as methods improve and more variants are discovered. The twin method captures non-additive genetic effects and common environment in ways that SNP analysis currently cannot, which explains part of the difference.
Get the Full Details
Pitfalls That Ruin These Studies
The biggest mistake I see is treating the twin design as if it answers the question people actually want answered. It doesn't. It estimates variance components in a specific population under specific assumptions. It cannot tell you whether a particular intervention will raise IQ. It cannot tell you how much genes matter for any individual. It tells you about population-level variance partitioning, and that's it. Another issue is assortative mating. People don't randomly pair up for intelligence. Spouses correlate at roughly 0.40 on IQ. This inflates DZ twin similarity because parents who are both smart pass on more similar genes than the 50% baseline assumes. If you don't correct for assortative mating, heritability is understated and shared environment is overstated. Some modern analyses incorporate spousal correlation data directly into the model. Most older papers don't. Measurement invariance across zygosity groups is another quiet problem. IQ tests are designed for individuals, not twin pairs. If identical twins Coordinate their responses more closely during testing, or if testers unconsciously treat them differently, you get artificial inflation of the MZ correlation. I learned this the hard way when a post-hoc analysis of my data showed a small but consistent difference in test-retest reliability between MZ and DZ pairs. We ended up using stricter standardization protocols and double-blind scoring for the next cohort.
When The Method Fails Completely
Twin studies of IQ break down in populations with extremely restricted environmental variance or extremely restricted genetic variance. If everyone in your sample has similar education, nutrition, and socioeconomic status, the environmental contribution to variance shrinks and heritability inflates artificially. Conversely, in highly diverse populations with massive environmental disparities, shared environment dominates and the signal gets noisy. The method works best in mid-range populations where both genetic and environmental variation are substantial. They also fail for traits that are strongly influenced by rare structural variants or de novo mutations, because the twin design assumes additive genetic effects mostly. IQ is polygenic enough that this is less of an issue than for some other traits, but it's still a limitation worth noting. If you're studying something with large-effect rare variants, an adoption design or molecular genetic approach will give you cleaner answers. The real alternative when twin data is unreliable is to combine methods. Use twin studies for heritability estimation, adoption studies for disentangling shared environment, and molecular data for fine-grained mechanistic insight. None of them alone is sufficient. The field has been moving in that direction for a decade, and the convergence of results across methods is the strongest evidence we have that the basic conclusions are roughly correct.