The Practical Side of Phonetics
Most people enter phonetics because they're fascinated by how voices work. They quickly find out that fascination doesn't help when you're staring at a waveform at 2 AM trying to figure out whether a vowel is tense or lax. The Study Of Speech Sounds is less about romance and more about pattern recognition under pressure. I learned this the hard way during a project where I was transcribing conversational American English for a speech recognition startup. The client wanted dense phonetic annotations at the word and phoneme level. I started doing it the way I'd been taught in grad school, manually marking boundaries in Praat. It took roughly four hours per minute of clean studio audio. We had about sixty hours of raw field recordings to get through. Something had to give. At its core, this field sits between acoustics and linguistics. You're looking at how the vocal tract shapes sound, how those shapes map onto linguistic categories, and where the two diverge. The International Phonetic Alphabet gives you a coordinate system. The tools like Praat, WaveSurfer, and Audacity give you ears and eyes. The actual work is knowing when to trust your ears, when to trust the spectrogram, and when to admit you don't know yet. I keep it simple on my end. I install Praat and set it to display both the waveform and the broadband spectrogram simultaneously. That's enough for most transcription work. You create separate tiers for the orthographic text, the phonetic transcription, and any notes about speaker variation or ambient issues. The tier system in Praat is not glamorous but it prevents you from losing context when you come back to a file three days later. I also run everything through an automated forced alignment tool like Montreal Forced Aligner before I touch it with manual transcription. This gives you a scaffolding to verify rather than build from scratch. The alignment step usually cuts the process down from 2 hours per minute of audio to about 15 minutes, depending on your setup and how clean the recordings are.
A Problem I Actually Faced With Transcription
Here is a specific edge case that nearly cost me a deadline. I was transcribing a speaker of General American English who reduced vowels extensively in casual speech. The word "tomorrow" came out as something approaching [tmo] depending on the recording condition. My initial manual transcription flagged it as [tmro] because that is what the dictionary says. The acoustic evidence told a different story. The spectrogram showed no clear second formant target for either /o/ or //. The duration was also markedly shorter than in careful speech. I spent three hours going back and forth on whether this was a transcription error or a genuine phonetic phenomenon. The workaround was straightforward once I knew what to look for. I switched to a narrowband spectrogram with a higher window length, which revealed the formant structure more clearly. What I found was that the speaker was producing a reduced central vowel in both the first and third syllables, with the middle consonant cluster undergoing both debuccalization and lateral release. The correct transcription was closer to [tmo] with schwa reduction in non-stressed positions. The lesson here is that dictionary pronunciations and actual produced speech live in different universes. Automatic aligners will often misalign heavily reduced segments because they default to citation forms. I learned to trust the acoustic signal over the lexical entry, which is easier said than done when you're tired.
Where Beginners Go Wrong
The biggest mistake I see is treating the IPA as a one-to-one mapping system. It is not. A single phoneme in a language can correspond to dozens of allophones depending on context, register, speaker identity, and surrounding sounds. Transcribing every allophonic detail is sometimes necessary and sometimes pathological. You need to know when the distinction matters for your research question and when it is noise. Another common error is ignoring coarticulation. Sounds do not exist in isolation. The /t/ in "top" is aspirated. The /t/ in "stop" is not. The /t/ in "butter" in many American dialects becomes a flap []. These are not quirks. They are predictable patterns governed by stress, position, and dialect. If you transcribe each instance identically, you are not doing phonetics. You are doing calligraphy. There is also the issue of over-transcribing. I have seen projects where transcribers marked glottalization on every stop consonant in a corpus, including ones where the glottal feature was acoustically negligible. This creates a dataset that is internally inconsistent and practically unusable for analysis. Your transcription should be dense enough to be useful and sparse enough to be reliable. The goldilocks zone depends entirely on your research question.
Get the Full Details
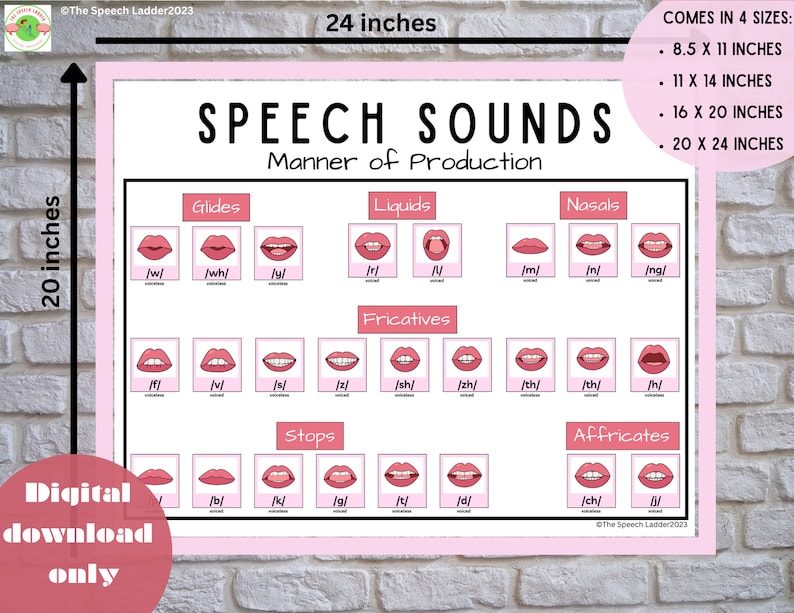
The Tools That Actually Work
Praat remains the standard for a reason. It handles waveform display, spectrograms, pitch tracking, formant measurement, and annotation all in one environment. It has a learning curve, but the documentation is thorough. For forced alignment, Montreal Forced Aligner is the most widely used option. It requires a pretrained acoustic model for your target language and a pronunciation dictionary. The output is a set of TextGrid files that you can open directly in Praat. From there, you verify and correct, not rebuild from zero. For corpora that involve multiple speakers or noisy environments, I recommend combining acoustic analysis with perceptual validation. Run your transcriptions by a second listener independently, then compare. Inter-rater reliability in phonetic transcription is usually around 85 to 92 percent for trained transcribers working with clear speech. It drops significantly with reduced or dialectally unfamiliar material. If your agreement is below 80 percent, your transcription scheme is probably too fine-grained for the data quality you have.
What This Approach Does Not Handle Well
Phonetic transcription as I have described it breaks down in several scenarios. It struggles with highly non-standard dialects for which no pronunciation dictionary exists. It struggles with pathological speech, severe accents, or languages with tone, nasal harmony, or other suprasegmental features that are not well supported by your toolchain. It also struggles with overlapping speech, which is every conversational corpus you will ever work with. Forced alignment tools tend to collapse or misalign when two speakers talk at once. You will need manual intervention for those sections, and manual intervention is slow and error-prone. If you are working with tonal languages, you need additional tools. Praat can display pitch contours, but proper tonal analysis often requires dedicated software like ToBI annotation conventions and specialized aligners. For supersegmental features like vowel length distinction in Japanese or consonant gemination in Italian, duration-based automatic detection can help but should never be trusted without manual verification. These features are subtle and context-dependent. The honest limitation is that no amount of tooling replaces the trained ear. Automation handles the scaffolding. You handle the judgment calls. That is the actual job, and it is not as glamorous as the theory makes it sound, but it is also not as tedious as the workflow suggests if you set up your pipeline correctly from the start.