Mean Subtraction in Practice
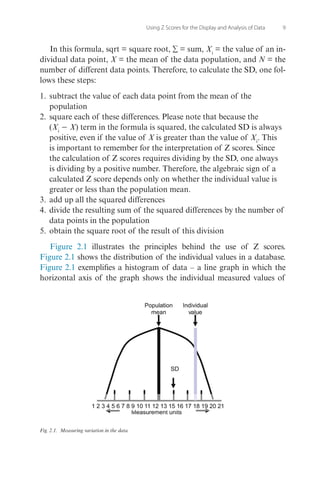
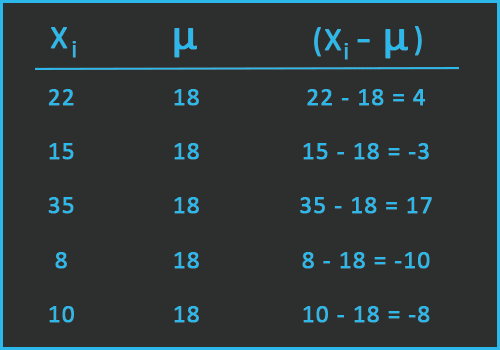
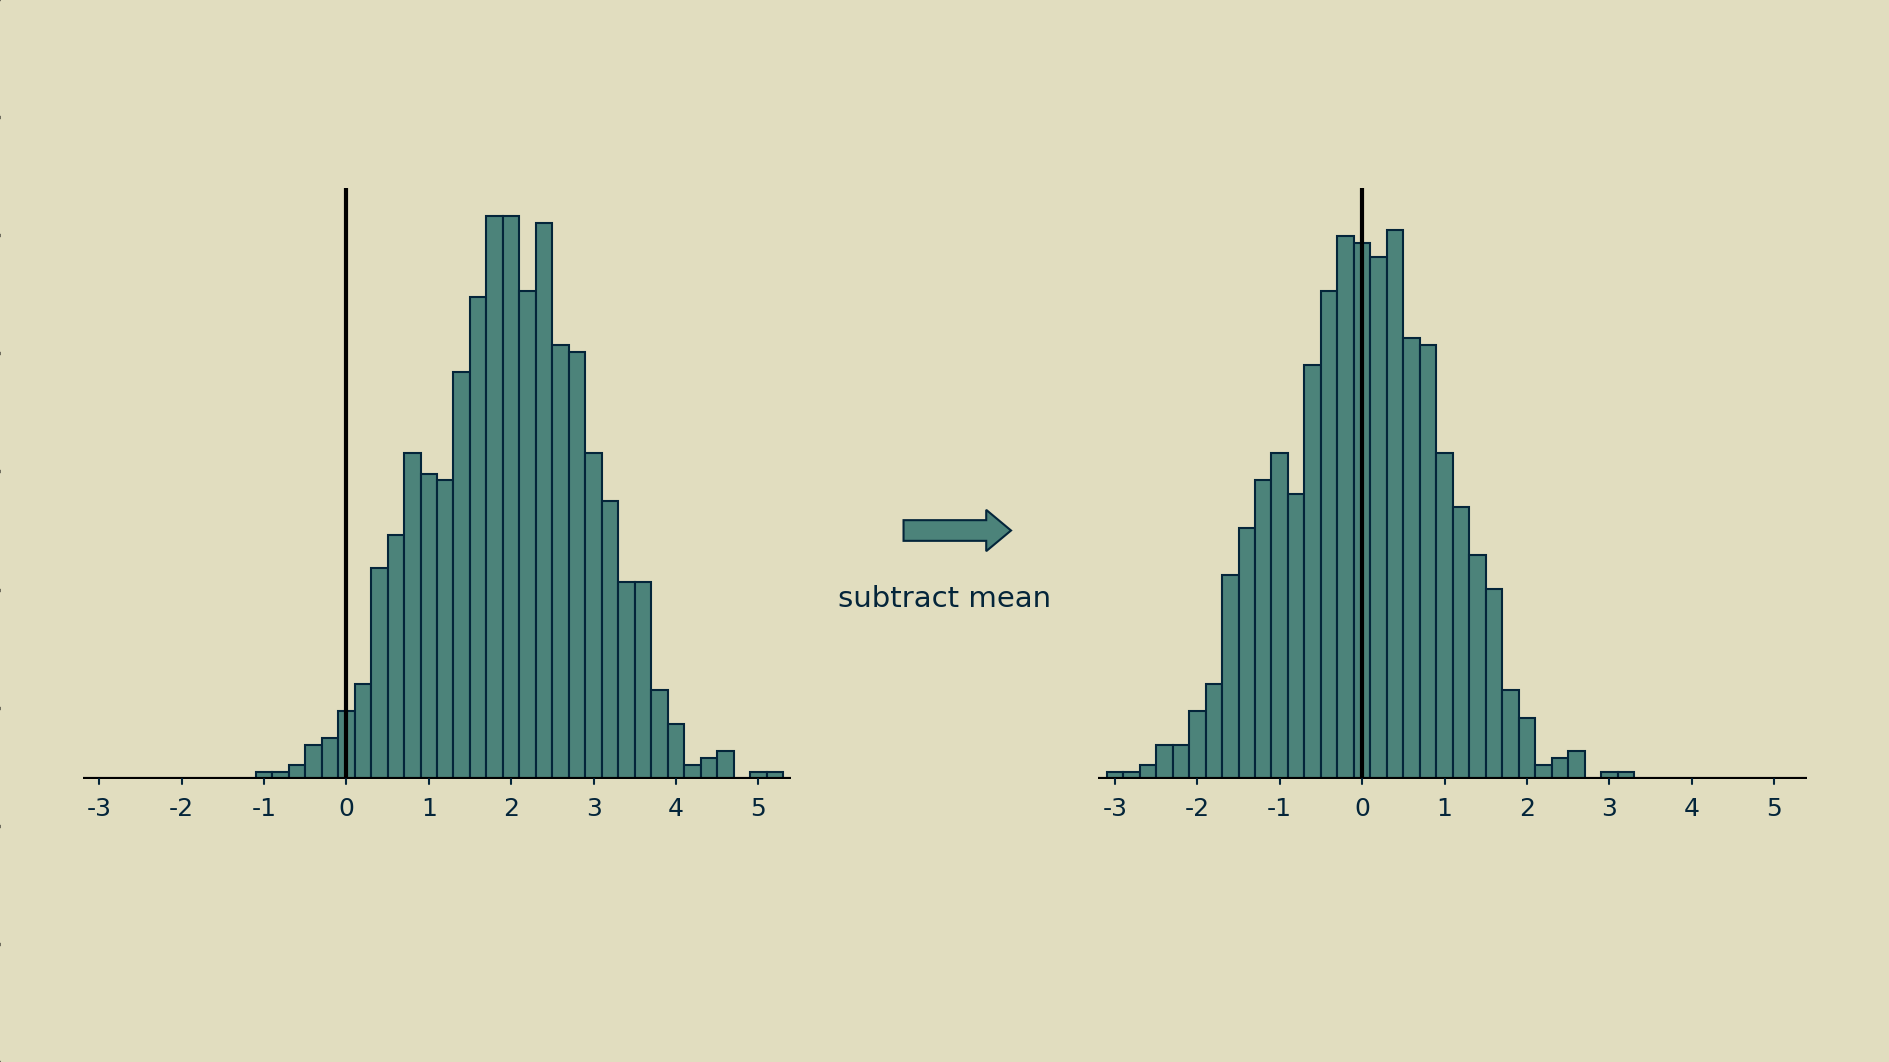
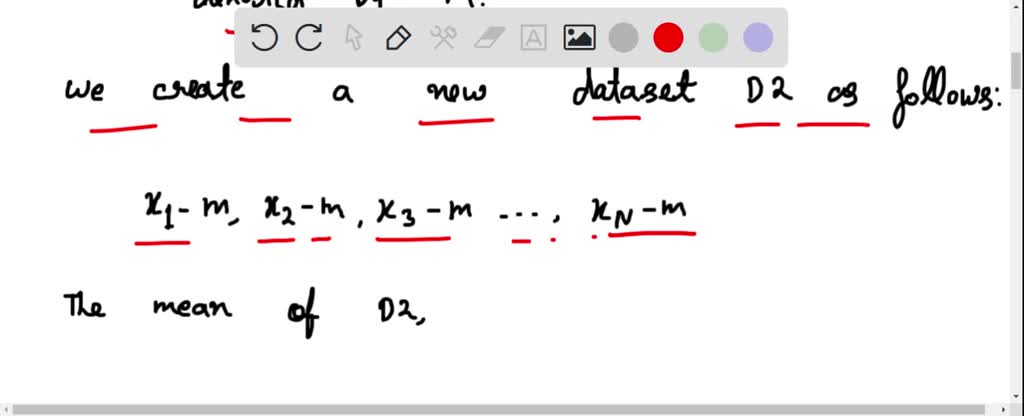
When you work with real datasets, you'll quickly find that subtracting the mean from each data point is one of those routine operations that makes everything else easier down the line. It's called centering the data. You take the average of your feature, then subtract that average from every individual value in the column. What you get is a transformed dataset where the new mean is zero. The mechanics are straightforward enough that you don't really need a tutorial for the arithmetic. Take your mean. Subtract it from each observation. Done. The part people get wrong isn't the math. It's knowing when to do it and when it becomes a liability. In linear regression, centering a predictor eliminates multicollinearity between that predictor and its interaction terms. If you're running a model with an interaction term like X times Z and both X and Z are uncentered, the correlation between X and XZ can inflate variance estimates to the point where your standard errors become meaningless. Center both predictors first and that correlation drops substantially. I've seen VIF values go from 40 down to under 3 just by centering.
For gradient descent, it matters more. Unnormalized features force the optimizer to take tiny steps because the loss surface is elongated. Subtracting the mean is step one. Scaling by standard deviation is step two. Skipping either leaves you waiting hours for convergence on data that should have taken minutes. Here's a scenario that tripped me up recently. I was preprocessing text classification data where I subtracted the mean from TF-IDF scores across documents. Standard stuff. But my test set had a completely different vocabulary distribution from the training set. I calculated the mean on training only, subtracted it from train and test, and the model performance tanked. The issue was that centering shifted the test distribution into a region where the feature space looked alien compared to training. The fix was simple but easy to miss: I switched to applying the training mean without recentering, essentially using it as a raw offset correction rather than a full standardization pipeline. The model stabilized after that. There are edge cases worth noting. If your data contains a constant column, the mean equals that constant and subtracting it produces a column of zeros. That zero column then gets dropped by most modeling functions, which silently changes your feature count. You might not even notice until your model's dimensions don't match what you expected.
Another gotcha is with missing values. If you use numpy or pandas and there's a NaN in your feature, the mean calculation returns NaN, which means every single output becomes NaN. You lose the entire feature. The workaround is either to impute before centering or to use a function that handles NaNs explicitly, like nanmean in numpy. Don't skip this step just because the code looks clean. Time-wise, centering a column in pandas takes roughly the same time as computing the mean. For a million-row DataFrame, that's about 2 milliseconds on a modern machine. The actual subtraction vectorizes so fast it's negligible. The bottleneck is always the data loading, not the operation itself. If you're working in Python, the implementation is:
Get the Full Details
import numpy as np
mean = np.mean(data)
centered_data = data - mean
In R it's even shorter since scale() does it in one call, though scale() also centers and standardizes by default. If you only want centering, pass scale=FALSE. sklearn's StandardScaler is the common choice for production pipelines. It fits on training data and transforms both sets consistently. The fit_transform vs transform distinction is where most bugs hide. Fit on train only. Transform both. Anything else leaks information. The main downside to mean subtraction is that it changes interpretability. A centered coefficient no longer tells you the effect at the mean value of the predictor in an intuitive way without back-transforming. For reporting to stakeholders who don't work with matrices daily, that can be a real problem. I've had to reconstruct raw predictions from centered models just to explain results to non-technical teams. It's an extra step that adds up over time.
Also, centering doesn't fix skewed distributions. It only shifts the axis. If your data is heavily right-skewed, the mean gets pulled toward the tail and the centering doesn't do what you might hope. Log transformation before centering is often the right call in those situations, but again it depends on the downstream model. Resources: sklearn.preprocessing.StandardScaler documentation