Getting a clean Sunderkand In Hindi Pdf file is harder than it should be
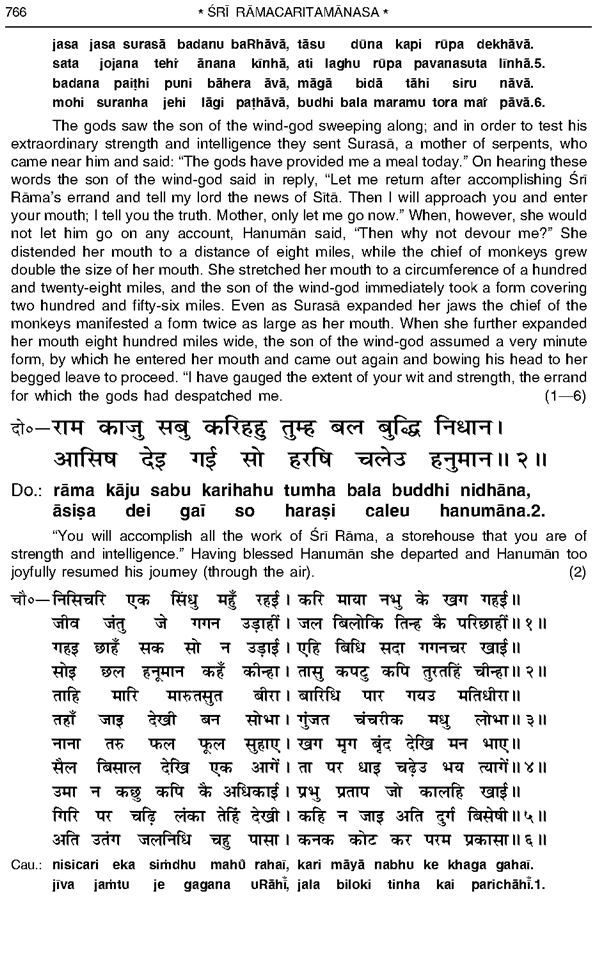
The internet is full of broken PDFs that won't open on mobile, scanned pages that are too dark to read, and OCR text that turns "" into garbage characters. I spent months sifting through these before settling on sources that actually work. The core problem is that Sunderkand exists in multiple text traditions - the Awadhi version from the Ramcharitmanas by Tulsidas is the most common, but there are also Braj Bhasha recensions and regional variations that change the phrasing significantly. Most free PDFs online don't specify which version they're using, so you end up downloading something that doesn't match what you were looking for. Start with archives that have clear source attribution. The Government of India's Gita Press publications are widely available as PDFs through their official website and a few academic repositories. These are scanned directly from the printed edition, which means the Devanagari rendering is accurate. Another solid option is the Digital Library of India, which has multiple scans of different editions. The catch is that their interface is dated and the search function is unreliable. You'll need to browse manually or know the exact title to find what you want. Archive.org also has several versions uploaded by individuals, but the quality varies wildly. I once downloaded a file that claimed to be the complete Sunderkand but turned out to be only 47 of the 96 Kandas compressed into a single poorly formatted page. For a practical approach, I recommend checking the file size first. A proper full-text Sunderkand PDF with accurate Devanagari characters and proper line breaks usually lands between 8 and 15 megabytes. Files under 2MB are almost always either truncated or have corrupted text encoding. Files over 20MB are typically just high-resolution scans with no searchable text, which defeats the purpose if you're trying to search or cite specific passages.
What most people get wrong about Hindi Sunderkand PDFs
The biggest issue I've run into repeatedly is the difference between a true Hindi text and something labeled Hindi that is actually in a different register. The Ramcharitmanas is written in Awadhi, not standard Hindi. Many PDFs slap a "Hindi" label on them for searchability, but the actual content uses Awadhi grammar and vocabulary. This matters if you're doing serious study or teaching, because the linguistic differences affect how certain verses are parsed and understood. The word "" itself is a Sanskritized form; Tulsidas used " " in the original manuscript tradition. Another thing nobody mentions is pagination. Different editions number the chapters differently. Some printings use the traditional "Sarga" numbering from the Valmiki Ramayana tradition, while others use a simpler numbered scheme. When you're cross-referencing between a PDF and a physical book or trying to discuss a specific passage with someone who has a different edition, the lack of consistent pagination becomes a real headache. I solved this by keeping a reference table of the most common edition numbers side by side rather than trying to memorize them. It takes about ten minutes to set up and saves you from constant back-and-forth checking. The character encoding problem is also worth understanding. Many free PDFs use non-standard font mappings for Devanagari, which means copying text from them into another document produces unreadable characters. This happens because the PDF was created with a custom font substitution that doesn't map to Unicode. If you need to quote from the PDF somewhere, the workaround is to use a PDF reader that exports to plain text with Unicode encoding rather than just selecting and copying. Adobe Reader's export function handles this better than most other tools. I also keep a small script that checks copied text for mojibake before I paste it anywhere, which catches the issue early.
A specific problem and how I fixed it
Last year I needed to reference a particular verse from Sunderkand in a discussion about regional linguistic variations in the Ramcharitmanas. I had a PDF that looked correct on screen, but when I searched for the verse reference, the PDF text search returned zero results even though the verse was clearly visible on the page. The file was a scanned image PDF with no OCR layer at all. The preview looked like normal text because the PDF viewer was rendering the embedded font, but the underlying data was purely pixel-based. I ran it through a dedicated OCR tool with Devanagari support, which took about twenty minutes for the full text, and then merged the OCR layer back into the PDF using a free tool. The result was searchable and selectable text. The initial OCR had about a 5% error rate on complex compound words, which I cleaned up manually by spot-checking random pages. Worth noting that standard OCR engines trained on modern Hindi perform poorly on classical Awadhi texts because the spelling conventions are different. Tools that support archival or scholarly Devanagari output give noticeably better results. PDFs are convenient but they're not ideal for deep textual study. They flatten the material - you lose the ability to easily compare variant readings across editions, add your own annotations at the paragraph level, or run computational analysis on the text. If your goal is serious engagement with the Sunderkand rather than casual reading, I'd recommend looking into open-source digital editions instead. Projects like the Sarada repository or the SAHI (South Asian Historical corpora) initiatives provide tagged, searchable versions of the Ramcharitmanas in multiple dialects with variant readings documented. They require more setup than downloading a PDF, but they save time once you're past the initial configuration. The learning curve is maybe an hour if you're familiar with basic command-line tools, or a couple of hours if you're not. For most people though, a well-chosen PDF is sufficient. Just verify the source, check the file size, confirm it's searchable text and not just a scan, and be aware of the Awadhi versus Hindi distinction so you know what linguistic tradition you're actually reading.
Get the Full Details